Antonio Evans
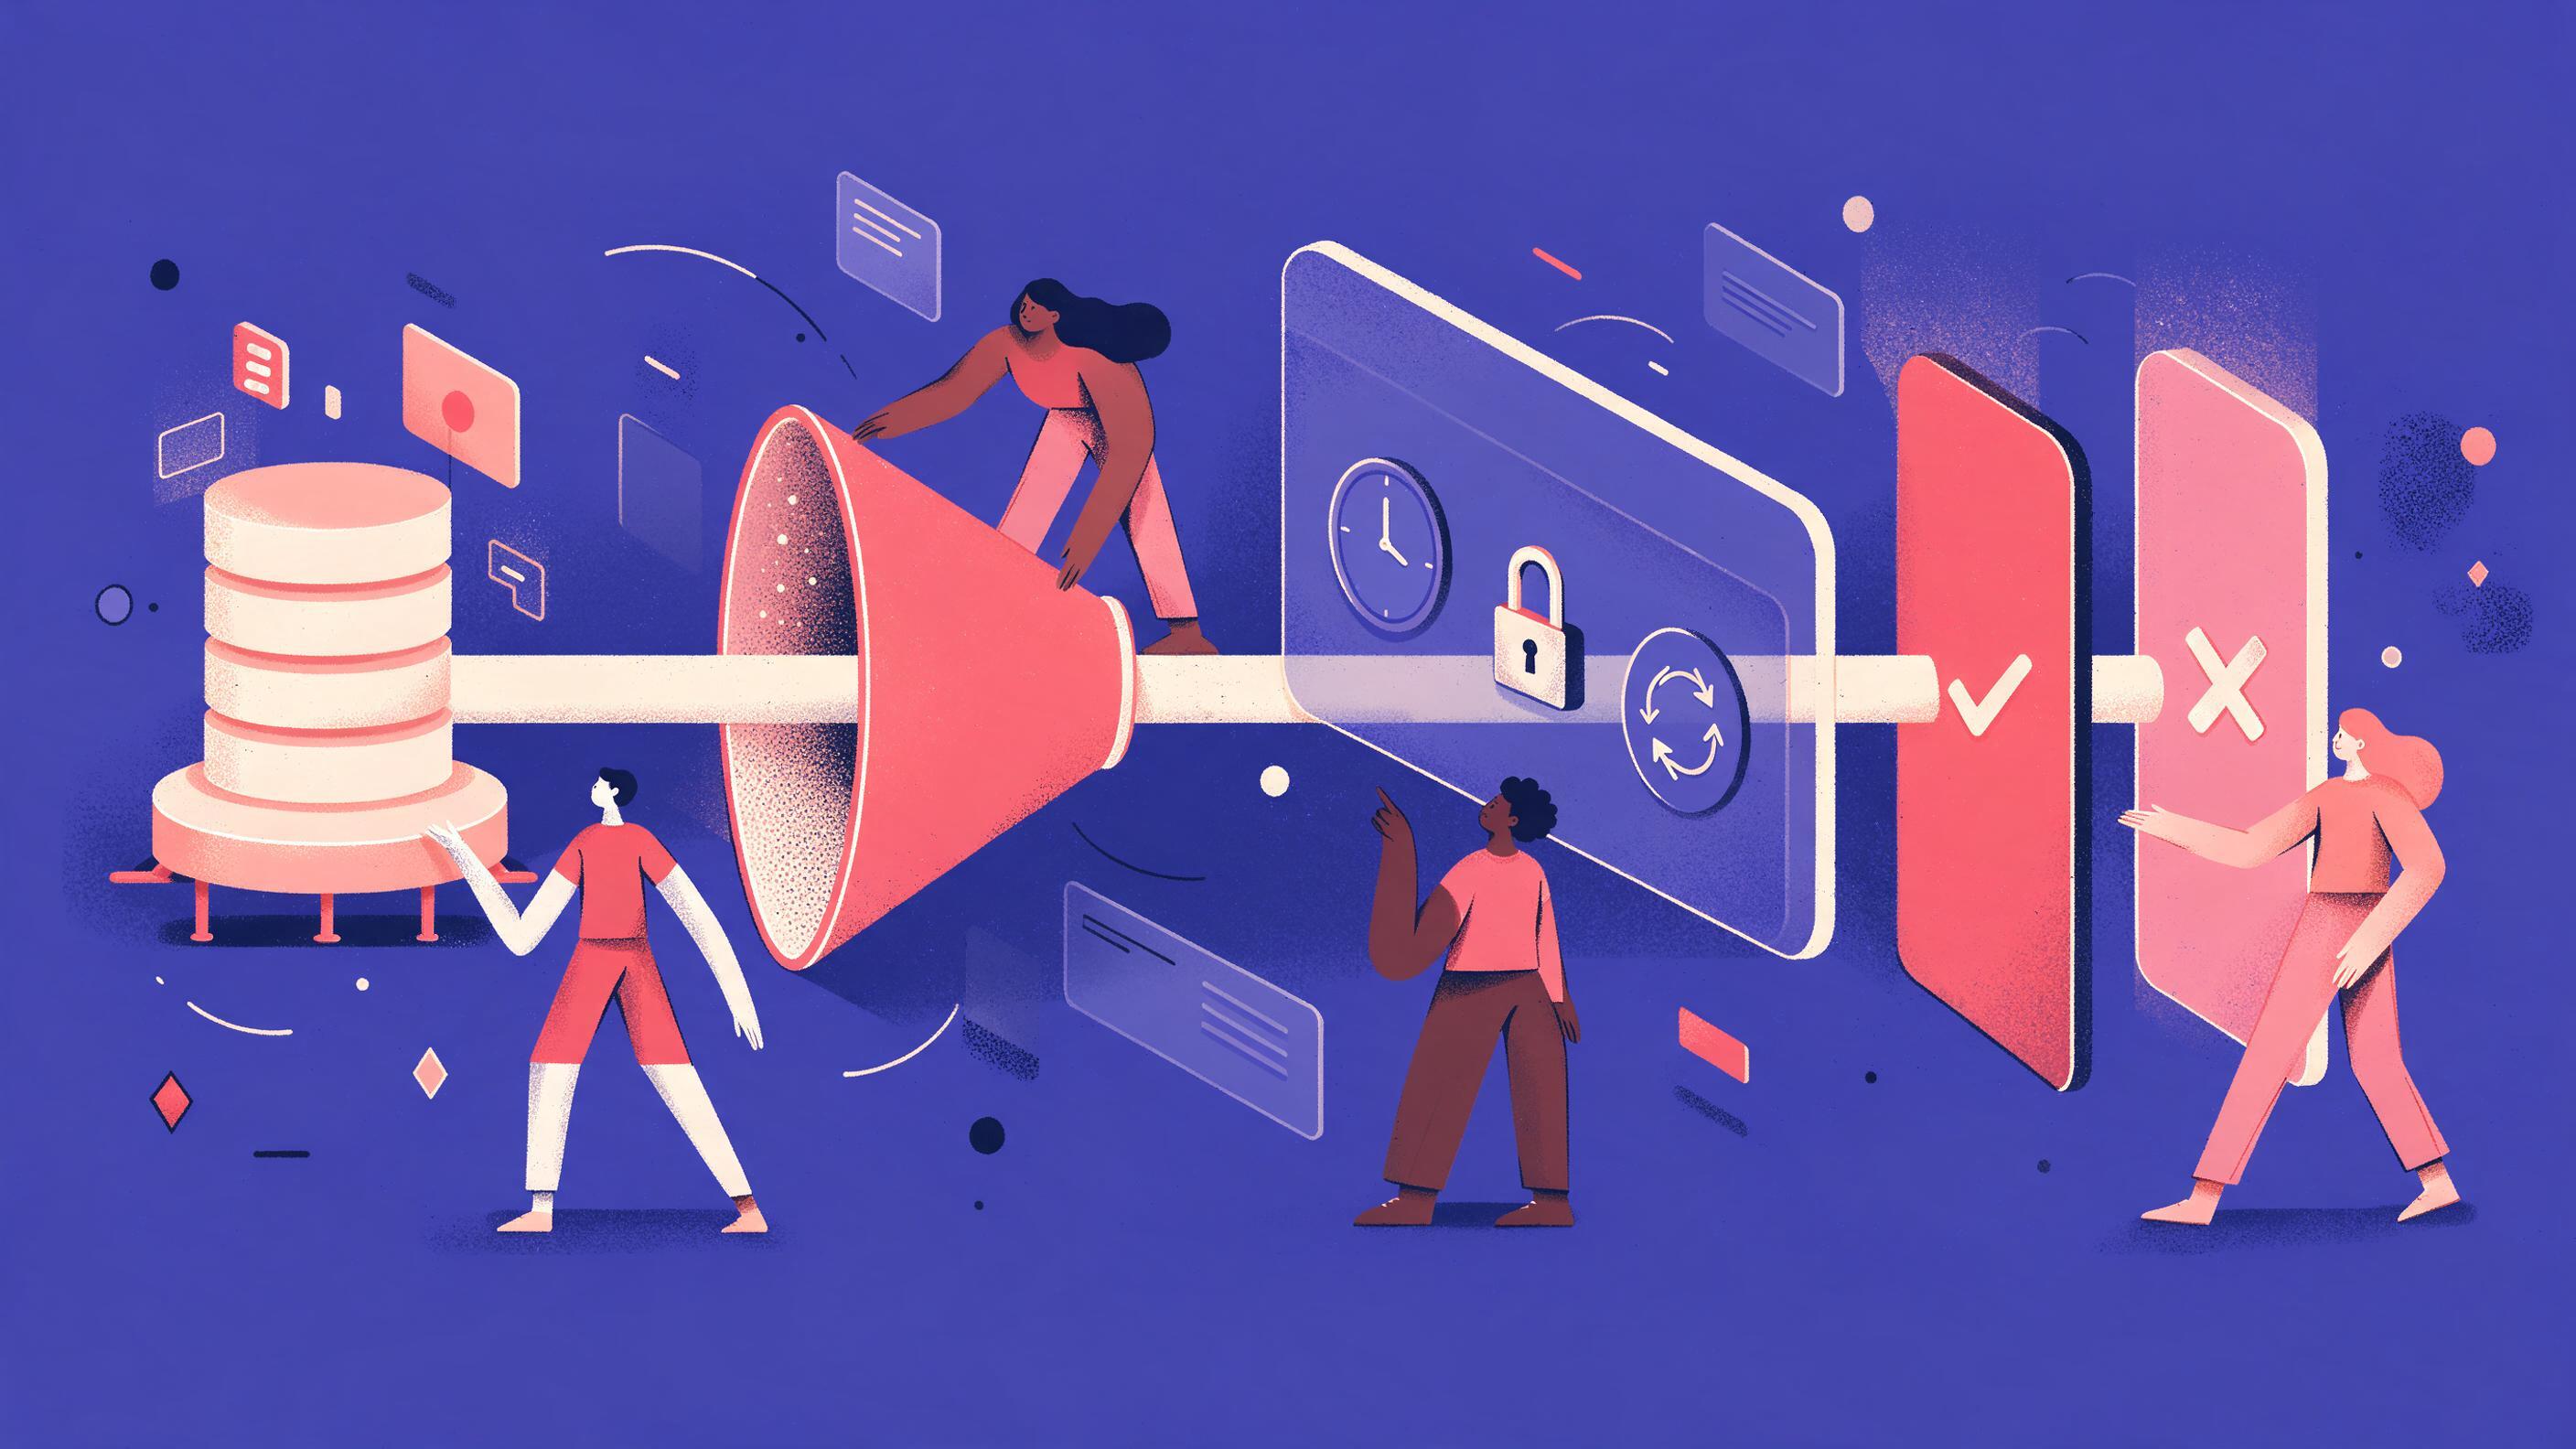
Most agent migrations fail in production for one of two reasons: the change is incompatible with running code, or it holds a lock for longer than the application can tolerate. The first kind is caught by ordinary tests. The second kind is invisible to them, because a test database with a few hundred rows does not reproduce the lock queue that a table with tens of millions of rows produces.
The lock mechanics are not subtle once you look. In PostgreSQL, ALTER TABLE acquires an ACCESS EXCLUSIVE lock unless a subform documents otherwise, and that mode conflicts with every other lock mode, including the ACCESS SHARE a plain SELECT takes (PostgreSQL explicit locking). Worse, other statements that need a lock on that table queue behind the waiting ALTER, so a migration that is merely waiting for a long report can still take a table offline for reads and writes (Xata on the lock queue). A dry run that measures the wait, rather than assuming it away, is the only way to see this before production does.
MySQL and Vitess have their own version of the same problem. A direct MySQL ALTER TABLE is blocking and resource heavy, which is why Vitess recommends managed, online schema changes and offers strategies that copy the table in the background (Vitess schema changes). Tools such as pt-online-schema-change copy rows in small chunks to avoid locking the original table, and they explicitly tell you to test on a non-production server first (Percona Toolkit). That advice is sound, and it is exactly what a CI job industrializes.
The decision rule is simple. If a migration changes a table larger than a few hundred thousand rows, or touches an index on a hot path, the pull request needs a dry run with metrics, not a code review comment that says "looks fine."