
Development

A Routing Rule That Sends Overflow Traffic to a Cheaper Model

Antonio Evans8 min read

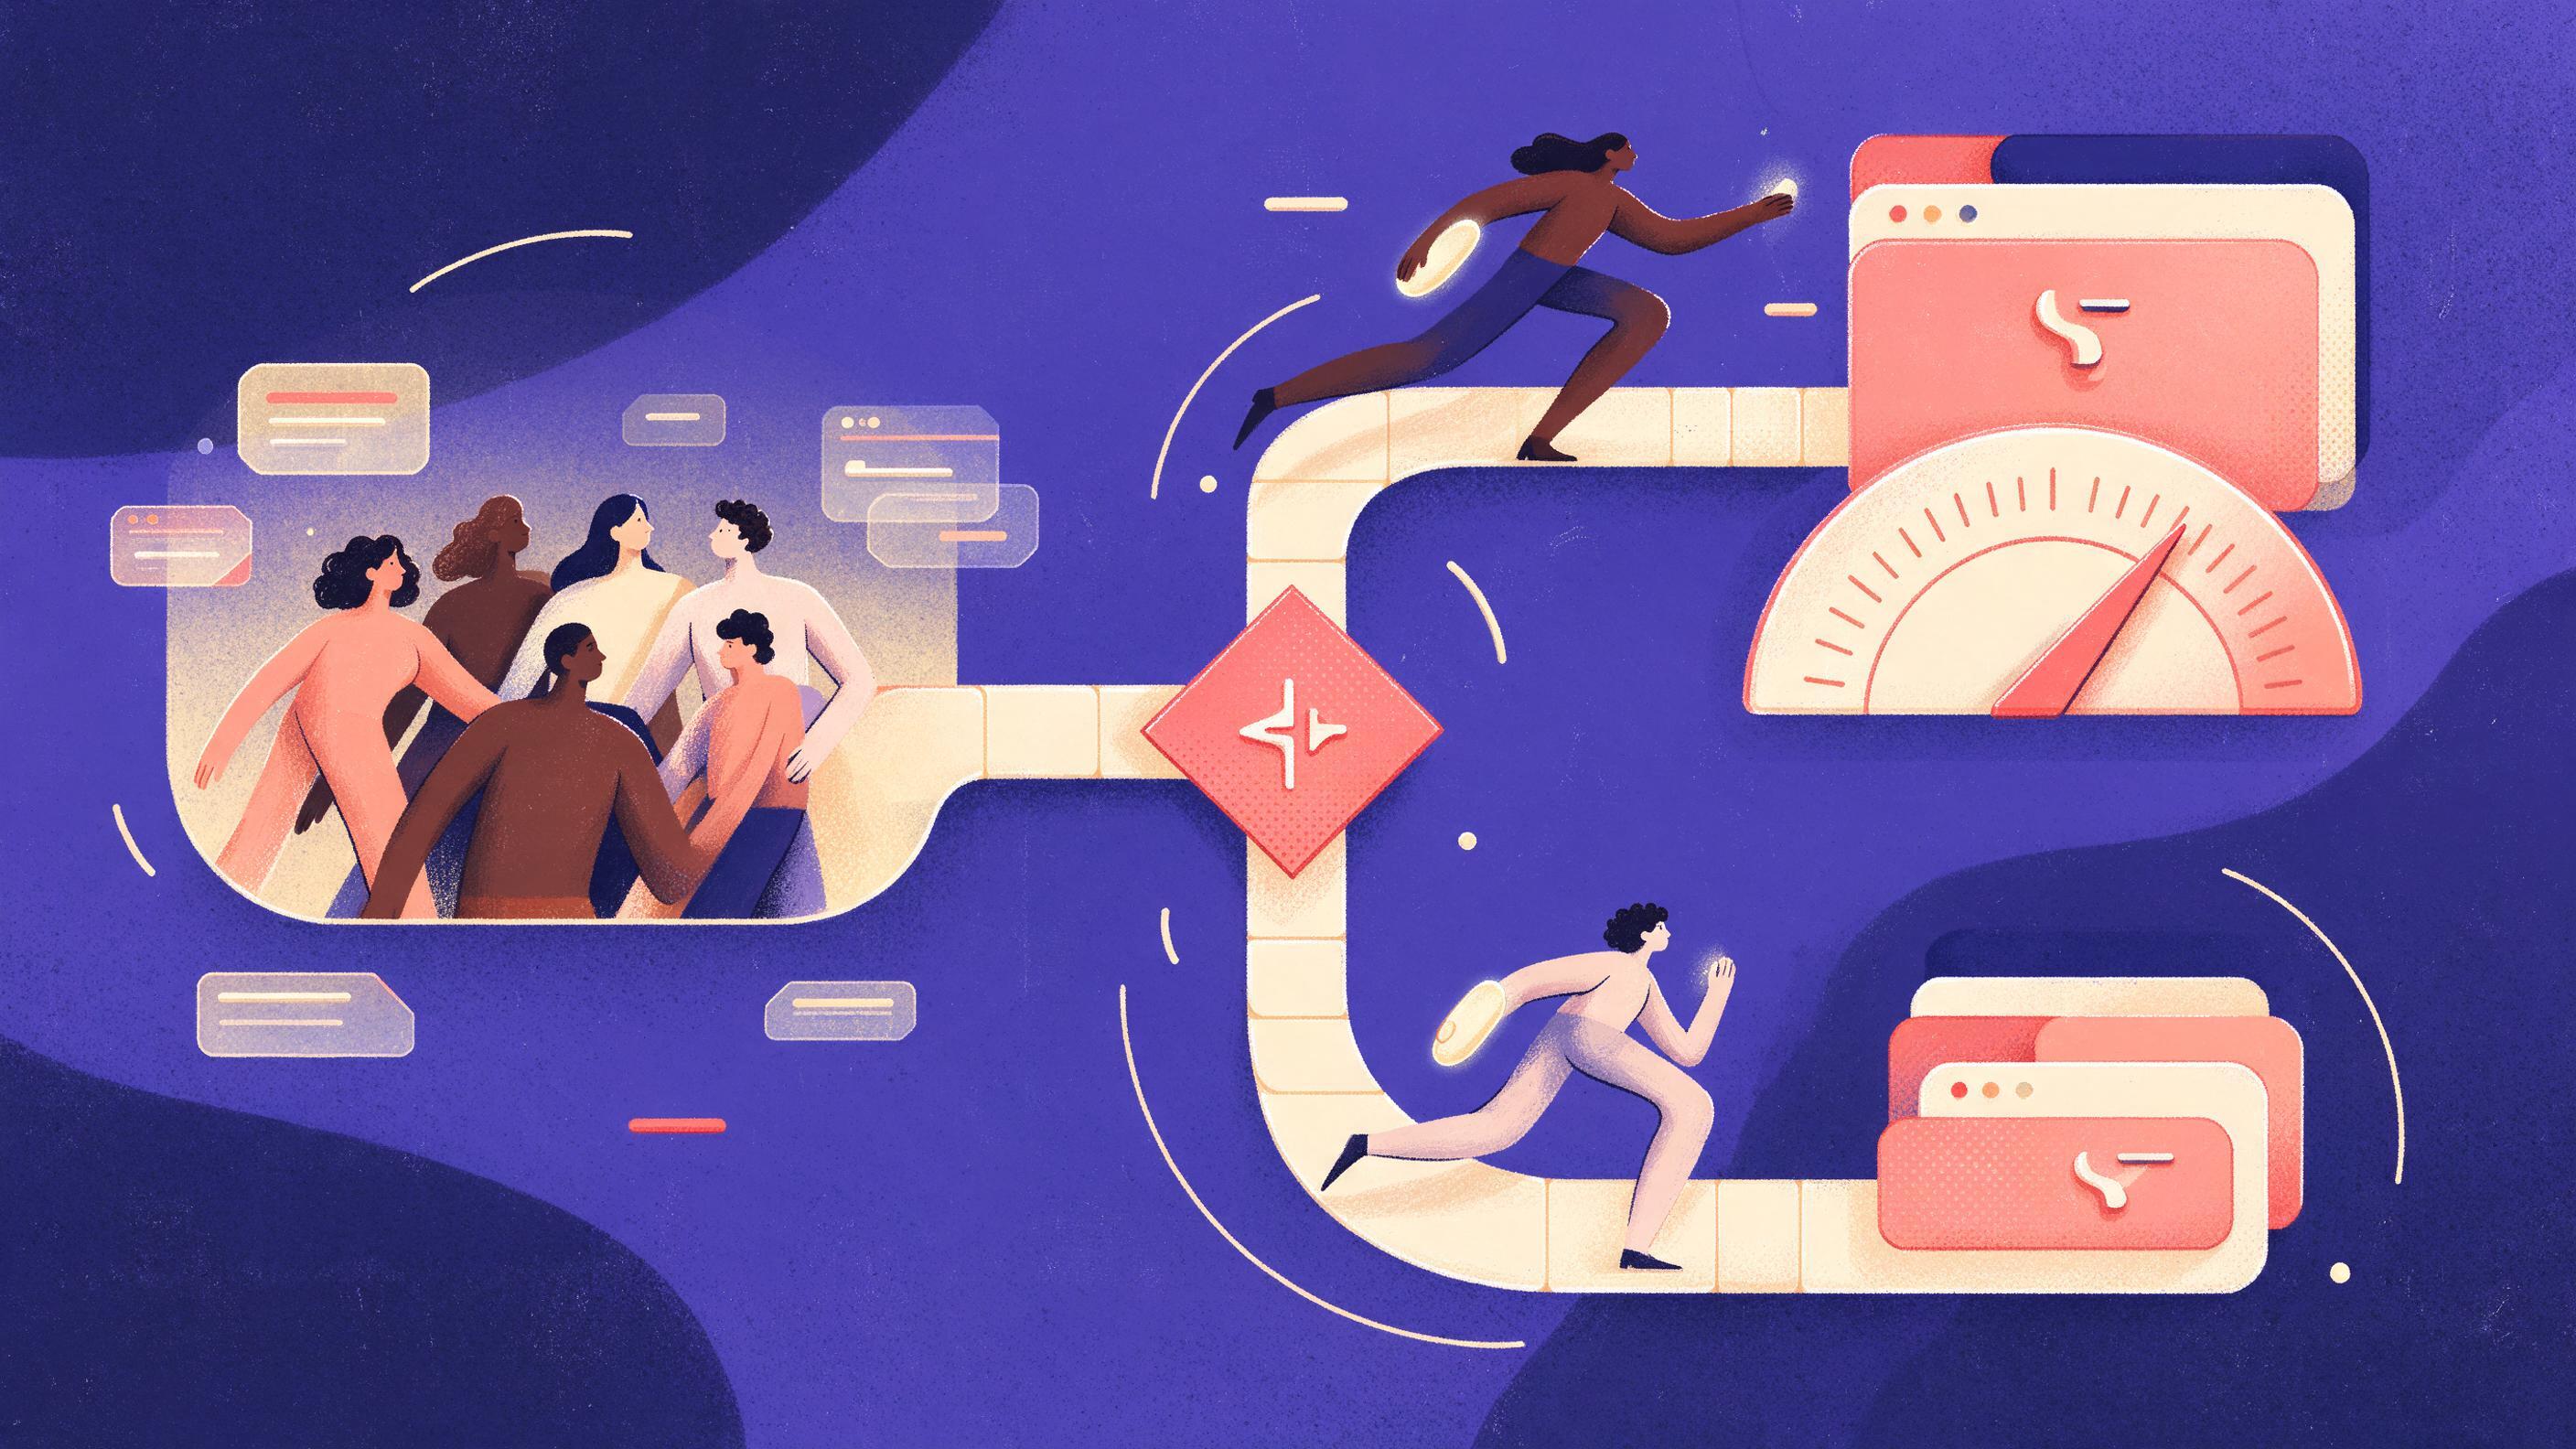
A horizontal pipeline diagram: a request queue splits at a diamond labeled difficulty classifier, with an upper branch to a large reserved model behind a capacity gauge and a lower branch to a small cheap model.
Key points

Key points

  1. 1When committed capacity is exhausted, route overflow by request difficulty so hard prompts keep the reserved model.
  2. 2A cheap classifier scores each request before the switch, and only the easy band reaches the cheaper model.
  3. 3A scoring gate against a frozen golden set decides whether the cheap model's output may leave.
  4. 4Tune the gate threshold and sample rate from measured data, not from a vendor comparison sheet.

Why the reservation runs out before the peak does

A reservation is sized for a baseline, not a peak, and the peak is what breaks the service level agreement. Reserved capacity discounts on ordinary cloud compute typically run 30 to 60 percent against on-demand rates, and they only pay off above a utilization break-even point computed as (1 minus discount rate) times term length per ProsperOps. Buy for peak and you pay for idle capacity most of the month. Buy for average and the peak is the exact moment you have no cover.

AI inference sharpens this because GPU hours cost far more than CPU hours. One infrastructure vendor describes AI traffic peaks running 3 to 10 times average load, and notes that provisioning a dedicated endpoint for a 10x peak means 9 idle GPU hours for every hour of real production per GMI Cloud. Their operational signal is useful: a queue depth above 50 pending requests per GPU indicates incoming traffic has outrun serving throughput, and below that the existing configuration still has headroom.

The model price gap is just as wide. On Bedrock, an older mid-tier model bills at $6.00 input and $30.00 output per million tokens, while a small-model tier sits at $1.00 and $5.00 per Inventive HQ. A comparison sheet tells you the small model is cheaper. It does not tell you what to do at 14:20 on the day the reservation is dry and the queue is 80 deep per GPU. Spilling that traffic to on-demand keeps the expensive model and only changes the billing code; a difficulty router changes the model instead.


The shape of the routing rule

The rule has four parts, and each is a place a naive build fails.

  1. A reservation budget. Track consumed input and output tokens per minute against the committed rate, not a running request count. Bedrock reserved capacity is expressed as a tokens-per-minute rate for one- or three-month terms, and traffic above it spills to on-demand rather than being throttled per Inventive HQ.
  2. A difficulty classifier. Score the request on cheap, deterministic features before any model call.
  3. A routing decision. Hard requests go to the reserved model, easy requests to the overflow model, and unplaceable requests stay reserved.
  4. An evaluation gate. Sample overflow outputs, score them against the golden set, and let the pass rate decide whether overflow stays enabled.

Start the classifier as rules, not a model: prompt length, whether the request asks for code, whether it names several constraints, whether an earlier turn in the session hit a retry, and an allowlist of forgiving endpoints. A learned router beats this once you have labels, but the gate is identical either way, so you can swap the classifier without touching it.

The payoff is real. The RouteLLM study found that sending easy queries to a cheaper model cut costs by over 85 percent on MT Bench while keeping 95 percent of the frontier model's quality per Maxim AI. That also names the risk: the quality you give up is not spread evenly across prompts, and the gate exists to catch the case where it clusters.

Building the golden set and its scorers

A gate is only as good as the set it scores against. The golden set is a frozen, versioned collection of prompts with reference outputs and a scorer for each, built from production traffic rather than public benchmarks. Sample a few hundred real requests over a normal week, stratify by endpoint and by the classifier's own score bands, and hand-label what the reserved model produced. Those become the reference; then score the overflow model on the same inputs with the same scorer.

Golden set ingredientWhat to includeWhy it matters
Easy band samplesBottom third by classifier scoreOverflow handles these most often
Boundary samplesRequests at the cutoffWhere misroutes appear first
Hard band samplesTop third by classifier scoreConfirms the reservation still earns its cost
Format checksOutputs with contractual structureA schema failure is a hard fail, not a rubric debate
Refusal casesPrompts that must be declinedA cheap model that answers these is a liability
Session continuationsFollow-ups with dense prior contextLong context is where small models lose the thread

Keep scorers mechanical where you can: exact match on extracted fields, schema validation on structured output, regex for required content. Rubric scoring with a judge model is expensive and drifts, so pin the judge and re-validate the judge itself whenever the set changes. Freeze the set during a gate cycle, because editing prompts mid-cycle makes a pass-rate drop meaningless. Version the set and record which version each gate result used.

Evaluation tooling exists to do exactly this: hold the set, run scorers, keep results versioned per Braintrust. If you already run evals in CI, reuse the harness and scorers. If not, a small script and a JSON file are enough to start.

Thresholds, sample rates and the flip

The gate has two numbers to tune, both from measurement.

The threshold. Use the overflow model's pass rate on the golden set before you switched any production traffic, minus a safety margin. If the cheap model passed 91 percent and the reserved model passed 97 percent on the same set, 88 percent tolerates small sampling noise while catching a real drop.

The sample rate. You need enough scored outputs per window for a pass rate that is not noise, and 20 scored outputs is the practical floor. At a 5 percent sample, that means roughly 400 overflow requests in the window. Raise the rate during the first week of an overflow event and lower it once the pass rate stabilizes. Scoring every output recreates the expense the cheap model was meant to save.

scored = score_against_golden_set(sample(overflow_window, rate=sample_rate))

if len(scored) < min_scored:
    decision = "hold"            # not enough evidence, keep the last decision
elif pass_rate(scored) >= threshold:
    decision = "overflow_on"     # cheap model may keep serving the easy band
else:
    decision = "overflow_off"    # flip back to reserved, queue the excess

record(decision, pass_rate(scored), len(scored), threshold, sample_rate)

The "hold" branch matters most. A gate firing on 6 scored outputs oscillates every few seconds and produces an outage nobody can reproduce from logs, so make "keep the last decision" the default when evidence is thin. The gate must also flip in both directions: sustained recovery above the threshold brings overflow back, and every flip is logged with the pass rate that caused it.

Now the failure modes. Set the threshold too high and the gate fires on noise, so every overflow event bounces back and queues: a service-level failure dressed up as caution. Set it too low and the gate sits quietly while a cheaper model degrades quality, and you hear about it from users. Start slightly high, count unnecessary flips for a few days, and lower the threshold only when that count is measured and unacceptable.

What the reserved model does with what comes back

A flip-back is not free. The excess returns to a reserved model that is full, so the router needs a queue that does not break the agreement worse than the cheap model would have.

Flip-back behaviorEffect on the SLAEffect on costWhen to use
Queue with a deadlineHolds if the queue drains in timeNone while queuedAlways, as the default
Stricter classifier cutoffSheds marginal loadSlight rise in reserved loadQueue depth past your headroom
Cache backfillImprovesFallsWhenever prompt caching is available
On-demand spillHoldsRises sharplyLast resort, small slice only

Every request carries a deadline, and requests that would miss it get an honest degraded response rather than a silent drop. Cache helps more than most teams expect: repeated prompts within a short window can be served at a reduced rate on the same provider per the AWS Builders guide, and a cache hit never touches the reservation's token rate. Reach for on-demand spill last, and only at the margin, because it keeps the expensive model anyway per Inventive HQ. If spill is more than a few percent of a flip-back window, the threshold is wrong, not the infrastructure.

The capacity literature reaches the same conclusion in different words: reservations pay off only above a break-even, and burst workloads belong on on-demand or spot capacity per OneUptime. The router decides which bursts get the reserved capacity and which go elsewhere.

Worked example: the arithmetic behind a threshold

Take a reservation of 2,000,000 input and 800,000 output tokens per minute. Baseline traffic runs at 55 percent, averaging about 1,200 input and 400 output tokens per request, roughly 900 requests per minute. At 2.5x baseline the reservation is 25 percent over, and about 450 requests per minute overflow.

At the rates cited for a legacy mid-tier model ($6.00 input, $30.00 output per million tokens) per Inventive HQ, each overflow request costs about $0.0072 in and $0.012 out, so $0.0192, or about $8.65 per minute. The small-model tier at $1.00 and $5.00 costs about $0.0012 in and $0.0020 out, so $0.0032 each, or about $1.44 per minute. A 40-minute spike costs about $346 on the reserved model and about $58 on the cheap one.

Now the gate. The overflow model's golden-set pass rate was 91 percent against a threshold of 88 percent. At a 5 percent sample, the spike yields about 22 scored outputs, just above the floor. If they pass at 86 percent, the gate flips and the excess queues: the 40 minutes cost $346 instead of $58, and no user gets a poor answer. If they pass at 92 percent, the saving stands.

The decision rule is that the threshold sits so the expected cost of a false negative (quality degrades, you learn from users) exceeds the expected cost of a false positive (the cheap model was fine, you pay the reserved rate briefly). At a 4 to 5 times price gap, a quality regression costs far more than four minutes of peak traffic, so the threshold belongs confidently above the noise floor.

One asymmetry to plan for: if traffic shifts harder, the easy band shrinks, overflow volume falls and the gate sees fewer scored outputs per window. Set the sample rate as a target count per window, not a fixed percentage, so the gate keeps getting evidence.

Making the classifier good enough to trust

Three rules keep the classifier useful.

Score the request, not the answer. The classifier never calls a model. A classifier on the critical path that calls a model adds latency everywhere and doubles the cost of requests it routes cheaply.

Calibrate against outcomes. Label a few thousand historical requests by whether the reserved model's answer was actually better, then fit the classifier against those labels. Classifiers tuned on gut feel overestimate difficulty, which is safe but expensive.

Re-fit on every flip. Each gate flip is a labeled example of a request the classifier called easy and the scorer rejected. Feed them back. Learned routers need training data and drift as the underlying models change per Maxim AI, and the flip log is the cheapest training data you will get. If you would rather not build the routing plumbing across providers, Quanta Inference puts text, image, video, audio and embedding models behind one API key at https://quantaintelligence.ai/inference, so the overflow policy lives in one place.

FAQ

FAQ

What actually triggers overflow?

A warning line you set in advance, usually 85 to 90 percent of the reserved tokens-per-minute rate, not a full reservation. Routing takes time and the gate needs room to act before the queue builds. Because excess traffic spills to on-demand rather than being throttled per Inventive HQ, the policy has to decide before the spill.

How large should the golden set be?

A few hundred prompts, stratified across the classifier's bands, is enough for a stable pass rate and far more useful than a thousand sampled uniformly. Include the boundary band explicitly, since misroutes concentrate there. Size matters less than freezing and versioning the set.

What keeps the gate from oscillating?

A minimum scored count per window, a hold state when evidence is thin, and a requirement that recovery be sustained for a full window before overflow returns. Without all three, a noisy sample flips every few minutes. Log each flip with its pass rate and sample size so oscillation shows up as a count.

Is this the same as a fallback chain?

No. A fallback fires after the primary errors, times out or rate-limits, and it exists to keep the application up per Maxim AI. Overflow fires before any call, based on capacity and difficulty, and changes which model serves the request. You need both: overflow for planned pressure, fallback for unplanned failures.

Where does an evaluation platform fit?

The gate needs a home for the golden set, the scorers and versioned results, which is the job of an evaluation layer under a router per Braintrust. If evaluations already run in CI, extend that harness to a scheduled production gate. If not, start with a script and a frozen file; the value comes from the discipline of the pass rate, not the tool.

Sources

Sources

  1. Calculate your RI break-even point
  2. Burst Capacity for AI Inference Traffic Spikes - GMI Cloud
  3. AWS Bedrock Pricing Guide: On-Demand vs Provisioned ...
  4. What Is an LLM Router? How Model Routing Works
  5. Best LLM routers and model routing platforms in 2026 - Articles
  6. Understanding Amazon Bedrock Pricing: From On- ...
  7. How to Implement Reserved Capacity with Resource Reservations
About the author

About the author

Antonio Evans
Antonio Evans

Antonio Evans is the founder of Quanta Intelligence and a fractional CTO who builds HIPAA-ready AI systems for health and life-science companies. Before that he was technical co-founder of FriendsEAT for twenty years, CEO of Socialdraft, and a data engineer at IBM. Antonio lives with his dog Santino in Lisbon, Portugal.

All articles
