
Security

Approval Gates for Agents: Which Actions Need a Human

Antonio Evans11 min read

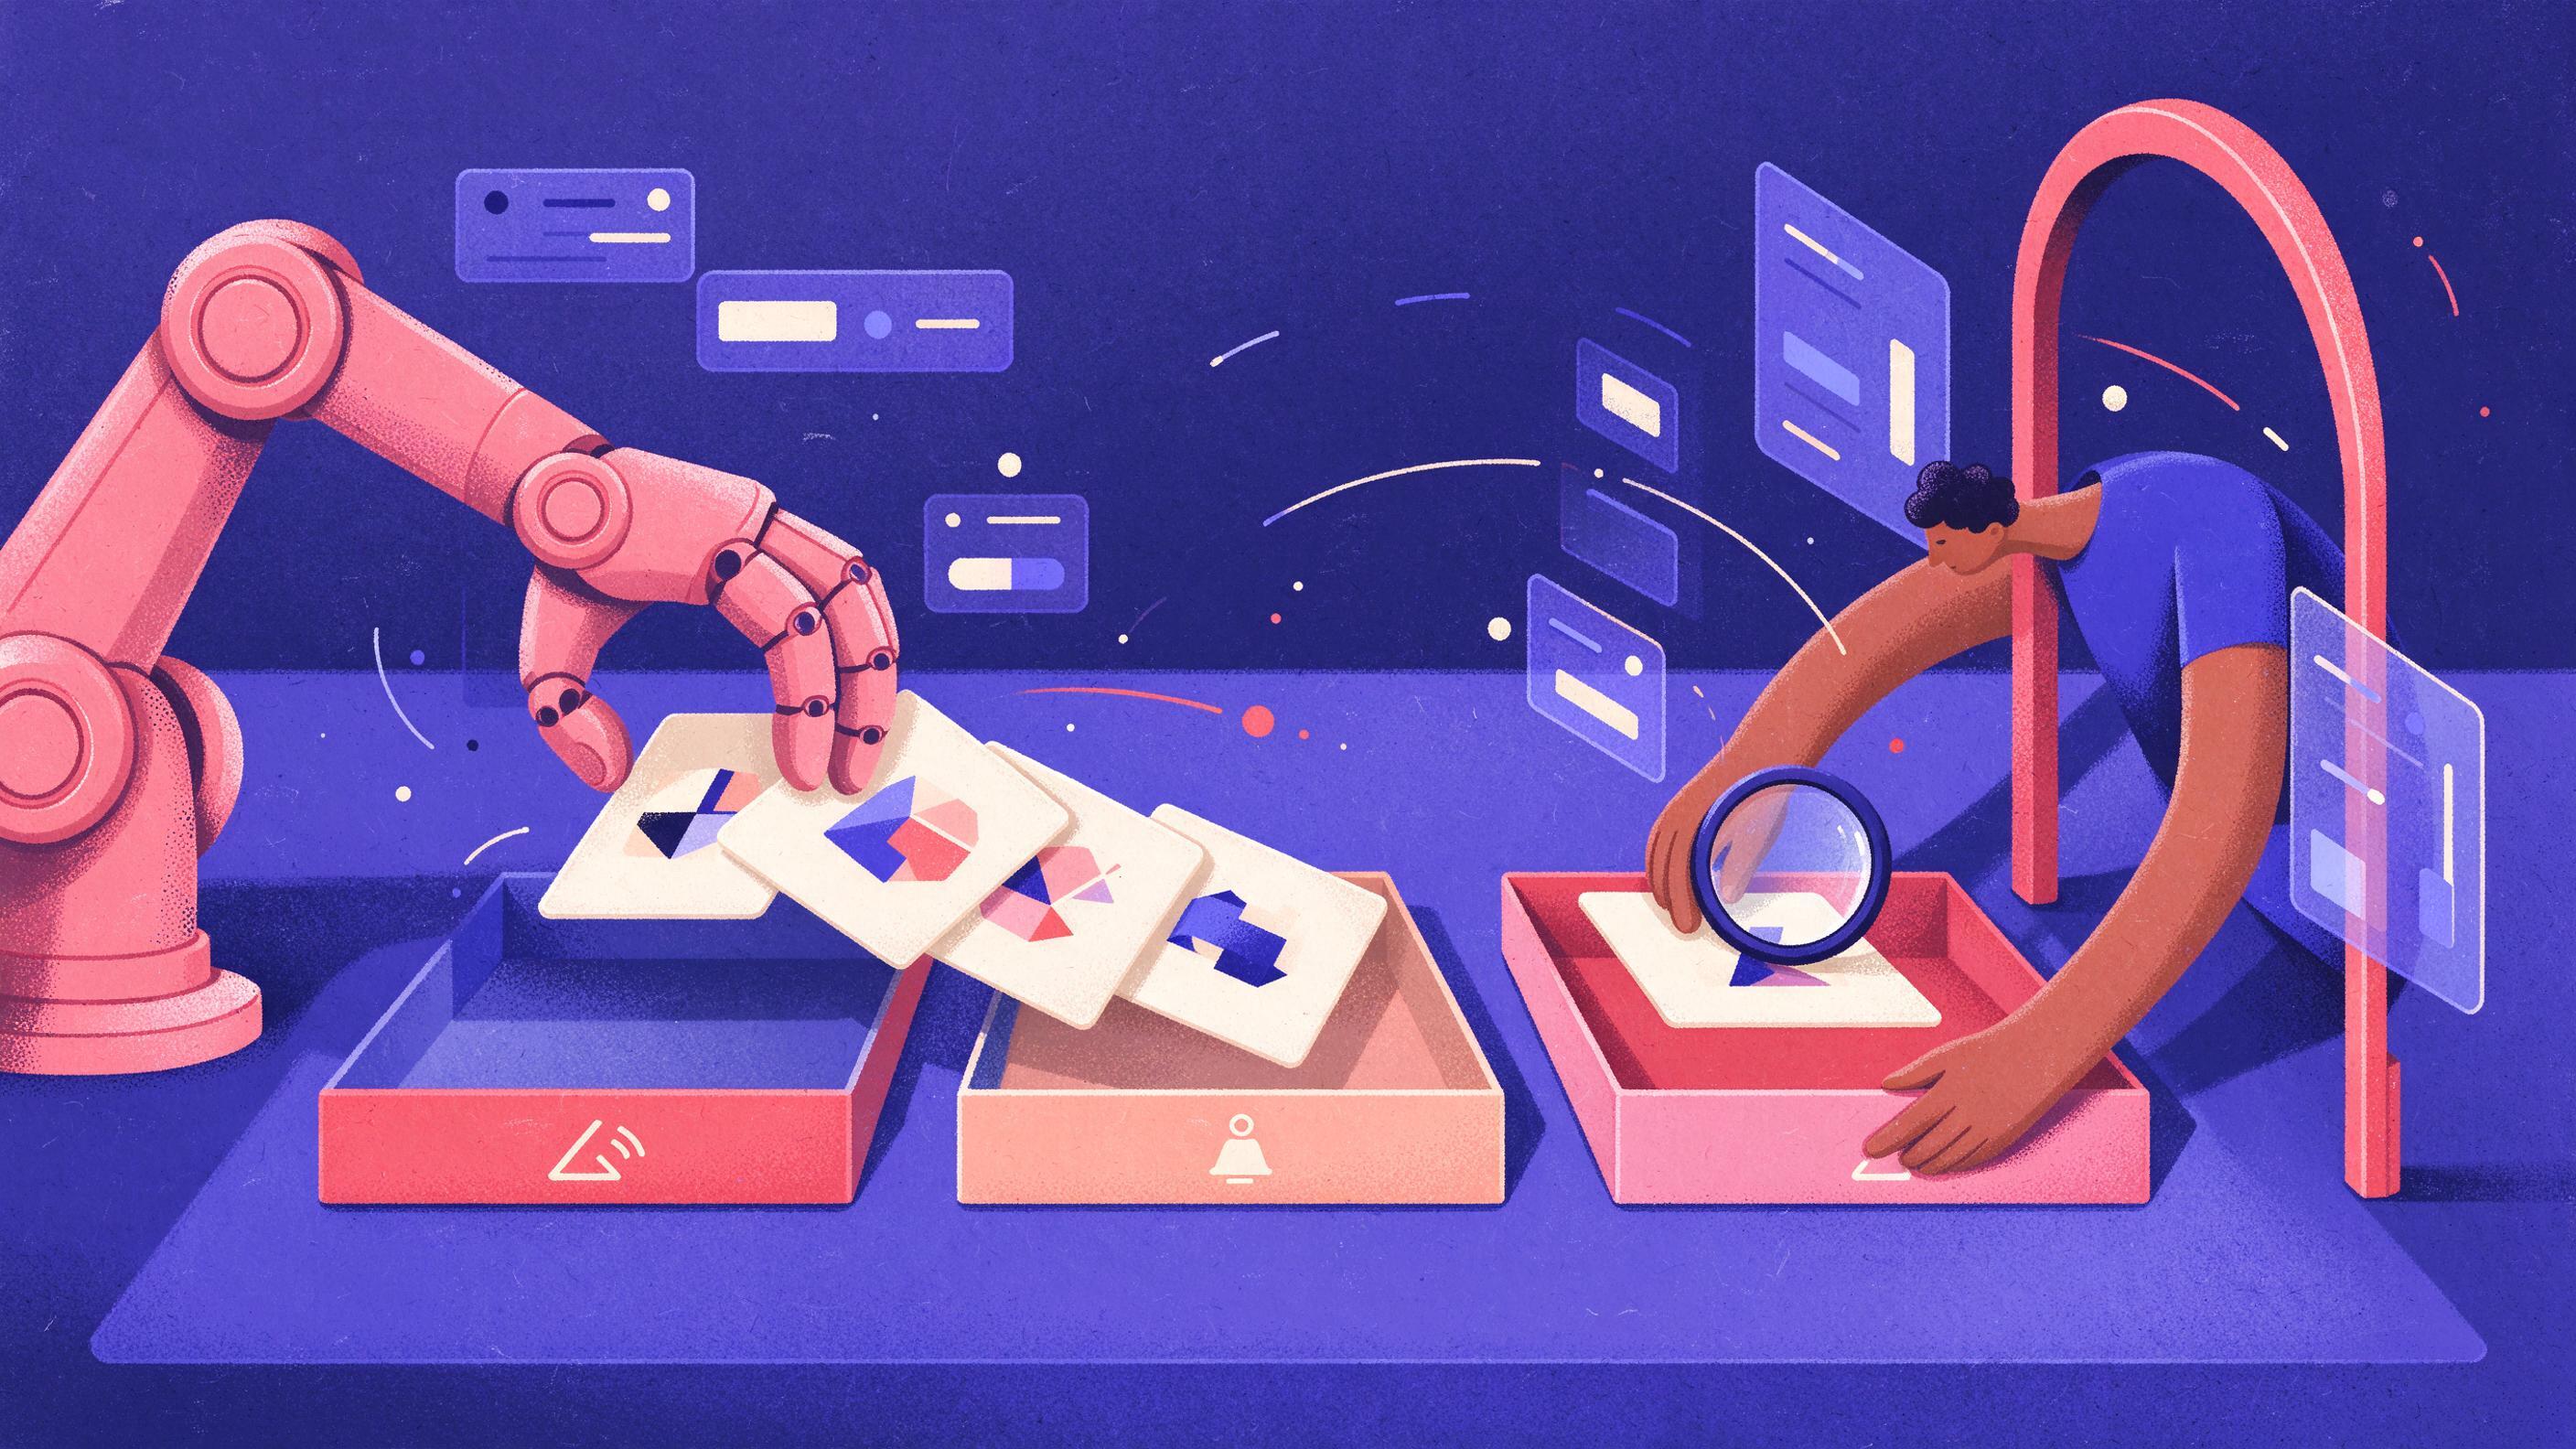
A robot arm fans action cards across a desk into three trays labeled AUTO, NOTIFY and HUMAN, with a person at the HUMAN turnstile reading one card under a magnifier.
Key points

Key points

  1. 1Gate an action when any one of three conditions holds: it cannot be undone within the same working session, it moves more money than your pre-agreed daily loss limit, or it touches more than a set number of records or systems in one call.
  2. 2Prompt injection research shows that instruction filtering alone cannot be relied on, so the approval gate belongs in the execution layer, outside the model's control.
  3. 3The gate that fires on everything trains reviewers to click approve without reading, which is worse than no gate at all because it looks like oversight.
  4. 4Every gate should record what was proposed, what the reviewer saw, who decided and what executed, so the decision is auditable after the fact.

Start from the risk review, not from the agent

A risk review typically ends with a list: here are the tools the agent can call, here is what each one touches, here is what looked dangerous. That list is an inventory, not a policy. The next step is deciding, per action, whether a person must sign off before it runs and what the fallback is when nobody responds.

Two framing mistakes cause most of the trouble. The first is treating human oversight as a switch at the level of the agent: this agent is supervised, that one is not. The second is assuming a well-written system prompt is a control. Neither survives contact with production.

The more useful framing is per action. As one governance write-up puts it, the same support agent might draft replies with no approval, require a human before issuing a refund over a threshold, and be blocked entirely from closing an account: one agent, three different oversight rules (Arthur AI). The unit of decision is the tool call with its arguments, not the agent.

There is a reason the decision has to sit outside the model. LLMs do not reliably separate instructions from data, so any content the agent processes is a candidate instruction (OWASP LLM01). A prompt that says "never delete production data" is a suggestion to a system that reads attacker-controlled text. The approval gate has to be enforced by the component that actually executes the call.


The three-axis test

Score every candidate action on three axes. Each one produces a yes or no, and any yes means the action is gated by default.

Reversibility. Can the effect be undone, and how? Reading a record, drafting a document or querying a log is reversible in the sense that nothing changed. Sending an email to an external party, deleting records, merging to main, changing permissions or submitting a form to a government portal is not: once the side effect leaves your systems, you cannot recall it. As the guidance in the Anthropic-adjacent literature puts it, agents should prefer reversible over irreversible actions and request narrower scope when reversibility is unclear (Scalekit). A practical test: can a competent engineer undo this within the same working session, using tools they already have, without asking anyone outside the team? If not, gate it.

Dollar value. What is the financial exposure if the action is wrong? Not the expected value, the exposure: the amount that leaves the account or is committed before anyone notices. Set a daily loss limit per agent, the same way a trading desk does, and gate any single action that could exceed it. A refund of 40 dollars on a support agent with a 500 dollar daily limit is noise. A wire transfer of 40,000 dollars on an agent with a 2,000 dollar limit is a hard gate. The threshold belongs in the policy, not in the prompt.

Blast radius. How many systems, records or people does one call affect? A single-record update and a bulk update of the same table share an OAuth scope but not a risk profile (Scalekit). Set a cap, for example 100 records per call or two downstream systems per workflow, and gate anything above it. Blast radius also covers people: an action that changes what thousands of customers see is gated even if each individual write is cheap.

AxisQuestionGate ifAutomatic if
ReversibilityCan it be undone this session?No (external email, delete, merge to main, permission change, portal submission)Yes (read, draft, internal note, ticket comment)
Dollar valueWhat leaves or is committed if wrong?Above the agent's daily loss limitWithin the limit and under the per-action cap
Blast radiusHow many records, systems or people?Above the record cap or touching more than the allowed number of systemsOne record, one system, internal audience
Data sensitivity (tiebreaker)Does it expose or modify PII, financial or health data?Yes, and the destination is outside the trust boundaryYes, but confined to an approved internal system
Autonomy (tiebreaker)Long unattended chain or low confidence?Yes, add a checkpoint even if each step looks minorShort chain, high confidence, known path

The two tiebreakers matter because the three main axes occasionally miss. Data sensitivity raises the bar even when dollar value is zero: reading customer records and sending a summary to an external address is an exfiltration event, not a spend event. Autonomy raises the bar because compounding errors across a multi-step workflow are a distinct risk class (Frontier Model Forum). If the agent has been running for forty steps without a human touch and is about to take its first write, add a checkpoint regardless of the other scores.

The decision rule, stated plainly

Gate an action when any one of three conditions holds:

  1. It cannot be undone within the same working session.
  2. It can move more money than the team's pre-agreed daily loss limit.
  3. It touches more than the set number of records or systems in one call.

Everything else runs automatically with a notification. Hard gates in practice: sending email or messages to external parties, deleting or overwriting data, merging to main, changing permissions or IAM, and submitting forms to government portals. Payments above the loss limit. Any action whose blast radius exceeds the cap.

Notice what is not on the list. Reading, searching, summarizing, drafting, opening a ticket, posting to an internal channel. OWASP's agent security guidance groups these differently: read-only access gets no gate, reversible low-impact actions get notification only, production changes get one approval, and destructive or irreversible actions get two approvals, including the service owner (vibraniumlabs). That tiering is a good default to copy, and it is compatible with the three-axis rule: the axes decide the tier, the tier decides the gate depth.

Here is the same rule as pseudo-code. The important property is that it lives in the execution layer and returns a deny when anything is unknown.

def decide(action, policy):
    # Fail closed on anything unrecognized
    if action.tool not in policy.known_tools:
        return "deny"
    if action.irreversible:
        return "gate_two" if action.destructive else "gate_one"
    if action.amount_usd > policy.daily_loss_limit:
        return "gate_two"
    if action.records > policy.record_cap or action.systems > policy.system_cap:
        return "gate_one"
    if action.contains_pii and action.destination outside_trust_boundary:
        return "gate_one"
    return "notify"

Two details in that snippet carry most of the weight. First, gate_two for destructive actions: dropping or migrating data, deleting resources, rotating credentials and changing IAM get two approvers, in line with the four-tier model above. Second, known_tools as an allowlist: unknown tools fail closed rather than defaulting to running. The Verification Cheat Sheet in OWASP's agent guidance puts it directly: fail closed for unknown tools or missing approval requirements, and check and consume the approval in one atomic step immediately before execution so it cannot be reused (OWASP AI Agent Security).

That atomic-consume rule matters more than it looks. A user_confirmed: true flag passed through the agent's context is not an approval; it is a string the model can produce. The approval has to be a record created by the reviewer, bound to the exact tool call and arguments, validated by the executor, and burned on use.

Worked example: a support agent

Take a support agent that can read tickets, draft replies, send replies, issue refunds, update customer records and close accounts. Assume a daily loss limit of 500 dollars and a record cap of 50.

ActionReversibilityDollar / blast radiusDecision
Read ticket historyReversible0 dollars, 1 ticketAutomatic, log only
Draft replyReversible0 dollars, 1 ticketAutomatic, no notification
Send reply to customerIrreversible0 dollars, 1 personGate one, approve before send
Refund 30 dollarsPartly reversible (chargeback)30 dollarsAutomatic, notify, and recheck daily total
Refund 380 dollarsPartly reversibleCumulative near limitGate one
Refund 900 dollarsIrreversible at scaleAbove daily limitGate two
Tag 12 ticketsReversible12 records, under capAutomatic, notify
Bulk-update 200 recordsHard to reverse200 records, over capGate one, require dry-run diff
Close accountIrreversible1 person, contract-endingGate two

Now count the queue. If this agent handles 400 tickets a day with roughly one reply each, the send gate fires 400 times a day. That is not a queue, it is a rubber stamp with extra steps, and reviewers will start approving without reading within a week. The fix is not to remove the gate, it is to change what sits behind it: auto-send drafts that pass a deterministic check (recipient is the ticket requester, content matches the draft the agent proposed, no new external addresses), and gate only the ones that fail the check. The gate stays in policy; the volume drops to the cases that actually need judgment. Arthur's guidance names this failure mode explicitly: if a gate fires so often that reviewers stop reading, the threshold or the routing is wrong (Arthur AI).

The numbers also show why the axes are better than a flat rule. Reversibility alone would gate every send and leave the 900 dollar refund to a rule you forgot to write. Dollar value alone would miss the bulk update. You need all three.

Designing the queue so the gate means something

A gate is only as good as what happens when it fires. Four design decisions determine whether the queue produces judgment or clicks.

What the reviewer sees. The request must carry the agent, the requesting user, the tool, the target resource, the data involved and the expected result (ThreatLocker). For a bulk update, show the diff: which 200 records, which fields, before and after. For a payment, show the destination and the invoice it maps to. A reviewer asked to approve "update records" cannot form an opinion; a reviewer shown 200 name changes from a source the agent did not previously use can.

When approval expires. The credential valid at pause time is not guaranteed to be valid at resume time, and the state that made the action safe may have changed while the request sat in the queue (Scalekit). Revalidate before executing: does the approval still match the current arguments, is the reviewer still authorized, has the daily total moved? If any of that changed, request a new decision rather than executing a stale yes.

Timeout behavior. Deny by default. An approval that times out into execution is a gate that does not exist. Route by risk and domain so the right person sees the decision, and set an escalation path after the timeout rather than a silent pass.

Decision types. Approve and reject are not enough. Allow modify (the reviewer adjusts the arguments) and escalate (the reviewer cannot judge and hands it up). Both keep the workflow moving without weakening the control, and both need their own log events.

Audit the gate itself, not just the agent

The audit trail is what turns human oversight from a UI feature into governance. Every approval, denial, override and timeout should be logged as an event with the context behind it: what the agent proposed, what the reviewer saw, who decided, and what executed (Arthur AI).

Four fields that most implementations leave out:

  • Human approval information: reviewer identity, review timestamp, the risk flag that triggered the gate, and the outcome. Without this, you cannot answer "who authorized this" six months later (Runlayer).
  • Agent configuration: the model and policy version in force at the time of the action. Policies change; the record has to show which one applied.
  • Access control flow: the user role and agent role, or the policy sequence, that permitted the call. If a privilege escalation happens later, this is how you find the gap.
  • Tamper evidence: append-only storage with cryptographic chaining, because mutable logs fail a basic chain-of-custody test (Digital Applied).

Record a policy outcome separately from enforcing it. A log line saying "action denied" proves the decision was made, not that execution was blocked; the enforcement point must be the same component that writes the log entry, or the two can disagree.

Alert on sequences, not single calls. Clustered policy denials suggest something is probing the boundaries. A spike in tool-call volume, sensitive-data access outside the agent's normal scope, or intent drift (actions stop matching the assigned task) are all better signals than one unusual call (Runlayer).

Where approval gates are not enough

A gate is a control for a decided action, not a substitute for constraining what the agent can reach. The lethal trifecta framing is useful here: when an agent combines access to private data, exposure to untrusted content, and an outbound communication path, an attacker can chain them to exfiltrate (Simon Willison). The gate catches the final send, but only if the send is gated; if the exfiltration rides out through an image URL or a webhook the policy classified as harmless, no queue sees it.

The layered answer is to assume injection will happen and reduce what a successful one can reach: least privilege on tools, short-lived credentials, information flow control so untrusted content cannot reach critical planning, and human verification for risky actions as the last line (Microsoft Learn). Design patterns that constrain what an agent can do at all, rather than relying on it to choose correctly, trade some utility for provable resistance (the design patterns paper). Approval gates sit inside that stack, not above it.

A useful review pass: for each gated action, ask whether an injection in the content the agent reads could produce an action that passes the rule as automatic. If yes, either the tool does not need to exist in that agent's set, or the rule needs tightening. The specific vectors to think about are the ones documented repeatedly in the wild: hidden instructions in emails and documents, in commit messages and issue descriptions, in web pages and in metadata (OWASP Cheat Sheet).

If you are wiring an agent that touches several model providers, keeping one execution layer with one policy file is easier than duplicating the gate per vendor; Quanta Inference puts text, image, video, audio and embedding models behind one API key, so the approval logic stays in one place (https://quantaintelligence.ai/inference).

A short rollout sequence

  1. List every tool the agent can call with its arguments, and mark each read, reversible write, or irreversible/destructive write.
  2. Set the two numbers: a daily loss limit per agent and a record/system cap per call. Write them down; they are policy, not settings.
  3. Apply the three-axis rule to the list, plus the sensitivity and autonomy tiebreakers. Produce a decision per tool.
  4. Move enforcement into the execution layer. Allowlist tools, fail closed, bind approvals to exact arguments, consume on use.
  5. Design the request payload and the queue routing. Estimate volume per day per gate; if any gate exceeds what a reviewer can genuinely read, add a deterministic pre-check rather than removing the gate.
  6. Log every request, decision and execution with reviewer identity and policy version. Set sequence-level alerts.
  7. Run a tabletop: can an injected instruction in a support ticket trigger an action that passes as automatic? Tighten until the answer is no.

If the third step keeps producing "we are not sure," that is the moment a structured second opinion pays for itself. A free 30 minute discovery call walks through your action list and the numbers you have not agreed on yet (https://quantaintelligence.ai/calendar).

FAQ

FAQ

Should every write action require approval?

No. A write that is reversible within the session, within the daily loss limit and under the blast radius cap can run with a notification. Gating everything recreates the manual process the agent was supposed to replace, and reviewers respond by approving without reading (Arthur AI). Reserve pre-execution gates for irreversible, high-value and wide-blast actions.

Can the gate live inside the agent's prompt?

No. Prompt instructions guide but do not constrain a model that reads attacker-controlled content, and indirect prompt injection is well documented in production systems (Microsoft Learn). The approval must be verified and consumed by the execution component, outside the model's context, in one atomic step before the call runs (OWASP AI Agent Security).

What happens when nobody approves in time?

Deny and escalate. If no approver responds within the window, the action should fail closed rather than proceed, and the escalation path should name who picks it up next (Arthur AI). An approval that times out into execution is indistinguishable from having no gate at all.

How do I pick the loss limit and the record cap?

Start from what the team already tolerates in manual work. If an engineer can approve a refund up to 200 dollars without asking anyone, that is a defensible starting limit for the agent. The record cap should be the largest bulk operation a reviewer can actually verify from the diff; if nobody can check 500 records in a sitting, the cap is lower than 500. Tune both with telemetry after a month.

Is a human-on-the-loop model ever acceptable for writes?

For reversible, low-value writes, yes: let the agent act and give the reviewer an undo window with a notification. For irreversible or destructive actions, no. The distinction is whether a person can block the action before it runs; if they cannot, the agent is not human in the loop, whatever the dashboard suggests (vibraniumlabs).

Sources

Sources

  1. Human-in-the-Loop Governance for AI Agents - Arthur AI
  2. LLM01: Prompt Injection - OWASP Gen AI Security Project
  3. Human-in-the-Loop Tool Calling: Approval Gates for AI ...
  4. Emerging Security Practices for AI Agents - Frontier Model Forum
  5. should an AI agent have production access?
  6. AI Agent Security - OWASP Cheat Sheet Series
  7. What should require human approval when using AI agents?
  8. AI agent audit trails: audit log best practices
  9. Agent Audit Trail Design: 7 Best Practices for 2026
  10. The lethal trifecta for AI agents: private data, untrusted content, and ...
  11. Defend against indirect prompt injection attacks | Microsoft Learn
  12. Design Patterns for Securing LLM Agents against Prompt Injections
  13. LLM Prompt Injection Prevention - OWASP Cheat Sheet Series
About the author

About the author

Antonio Evans
Antonio Evans

Antonio Evans is the founder of Quanta Intelligence and a fractional CTO who builds HIPAA-ready AI systems for health and life-science companies. Before that he was technical co-founder of FriendsEAT for twenty years, CEO of Socialdraft, and a data engineer at IBM. Antonio lives with his dog Santino in Lisbon, Portugal.

All articles
