
AI coding

Budgeting a Full Mutation Run

Antonio Evans11 min read

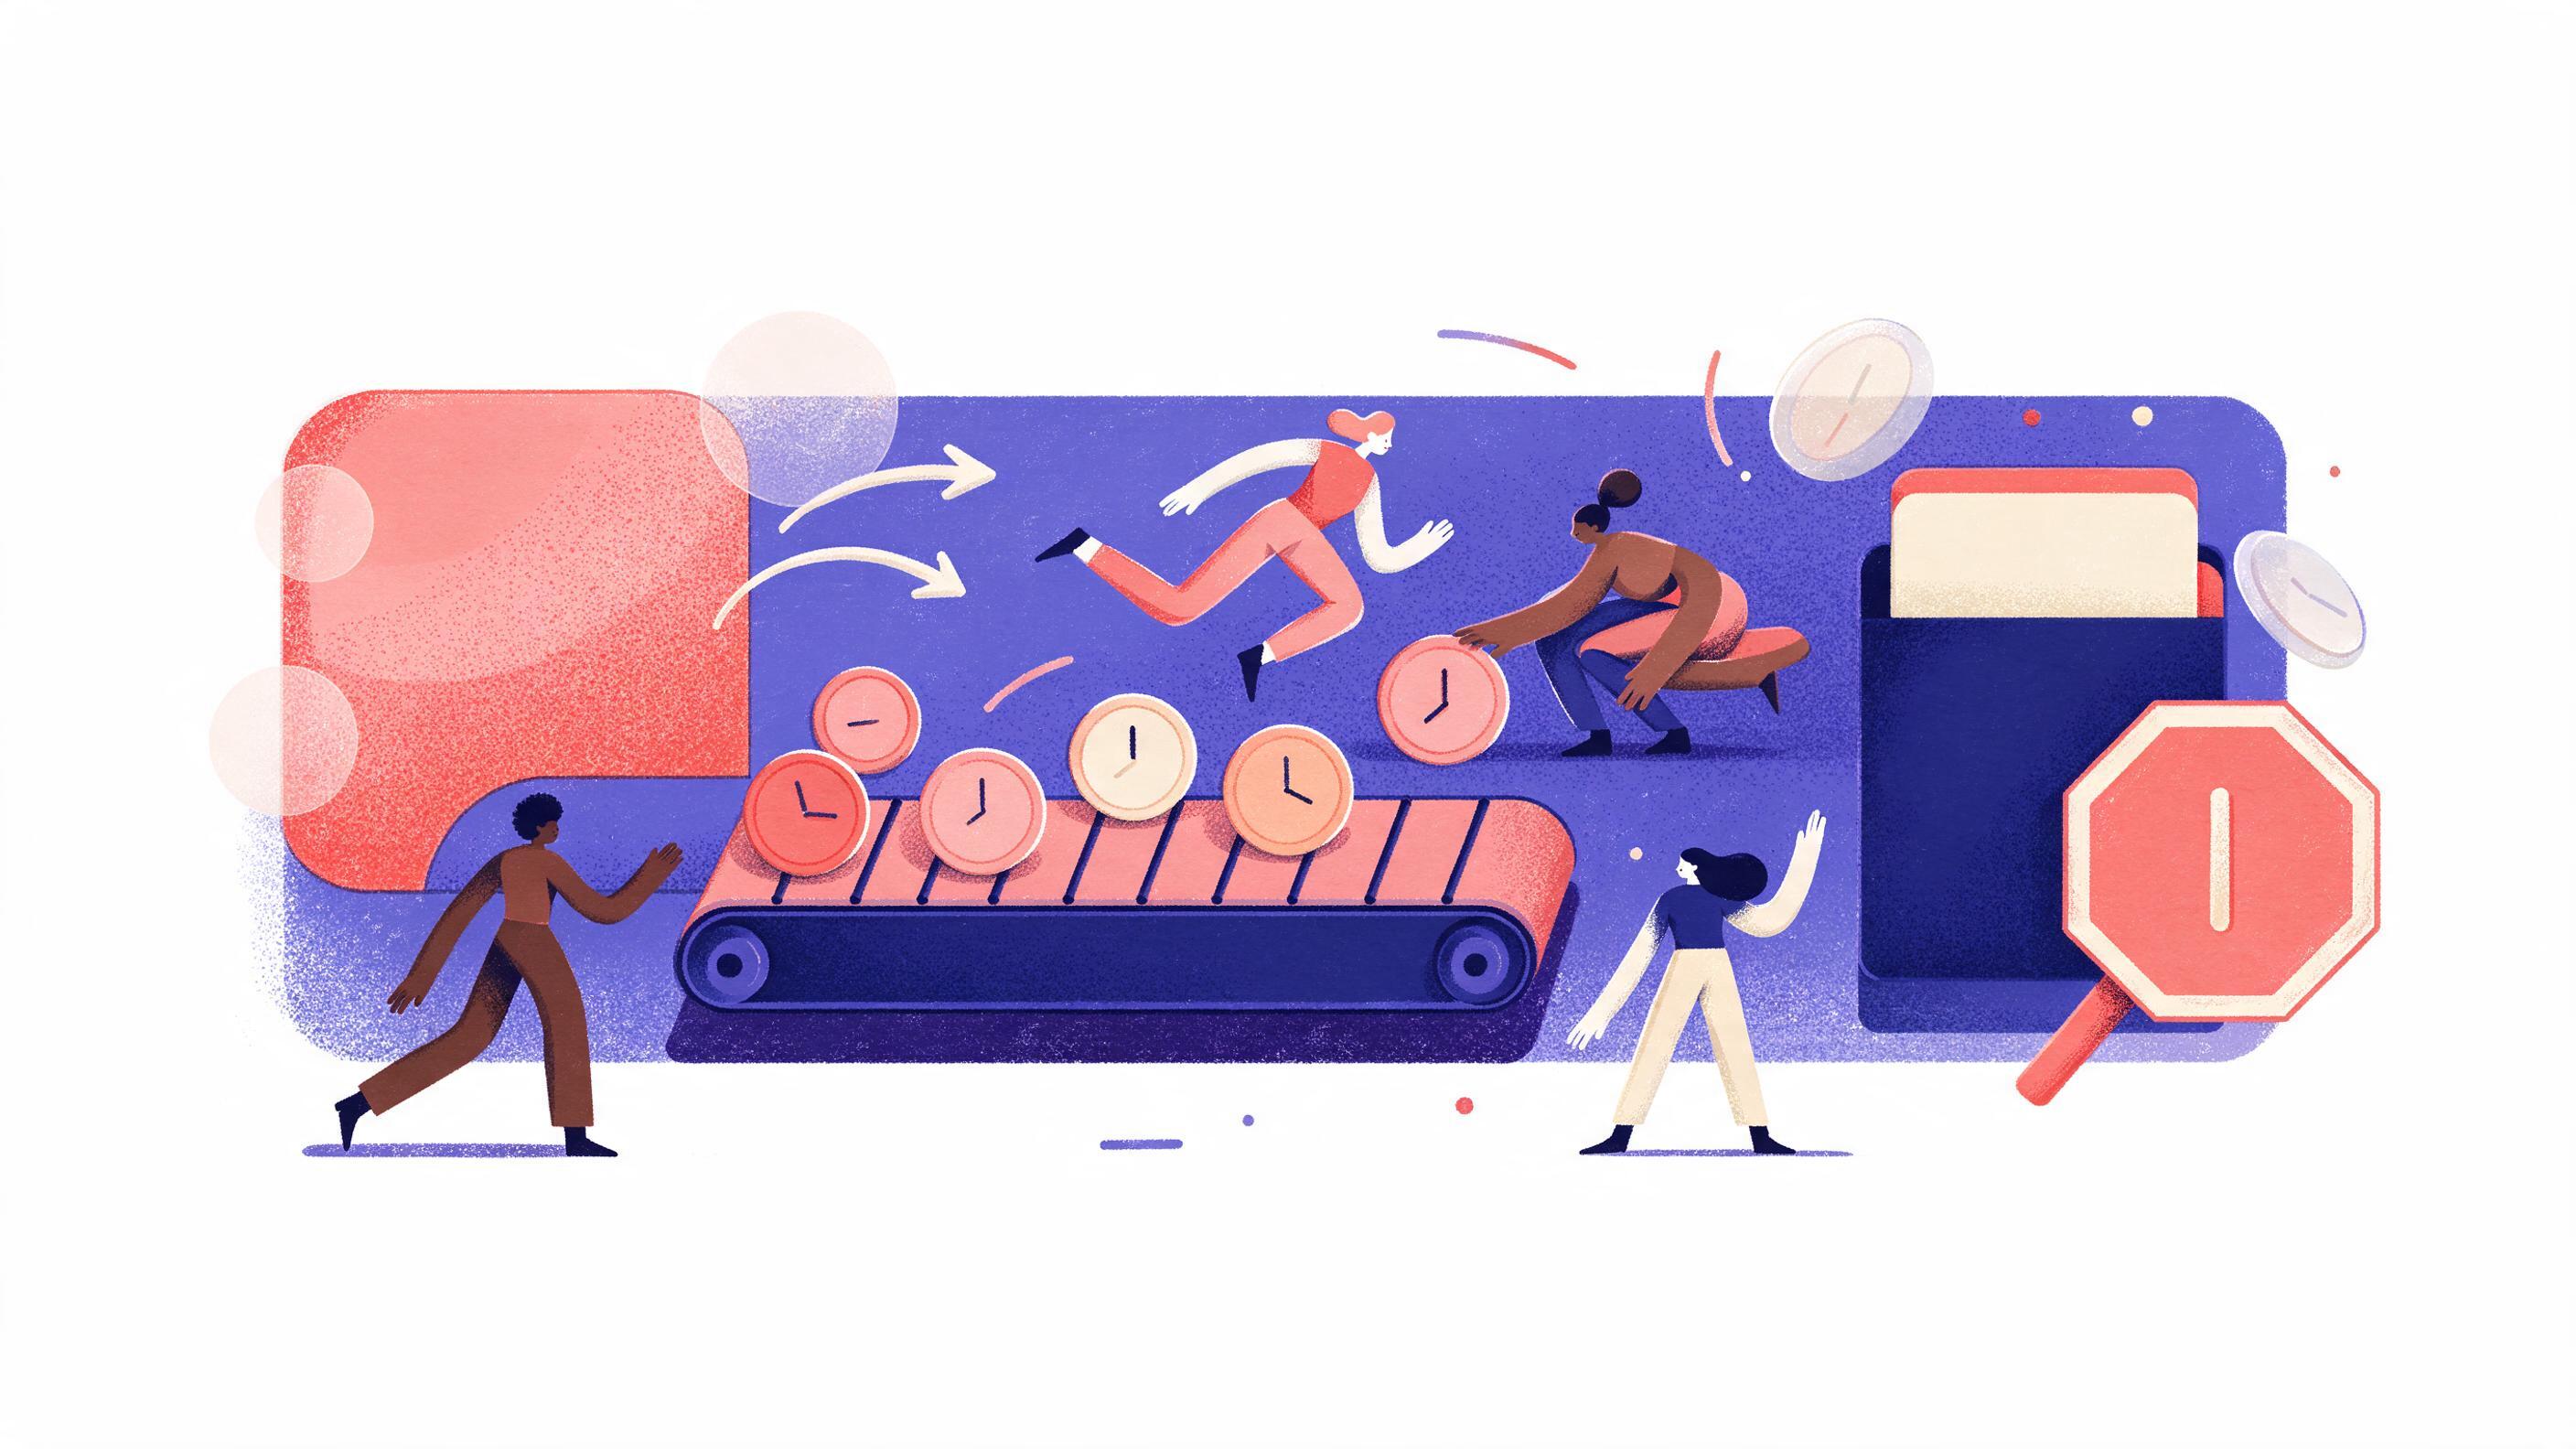
A flat vector diagram on white: a function block with 'mutants: 42' on the left, a conveyor belt with timer icons in the middle, and on the right a CI bill meter with a cap line and a stop sign labeled 'stopping rule'.
Key points

Key points

  1. 1Budget a full mutation run as mutants multiplied by average runtime per mutant, then divide by parallel workers to get wall-clock CI minutes.
  2. 2Full runs belong on a nightly or weekly schedule, while pull requests should get a narrow, incremental slice of mutants.
  3. 3Cap spend with hard timeouts, a concurrency ceiling and a mutation scope that excludes static mutants and uncovered lines.
  4. 4Apply a stopping rule: stop writing tests for surviving mutants when the marginal cost per killed mutant exceeds the risk the test would retire.

Build the cost model before you turn the tool on

Mutation testing is expensive because each mutant needs a test run, and the number of mutants scales with the size of the code you mutate. The CircleCI introduction to mutation testing describes the loop plainly: the tool generates one mutant per applied operator at each eligible location, then runs the suite against each mutant and classifies the result. Every one of those runs consumes the same machine resources as a normal test execution.

So the arithmetic has three inputs. The first is the mutation scope: how many functions or files you hand to the tool. The second is the mutant density, or how many mutants the tool generates per function. The third is the average time a test run takes once a mutant is active. Multiply them and you have raw test-execution time, which you then divide by the number of parallel workers your CI budget permits.

A useful unit of account is the function-minute: how many CI minutes one function costs when fully mutated. If a service has 240 functions that average 6 mutants each, you have 1,440 mutants. If a full test pass takes 40 seconds per mutant and you run 8 workers, wall-clock time is 1,440 × 40 / 8 = 7,200 seconds, or 2 hours. That single line of arithmetic tells you more about feasibility than any benchmark you will read online, because it uses your numbers.

Two properties make the raw number worse than it looks. First, mutation testing needs a green baseline before it starts, and every tool performs a dry run to discover tests and per-test coverage; the StrykerJS incremental documentation states that the dry run remains required even in incremental mode. Second, static mutants (mutants in code that executes once at startup rather than during tests) cannot be activated per test and may need a fresh environment per mutant. The Stryker team documents this as a "big performance impact" and notes that Stryker4s simply ignores static mutants by default, while StrykerJS offers an --ignoreStatic flag (static mutants). Ignoring them is usually the correct budgeting decision.

Here is a template spreadsheet row you can reproduce for each module:

InputHow to get itExample
Mutated functionsCount functions in scope240
Mutants per functionOne trial run on a sample6
Total mutantsFunctions × mutants per function1,440
Seconds per mutantTime a filtered test pass40
Parallel workersCI concurrency cap8
Wall-clock minutesMutants × seconds / workers / 60120
Dry-run overheadMeasured baseline pass4
Realistic budgetWall-clock plus 25% headroom155

The headroom matters. Survivors that time out, mutants that hang, and runners that restart all consume minutes you did not model.


Measure mutant density on a sample, not the whole repo

You do not need a full run to estimate cost. Pick three modules of different shapes (a pure utility, a handler with branching, a module with heavy setup) and run mutation testing on each with a hard timeout. Record mutants generated, wall-clock seconds, and the number of surviving mutants. Scale linearly from there with a caveat: density rises with the number of decision points, so a module full of conditionals will generate proportionally more mutants than a thin wrapper.

The Bitcoin Core project publishes an instructive real-world datapoint. Its contributor write-up on incremental mutation testing in Bitcoin Core reports a weekly run against master that "takes over 30 hours on our current setup," and attributes most of that cost to functional tests, where a single test can exceed one minute, meaning 20 mutants alone can require at least 20 minutes. The same post lists the levers the maintainers are pulling: avoid equivalent and redundant mutants, run only the tests required for each mutant, skip files nobody touched, and skip lines with no test coverage. That list is effectively a budgeting checklist, and it comes from a project that mutates carefully rather than broadly.

For a smaller team, the sample approach gives you a defensible number within an afternoon. If your sample shows 5 mutants per function at 30 seconds each, and you have 400 functions in scope, that is 2,000 mutants and roughly 16.7 hours of serial work. Divide by 10 workers and it is 100 minutes of wall-clock time. Whether that is acceptable depends entirely on when you schedule it.

Schedule: narrow on pull requests, wide on a timer

The single most common budgeting mistake is putting a full run on every pull request. A pull request changes a handful of lines. The full run tests the entire codebase regardless. You pay the full price to learn something about code that did not move.

Split the schedule into three tiers with different scopes and different budgets.

TierTriggerScopeTarget wall clockBlocks merge
Diff runEvery pull requestMutants on changed lines onlyUnder 10 minutesYes, on score
Module runMerge to mainMutated modules plus their dependentsUnder 30 minutesNo
Full runNightly or weekly timerEntire scope, incremental cache onOvernight windowNo, reports only

Diff-scoped selection is the same idea as diff coverage: compute which lines the change touched and mutate only those. The diff-cover tool applies this principle to coverage, reporting the percentage of new or modified lines covered by tests, on the argument that "if you touch a line of code, that line should be covered" (diff-cover on GitHub). The Open edX retrospective on diff-cover gives the reason this works so well: global coverage barely moves on a single pull request, so per-diff measurement creates a clear, achievable standard instead.

Incremental mode is the second half of the scheduling answer. StrykerJS tracks changes to code and tests and reuses previous results where a killed mutant's culprit test still exists and is unchanged, or where an unkilled mutant is untouched and no new test covers it. The tool reports reuse in the console, in a form like "3731 of 3965 mutant result(s)," meaning only 234 mutants need to run in that pass (announcing incremental mode). That is roughly a 94% reduction in mutant executions from reuse alone, with no change to the final report. The same page lists the limitations you must plan around: changes to files outside mutated files and test files are not detected, some test runners report only test names, and static mutants have no runtime coverage so test changes are invisible for them. Schedule a forced full run on a cadence to resynchronize.

The Bitcoin approach of a weekly run on master is a reasonable default for medium codebases, because the report is a backlog of test improvements rather than a merge gate. Reports work best when someone owns the backlog. A surviving mutant is an instruction: either the assertion is missing, or the code is meaningless. The mutation-testing guide for AI-generated code describes mutation score as a review signal rather than a coverage number, which is the right posture for a nightly report: triage and assign, do not block.

Cap the spend with timeouts, concurrency limits and scope

Estimates are not caps. Set a hard ceiling in three places.

The first is a per-mutant timeout. Mutants that cause infinite loops get classified as timed out; Stryker's documentation counts them as killed, while other tools classify them separately. Either way, a mutant that runs for 10 minutes has burned your budget on a result you did not want. A per-mutant timeout slightly above your slowest legitimate test pass is the right setting.

The second is a total job timeout. Give the mutation job a duration slightly above your realistic budget (the table row above includes 25% headroom) and treat hitting it as a signal to shrink scope, not to retry. A job that runs to the timeout every night is telling you the mutation scope is too wide.

The third is a concurrency cap. Parallel workers reduce wall clock but multiply the rate at which you consume minutes and saturate shared runners. If other CI jobs queue behind mutation testing, you have moved the cost, not capped it. Decide the worker count from your bill, not from available cores.

Timeout configuration in a StrykerJS config file looks like this:

{
  "timeoutMS": 60000,
  "concurrency": 6,
  "ignoreStatic": true,
  "incremental": true,
  "mutate": ["src/domain/**/*.ts", "!src/domain/**/*.spec.ts"]
}

Scope narrowing does more than any timeout. Exclude files with no test coverage, since mutants there cannot be killed and only report as undetected. Exclude generated code and configuration. On the script side, a nightly job that refuses to spend more than its budget is a short shell wrapper:

START=$(date +%s)
timeout 7200 npx stryker run --incremental || echo "mutation run hit the hard cap"
echo "elapsed: $(( $(date +%s) - START )) seconds"

Two hours, then stop. You still get a partial report from incremental mode, because interrupted runs save partial results and the next run picks up where the last one stopped (StrykerJS incremental docs). That property turns a hard cap from a loss into a pause.

Prioritize survivors by subsumption, not by score

Once you have a list of surviving mutants, the instinct is to write tests until the score rises. That instinct is expensive and frequently wrong. Not all survivors carry the same information, and some carry none.

The cleanest filter is subsumption. Some mutants are subsumed by others: if a test kills mutant A, it necessarily kills mutant B, so B tells you nothing new once A is on the list. Research on efficient LLM-driven test generation built on mutant subsumption graphs, with a prioritization module that predicts the usefulness of each surviving mutant, reports that prioritization consistently outperformed random mutant selection while keeping mutation coverage high (the PRIMG paper). For budgeting, the practical rule is: kill the mutants that, if killed, would also kill several others, and skip the ones sitting in a dense cluster of already-killed neighbors.

The second filter is equivalence. An equivalent mutant behaves identically to the original for every input and cannot be killed by any test. Determining equivalence is undecidable in general, so no tool finds all of them, and historically developers inspected survivors by hand (the AI-enhanced mutation testing survey). Every hour spent hunting an equivalent mutant is pure cost with zero signal. When a survivor survives two or three honest attempts, mark it equivalent and move on. Treat that decision as data, not defeat.

The third filter is coverage classification. A mutant in a line no test reaches is not a test-quality problem, it is a dead-code or missing-coverage problem, and it belongs on a different backlog. Fix it with a coverage decision, not with a mutation-driven test.

Worked example. A pricing module generates 180 mutants; 40 survive. Of those, 12 are uncovered lines, 8 are judged equivalent by two engineers, and 5 are subsumed by a survivor already on the kill list. That leaves 15 mutants worth acting on. If each needs about 25 minutes of engineer time to write and stabilize a test, the whole backlog is roughly 6 hours of work, and the report just became tractable. Without the filters you were looking at 40 tickets.

A stopping rule you can apply to each surviving mutant

Cost per killed mutant is the right stopping metric, and it needs a denominator that includes engineer time, not just CI time. Estimate the monthly CI cost of the full run, then add the engineer hours required to kill the remaining survivors. The marginal cost per mutant rises sharply as you approach 100%, because the easy assertions are already written and what remains is edge cases, mocks that were never checked, and log-output assertions.

The Nimble Approach experiment is the clearest published illustration of where the easy gains live. A Python module with 12 AI-generated tests passed everything at roughly 85% coverage but killed only 57.3% of mutants. After human refinement the suite reached 100% coverage and 80.4% kill rate with 33 tests. The largest single category of survivors, nearly 45% of the gaps, was ignored logging and counters: a mutation changed count += 1 to count = 1 and no test read the log message that would have revealed it (why mutation testing is essential). That finding sets the priority order. State and behavior assertions, then side-effect and log assertions, then boundary cases, then the long tail.

Apply this stopping rule in order:

  1. Kill any survivor in a line that a real incident, bug report or security review has touched. Risk justifies the cost regardless of the margin.
  2. Kill survivors in money, authentication or data-integrity paths until the kill rate there is high (this is a business judgment, not a universal number).
  3. Kill survivors whose tests are cheap, meaning one clear assertion with no new fixtures.
  4. Stop when the next survivor requires a new fixture, a new dependency or a refactor of untestable code. Log it as accepted risk with a named owner and a review date.
  5. Stop entirely when the number of mutants killed per engineer hour falls below the rate you would accept on any other maintenance work.

Step 4 is the one teams skip, and it is the one that prevents mutation testing from becoming a permanent guilt list. An accepted, owned, dated survivor is a budget line; an unowned survivor is a slow leak.

There is a subtlety about who writes the tests. When agents generate tests alongside code, the tests can be vacuous, passing regardless of behavior, and the failure mode is that a test looks like every other green test in the suite (how to stop letting AI agents fake their own tests). Mutation testing is the check that catches this, which is why it deserves its own budget line rather than being folded into the normal pull request gate. The same logic applies to agentic systems more broadly: when behavior is non-deterministic, a single clean run is not verification, and teams need systematic repeated evaluation rather than a spot check (How to Test AI Agents). If your mutation backlog is large because agent-written tests are weak, the fix is a stronger generation step, not more CI minutes.

Turn the budget into a report the team acts on

A budget is only real when it is visible. Emit three numbers from every full run: total mutants, wall-clock minutes, and survivors after the subsumption and equivalence filters. Track the third number over time rather than the mutation score, because a rising score on a shrinking scope is not progress. Publish the accepted-risk list with owners alongside it.

If your codebase spans several stacks, the runtime per mutant varies enormously between a fast unit test and an integration test that spins up a database. That is the main reason to keep integration-heavy modules out of the mutation scope until the cheaper modules are clean. Where your workflow already sends work to models, whether for test generation, survivor triage or log analysis, a single gateway keeps the per-token cost predictable while you iterate (Quanta Inference offers text, image and embedding models through one OpenAI-compatible key).

The end state is a routine: nightly incremental runs within a hard timeout, a weekly forced full run, a triaged survivor list that respects a marginal-cost threshold, and a documented set of survivors the team has chosen not to kill. That is a mutation program with a price tag, which is the only kind that survives a budget review.

FAQ

FAQ

How many CI minutes should a full mutation run take?

There is no universal number, because the cost is mutants times runtime per mutant divided by workers, and all three inputs are specific to your code. Use a hard cap you can defend from your overall CI budget, and size the mutation scope so a typical run finishes comfortably inside it. If the run repeatedly hits the cap, shrink scope before adding workers.

Should mutation testing block pull requests?

Only the diff-scoped run should block, and only on a threshold you can meet consistently. Full runs produce backlogs, not merge decisions, and gating merges on a full run either slows delivery or forces the team to weaken the threshold until it means nothing. Nightly reports with a named owner work better than gates.

What do I do with a surviving mutant that looks impossible to kill?

Mark it as equivalent after two or three honest attempts, or as accepted risk if it is in awkward, low-risk code. Equivalence is undecidable in general, so some survivors genuinely cannot be killed. Record the decision with a date and revisit it only if the code changes.

Is incremental mode safe to rely on for the only run?

No. Incremental mode does not detect changes in files outside mutated files and test files, and static mutants are outside its reach. Schedule a periodic forced run to resynchronize, and treat incremental results as valid for the changed scope only.

How do I keep AI-generated tests from inflating my mutation bill?

Check generated tests with mutation testing before they enter the suite at scale, and reject tests that pass regardless of behavior. A generated suite can show high coverage while killing a minority of mutants, which means you pay for the full run and learn little.

Sources

Sources

  1. What is mutation testing?
  2. Incremental
  3. Static mutants
  4. Incremental mutation testing in the Bitcoin Core
  5. Bachmann1234/diff_cover: Automatically find diff lines that ...
  6. Diff-cover: Test coverage for Git commits
  7. Announcing StrykerJS incremental mode
  8. Mutation Testing for AI-Generated Code: A Practical Guide
  9. PRIMG : Efficient LLM-driven Test Generation Using Mutant ...
  10. AI-Enhanced Mutation Testing in Software Engineering
  11. Why Mutation Testing Is Essential for Trustworthy AI -
  12. How to Stop Letting AI Agents Fake Their Own Tests
  13. How to Test AI Agents
About the author

About the author

Antonio Evans
Antonio Evans

Antonio Evans is the founder of Quanta Intelligence and a fractional CTO who builds HIPAA-ready AI systems for health and life-science companies. Before that he was technical co-founder of FriendsEAT for twenty years, CEO of Socialdraft, and a data engineer at IBM. Antonio lives with his dog Santino in Lisbon, Portugal.

All articles
