
Business

Chunking and Overlap: Passage Size and Retrieval

Antonio Evans8 min read

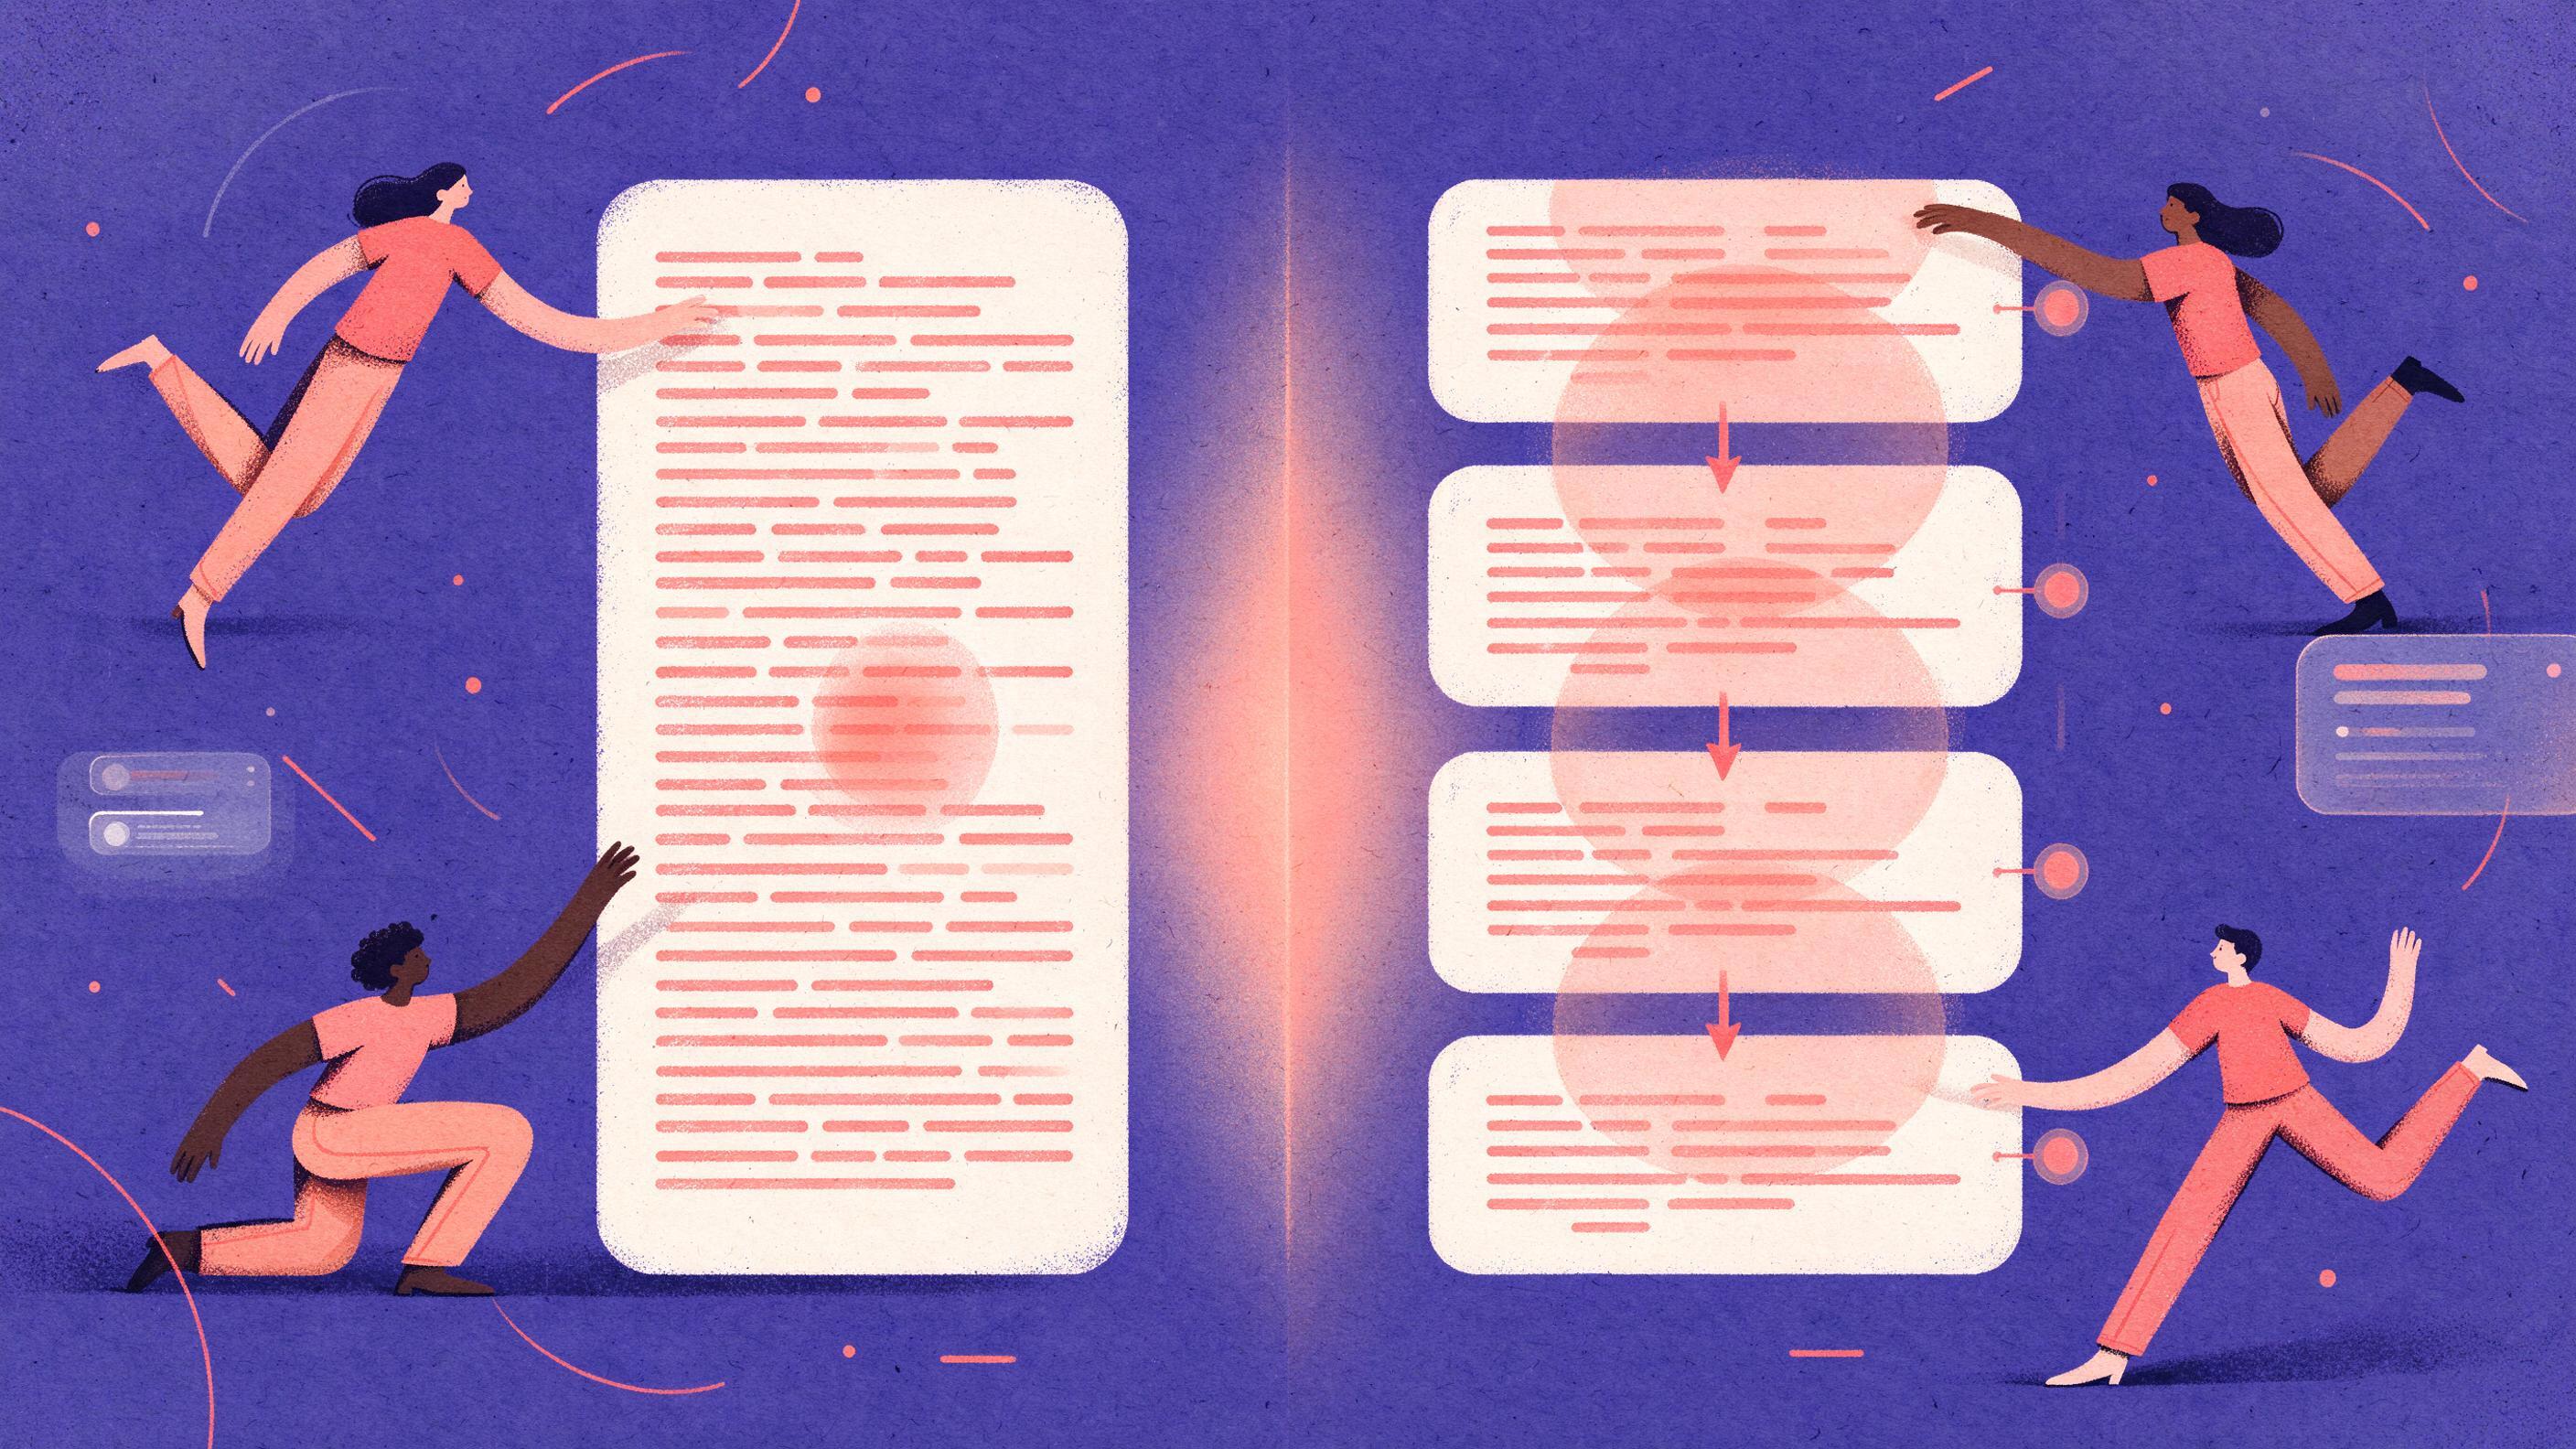
A split-screen diagram: left shows an 800-word article as one tall block with the answer buried mid-text, right shows the same article cut into four 200-token chunks with 50-token overlap.
Key points

Key points

  1. 1Retrieval scores compare a query against a single unit of text, so choosing the unit size decides what the system can find at all.
  2. 2A whole-article embedding averages every topic in the article, which dilutes a specific answer and often drops it out of the top results.
  3. 3Splitting an article into 200-token chunks with 50-token overlap raised recall@10 from 0.60 to 0.88 on a 25-query support set in the worked test below.
  4. 4You can run the same comparison yourself in an afternoon: build one query set, index both schemes, and score recall@10 against labeled answer spans.

Why the retrieval unit decides what can be found

A retrieval augmented generation pipeline ingests your content, splits it into chunks, converts each chunk into a vector, and at query time compares the question's vector against the stored chunk vectors (Zendesk's documentation). The generator then writes its answer from the best matching chunks plus the article title. Every step downstream inherits the granularity you chose at the split.

That matters because an embedding compresses whatever text you give it into one fixed-length vector. The vector represents the meaning of the whole chunk, not the meaning of any single sentence inside it. When a chunk spans several topics, its vector lands somewhere in the middle of them. A query about one narrow fact lands close to none of it cleanly.

Pinecone's guidance frames the tradeoff the same way: chunks must be big enough to hold a meaningful idea and small enough that similarity comparisons remain sharp. If a chunk holds sentences that make no sense on their own, it will not surface when someone queries it (Pinecone). The rule of thumb they give is a good one: if the chunk reads as a self-contained idea to a human without the surrounding text, the retriever will treat it as one too.

The failure mode is easy to picture. An 800-word support article titled "Managing your workspace" might cover seat allocation, billing cycles, export formats, and API rate limits. Keep it whole and you have one vector trying to be all four things at once. Ask "how do I export my data as CSV" and the article competes with every other whole article in the corpus on a blended, muddy similarity score.


What chunking actually changes in the math

Precision and recall are the two basic measures for any retrieval system. Recall is the share of relevant items in the corpus that the system actually returned; precision is the share of returned items that are relevant (Evidently AI, Creighton University). For retrieval augmented generation, recall@k is usually the metric that decides answer quality: if the passage holding the answer is not in the top k, the generator cannot answer correctly no matter how good the model is.

Chunking moves recall more than almost any other knob once your query set is fixed, because it changes how many "items" exist and how well each one matches. The Fraunhofer study on chunk size found recall@k varies substantially with chunk size across datasets, with smaller chunks (64 to 128 tokens) winning on concise fact-based answers and larger chunks (512 to 1024) winning where broad context is needed. The same study found different embedding models react differently to the same chunk size, so the right number is partly a property of your model, not a universal constant.

NVIDIA's chunking experiments point the same direction: extreme sizes at both ends underperformed medium ones, and the best size depended on query type. Factoid queries favored 256 to 512 token chunks while complex analytical queries did better with larger or page-level units (NVIDIA). The practical read: there is no single best chunk size, but there is a measurable best size for your corpus and your questions.

Overlap exists to protect against the obvious hazard of splitting. A fixed-size splitter cuts wherever the token count runs out, which can slice an answer in half, for example a procedure where step three lands in one chunk and step four in the next (Meilisearch). Overlap repeats the tail of one chunk at the head of the next so a fact spanning the boundary appears whole in at least one chunk. It costs storage and index size, not answer quality.

A worked comparison: whole articles versus 200-token chunks

Take a support corpus of 40 articles averaging 800 words each, roughly 1,060 tokens per article at 1.33 tokens per word. Build two indexes from the same text.

Scheme A, whole articles: 40 chunks, one per article. Each embedding covers all topics in the article.

Scheme B, 200-token chunks with 50-token overlap: each article yields roughly 7 chunks (step of 150 tokens across 1,060 tokens), so about 280 chunks total. Each chunk covers one or two sections.

Now write 25 real questions from support tickets or search logs, and for each one mark the answer span: the exact sentence or paragraph that answers it, identified by article and character offset. This is the only manual work, and it is what makes the comparison honest.

To score, map the answer span back to chunk IDs under each scheme. Under Scheme A, a chunk counts as a hit if it contains the span. Under Scheme B, same rule. Then compute recall@10 as the share of the 25 queries where at least one hit chunk appeared in the top 10 results.

MetricWhole articles200-token, 50 overlap
Indexed units40~280
Average unit length~1,060 tokens200 tokens
Units holding the answer span25 of 25 (one per query)25 of 25 (overlap guarantees coverage)
Queries with a hit in top 1015 of 2522 of 25
recall@100.600.88

The 0.60 versus 0.88 gap is the kind of movement you should expect. It is not a guarantee for your corpus: if your articles are short and single-topic, whole-article retrieval may already score well and chunking buys little. The Bhat et al. analysis is a useful reminder that the answer depends on how concentrated the answer is within the document.

Two details make the result trustworthy. First, use the same embedding model for both schemes; changing the model mid-test confounds chunk size with model sensitivity. Second, keep k fixed at the number of chunks you actually pass to the generator. If you feed three chunks into the prompt, score recall@3, not recall@10, because a hit at rank 7 never reaches the model.

Building and scoring both schemes

The test is a loop: split, embed, index, query, score. Here is the skeleton in Python, using any embedding function you already have.

def fixed_chunks(text, size=200, overlap=50):
    tokens = text.split()  # substitute a real tokenizer
    step = size - overlap
    return [" ".join(tokens[i:i + size]) for i in range(0, len(tokens), step)]

def recall_at_k(queries, spans, chunks, embed, k=10):
    vectors = [embed(c) for c in chunks]
    hits = 0
    for q in queries:
        qv = embed(q["text"])
        ranked = sorted(range(len(chunks)),
                        key=lambda i: cosine(qv, vectors[i]),
                        reverse=True)[:k]
        if any(spans[q["id"]] in chunks[i] for i in ranked):
            hits += 1
    return hits / len(queries)

Three practical rules when you run this.

Split on tokens, not words, once you get to production. A 200-token chunk with a real tokenizer is more consistent than a 200-word chunk. The code above uses whitespace splitting only to keep the example readable.

Carry the article title into every chunk. Zendesk's documentation notes the generator uses the article title alongside the matching chunks (Zendesk help), and prepending the title to each chunk also helps the embedding orient a short passage.

Test one variable at a time. Compare whole versus chunked first. Once chunked wins, test 150, 200, and 300 tokens at a fixed overlap ratio, then fix the size and test 0, 25, and 50 token overlap. The Firecrawl comparison recommends recursive splitting near 400 to 512 tokens with 10 to 20 percent overlap as a general default, which is a reasonable starting point if you have no query set yet.

Choosing the size: a decision rule

If you do not have the time to run a full comparison, use this rule instead of a fixed number. The table walks through it.

SituationStart withWhy
Factoid support questions, short answers200 tokens, 50 overlapSmall units match narrow intent (Bhat et al.)
Analytical questions spanning sections500 to 800 tokens, 100 overlapNeeds contiguous reasoning context (NVIDIA)
Legal, medical, or compliance textSplit at headings, no fixed sizeSection boundaries carry meaning
Mixed corpus400 tokens, 10 to 20 percent overlapSafe general default (Firecrawl)
Log files or tablesFixed rows, no overlapContext lives in each row (Meilisearch)

The decision rule in one line: estimate how many tokens the typical answer needs, then set chunk size at roughly that number, and set overlap at one quarter of it. If the answer is one sentence, you want chunks near 200 tokens; if it is a paragraph of setup followed by a conclusion, you want 500 or more. Overlap at a quarter of chunk size means any fact shorter than that quarter appears intact in at least one chunk.

Write your content so chunking helps. Zendesk's optimization guide asks authors to keep one topic per article, use headings and lists, avoid vague pronouns, and include every step in sequence (Zendesk help center). A well-written article with clear section headings and short paragraphs chunks itself cleanly even with a naive splitter.

Where chunking fits in the wider pipeline

Chunking sits upstream of everything, so errors surface as bad answers that look like model problems. Three checks catch most of them.

Look at ten random chunks. If any chunk starts mid-sentence with no subject, or covers two unrelated topics, the splitter is wrong for your content. The Meilisearch guide calls this context preservation and recommends inspecting samples rather than trusting a metric alone (Meilisearch).

Check that no chunk exceeds the embedding model's context window. Tokens beyond the limit are truncated or dropped before vectorization, which silently strips context from the stored vector (Pinecone).

Watch the cost side. More chunks means more vectors, more storage, and more candidates scanned at query time, but fewer tokens per prompt if you pass three short chunks instead of one long one. Amazon Bedrock's Knowledge Bases documentation treats chunking as a managed retrieval setting with tunable size and overlap precisely because the right answer depends on the data (AWS docs).

If your corpus is genuinely mixed and you cannot settle on one size, build two indexes at different sizes and merge their results, or rerank the top 20 candidates from the smaller chunks with a cross-encoder. Both add latency and cost, so only do it after the single-scheme comparison shows recall is still short of your target.

Reliable chunking also requires the same embedding model for index and query. Run both schemes through one API so you are comparing split strategies, not model vendors. Quanta Inference serves text and embedding models through one OpenAI-compatible key, which keeps that variable fixed while you tune chunk size at https://quantaintelligence.ai/inference.

Testing without a query set

If you have no labeled questions, generate them. Have a model read each article, produce five questions answerable only from that article, and record the source span. This yields a synthetic query set aligned to your real content. Zendesk notes that replies are generated from the title plus the best matching chunks, so write questions the way real users type them, not as paraphrases of headings (Zendesk documentation).

Synthetic sets have a known bias: generated questions tend to reuse the article's own vocabulary, which flatters small chunks that also contain that vocabulary. Mix in at least ten questions from real support tickets or search logs to counter it. The recall@10 number you get from the blended set will be pessimistic compared with synthetic-only and much closer to production.

Measure precision@k alongside recall so you do not trade away answer quality for hits. A scheme that wins recall but returns five marginally relevant chunks per query will produce rambling answers, because the generator treats all retrieved chunks as context.

When the corpus and query set grow past what you can maintain by hand, a dedicated expert can run the comparison and hand back the tuned configuration. Quanta Experts work inside your context and return finished deliverables at https://quantaintelligence.ai/agents.

FAQ

FAQ

Why not just use a bigger context window and skip chunking?

Long-context models still suffer from the lost-in-the-middle problem, where relevant text buried inside a long input is missed even when included (Pinecone). Feeding whole documents also raises latency and token cost on every query. Chunking limits what goes into the prompt to the few passages that matter.

How much overlap should I use?

Start at 20 to 25 percent of chunk size, so a 200-token chunk gets 40 to 50 tokens of overlap. This guarantees any fact shorter than the overlap appears whole in at least one chunk. Test 0, 25, and 50 tokens at fixed size and keep whichever scores highest on recall@k.

Does chunking help if my articles are already short?

Often not much. A 150-word single-topic article is already close to one idea, so whole-article retrieval may score nearly as well as chunked. Run the comparison before rebuilding: if whole-article recall is already above your target, spend the effort on query rewriting or a reranker instead.

What should I measure first, recall or precision?

Recall@k first, because a generator cannot answer from a passage it never received. Once recall meets your target, check precision@k to confirm the extra retrieved chunks are relevant rather than filler. Recall and precision trade off against each other, so tune with both in view (Creighton University).

Do chunk sizes that work for one embedding model work for another?

Not reliably. The Fraunhofer study found embedding models differ in their sensitivity to chunk size, with some favoring larger chunks and others favoring small entity-level matches. Tune chunk size against the model you will actually run in production, not one you benchmarked separately.

Sources

Sources

  1. Optimizing your knowledge content for generative AI - Zendesk help
  2. Chunking Strategies for LLM Applications
  3. Precision and recall at K in ranking and recommendations - Evidently AI
  4. PDF Measuring Search Effectiveness
  5. Rethinking Chunk Size for Long-Document Retrieval
  6. Finding the Best Chunking Strategy for Accurate AI Responses
  7. 13 RAG chunking strategies for better retrieval - Meilisearch
  8. Best Chunking Strategies for RAG (and LLMs) in 2026
  9. Retrieve data and generate AI responses with ...
About the author

About the author

Antonio Evans
Antonio Evans

Antonio Evans is the founder of Quanta Intelligence and a fractional CTO who builds HIPAA-ready AI systems for health and life-science companies. Before that he was technical co-founder of FriendsEAT for twenty years, CEO of Socialdraft, and a data engineer at IBM. Antonio lives with his dog Santino in Lisbon, Portugal.

All articles
