
AI agents

Citing Spans, Not Chunks: The Gate Gets Sharper

Antonio Evans10 min read

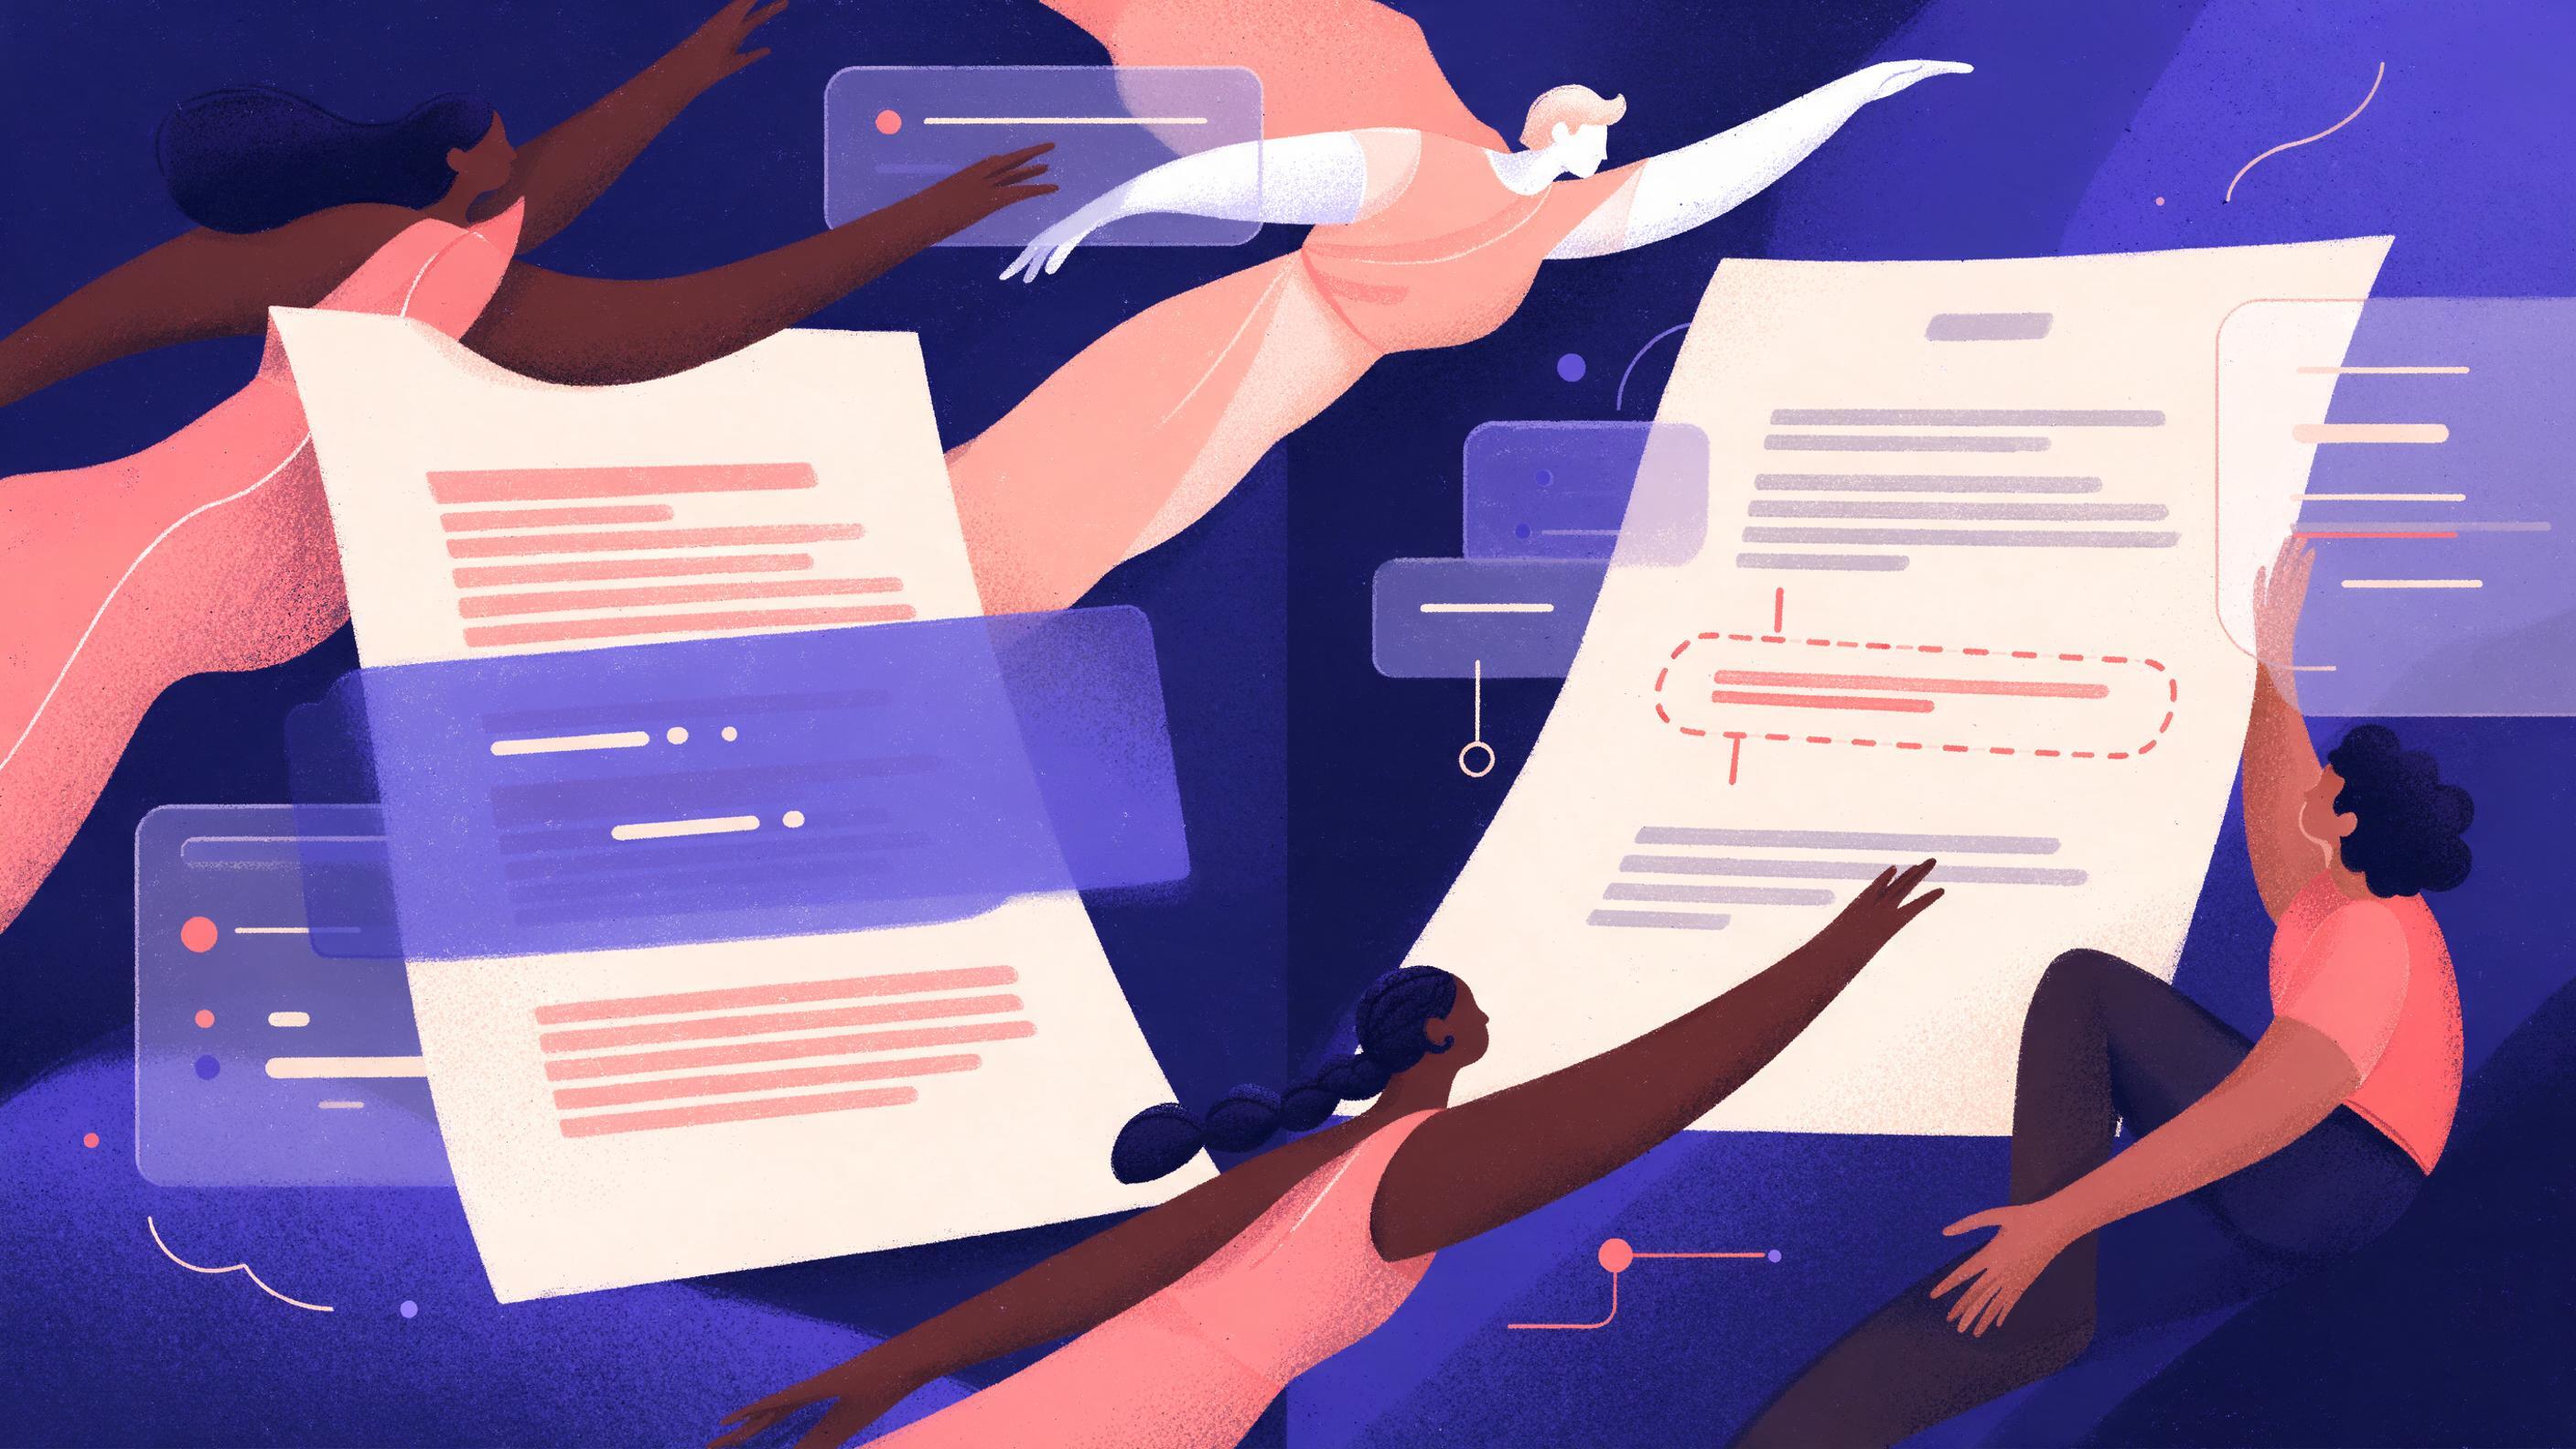
A two-panel diagram: left, a document page with a wide shaded block labeled chunk over three paragraphs; right, the same page with one sentence outlined and offset markers 142 to 198.
Key points

Key points

  1. 1Cite a span (document id plus start and end character offsets) rather than the retrieved chunk, so the support check compares one claim to one bounded passage.
  2. 2Span citation is an ingestion decision: split each source into sentences, record offsets against the original text, assign stable ids, and return those ids from retrieval.
  3. 3Inline citation by the generator is unreliable at long output lengths, so a separate post-hoc extractor over bounded claim and context pairs is the safer pattern.
  4. 4Sentence-level attribution beats passage-level for verifiability, and span-level matching can be scored as a retrieval problem with precision, recall and F1.

Why the unit of citation decides the cost of the check

A support check has two jobs. It asks whether the cited passage actually entails the claim, and it asks whether the pointer lands on the passage the claim came from. Both jobs get cheaper or harder depending on the unit you cite.

If you cite a whole chunk, the first job becomes a search inside the chunk. A 500-token chunk with four paragraphs may contain one sentence that supports the claim, two that are silent, and one that contradicts a different claim nearby. The checker has to locate the relevant sentence before it can judge it, and that locating step is where most of the error and most of the tokens go.

If you cite a sentence range, the first job is a single comparison. The checker reads one sentence, reads one claim, and decides. There is nothing to locate. The work is bounded by the length of the longest sentence in your corpus, not by your chunking strategy.

The second job gets sharper too. With a chunk pointer, a citation that is off by a sentence is invisible: the pointer is still "valid" because the chunk contains the sentence. With a span pointer, a citation that is off by a sentence is a boundary error you can detect and count. That turns citation quality into a measurable number rather than a vibe.

This connects to a distinction that the RAG literature treats carefully. Work on attributed text generation separates citation correctness, meaning the cited document supports the statement, from citation faithfulness, meaning the model actually relied on that document rather than rationalizing after the fact. That study found unfaithful citation in up to 57% of cases, and argues that you cannot build justified trust from correctness alone (Correctness is not Faithfulness in RAG Attributions). A span pointer does not solve faithfulness on its own, but it removes one hiding place, because a post-rationalized citation that points at a single sentence is much easier to catch than one that points at a chunk.


What span citation looks like on the wire

The data contract is small. For every sentence in every source you keep four fields: the document id, the start offset, the end offset, and a span id derived from the first three so it stays stable across re-ingestion.

{
  "span_id": "doc-8841:s17",
  "doc_id": "doc-8841",
  "start": 3421,
  "end": 3512,
  "text": "The retention period ends ninety days after the final invoice.",
  "sent_index": 17
}

The offsets are character positions into the normalized source text, not into the chunk. That last point matters: if you store offsets into a chunk string, then change your chunker, every offset shifts and every stored citation silently rots. Store offsets against a text you never reflow, and chunking becomes a retrieval concern that can change freely.

Two rules keep ids stable. First, derive the span id from content plus position rather than from an incrementing counter, so re-running ingestion on an unchanged document reproduces the same ids. Second, version the document, not the span: when a source changes, cut a new document version and let old citations keep pointing at the old one. A citation that resolves to the text that existed when the claim was made is a feature, not a bug, in any audit context.

Retrieval then returns spans, not chunks. You can still retrieve at chunk granularity for recall, because larger units embed better and carry more context, but the response object should carry the span ids that fall inside the returned chunk, and the model should be asked to cite those ids. The retrieval layer does the mapping once, so no downstream component ever has to reconstruct it.

The ingestion pipeline, step by step

  1. Normalize conservatively. Strip boilerplate that you are sure is not content, fix encoding, and then freeze that text. Every offset after this step is relative to this frozen string.
  2. Split into sentences with a real segmenter, not a regex on periods. Abbreviations, decimals, citations and bulleted lists all break naive splitting, and a bad split produces a span that cuts a claim in half.
  3. Guard sentence length. Very long sentences (legal prose is full of them) get sub-split at clause boundaries so that no single span exceeds your checker's comfortable input. Record the sub-splits as child spans of the parent sentence.
  4. Compute offsets as you split, not after. Walk the frozen text and record the character index at the start and end of each emitted span.
  5. Assign span ids deterministically and store the mapping.
  6. Embed whatever unit you retrieve on (chunk or sentence), and store the list of span ids that belong to each retrieval unit.
  7. Return span ids and offsets alongside the retrieved text in every retrieval response.

Step 7 is the one teams skip, and it is the one that makes everything downstream possible. If retrieval returns anonymous text blobs, the generator has nothing precise to cite, and every later stage is guessing.

There is a cost angle worth naming here, because it is the part most teams get wrong. The choice of embedding model and dimensionality drives the storage and latency bill far more than most teams expect. One practitioner analysis puts 1 million vectors at 768 dimensions at roughly 3 GB and the same million at 3072 dimensions at roughly 12 GB, and notes that HNSW search degrades as dimensions climb because high-dimensional vectors become nearly equidistant (The Vector Dimension Tax). Research on storage optimization reports that float8 quantization gives a 4x storage reduction with under 0.3% performance degradation, and that combining moderate PCA with float8 reaches 8x compression with less quality loss than int8 alone (Optimization of embeddings storage for RAG systems). If you move to sentence-level retrieval units, your vector count rises, so fix the dimension and quantization story before you multiply the row count.

DecisionChunk citationSpan citation
Unit of support checkMulti-paragraph passageOne sentence or clause
Checker input sizeHundreds of tokensTens of tokens
Boundary error detectableNo, still inside the chunkYes, offset mismatch
Stable across re-chunkingNo, chunk ids changeYes, offsets are per document
Audit trail for a reviewer"It was somewhere in here"Exact range with offsets
Extra ingestion workNoneSentence split plus offset tracking
Storage overheadBaselineSmall, offsets and ids only

The right column is not free, and the middle column is not worthless. Chunk citation is fine for casual search. Span citation is what you need the moment somebody has to verify the answer.

Where retrieval and citation drift apart

A retrieval system ranks passages. A citation system points at evidence. Those are different objectives, and they fail differently.

Retrieval failure looks like this: the right sentence was never returned, so the model answers from parametric memory and cites whatever was returned. Citation failure looks like this: the right sentence was returned, the model used it, but the pointer it emitted names the wrong span or the wrong document index.

The second failure is mechanical, and it gets worse with output length. ZeroEntropy's writeup on span attribution describes the mechanism: inline citations are emitted as tokens during the same decode that produces prose, and the model has to hold a mapping from logical position in the context to bracketed index in working memory, competing with everything else it is attending to. The slip rate climbs roughly linearly with output length, and by the fourth paragraph the model is often citing the wrong index entirely. They put inline citation accuracy for top models at 85 to 95%, which is high enough to look right and low enough that one citation in ten to twenty misleads (Citation extraction).

That number is the argument for span citation plus a post-hoc check. If you cannot get inline citation to be reliable, then make citation a separate step with a bounded input: one claim, a handful of candidate spans, and a required output shape of document id plus character offsets, or null. A small specialized model handles this well because each call is independent and the model never has to track index state across paragraphs.

There is also independent evidence that finer granularity helps attribution quality. ReClaim, a method that interleaves reference selection with claim generation, reports sentence-level citations in long-form question answering with a citation accuracy rate of 90%, and its authors argue explicitly that passage-level and paragraph-level attribution falls short in verifiability (Ground Every Sentence). That is the same conclusion from the generation side that span citation reaches from the data side.

A worked example with numbers

Take a corpus of 100,000 documents averaging 40 sentences each. That is 4 million sentences, which is a useful scale because it is large enough for the numbers to mean something and small enough to run on one machine.

Ingestion cost. You split and offset 4 million sentences. A sentence splitter plus offset bookkeeping runs at tens of thousands of sentences per second on a single core, so the whole corpus is minutes of compute, not hours. This is a one-time cost per document version.

Storage cost. Four fields per sentence. A document id of 12 bytes, two 4-byte integers, a span id of 24 bytes, and an average sentence of 100 characters. Call it roughly 150 bytes of structured record per span before any index overhead. Across 4 million spans that is around 600 MB of raw record data, plus index structures on top. Compare that to your vector store, which at 768 dimensions and 4 bytes per value is about 3 KB of vector per row (The Vector Dimension Tax). If you retrieve and embed per sentence, the vectors dominate the bill by a factor of roughly 20, which tells you where to spend optimization effort: quantize the vectors, not the offsets.

Check cost. Suppose you check 1,000 answers a day, averaging 4 claims each, so 4,000 support checks. Each check reads one claim of about 20 tokens and one span of about 30 tokens, so about 50 tokens of input per check, plus a short rubric and a short output. That is roughly 200,000 input tokens a day, before prompt scaffolding. Now suppose you had cited chunks instead: a 500-token chunk per claim gives 2 million input tokens a day for the same checks, ten times the volume, and each check is harder because the checker has to find the supporting sentence first. The ten-times figure is illustrative arithmetic on the two token counts, not a benchmark, but the direction is robust to any reasonable chunk size.

Boundary error rate is the metric to track once you ship this. Replay a sample of historic answers, resolve each cited span, and count how many resolve to a span that the checker judges non-supporting while an adjacent span does support. That count is your boundary error rate, and it is only computable if you stored offsets. Teams that cite chunks cannot compute this number at all, which is exactly why the check stays vague.

Evaluating span citations as a retrieval task

Once citations are spans, evaluation stops being a judgment call and becomes a standard retrieval metric. For each claim you have a gold set of supporting spans and a predicted set. Precision is the share of predicted spans that actually support the claim. Recall is the share of gold spans you found. F1 combines them.

Exact matching is too strict in practice, because a gold span of characters 3421 to 3512 and a predicted span of 3430 to 3505 cover almost the same text. Use intersection over union, and treat an overlap above a threshold as a match. ZeroEntropy recommends IoU above 0.5 as the usual threshold, and notes that F1 is the natural metric here because the output is an unordered set of spans rather than a ranked list (Citation extraction).

Two cautions before you trust an F1 number.

First, a span that supports the claim is not the same as a span the model actually used. That is the correctness versus faithfulness split again, and it can only be tested by intervention, for example by removing the cited span and seeing whether the answer changes. If the answer survives the removal, the citation was post-rationalized (Correctness is not Faithfulness in RAG Attributions).

Second, surface citation quality can mask factual failure. A large evaluation of deep research agents found that even the strongest frontier models kept link validity above 94% and topical relevance above 80%, yet reached only 39 to 77% factual accuracy, and that fact-check accuracy dropped by roughly 42% as tool calls scaled from 2 to 150 (Cited but Not Verified). A citation that resolves perfectly can still point at a passage that does not support the sentence. Span citation makes that failure visible and cheap to measure; it does not make it disappear.

Practical rules for the build

Return span ids, always. Every retrieval response carries the span ids and offsets inside the returned text. Anything that consumes retrieval output should be able to resolve a span without a second lookup against the corpus.

Cite by id, not by index. Bracketed numerical indices in a prompt are the source of drift. Ask for span ids, which are globally unique strings, so a model cannot confuse [3] with the fourth document.

Allow null. A claim with no supporting span is a valid and important output. Forcing a citation produces a confident pointer to a passage that does not support the claim, which is worse than an admitted gap.

Check after generation, not during. Run a separate extractor or checker over bounded claim and span pairs. This keeps the input small, the output shape strict, and each call independent.

Keep both granularities for retrieval. Retrieve wide, cite narrow. Chunk-level retrieval improves recall; span-level citation improves verification. The mapping between them is the retrieval layer's job.

Version documents, not spans. When a source changes, cut a new version and let old citations resolve against the old text. Auditors need to see what was true when the answer was written.

If you are assembling the inference side of this pipeline, one option is to route text, embedding and checking models through a single OpenAI-compatible endpoint with prepaid billing in US dollars, which removes per-provider key handling from the build: Quanta Inference. The choice of model matters less here than the data contract, and the contract is entirely yours to define.

FAQ

FAQ

Why not just cite the chunk and let the checker find the sentence?

Because that redistributes the hardest part of the job to the checker, every time, on every claim. Locating the supporting sentence inside a multi-paragraph chunk is the task most likely to fail, and it costs tokens proportional to chunk size rather than to the length of the evidence. When you cite a span, the locating work happens once at ingestion and the check becomes a single bounded comparison.

How do I keep offsets valid when I re-chunk a corpus?

Store offsets against a frozen normalized text per document version, not against chunk strings. Chunking then becomes a retrieval setting that you can change at will, because it never touches the offset field. If the source itself changes, create a new document version so historic citations keep resolving to the text that existed when the claim was made.

Does sentence-level splitting break on legal or scientific text?

It can, which is why you use a real segmenter and add a length guard. Sentences that exceed your checker's comfortable input should be sub-split at clause boundaries and recorded as child spans of the parent sentence. The goal is that no span is so long that the checker has to re-locate the supporting clause inside it, because that reintroduces the chunk problem at a smaller scale.

How do I know a spanned citation is honest rather than post-rationalized?

Test it by intervention. Remove the cited span from the context and regenerate the answer. If the claim survives unchanged, the model was not relying on that span, and the citation was rationalized after the fact. Research on attribution finds this failure in a large share of citations, so treat a resolving span as necessary but not sufficient evidence of grounding (Correctness is not Faithfulness in RAG Attributions).

What metric should I put on a dashboard first?

Boundary error rate, defined as the share of replayed citations that resolve to a non-supporting span while an adjacent span does support the claim. It is cheap to compute, it requires only the offsets you already stored, and it moves when your segmenter, your retrieval, or your extractor degrades. Pair it with span-level F1 using an intersection-over-union match threshold so you can compare candidate extractors on the same gold set (Citation extraction).

Sources

Sources

  1. arXiv:2412.18004v1 cs.CL 23 Dec 2024
  2. The Vector Dimension Tax: How Embedding Size Quietly ...
  3. Optimization of embeddings storage for RAG systems ...
  4. Citation extraction: tying RAG claims back to source spans - ZeroEntropy
  5. Improving Retrieval-Augmented LLMs with Interleaved Reference-Claim ...
  6. Parsing and Evaluating Source Attribution in LLM Deep ...
About the author

About the author

Antonio Evans
Antonio Evans

Antonio Evans is the founder of Quanta Intelligence and a fractional CTO who builds HIPAA-ready AI systems for health and life-science companies. Before that he was technical co-founder of FriendsEAT for twenty years, CEO of Socialdraft, and a data engineer at IBM. Antonio lives with his dog Santino in Lisbon, Portugal.

All articles
