
Development

Fitting a Retry Budget to a Tool That Fails Slowly

Antonio Evans10 min read

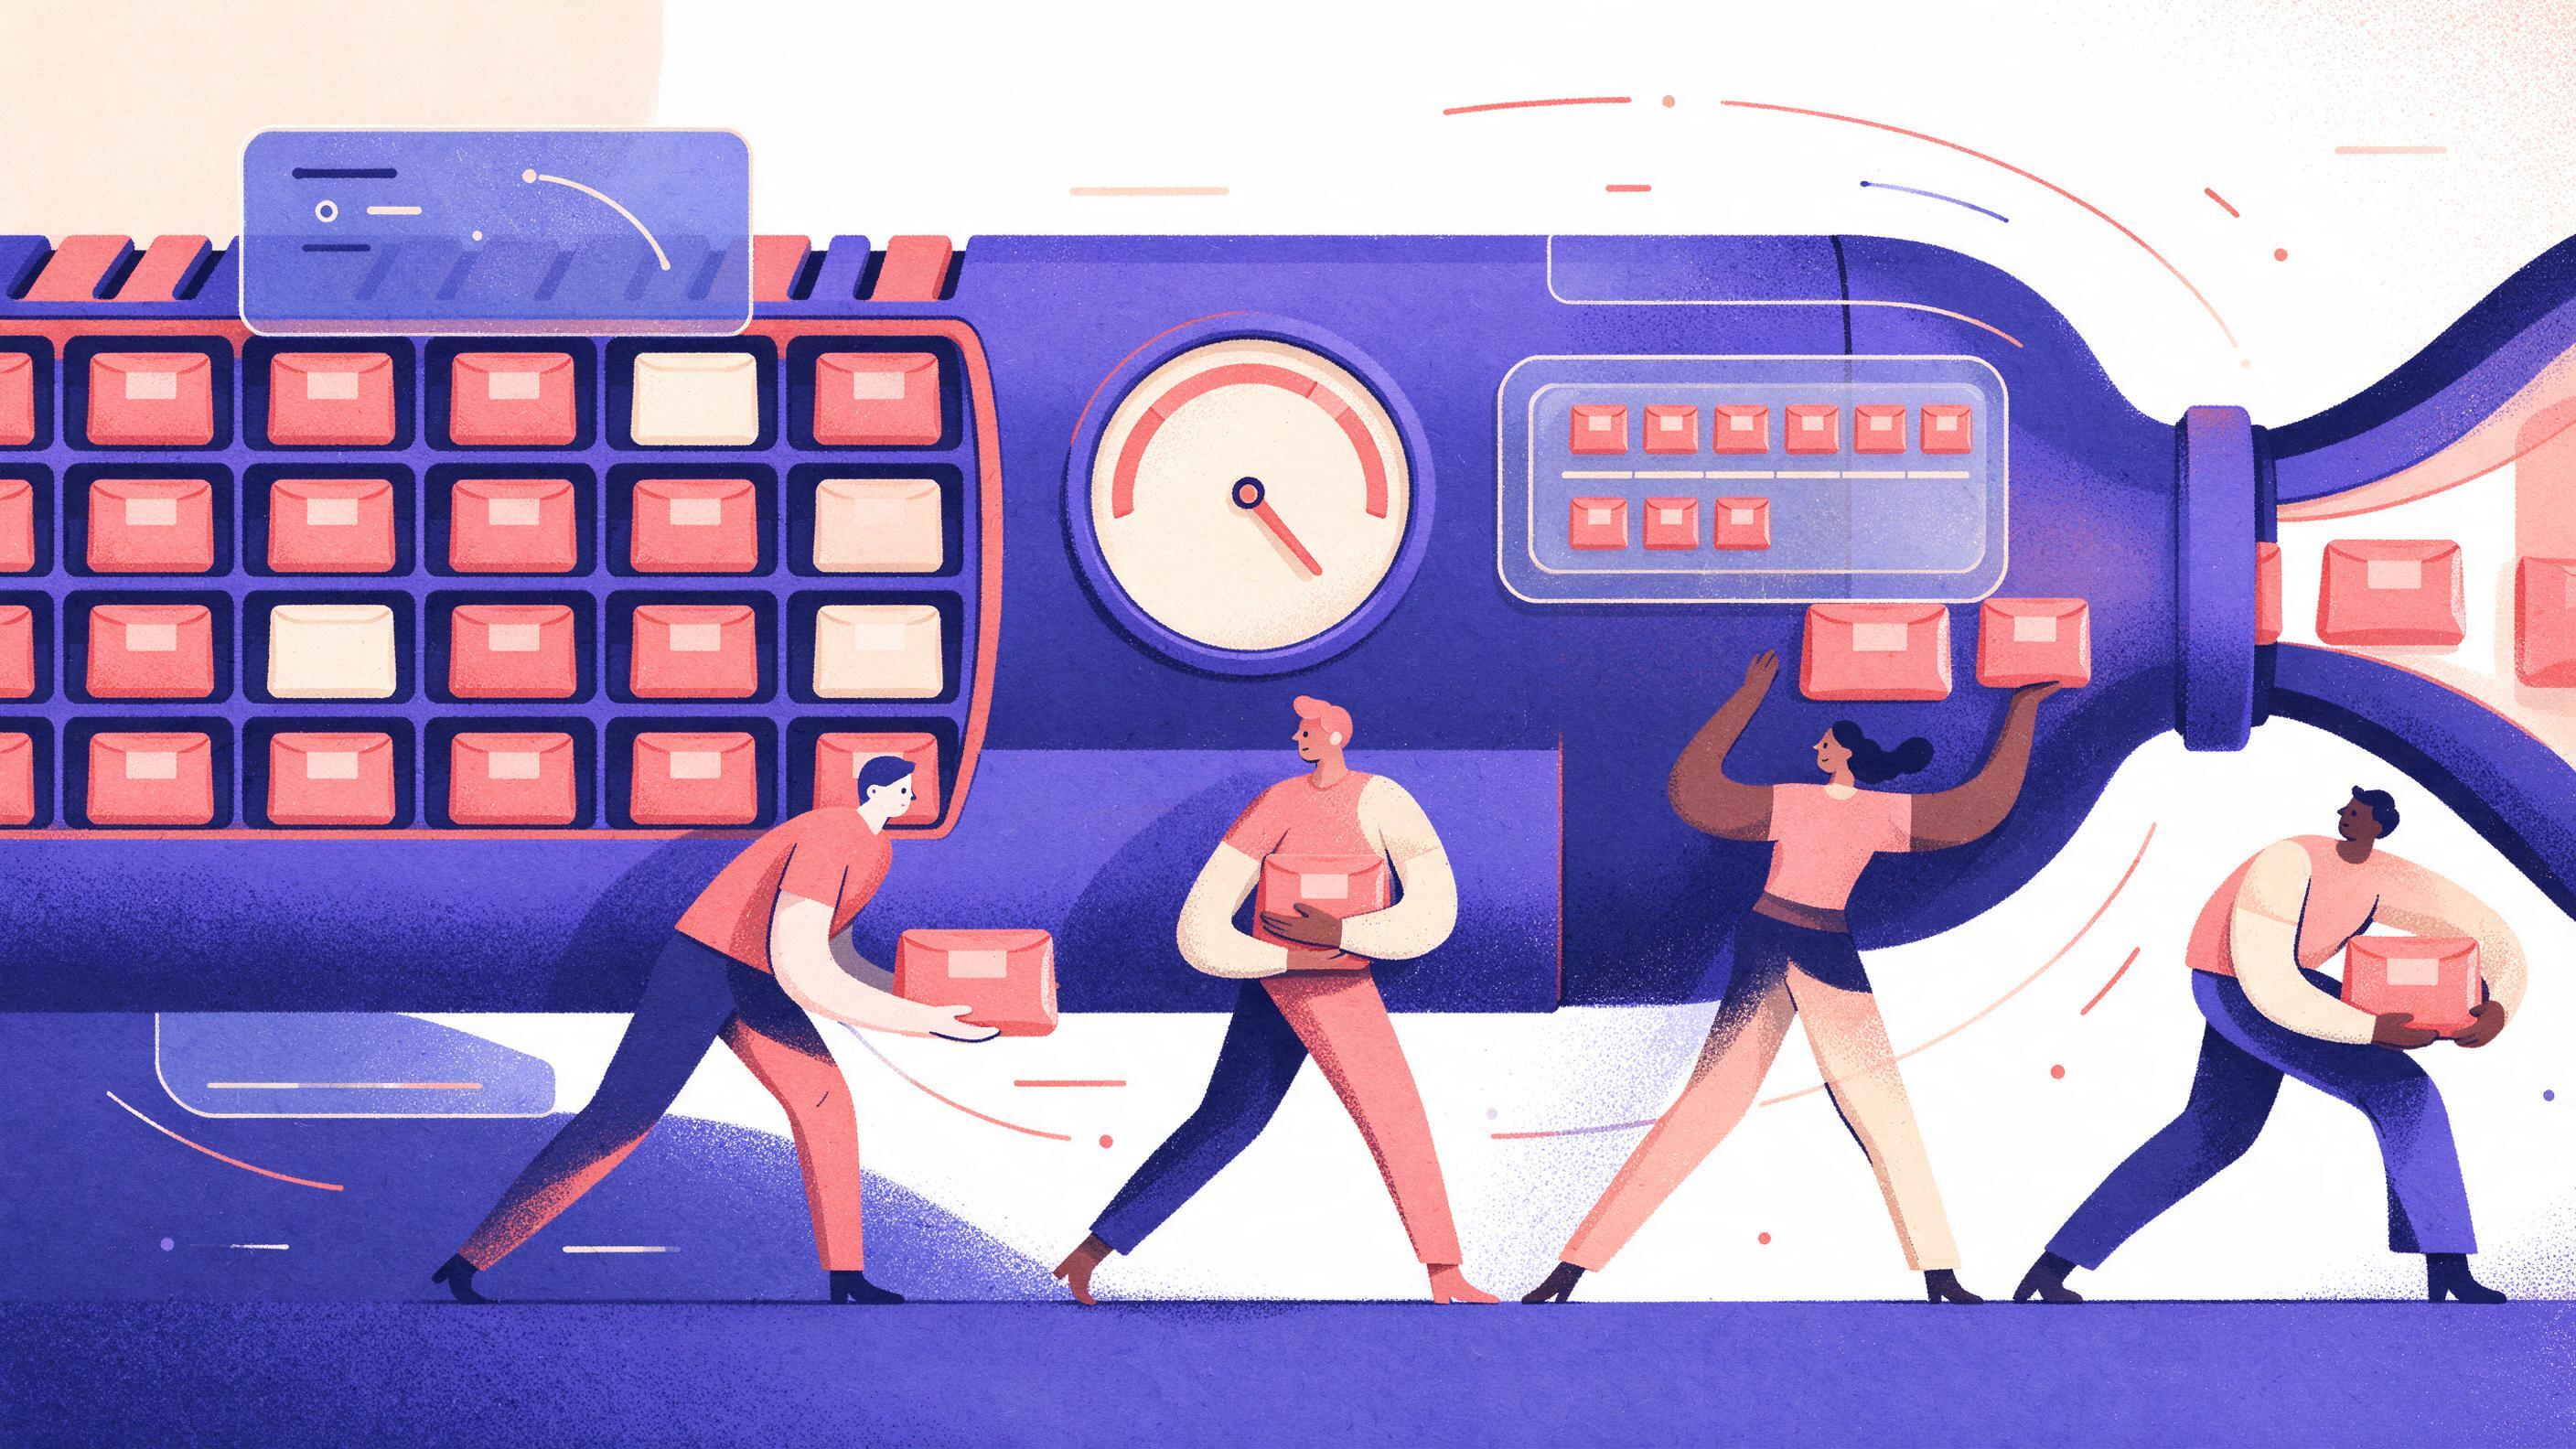
A cutaway pipe diagram with 20 package slots on the left, a gauge reading 20 percent errors, a counter showing 16 primary plus 4 retries, and four packages queued outside a narrowing cap line.
Key points

Key points

  1. 1A retry budget is a hard cap on retries expressed as a fraction of primary traffic, sized so that primary plus retry concurrency never exceeds your connection or rate-limit ceiling.
  2. 2Retries amplify load precisely when a dependency is slowest, because each failed call holds its slot for the full timeout before it can be retried.
  3. 3At a 20 percent error rate, retrying every failure once turns 16 concurrent calls into about 20, which sits at a 20-slot cap, and any retry that itself fails pushes it over.
  4. 4Budgets must be enforced centrally (proxy, client pool, or shared token counter), and they need a minimum floor so a quiet service can still recover from a single blip.

Why retries multiply concurrency when the dependency is slowest

A retry feels free because it is written as a few lines of configuration. In practice it is a second real request that consumes the same network socket, thread, and pool slot as the first, a point the retry and timeout guide at the System Design Academy makes explicitly: "a retry is not free error handling" (retry and timeout patterns). The problem is timing. Retries fire when errors are happening, and errors cluster when the downstream is degraded. So the moment your dependency has the least spare capacity is the same moment your callers multiply their offered load.

Connection pools make this worse than the raw request count suggests. A pool only cycles as fast as connections come back. As one systems write-up puts it, a pool of 100 connections returning in 10 milliseconds each can serve 10,000 queries per second, while 1,000 connections returning in 100 milliseconds each is "more exhausted" because circulation is slower (connection pool exhaustion). Slow calls hold their slot longer, so the same concurrency cap absorbs fewer requests per second, and then the retries arrive on top.

That is the trap. Your concurrency cap is a limit on requests in flight, not on requests offered. Retries sit outside the primary request but inside the same cap when they share a pool, a client, or a rate-limited API quota. If you size the cap for primary traffic alone, the retries have nowhere to go, and they either queue (inflating latency, which causes more timeouts, which causes more retries) or fail with a pool timeout, which the caller may retry again.

Two metrics tell you whether you are in this regime. The first is active connection count: a value pinned at the pool maximum for more than a few seconds is a warning sign, and a count that climbs and never recovers is a leak rather than a load problem (connection pool exhaustion). The second is acquisition wait time. Under 1 millisecond is healthy, and above 10 milliseconds means the pool is congested (connection pool exhaustion). Both move before anyone notices, which is why the fix belongs in capacity math rather than in an alert.


The worked example: 16 concurrent calls at a 20 percent error rate

Take a service that calls a payment or model API with a concurrency cap of 20. Normal operation keeps 16 calls in flight, leaving four slots of headroom. The dependency degrades and 20 percent of calls fail with a timeout or a 5xx. Suppose the retry policy is the common one: retry every failure once, immediately.

The arithmetic is small but easy to get wrong. Of 16 in-flight calls, 3.2 fail on average and are retried. Those retries occupy the four spare slots, taking in-flight from 16 to 19.2, which rounds to about 20 at any instant. Your system now runs permanently at the cap, with zero margin.

The margin is exactly what protects you from the next thing. At the cap, roughly 20 percent of the retries fail too. Each of those is another candidate for a retry, and every one that fires pushes offered concurrency to 21 or 22. Once offered load exceeds the cap, the excess queues for a slot. Queued requests take longer, and longer requests are more likely to hit the client timeout, which produces a fresh failure and a fresh retry. That is the retry storm, and the Azure Architecture Center documents the mechanism plainly: retries within a short period are unlikely to succeed because the service has not recovered, and excessive connection attempts during recovery intensify the original problem (retry storm antipattern).

Error ratePrimary in flightFailed and retriedEffective in flight at cap of 20Headroom left
0%16016.04.0
5%160.816.83.2
20%163.219.20.8
40%166.422.4over by 2.4
20%, retries at 100 concurrency204.024.0over by 4.0

The last row is the case people hit in production. If you set your client pool to the cap of 20 and then retries draw from a separate pool, the two pools add rather than share, and the dependency sees 24 concurrent requests against a 20-slot limit. The interesting insight is not that retries add load. It is that a retry policy which looks safe at 5 percent error is already at the edge at 20 percent, and past the edge at 40 percent, with no configuration change in between.

The budget formula and how to size it

A retry budget sets the maximum retries as a ratio of successful or primary traffic, so that the sum stays under the cap. Write it as:

max_retry_fraction = (cap - planned_primary_in_flight) / planned_primary_in_flight

Using the worked example with a cap of 20 and planned primary of 16, the budget is 4/16, or 25 percent. That is the maximum share of traffic that may be retries at any moment. Two familiar implementations default to a similar number. Envoy's retry budget circuit breaker exposes budget_percent, which caps concurrent retries as a percentage of active and pending requests, and it defaults to 20 percent with a floor of 3 minimum retry concurrency (GEP-3388 retry budgets). Linkerd makes budgeted retries the default policy rather than a static max retry count, using the same shape of limit (GEP-3388 retry budgets).

The formula has three inputs you can actually measure. Cap comes from whichever limit binds first: pool size, an upstream concurrency limit, or a rate-limit header. Planned primary in flight is your working set at normal load, not your peak. The fraction falls out, and then you compare it to your observed error rate.

The decision rule that matters:

SituationRule to apply
Observed error rate well below budget fractionAllow retries; the dependency has slack
Error rate near budget fractionReduce primary concurrency before retries consume the rest
Error rate above budget fractionStop retrying, fail fast, let the caller decide
Dependency returns 429 or retry-afterRetry zero times until the stated time passes
Single blip on a quiet serviceAllow the minimum floor (a handful of retries)

That last row is why every budget needs a floor. On a low-traffic service, a strict percentage of a small number rounds to zero retries, so a single dropped connection turns into a user-facing error. Envoy's default minimum of 3 concurrent retries exists for this reason (GEP-3388 retry budgets). Set the floor at a number you can afford at your cap, not at your average.

Two related limits deserve the same treatment. If you are calling a third-party API rather than your own database, the provider is already enforcing a ceiling on your behalf, and the shape of that ceiling tells you what to budget for. Concurrency limits return 429 when the slot count is exhausted, and the response carries headers such as X-Concurrency-Limit-Limit and X-Concurrency-Limit-Remaining that you can meter against, with proactive metering recommended well before the limit is hit (concurrency limits). Rate limits keyed on requests or tokens per minute, like those on the Claude Messages API, are enforced differently: limits are defined per usage tier and a 429 comes with a retry-after header telling you how long to wait (rate limits). If your dependency gives you that header, honoring it is not optional politeness, it is the cheapest retry budget you will ever get.

Never average your way into a retry decision

The temptation with a budget is to size it from an average error rate or an average latency. Both averages hide the case you are budgeting for. A mean latency of 120 milliseconds can sit on top of a p99 of four seconds, and at a million requests a day that 1 percent tail is 10,000 slow responses (performance percentiles). The retries are triggered by the tail almost exclusively, because the healthy middle of the distribution never times out.

Percentiles also do not add. You cannot average per-instance p99 values to get a fleet-wide p99, and you cannot average per-minute p99 series into an hourly one; you have to keep the underlying histogram and recompute (p95 latency). For retry budgeting, the practical version of this rule is to measure at the dependency, not at the client, and to look at p95 and p99 concurrency rather than means. A dependency whose p99 in-flight count exceeds the cap once a minute will produce a periodic spike of pool waits that looks random in aggregate dashboards.

There is a compounding effect worth remembering when a single user action fans out to several backend calls. If a page load needs five parallel calls and each has 99 percent of responses under 100 milliseconds, the chance all five finish that fast is about 0.99 to the fifth power, or roughly 95 percent, so about one in 20 loads waits on someone's tail (p99 latency). Add a per-call retry on top and the fan-out multiplies both the offered concurrency and the chance that at least one branch is retrying. Budget at the fan-out level, not per hop, or the per-hop budgets will sum to something you never approved.

Implement the budget in the client, not in a comment

The budget only holds if it is enforced somewhere that sees all callers. Three placements work, and the trade-offs are worth stating.

PlacementStrengthsWeaknesses
Sidecar or service mesh retry budgetOne config, sees every caller, no app changesNeeds mesh adoption; semantics differ by data plane, which is why the Gateway API work exists (GEP-3388)
Shared semaphore in the clientSimple, lives with the code, easy to testPer process; N instances means N budgets unless you divide through
Upstream budget via rate-limit headersAccurate, provider-maintainedOnly available where the dependency exposes it (concurrency limits)

If you go with the in-process route, the counter has to be shared by primary and retry calls. A sketch in Python, using a semaphore sized to the cap and a retry gate that checks the budget before spending a slot:

from threading import Semaphore, Lock

CAP = 20
PRIMARY = 16
BUDGET = CAP - PRIMARY          # 4 retry slots
slots = Semaphore(CAP)
retry_slots = Semaphore(BUDGET)
lock = Lock()
retries_in_flight = 0

def call(fn, is_retry=False):
    if is_retry:
        if not retry_slots.acquire(blocking=False):
            raise RuntimeError("retry budget exhausted")
    try:
        with slots:
            return fn()
    finally:
        if is_retry:
            retry_slots.release()

The important line is the non-blocking retry acquisition. A retry that waits for a budget slot has stopped being a retry budget and become a second queue, and a queue inside a degraded dependency is how the original error turns into a cascade. If the budget is exhausted, fail fast and let the caller (or a higher-level policy) decide.

If your dependency is a database, the same math applies to pool size, and the sizing has to happen across the whole deployment rather than per pod. Each instance carries its own pool, so twenty pods with a pool of twenty demand 400 connections, which can exceed a server-side max_connections even though each pod looks reasonable (connection pool exhaustion). The usable budget is the server limit minus admin, migration, and monitoring reserves, divided by the maximum autoscaled instance count, sized against the peak instance count rather than today's steady state (connection pool exhaustion).

Once retries are part of the picture, a pair of backoff and a jitter is not enough on its own. Exponential backoff spaces retries geometrically so the target gets breathing room, and jitter decorrelates retry waves across callers so they do not arrive in lockstep, but both bound the shape of an individual caller's retries while the budget bounds the aggregate (resilience patterns at scale). Use all three, and put a circuit breaker in front of a dependency that is consistently failing so the retries stop entirely for a window.

What to monitor so the budget stays honest

Four signals, all cheap to emit:

  1. Retry fraction. Retries divided by primary requests, sampled every few seconds. Alert when it crosses 80 percent of the configured budget for a sustained window. This is the leading indicator that the dependency is degrading, and it usually moves before p99 does.
  2. In-flight concurrency at the dependency. Count primary and retry together. If p99 in-flight count equals the cap, your headroom is gone regardless of the error rate.
  3. Pool or slot wait time. Under 1 millisecond healthy, above 10 milliseconds congested, per the thresholds above (connection pool exhaustion). Rising wait time with a static error rate means retries are consuming the spare capacity.
  4. Pool wait time versus query execution time. If waiting for a connection exceeds the time spent executing, the bottleneck is contention, not the query, and adding pool size will only shift the queue downstream (connection pool exhaustion).

For a database-backed service, a quick check of connection states separates the ordinary case from the pathological one. Postgres exposes pg_stat_activity, and a high count of connections in idle in transaction is a hallmark of holding a connection across a slow external call, which is exactly the pattern that starves a pool under retry load (PostgreSQL connection states). A count that climbs steadily and never drops is a leak, not a budget problem, and increasing the budget will delay the discovery without preventing it.

One more habit closes the loop. When you set a budget, write the test that proves it. Drive the service at planned primary concurrency with an injected error rate just above the budget fraction, and assert that dependency in-flight count never exceeds the cap and that retries stop being issued once the budget is spent. The retry policy that looks correct in staging against clean, isolated failures is precisely the one that amplifies load when hundreds of callers hit the same slow dependency at once (the retry storm). Testing at one caller and one error never exercises the correlated case.

If your callers fan out to several model providers rather than one dependency, the budget has to be shared across all of them, or a provider-specific cap becomes invisible when the router fails over. Running every model behind one key with a single concurrency pool is one way to make that budget enforceable in one place: Quanta Inference puts text, image, video, audio, and embedding models behind one OpenAI-compatible API, so retry and concurrency policy is configured once rather than per provider.

FAQ

FAQ

Does a retry budget replace max retries per request?

No. They bound different things. A per-request max retry count caps how many attempts a single call makes; a retry budget caps the aggregate share of traffic that retries may consume across all callers. You want both, with the per-request count small (one or two) and the budget enforced where all callers meet.

How do I pick the budget percentage?

Work backward from the cap. Subtract your planned primary concurrency from the cap, divide by planned primary, and you have the maximum retry fraction. At a cap of 20 and primary of 16, that is 25 percent. Then check it against observed error rate: if your p95 error rate already exceeds the fraction, the budget will bind constantly and you should reduce primary concurrency instead.

What happens when the budget is exhausted?

The retry is refused and the original failure propagates immediately. That is the point: failing fast at the caller is cheaper than queueing at a degraded dependency. A circuit breaker should typically open around the same threshold so the failed calls stop reaching the dependency at all.

Should the budget count retries of successful requests?

No, only failed attempts consume budget. Count every attempt that was issued because a prior attempt failed, and compare that against primary requests, which is how Envoy's budget_percent frames it: concurrent retries as a percentage of active and pending requests (GEP-3388 retry budgets).

Does honoring retry-after make a budget unnecessary?

It helps for the dependency that sends one, and the Claude rate-limit documentation is clear that a 429 with retry-after means you wait that many seconds before retrying (rate limits). But many dependencies send nothing on a timeout, and a slow dependency that has not started failing will not send a header either. The budget covers the cases the header does not.

Sources

Sources

  1. Retry and Timeout Patterns in Distributed Systems
  2. Connection Pool Exhaustion: The Silent Killer
  3. Connection Pool: Detect & Fix Issues Fast
  4. Retry Storm Antipattern - Azure Architecture Center
  5. GEP-3388: Retry Budgets
  6. Concurrency Limits - Encompass Developer Connect
  7. Rate limits - Claude Platform Docs
  8. Performance Percentiles: p50, p95, p99 Explained (2026)
  9. P95 Latency: What It Is & Why It Matters
  10. What Is P99 Latency? Understanding the 99th Percentile of ...
  11. Connection Pool Exhaustion: Causes, Diagnosis & Fixes
  12. Resilience Patterns at Scale: Exponential Backoff, Jitter, ...
  13. PostgreSQL Connection States: Types, Monitoring &
  14. The retry storm we caused with good intentions
About the author

About the author

Antonio Evans
Antonio Evans

Antonio Evans is the founder of Quanta Intelligence and a fractional CTO who builds HIPAA-ready AI systems for health and life-science companies. Before that he was technical co-founder of FriendsEAT for twenty years, CEO of Socialdraft, and a data engineer at IBM. Antonio lives with his dog Santino in Lisbon, Portugal.

All articles
