
Founders

How to Keep a Model's Theme Tags Stable Across Batches

Antonio Evans8 min read

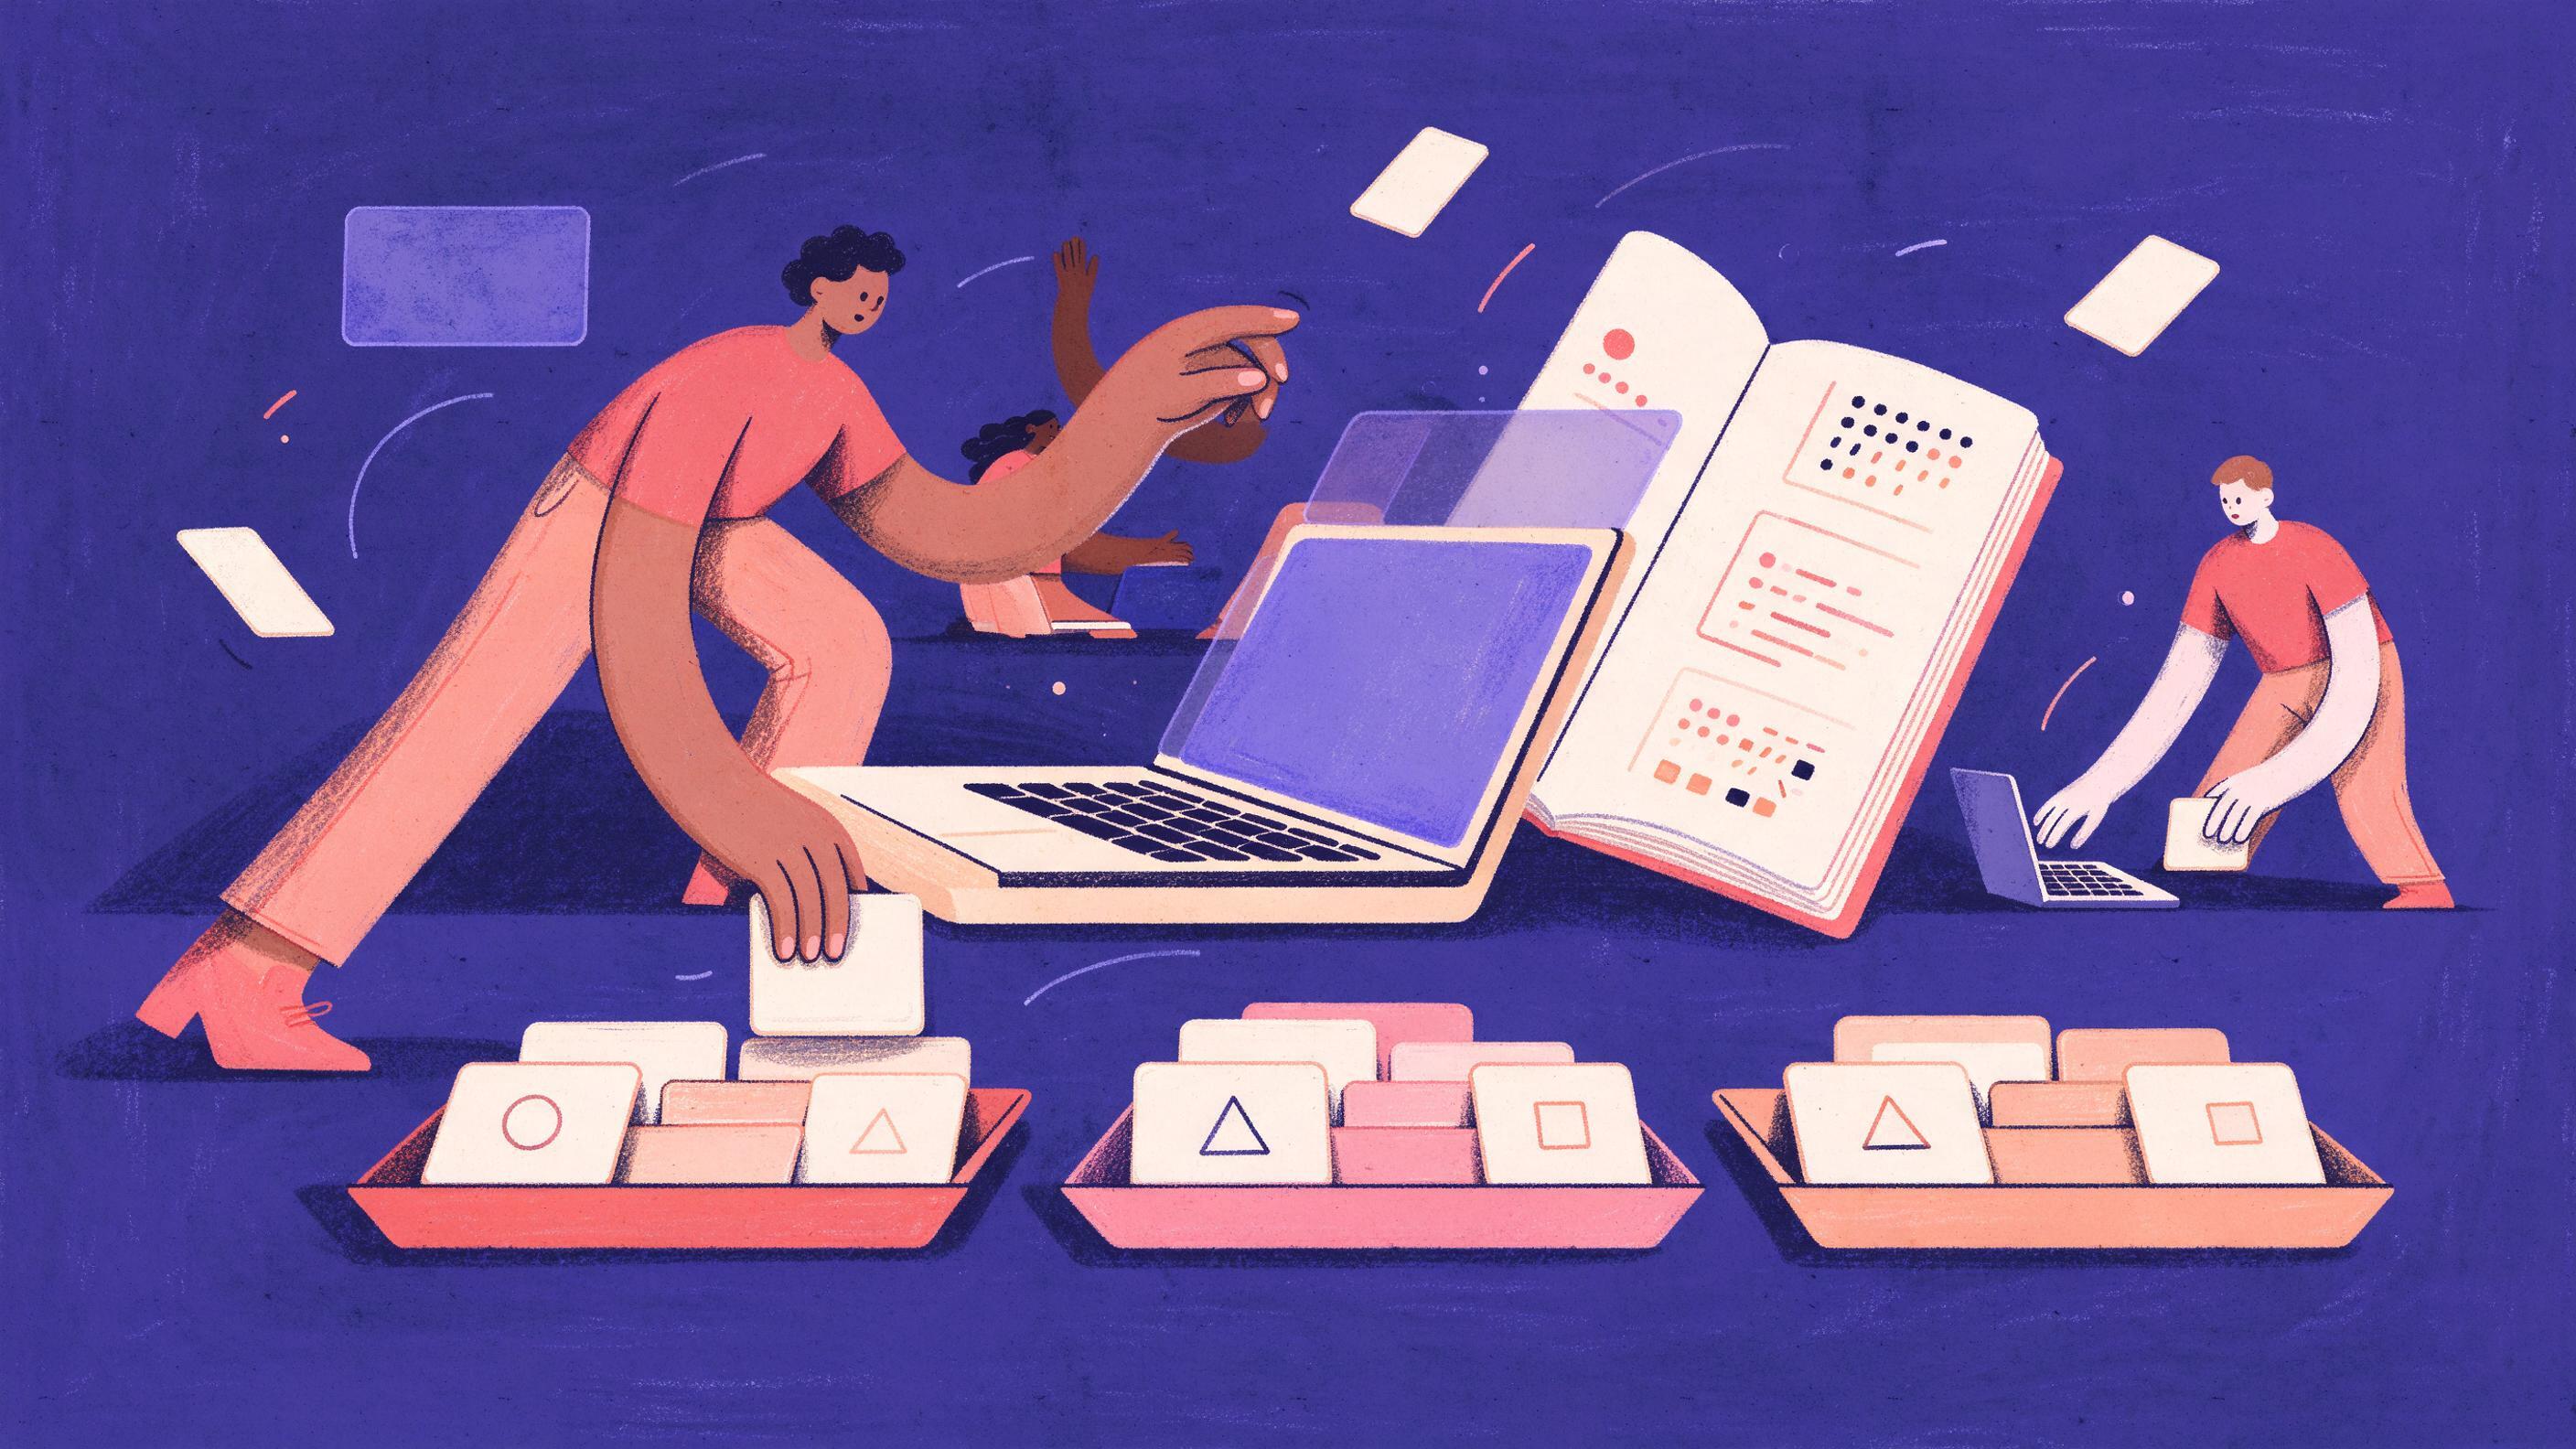
A person at a laptop sorts short text cards into trays labeled YES, NO and ASK, with an open codebook page beside them showing yes, no and boundary examples for one theme.
Key points

Key points

  1. 1A stable theme tag needs three parts in its definition: a presence rule, at least two positive examples, and at least two negative examples that look similar but must not get the tag.
  2. 2Boundary cases, items that sit between two tags, need a written precedence rule so the same item gets the same tag no matter who (or what) applies the codebook.
  3. 3Store the codebook in version control, attach the codebook version to every batch, and re-score a fixed anchor set before each new batch ships.
  4. 4When a batch surfaces a new edge case, add it as a new boundary example with a changelog entry instead of rewriting the definition, so the tag grows without moving.

Why tags drift when you tag in monthly batches

Tag drift is the slow divergence between what a tag meant at batch one and what it means at batch twelve. It rarely comes from one bad decision. It comes from small ones: a coder resolves an edge case in chat, a reviewer makes a judgment call that nobody records, a new annotator reads the definition a little differently. Qualitative researchers see the same thing in codebook development, where a definition that lives only in someone's head produces a different set of themes from every analyst who applies it. The Delve codebook guide treats consistency, transparency and collaboration as the main reasons to write one down in the first place the Delve codebook guide.

The labeling literature names the most common failure precisely. Guideline creep happens when a Slack message or a single reviewer call clarifies an edge case and "what counts" shifts, but the dataset never records when or why it shifted. The symptom is systematic: older batches disagree with newer batches on the same patterns annotation drift checks. If your theme counts trend in one direction while the underlying text stays flat, that is drift, not signal, until you prove otherwise.

There is a second, less obvious source: the model itself. A model's judgment is sensitive to how it was prompted and what it has already seen in a conversation or a batch, and it can anchor on the first framing it gets. Experimental work on anchoring bias in large language models found responses sensitive to biased hints, and found that simple fixes such as chain-of-thought prompting or telling the model to ignore the hint did not reliably remove the effect; you need information from several angles the anchoring bias study the published version. Practically: tag each item in a fresh context, from a codebook that carries its own counter-examples, rather than relying on the prompt to "be consistent."

Human coding has the same problem, which is why the codebook, not the coder's instinct, is the unit of stability. Studies of inter-coder agreement recommend developing a deductive codebook, writing a process for resolving disagreements, and keeping an audit trail of every codebook change the inter-coder agreement paper.


The three-part definition: presence, positive examples, negative examples

Write every theme definition to answer three questions in order: what must be present for this tag, what real items got this tag, and what real items look close but must not get it.

The first part is a presence rule, one sentence, no adjectives that need interpretation. "Customer says they abandoned setup before inviting a teammate" is a presence rule. "Customer had a bad onboarding experience" is not, because "bad" is a judgment call and "onboarding" is a phase, not an event.

The second part is positive examples, at least two, quoted verbatim from your own data and trimmed to the sentence that does the work. The third part is negative examples, also at least two, chosen for proximity: near misses that share vocabulary with the theme but fail the presence rule. The codebook guidance from Koji lays out a five-column structure (code name, definition, inclusion criteria, exclusion criteria, example excerpt) and notes that a code missing its exclusion criteria or its example will be read differently by a second coder the Koji codebook guide. Delve's guidance makes the same point: include non-examples, because near misses clarify boundaries and often reveal redundant codes worth merging the Delve codebook guide.

A worked entry, written for a support-ticket tagging project:

### Tag: setup-abandonment
Presence rule: The writer states they stopped using the product
during initial setup (before first successful core action) and did
not return.

Include when:
- Explicit stop, plus the setup phase is named.
- "I gave up", "I never finished", "I couldn't get past".

Positive examples:
1. "I signed up Thursday and by Tuesday I still hadn't figured out
   how to add my team, so I just gave up."
2. "Got stuck on the import step, closed the tab, never went back."

Negative examples (near misses, do NOT tag):
1. "Setup took a while but I got there in the end." (completed)
2. "I can't find the export button." (feature gap, post-setup)

Boundary rule: If the writer describes both a setup problem and a
general product complaint, apply setup-abandonment only when the
stop is explicit. Otherwise tag feature-gap.

The negative examples are doing most of the work here. Without them, a model or a junior coder will happily tag "setup took a while but I got there" because every keyword matches. With them, the exclusion is concrete and checkable, and the tag holds its meaning batch after batch.

Boundary cases and a precedence rule

Boundary cases are items that sit between two tags. You have three honest options, and only one of them keeps a codebook stable.

OptionWhat it means in practiceEffect on stability
Let the coder decideEach borderline item resolved by judgmentHigh drift, low auditability
Force one tag alwaysPick a default winner for the pairStable but hides real ambiguity
Written boundary rule plus second reviewRule says which tag wins; boundary items route to a second reviewerStable, auditable, improves the codebook

Take the third. For each pair of tags that repeatedly collide, write one precedence sentence and store the colliding pairs as boundary examples. For example: "If an item names a workaround the person built themselves, tag workaround, even when it also describes the original failure; the failure is context, not the theme." That single sentence can settle hundreds of items, and it is checkable, which is what inter-rater agreement needs. The inter-coder agreement literature stresses that statistical agreement measures only make sense once you have a codebook and a disagreement-resolution process in place; without them you get the appearance of rigor rather than the substance the inter-coder agreement paper.

Boundary items should not be guessed, by a person or a model. Route them to a second reviewer, record the decision, and if the same shape of item shows up a third time, promote the decision into the codebook as a new boundary example. The Roberts et al. case study on codebook development describes this as an iterative discipline: build the codebook, test it on fresh data, revise it where it fails, and document the revision the codebook development case study.

One more caution on models specifically: a language model will usually give you a confident answer to a borderline item, and confidence is not correctness. Research comparing open-source models against human coders in thematic analysis found rough alignment but also that 22 to 39 percent of model-generated codes were duplicative and nearly half lacked sufficient context the LLM qualitative analysis study. Treat a model's boundary call as a draft, not a verdict.

Put the codebook in version control and pin it to every batch

A codebook that exists outside version control is a rumor. Put it in a repository as a single Markdown or YAML file, one entry per tag, and treat every change as a commit with a message that says which batch produced it and why.

Structure that survives scale:

codebook/
  themes.yaml          # tag definitions, examples, boundary rules
  CHANGELOG.md         # one entry per change, with batch id and reason
  anchors/
    anchor_set.jsonl   # fixed items with agreed tags, never edited
  batches/
    2025-11/batch.jsonl
    2026-01/batch.jsonl

Each batch record should carry the codebook commit hash it was tagged against. That single field turns "why do these counts disagree" from an afternoon of archaeology into a one-line lookup. The annotation-drift checks recommend exactly this: version guidelines like code, attach the guideline version to every label, and re-label a small anchor set after each change to quantify its impact annotation drift checks.

The anchor set is the part teams skip and later regret. Keep 30 to 50 items whose tags are settled by consensus, spanning every theme and at least a few boundary cases. Before tagging a new batch, re-score the anchors under the current codebook. If agreement with the consensus tags drops, stop and find out why before processing thousands of new items. This is a cheap tripwire. It costs a few minutes per batch and catches drift at the point where it can still be fixed with a codebook edit rather than a re-labeling project.

Where the tagging runs against a hosted model, batch the calls so each item is tagged independently, with the codebook embedded in the prompt and no prior item's output in context. Quanta Inference exposes text, image and embedding models behind one OpenAI-compatible API key with prepaid US-dollar pricing, which suits this pattern of many small independent classification calls run on a schedule Quanta Inference.

A batch procedure that holds the line

The procedure below is deliberately boring. Boring is the point: predictability is what keeps a definition steady.

  1. Pull the codebook at a pinned commit. Record the commit hash in the batch manifest.
  2. Re-score the anchor set. Require agreement at or above your threshold (pick one and write it down; 90 percent is a defensible starting line for clearly defined tags).
  3. Tag the batch. Every item gets exactly one tag from the existing set, or the flag boundary.
  4. Route every boundary item to a second reviewer. Two reviewers disagreeing on the same pair three times is a signal the codebook needs a precedence rule, not a reminder to "use judgment."
  5. Compare the tag distribution with the previous batch. A shift larger than what the sample size and mix of source material can explain deserves a look before you publish.
  6. Log every new edge case as a proposed boundary example in a pull request. Merge only with a changelog line naming the batch and the reason.
  7. Freeze or archive the batch with its codebook hash so any future reader can reconstruct exactly which rules produced it.

Step 4 is where most teams improve fastest. The boundary queue is a running list of the places your definitions are thin, and thinning is normal. What matters is that thin places get patched in the codebook rather than absorbed silently into the tags.

Add, don't rewrite: how the codebook grows

The instinct when a batch produces a surprise is to rewrite the definition. Resist it. Rewriting moves the meaning of every past tag without telling anyone, and your month-over-month counts become incomparable overnight.

Add instead. Keep the presence rule intact, append the new item as a boundary example with its resolution, and write a changelog entry. If the new case genuinely contradicts the presence rule, that is a different situation: open a deliberate revision, bump the codebook version, re-score the anchors, and annotate the affected batches with both versions. The Delve process puts "continuously review and refine" last on its list for good reason, after the definitions and examples exist the Delve codebook guide. Refinement builds on a written baseline; it does not replace one.

Two smaller habits reinforce the same goal:

  • Cap the catch-all. Every scheme has an "other" tag. Set a maximum share of items it may hold per batch, and require a reason when it is chosen. An uncapped other bucket becomes a trash compactor and absorbs the ambiguity you were trying to resolve annotation drift checks.
  • Reuse codes across batches rather than reinventing them. Analysts who reuse a code set find later comparison far easier than those who start fresh each time, because the label means the same thing throughout one practitioner account of line-by-line coding.

The same discipline applies when a model does the tagging. A model prompted with the full codebook, including negative examples and boundary rules, reproduces those rules far more faithfully than one prompted with a tag name and a sentence of description. The model is not the source of stability; it is a very fast, very literal reader of whatever the codebook says. Write for the literal reader and the human reviewers will find their job easier too.

FAQ

FAQ

How many examples does each tag really need?

Two positive and two negative is the working minimum, and the negatives should be near misses rather than obvious non-cases. The Koji codebook guide notes that a code missing exclusion criteria will be read differently by different coders the Koji codebook guide. Add more examples over time as new edge cases appear, and never delete an example that once settled a real disagreement.

What do I do when two reviewers disagree on a boundary item?

Log the disagreement with the item text and both tag choices, and route it to a third reviewer or a short discussion. If the same pair of tags collides three times, write a precedence sentence into the codebook and add the case as a boundary example. The inter-coder agreement literature treats a documented disagreement process as a precondition for meaningful agreement measurement the inter-coder agreement paper.

Can a language model apply the codebook on its own?

It can apply it consistently if the codebook is complete and each item is tagged independently, but it should not be the final word on ambiguous items. Studies of LLMs in qualitative analysis report partial alignment with human coders alongside substantial duplication and missing context the LLM qualitative analysis study. Use the model for the clear majority and send boundary items to a person.

Does the anchor set need to change over time?

Change it rarely and deliberately. Anchors exist to detect drift, so swapping them out whenever they disagree with the current codebook defeats the purpose. If a definition is formally revised, create a second anchor set for the new version rather than editing the original, so you can measure the effect of the revision directly.

How do I handle a batch where the topic mix is genuinely different?

Rerun the anchor set first: if anchor agreement holds, the codebook is probably fine and the shift is in the data, not the tags. If agreement drops, investigate before tagging the rest. The annotation-drift guidance recommends exactly this re-labeling step after any change to guidelines, and it applies equally to a change in the batch itself annotation drift checks.

Sources

Sources

  1. How to Create A Codebook for Thematic Analysis
  2. The Myth of “Clean Labels” in ML. Why annotation drift ...
  3. Anchoring Bias in Large Language Models
  4. Anchoring bias in large language models: an experimental study
  5. inter-coder-agreement-in-qualitative-coding-considerations ...
  6. How to Build a Qualitative Research Codebook (With ...
  7. Attempting rigour and replicability in thematic analysis of ...
  8. Large Language Models in Qualitative Analysis
  9. From qualitative interview transcriptions, how do I code and ...
About the author

About the author

Antonio Evans
Antonio Evans

Antonio Evans is the founder of Quanta Intelligence and a fractional CTO who builds HIPAA-ready AI systems for health and life-science companies. Before that he was technical co-founder of FriendsEAT for twenty years, CEO of Socialdraft, and a data engineer at IBM. Antonio lives with his dog Santino in Lisbon, Portugal.

All articles
