Security

How to Prove Each Control Works: Test Cases for Your Risk Map

Antonio Evans11 min read

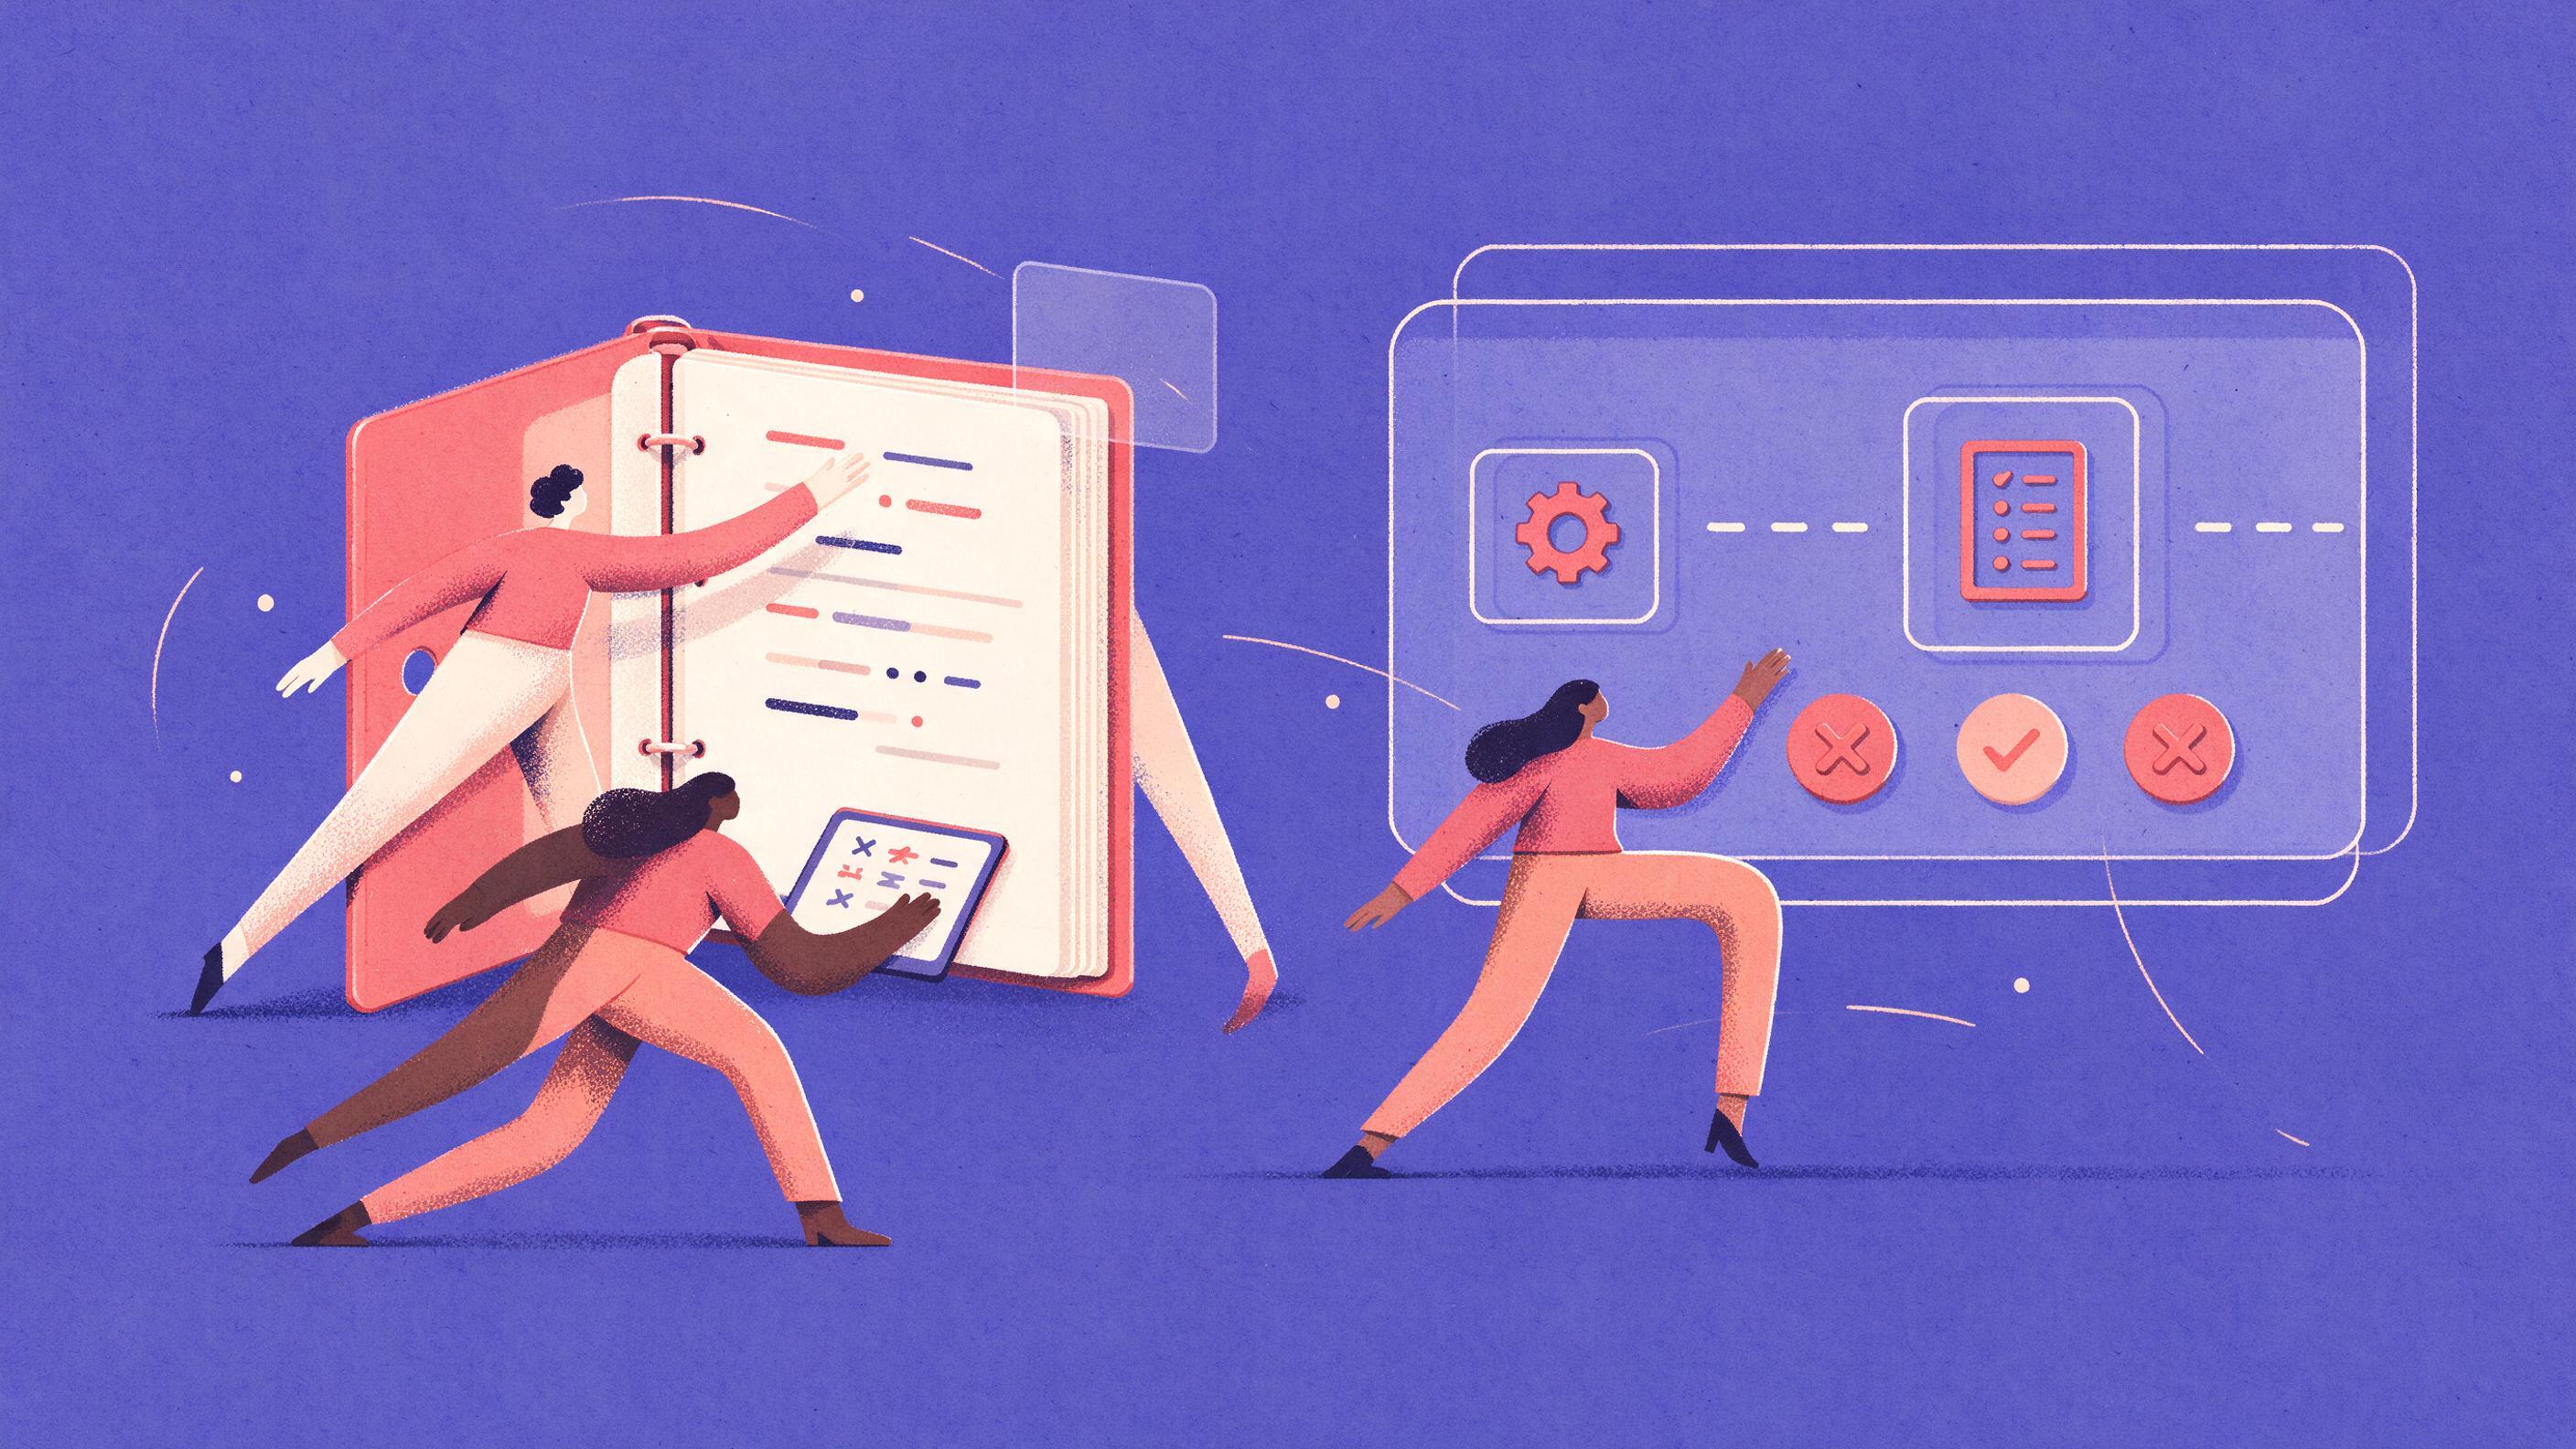
A split scene: on the left, a binder labeled 'Risk Map' open to a page with a control described in text; on the right, the same control shown as a CI pipeline stage with three test result badges (pass, fail, pass).
Key points

Key points

  1. 1A written control is a hope; an executable control is evidence, because a test that fails blocks the release before the control can be skipped.
  2. 2Start with three control families that check mechanically: input limits, output filters, and credential denial, and give every test the control ID from the risk map.
  3. 3The test has to send a known-bad input or request a forbidden action and assert the rejection or sanitization, then record that result where auditors can read it.
  4. 4Wire the suite into the pipeline as a required gate, so the release stops when a control regresses rather than when someone remembers to look.

Why a written control is not a control yet

A risk map lists controls as sentences: "inputs are limited to 4,000 characters," "PII is redacted from responses," "the agent's service account cannot delete rows." Sentences are easy to write and easy to drift away from. Six months later the limit lives in a frontend validator that an API client bypasses, the redaction runs on one endpoint out of four, and the database grant was widened to fix a support ticket. Nobody lied; the control simply stopped being true without anyone noticing.

The fix is discipline that security teams already apply elsewhere: every control becomes a test that runs before every release. The OWASP GenAI Security Project maps each LLM risk to concrete controls, which is a useful starting point for the list you are converting. For example, LLM10 Unbounded Consumption recommends strict input validation so inputs do not exceed reasonable size limits, alongside rate limiting and quotas. Each of those recommendations can be turned into a test with an expected result.

The pattern is not unique to AI. Teams that already run security testing in CI attach checks to the pipeline and report findings in the review context developers use, rather than in a dashboard nobody opens, as Cycode describes. A control test is the same idea scoped to a control you already wrote down.

One decision rule frames everything below: if a control's failure could be detected by sending one specific request and comparing the response, it belongs in the CI suite. If it cannot, it needs a different kind of evidence. Most controls in a modern AI risk map fall in the first bucket.


From control statement to test, in six steps

Treat this as a template you repeat for every row of the risk map. The work is mostly clerical once the pattern is clear, which is the point: a repeatable conversion beats a heroic one.

  1. Take one control statement and name the observable. "Inputs are limited" becomes "a request with a 100,000-character prompt returns HTTP 413 and the model is never called."
  2. Choose the known-bad input. Something that would succeed if the control were absent. Oversized strings, forbidden characters, out-of-range numbers, a URL with a javascript: scheme, an email address in the response body.
  3. Choose the expected outcome, and make it specific: a status code, an error type, a redacted marker in the payload, a denied permission error.
  4. Assert that the forbidden thing did not happen. For credentials, this means asserting the denial, not just the absence of a crash. A 200 with deleted rows is the failure you are hunting.
  5. Tag the test with the control ID from the risk map. One ID may have several tests; every test points back to exactly one control.
  6. Write the result to an evidence file that the pipeline archives: control ID, test name, pass or fail, timestamp, build number. That file is what you hand a reviewer who asks whether the control is operating.

That last step is where most programs stop short. A green pipeline run is not evidence unless it is attributable. A machine-readable file per build, stored with the release artifact, turns "we think this control works" into "here is the run against commit X, and the control passed."

The following table is a quick way to decide what kind of test a control deserves.

Control wordingTest typeKnown-bad inputPass condition
Input length is cappedUnit or integration100,000-character stringRejection with error code, no model call
Input charset is restrictedUnitEmoji, null byte, right-to-left overrideRejection or normalization per policy
Numeric field is in rangeUnitValue outside min or maxValidation error, no downstream write
PII is redacted in outputIntegration with fixed fixturePrompt that elicits a known test emailMarker present, raw value absent
URLs in output use allowed schemesUnit on filterjavascript: and data: payloadsStripped or replaced
Service account is least privilegeIntegration against a staging DBDELETE on a table it should not touchPermission denied error
Token is short-livedUnit plus clock injectionToken after expiry window401 rejected
Secret paths are blockedIntegrationRead from a secret directoryDenied or not found, logged

Control family one: input limits

Input limits are the easiest controls to test and the ones most often checked in the wrong place. The OWASP Input Validation Cheat Sheet is blunt about ordering: apply request size limits before buffering or parsing input, because a schema check after parsing cannot protect a parser that has already exhausted resources. Your test should prove the limit sits in the right layer, not just that some code path rejects long strings.

A useful structure is a small repository of cases per field, each with an expected outcome, driven by one runner. Written in Python, the runner is unremarkable:

import pytest

CASES = [
    ("input.max_length", "A" * 100_000, 413, None),
    ("input.charset", "hello\u200bworld", 400, None),
    ("input.numeric_range", 250, 400, "quantity out of range"),
]

@pytest.mark.parametrize("control_id,payload,status,detail", CASES)
def test_input_limit(client, control_id, payload, status, detail):
    response = client.post("/v1/ask", json={"prompt": payload})
    assert response.status_code == status, control_id
    if detail:
        assert detail in response.text
    record_evidence(control_id, "pass")

Three families of case matter most here.

Length. Test at the boundary, not just far beyond it. If the control says 4,000 characters, assert that 4,000 is accepted and 4,001 rejected. Then add a gross case (100,000 characters) because that is what a denial-of-wallet attempt looks like. OWASP notes that attackers can overload a model with numerous inputs of varying lengths and that continuous input overflow past the context window wastes compute, per its LLM10 entry.

Character set. Use an allowlist mindset, not a denylist. The OWASP cheat sheet warns that blocking apostrophes rejects legitimate names without making a query safe, and that free-form comments should permit broad Unicode while limiting length. So your charset test asserts the policy you actually chose: either the field rejects unusual scripts or it normalizes them, and either way the test records which.

Numeric range and structure. Convert text to an integer only establishes a type, not an acceptable quantity, the cheat sheet notes. Test the value outside the range, the missing field, the null, and the array with too many items.

One insight the first search result rarely gives you: test the layer, not just the behavior. Send the known-bad input directly to the internal endpoint that the frontend calls, bypassing the client-side validator. Client-side validation improves user experience and can never be a security control, since attackers control everything past it. A test that only exercises the browser form will pass forever while the API stays open.

You can also test the rate limit while you are in the file. Fire N plus one requests in a burst and assert the extra one gets a throttle response. That is the second half of the LLM10 control and it takes a few lines.

Control family two: output filters

Output controls catch what got through. The distinction matters because teams routinely put everything on the input side. One practitioner write-up makes the point directly: overzealous input filtering can suppress legitimate user intent, while output filtering is where disclosure and unsafe content get caught, and guard logic scattered through ad hoc code paths is hard to test against real behavior. Your test suite is what turns scattered guard logic into a measured control surface.

Three output controls are worth writing tests for on day one.

PII redaction. Use a deterministic fixture: seed the system with a known fake email, phone number, and account number, prompt the model to repeat them, and assert the response contains the redaction marker and not the raw string. The expected outcome is a negative assertion (raw value absent) plus a positive one (marker present), because either alone can be satisfied by an empty response. Keep the fixture values clearly synthetic so the test never becomes a real data-leak path itself.

The risk this addresses is not theoretical. OWASP's Top 10 includes sensitive information disclosure and improper output handling as separate risks, and its Improper Output Handling entry covers insufficient validation and sanitization of what the model produces. A test that fails when the redactor is removed is the only proof the redactor is wired in.

Allowed URL schemes. If your application renders links the model produces, the filter must reject javascript: and data: schemes. Test it by prompting for a link under each disallowed scheme and asserting the output contains a neutralized form or nothing. This is the output-side twin of input charset tests, and it catches the classic case where a model helpfully returns a link an attacker supplied earlier in the context.

Content safety. Here you need a threshold decision. Classifier-based content checks are probabilistic: they catch much more than regex but not everything, and they produce false positives. A practitioner account of four deployments reports regex filters catching roughly 60 to 70 percent of injection attempts and classifier-based checks reaching 89 to 94 percent, with combined layers approaching 99 percent; treat those as that team's measurements, not universal constants. The lesson for testing is that you assert on a labeled set of, say, 50 known-bad and 50 known-good outputs and set a pass threshold (for example, at least 90 percent of bad ones caught and at least 95 percent of good ones passed through). That is a test you can run in CI with a fixed model, fixed prompt, and fixed fixtures.

Two rules keep output tests honest. First, pin the model and sampling settings for the fixture run; a stochastic response makes a flaky test. Second, if the output depends on a live model, run that subset nightly rather than on every commit, and keep the deterministic subset (redaction of echoed fixtures, URL scheme handling) in the fast gate.

It is also worth testing the layers separately. The same practitioner account notes that the biggest production failures it saw came from output guardrails that were too aggressive, not too permissive, and that false positives blocking legitimate queries destroy user trust. So every output filter suite needs a pass-through set: legitimate requests that must not be blocked, asserted just as firmly as the bad ones. A filter that blocks everything passes every security test and fails the product.

Control family three: credential denial

This is the family that turns "the agent has least privilege" from an aspiration into a tested fact, and it is where most risk maps are weakest. OWASP's Excessive Agency entry names excessive functionality, excessive permissions, and excessive autonomy as root causes, with examples including a read-only extension whose database identity also has UPDATE and DELETE, and an extension acting for one user that connects with a privileged account reaching all users' files. Each example implies a test.

Merely asserting that a dangerous action does not crash is not enough; the test must assert the denial. Run it against a staging database with the real service account and the real grants.

def test_agent_cannot_delete(staging_db, agent_credentials):
    with connect(staging_db, agent_credentials) as conn:
        with pytest.raises(PermissionDeniedError):
            conn.execute("DELETE FROM customers WHERE id = 1")
    record_evidence("cred.least_privilege_db", "pass")

Three tests cover most of this family.

Least-privilege service account. Enumerate the grants the account holds and compare them to the allowlist in the risk map. Then back the comparison with an actual attempted operation for each forbidden verb: DELETE, UPDATE, DROP, and whatever else the control names. A grant list can be stale; a denied operation is current. A least-privilege framework for agent tool calling develops the same idea at the task level, activating only the roles a current task needs rather than leaving permissions active across tasks, and argues that overprivileged connector configurations are common enough to be found in deployed assistants.

Short-lived tokens. Test with an injected clock: mint a token, advance past its expiry, call the service, assert 401. Also assert the positive case, that a fresh token works, so the test cannot pass by rejecting everything. If tokens are meant to scope to one resource, add a test that the same token fails on a different resource.

Blocked secret paths. If the agent can read files or fetch URLs, test that it cannot reach credentials. Point it at /proc/self/environ, a cloud metadata endpoint, and your secret store mount, and assert each is denied and logged. These are the paths an attacker goes for after a successful injection, and a filter list without a test is a guess. OWASP's LLM07 entry covers exactly the failure where hidden context holds login credentials and an attacker pulls them out and reuses them, so the test should also assert that no secret value appears in the model's visible context at build time.

Keep these tests in the integration tier against a disposable staging environment, not against production. You want the real grant model and no real data.

Wiring the suite into the pipeline

A test that does not gate the release is a suggestion. Wire it in three moves.

First, run the fast tier (input limits, deterministic output filters, token expiry with an injected clock) on every pull request. Keep it under a few minutes so developers do not route around it. Second, run the slow tier (live-model safety thresholds, service-account denial against staging) on every merge to main and before every release. Third, make the release job depend on both and refuse to promote on failure.

Harnes's guide to automated security testing describes the mechanics in a general pipeline: identify what needs testing through risk analysis, prepare test data, and integrate the tools into the build and test stage so the checks run automatically rather than by hand. That last phrase is the whole argument: manual testing is time consuming and does not scale. Cycode's ten-step account adds the placement rule that matters most here: some checks belong close to the developer, others later, and findings have to arrive in the review context where people act on them. A failing control test should comment on the pull request with the control ID and the offending input, not file a ticket into a queue.

Two operational details make the gate survive contact with a busy team:

  • Quarantine, do not silence. A flaky test gets a tracking issue and a deadline, never a skip flag with no expiry. Skipped tests are how controls disappear.
  • Version the evidence. Store the evidence file with the release artifact and the commit SHA. When a reviewer asks, you produce one file, not a meeting.

The evidence file is also how you answer the harder question a risk committee eventually asks: not "is the control written," but "how many of our controls are tested, and when did each last pass." A simple scoreboard, controls total, controls with at least one test, controls passing in the last release, is more persuasive than any prose. When that number slips after a refactor, the pipeline already told you.

If the pipeline itself is where your team is thin, a short working session can map the controls to tests and agree on the gate. A free consultation is one way to get a second pair of eyes on the conversion before it hardens.

FAQ

FAQ

How many tests does each control need?

As many as it takes to prove the control's observable failure mode, usually one to three. Length limits need a boundary case and a gross case. Least privilege needs one attempted operation per forbidden verb. The rule is coverage of the failure mode, not a count, and every test should point at exactly one control ID.

What do I do when a control cannot be tested mechanically?

Split it. Most untestable controls are actually two controls: a mechanical part (the policy exists, the config value is set) and a judgment part (the policy is right). Test the mechanical part in CI and schedule a human review for the judgment part, with a dated record. Deciding the split is the useful work.

How do I stop security tests from making the pipeline slow?

Sort by cost. Deterministic checks with fixtures run on every pull request and stay under a few minutes. Anything that calls a live model, or needs a staging database with real grants, runs on merge to main and before release. Developers tolerate a fast gate and route around a slow one.

Output filters produce false positives. Should the test fail?

Yes, if the pass-through set fails. Every output filter suite should include legitimate requests that must not be blocked, weighted at least as heavily as the bad inputs, because over-aggressive filtering destroys trust faster than an occasional bad answer. A test that only checks blocking will pass while the product breaks.

Who owns the control tests after launch?

The team that owns the service owns the tests, and the security function owns the mapping from control ID to test. That split keeps the tests alive through refactors, because the people changing the code are the people who must keep the assertions green. Ownership that sits only with security tends to produce stale suites.

Sources

Sources

  1. OWASP LLM10: 2025 Unbounded Consumption
  2. How to Integrate Security Testing into CI/CD Pipelines - Cycode
  3. Input Validation - OWASP Cheat Sheet Series
  4. What do teams get wrong about LLM input validation and ...
  5. LLMRisks Archive - OWASP Gen AI Security Project
  6. LLM Guardrails That Actually Work in Production
  7. LLM06:2025 Excessive Agency - OWASP Gen AI Security Project
  8. PDF A Least Privilege Framework for Authorizing Tool Calling Agents
  9. Integrating Automated Security Testing in CI/CD Pipelines - Harness
About the author

About the author

Antonio Evans
Antonio Evans

Antonio Evans is the founder of Quanta Intelligence and a fractional CTO who builds HIPAA-ready AI systems for health and life-science companies. Before that he was technical co-founder of FriendsEAT for twenty years, CEO of Socialdraft, and a data engineer at IBM. Antonio lives with his dog Santino in Lisbon, Portugal.

All articles