
Fintech

How to Replay a Decision Log Against a Candidate Model

Antonio Evans9 min read

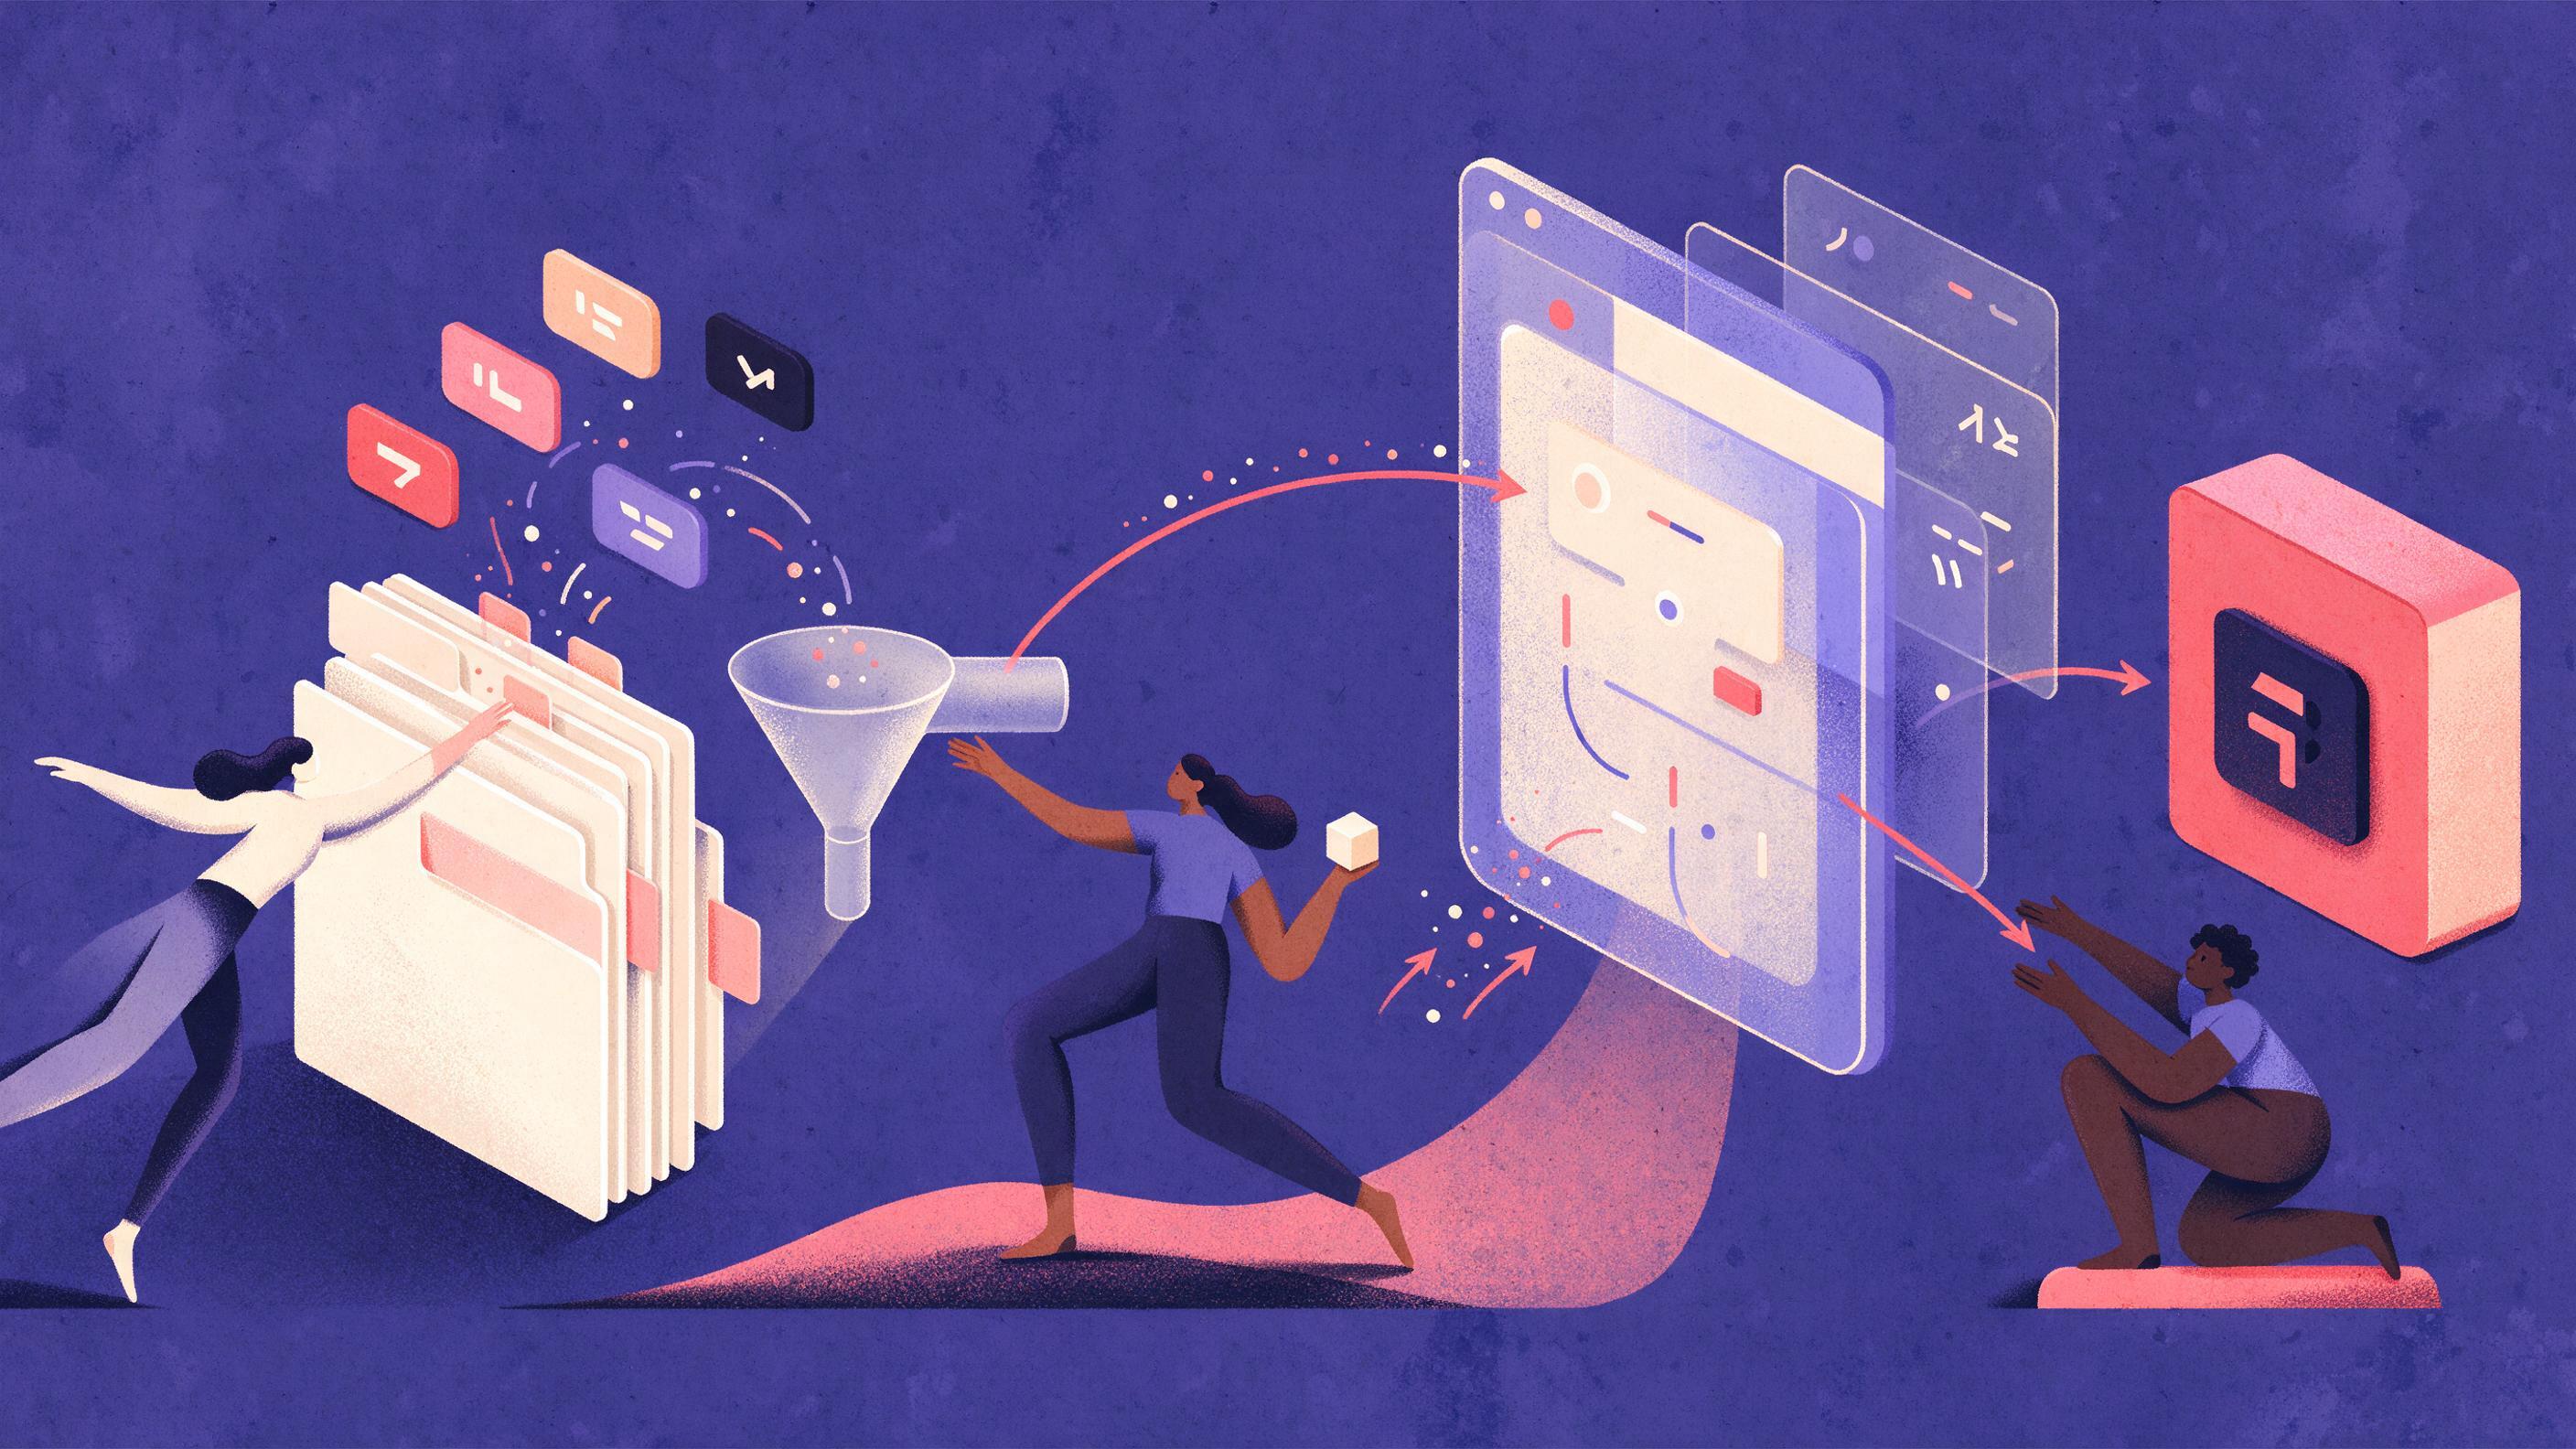
A split scene: on the left, a stack of log files with reason code tags (color-coded) being sampled into a funnel; on the right, a replay engine processing the sampled logs and feeding them into a candidate model box.
Key points

Key points

  1. 1A replay harness reads a stored decision log, reconstructs the inputs each decision saw, calls a candidate model, and records the new decision next to the original for comparison.
  2. 2Sampling by reason code, not by record count alone, is what stops a replay from silently skipping the decision paths you care most about.
  3. 3Cost per replay run is call count multiplied by the provider's published per-call price, and agentic or multi-pass configurations multiply input tokens several times over, reported as roughly 3.6x input replay in a published token cost study.
  4. 4When the log lacks a field the replay needs, the missingness is itself a finding: enrich from another system if you can, and fix the logging schema if you cannot.

What a replay actually is, and why it follows the schema

A decision log is a structured record of a choice: what was decided, on what evidence, under which policy or model version, and what happened as a result. A good log is deliberately compact and cites scoped evidence by reference rather than copying raw prompts or full customer records, which keeps review readable during an incident (decision log schema guide). That design choice has a direct consequence for replay: the log tells you what the model saw by reference, not by value.

A replay harness inverts that. It takes the reference, resolves it back into the exact input the model received, sends that input to a candidate model, and stores the candidate's output beside the original decision. In credit and AML settings the same idea appears under different names. Off-policy evaluation uses logged decisions to estimate how a candidate policy would have performed, and one published framework treats replay as a formal estimand with its own support assumptions rather than a free lunch (replay and launch readiness framework).

The key mental model: the log is the dataset, the harness is the query engine, and the candidate model is a pluggable function. Everything hard about replay lives in the gap between those three.

StageInputOutputWhere it breaks
SampleFull logStratified subsetRare reason codes get zero rows
ReconstructEvidence refsModel-ready input recordReferenced data has expired or changed
InvokeInput record + candidateCandidate decisionCost overrun, rate limits, nondeterminism
ScoreOriginal + candidateAgreement and drift metricsNo ground truth for what "correct" means
RecordEverything aboveReplay artifactNo version pin, so results can't be reproduced

Sampling by reason code, not by row count

The fastest way to build a misleading replay is to take a uniform random sample of the log. Uniform sampling preserves the frequency distribution of decisions, which sounds correct and is usually wrong. AML monitoring programs report false-positive rates that routinely exceed ninety percent, and one review cites up to 95% of alerts being false positives worldwide (Flagright, Adjapong, SSRN). A uniform sample of that log is dominated by the routine clear disposition, so a candidate model that is excellent on routine rows and terrible on the rare escalation will look excellent overall.

Sample by the field that encodes the decision path. In most logs that is a reason code, a policy verdict, or an action type, and the rule is simple: every distinct reason code gets a floor, and the rest of the budget is allocated proportionally to volume.

A worked example. Suppose the log holds 1,000,000 decisions across five reason codes, and the harness budget is 20,000 calls per run.

Reason codeLog rowsShareProportional allocationStratified floor of 2,000
Structuring threshold700,00070%14,00013,400
Velocity spike150,00015%3,0002,000
Cross-border layering100,00010%2,0002,000
Mule network match40,0004%8002,000
Manual referral10,0001%2002,000
Total1,000,000100%20,00021,400

The proportional column gives the rare mule and manual categories 1,000 rows between them, which is too few to trust any per-category agreement rate. The stratified column fails the budget by 1,400 calls, so you either raise the budget or lower the floor, and that decision belongs in writing before the run, not after you see which category moved.

Two refinements matter. First, stratify by the reason code the log actually stores, not the reason you wish it stored. If there is no explicit denial or escalation reason field, you cannot stratify on it, and you have found your first schema gap. Second, include a random "rest" stratum at a few percent so codes you did not anticipate still get some representation. Imbalanced sampling also distorts raw agreement rates, so report per-category agreement and volume-weighted agreement separately, the same way you would report per-class metrics rather than only an overall accuracy.

Reconstructing inputs the model actually saw

The reconstruction step is where a replay stops being a query and starts being engineering. Each log row should carry enough reference material to rebuild the input without guessing (decision log guide). Concretely, you need the feature snapshot, the point-in-time values of any derived fields, the policy or prompt version in force, and the model version that produced the original decision.

Point-in-time is the part teams underestimate. A customer's risk profile changes after the decision, so reading "current" customer attributes and calling them the decision-time input produces an input the original model never saw. That breaks the comparison in both directions: the candidate may look better because it gets fresher data, or worse because it gets a profile that no longer matches the reason code. The log should have captured the decision-time values, and if it did not, you must reconstruct them from an event store or history table.

Compare two candidate configurations with a decision rule rather than a feeling. Argue about outcomes, not scores. A candidate that shifts five percent of decisions from clear to hold is making a different business trade than one that shifts the same five percent from hold to clear, even if both show identical agreement with the original log.

Use the decision log's own reason codes as the yardstick for the original decision and for the candidate. Regulation B's Appendix C reason-code checklists are illustrative rather than exhaustive, and regulators have been explicit that a model's complexity is not a defense for vague reasons (CFPB circular commentary, Trussed appendix C guide). The practical reading for replay: if your candidate model cannot emit a reason code for each decision, you cannot compare it reason by reason, and you cannot produce a defensible adverse action notice from it.

Estimating cost per replay run

Cost per run is a multiplication, and the discipline is in getting both factors right.

Factor one: calls. Count model invocations, not log rows. One row can mean one call (a single classification), several calls (a retrieval plus a scoring plus a summary), or many calls (a multi-turn agent). A published token cost study of an evaluation workload measured a single structured pass at about $1.34 per cycle and a growing-context agentic configuration at about $4.64, attributing the gap to input replay, the agent re-reading its accumulated history at every step, measured at roughly 3.6x the input tokens (agent evaluation cost study). That multiplier is the single most important number for budgeting a replay: if your harness wraps the candidate in an agent loop, your call count per row is not one.

Factor two: price per call. Use the provider's published figures and state where you read them. The same study used $3.00 per million input tokens and $15.00 per million output tokens at list pricing, with cached input billed near 0.1x (agent evaluation cost study). Apply the price to your measured token counts, not to a guess.

A worked example, using those published rates:

  • 20,000 sampled rows, single call per row, 1,200 input tokens plus 150 output tokens per call.
  • Input: 24,000,000 tokens at $3.00 per million = $72.00.
  • Output: 3,000,000 tokens at $15.00 per million = $45.00.
  • Total: about $117.00 per replay run.
  • Same workload as a 4-turn agent at 3.6x input: about $259.20 in input cost plus output, roughly $304 per run.

Add a safety margin for retries, failures, and the inevitable second run after you fix a bug. Then multiply by the number of candidate models you actually intend to compare, because comparing three candidates costs three runs, and the comparison is the point.

Two cost decisions deserve a decision rule. If cached input is roughly a tenth of the base rate, enable caching and rerun the same sample rather than resampling each time, since cache hit rates fall when the sample changes between runs (agent evaluation cost study). And if the per-run cost exceeds what a single review cycle costs in investigator time, the replay has stopped being cheap evidence and become a project, which changes who owns the decision.

Handling missing fields without corrupting the result

Missing fields are the normal case, not the exception, and the replay is the instrument that finds them. Classify each gap before deciding what to do.

Gap typeExampleTreatment
Field never loggedNo decision-time customer profileCheck history or event store, else treat as unresolvable
Field logged but referenced data expiredEvidence link older than retentionReconstruct from an archive, else drop the stratum and report it
Field logged but semantically wrongReason code defaulted to a catch-allFix the taxonomy before replaying
Field exists but version unpinnedNo policy or model versionCannot attribute drift, so no replay
Derivable fieldAggregate not stored, components areRecompute deterministically and tag as derived

The rule: never impute a feature into a replay silently. Imputation is a model in its own right, and it makes your candidate's performance a function of your imputation choices. Enrichment from another system is acceptable if you record the source and timestamp, and if you can show the enriched value matches what the original decision could have seen.

Missingness is also evidence about the log itself. A decision log exists to let a teammate who was absent reconstruct the reason, authority, and result of an action from one record (decision log schema guide); fields the replay must have and the log does not contain are exactly the fields the schema is missing. Track them as a backlog, prioritized by how many replay rows they block. Ten missing fields that each block two percent of rows is a far smaller problem than one missing field that blocks the entire escalation stratum, and only the replay tells you which you have.

There is a stronger lesson in the published replay framework. Replay-only, off-policy-evaluation-only, guardrail-only, and holdout-only pipelines all selected the same policy but would each have recommended direct deployment, while the fuller framework changed the recommended action to online validation because propensities, bidder response, and interference were unresolved (replay and launch readiness framework). Replay is evidence about the log, not proof about production. Map your result to an action: launch, validate online, hold, or redesign.

Making the replay reproducible and auditable

A replay nobody can reproduce is a one-off estimate. Make the artifact self-describing: the sample definition and seed, the log snapshot ID, the evidence resolution versions, the candidate model and prompt version, token counts from the provider's usage object, and the scoring code version. Prompt and template versioning matters because behavior depends on the template and variables, not just the visible text, and versions must be immutable once referenced in logs (Braintrust prompt versioning guide). Immutability is what makes a historical replay defensible later.

Record the decision, not just the metrics. Architecture decision records capture context, the decision, and its consequences, and a decision log summarizing them keeps the reasoning findable (Microsoft engineering playbook). Your replay should produce one: we replayed sample S against candidate C, agreement was X per category, we treat missing field F as blocking, consequent action is online validation.

Determinism is the last piece. Nondeterministic candidate configurations make agreement numbers drift between runs, and majority voting over independent passes reduces but never removes that drift (a measured borderline flip rate of about 20% fell to about 10.4% at three votes) (agent evaluation cost study). If a result changed because you reran it, that is a finding about the candidate, and it should be in the artifact.

One practical option when the candidate is itself a model you host or call: route it through a single gateway so every call in the harness uses the same key, the same pricing in US dollars, and the same usage reporting. Quanta Inference puts text, image, video, audio and embedding models behind one OpenAI-compatible API, which simplifies the call-count and cost accounting the harness depends on.

FAQ

FAQ

What is the difference between a decision log and a trace for replay purposes?

A trace is built for latency, retries, spans, and model-call diagnostics, while a decision log records why the system was allowed to act and what was verified, including the policy verdict and reason codes (decision log schema guide). Replay needs the decision log, because it must reconstruct the business input and the policy context, not the request timing. Keep both and link them by stable ID.

How many decisions should I sample for a replay?

Enough that every reason code you care about clears a floor you are willing to trust, and then spend the remaining budget proportionally to volume. There is no universal number, because the right floor depends on how much per-category precision your decision requires. Build the allocation table before the run so the budget conversation happens once.

Can I replay decisions where the original reason code was wrong?

Not directly, because the reason code is often the thing you are comparing against. Fix the taxonomy first, or exclude those rows and report the exclusion rate, because a log with a catch-all default reason code is not a usable stratification key (Trussed appendix C guide).

Does replay tell me whether the candidate model is better?

It tells you how often and where the candidate disagrees with the logged decision, and which fields block a clean comparison. It does not settle causal questions like how customers or counterparties respond to the new decisions. Treat a favorable replay as grounds for online validation rather than direct launch (replay and launch readiness framework).

How do I estimate cost if my harness makes a variable number of model calls per row?

Measure tokens per row on a small pilot using the provider's usage object, then multiply by the real sample size and the published per-token price. Agentic configurations replay history at every step, so budget for a multiple of the single-pass input rather than the single-pass figure (agent evaluation cost study).

Sources

Sources

  1. AI Agent Decision Logs: Record Evidence Without Storing ...
  2. Decision Support for Marketplace Policies under ...
  3. Understanding False Positives in Transaction Monitoring - Flagright
  4. AI-Driven Transaction Monitoring Systems (AI-TMS): Reducing False ...
  5. on Machine Learning Model Adverse Action Notices
  6. Specific Adverse Action Reasons for AI Lending Models
  7. Agent Token Cost Study: Compiled vs Sequential
  8. What is prompt versioning? Best practices for iteration without ...
  9. Design Decision Log - Engineering Fundamentals Playbook
About the author

About the author

Antonio Evans
Antonio Evans

Antonio Evans is the founder of Quanta Intelligence and a fractional CTO who builds HIPAA-ready AI systems for health and life-science companies. Before that he was technical co-founder of FriendsEAT for twenty years, CEO of Socialdraft, and a data engineer at IBM. Antonio lives with his dog Santino in Lisbon, Portugal.

All articles


