Business

How to Write an AI Use Policy That Staff Will Actually Follow

Antonio Evans10 min read

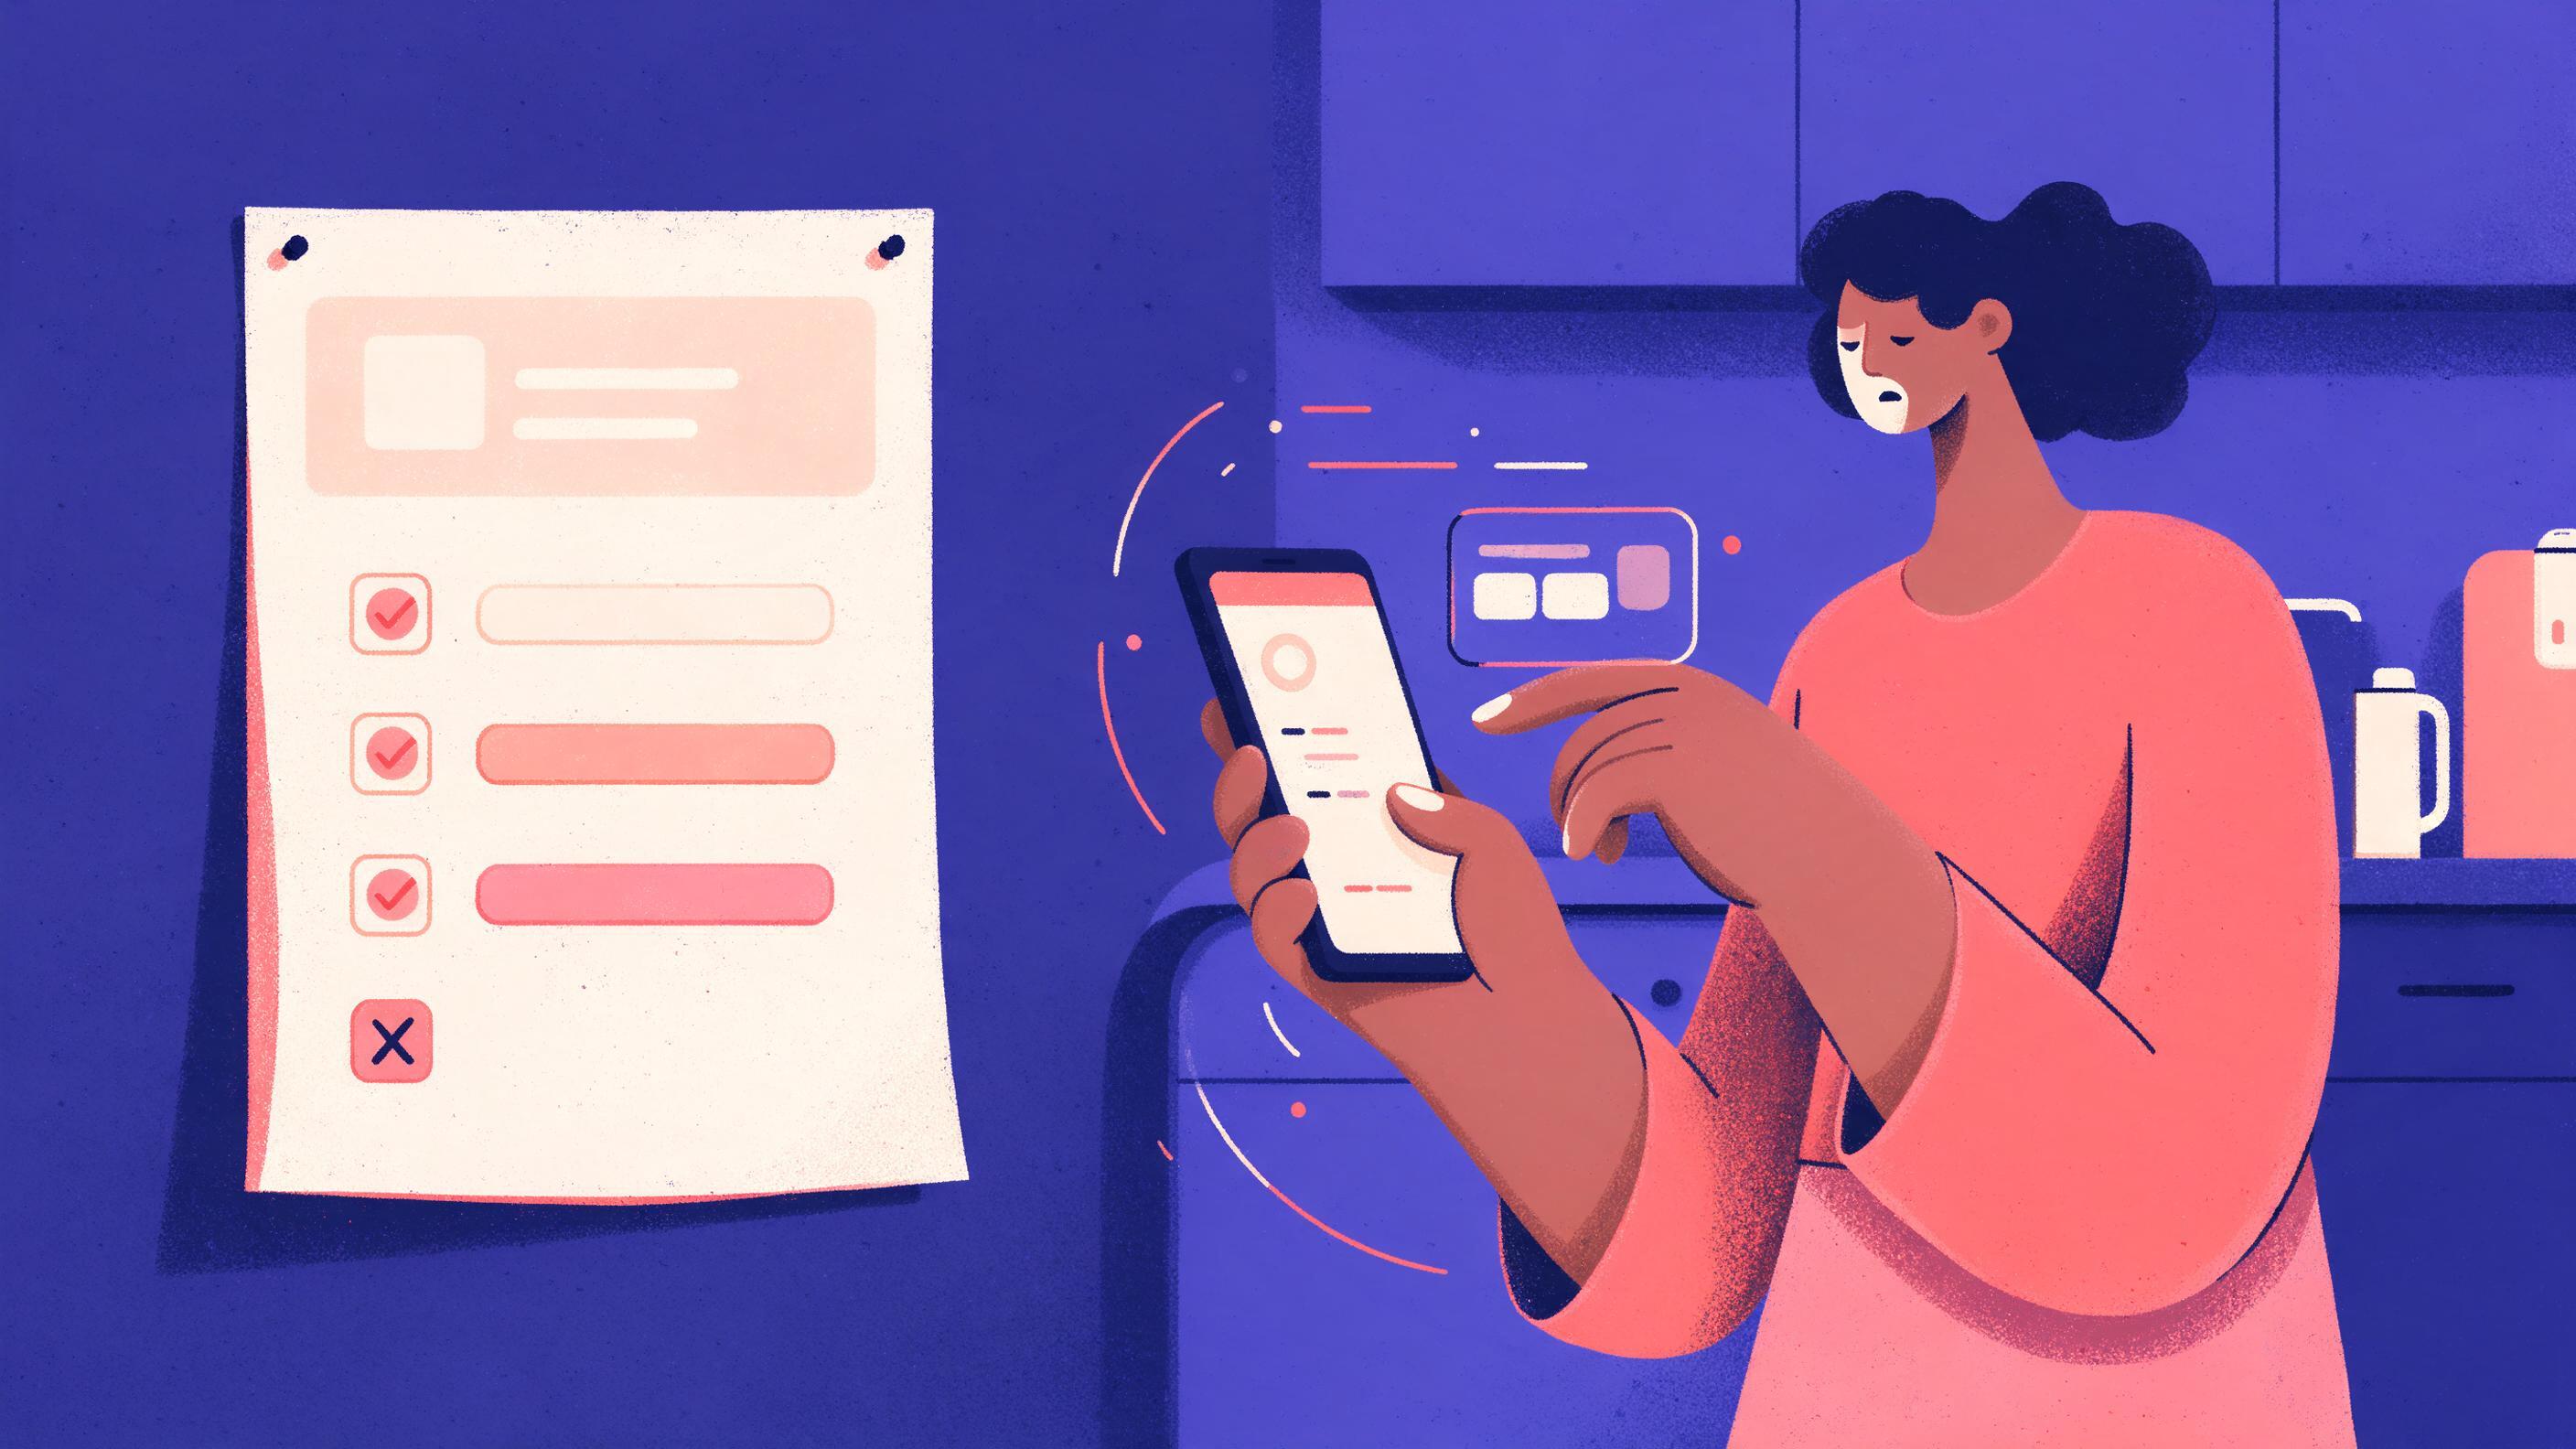
A single sheet of paper pinned to a breakroom wall, headed APPROVED TOOLS with three checkboxes and one red X, beside a printed prompt box where a hand holds a phone and hesitates before typing a customer email.
Key points

Key points

  1. 1A one-page policy with four parts (approved tools and owners, an exception path with a decision deadline, five hard examples of what not to paste, and a quarterly review) replaces the checklist you ran once.
  2. 2Approval should map to the tool and the data class together, because enterprise tiers of major tools differ from consumer accounts on training and retention.
  3. 3Five concrete examples beat any general instruction, because sensitive content is a large and growing share of what employees actually paste into AI tools.
  4. 4The first month is a feedback loop, not an enforcement campaign: publish where staff look, test on three real workflows, and fix ambiguity before you escalate.

Why the checklist becomes a policy

A one-off AI use checklist answers "are we okay right now?" A policy answers "what do we do next Monday when someone wants a tool we have not seen?" Those are different artifacts. The Future of Privacy Forum's internal policy checklist pushes organizations toward the second: a standing process for revision, with owners and review built in, rather than a single audit the FPF checklist.

The reason to make this shift is behavioral, not legal. Most AI incidents are not sabotage. They are employees trying to finish work faster with the tools they already have. Harvard's information security guidance frames the problem the same way: staff will use the version of a service they can reach, including personal and consumer accounts, unless a better approved path exists Harvard's generative AI best practices.

The approval-by-default principle

Here is the decision rule the article builds on, and it is the one most first drafts get wrong:

Approve the tool and the data class together, name one owner for each approval, and give every unapproved request a two-step path with a deadline.

Three consequences follow. Approval is cheap to grant when the tool is an enterprise tier with no-training defaults and a data processing agreement, so you should grant it broadly for low-risk content OpenAI's enterprise privacy commitments. Approval is expensive when the tool is a consumer account with defaults that enable training, so the policy spends its strictness there. And an unapproved request should never sit in a queue for weeks, because a stalled request turns into a personal account.

Part one: the approved-tool list

Keep this section to one screen. Each row has four fields: tool name, the content classes it may hold, the owner, and the last review date. The owner is a person, not a committee, and the review date is what triggers the quarterly cycle later.

A practical way to set the content classes is to borrow your existing data classification rather than invent an AI one. A policy that says no restricted or confidential data in any generative AI system is short, testable and maps directly to the labels staff already see on documents ICOM's acceptable use policy. If you have no classification, use three tiers: public, internal, and restricted, and define each in one sentence. Organizations that have drafted these policies repeatedly note that data classification is the foundation, because without it every exception request becomes a debate a template breakdown of key provisions.

Two rules keep this list honest. First, include embedded AI features, not just chatbots: the assistant in your collaboration suite, the coding assistant, the meeting transcriber, browser extensions, and any agent connected to internal systems are all in scope, because the risk tracks the tool's access to data more than its product label Zscaler's AI acceptable use guidance. Second, write down what "approved" means for each entry. For an enterprise workspace, the useful facts are that the provider does not train on business data by default, that the customer owns inputs and outputs, and that a data processing addendum exists OpenAI's enterprise privacy page.

Worked example: one line from the list

Suppose a marketing team asks for a chat tool. The owner is the head of marketing operations. The approved content class is public and internal marketing copy only. The conditions are: company workspace accounts only, no client names or unreleased campaign figures, and personal accounts prohibited for work. The row reads:

FieldValue
ToolCompany workspace chat assistant
May holdPublic and internal marketing content
May not holdClient data, unreleased financials, contracts, source code
OwnerMarketing operations lead
ReviewQuarterly, next date on the calendar

That single row replaces a paragraph of prose and is what an employee will actually read under deadline pressure.

Part two: the two-step approval path

Everything not on the list needs a route. A route with two steps and a clock.

Step one is submission. The requester fills a short form with four fields: the use case in two sentences, the tool and whether it is a company workspace or a personal account, the content classes involved, and the business reason. Four fields, not a questionnaire. You can run this in a shared form and a ticket queue.

Step two is a decision within a stated number of business days. Ten business days is workable for most organizations because it allows a security review of vendor terms, retention, and subprocessors without giving the requester time to give up and use a personal account instead. The decision is one of three: approved as described, approved with conditions, or declined with a named alternative that is already on the list.

Learn from published checklists before you draft the form. A useful employer checklist starts with a survey of where AI is already used, because employees may be using more of it than leadership realizes, including meeting assistants, writing tools and features embedded in software the company already licenses the ten-question employer checklist. That inventory belongs in the policy's first quarter, and the answers should populate the approved list rather than a separate spreadsheet.

The clock is the load-bearing part. Security and legal reviewers need a packet that answers the questions that actually change outcomes. The practical ones are: what retention period applies, whether a data processing addendum is available, which subprocessors are involved, and whether the provider trains on your inputs. Those questions exist because the "we never train on your data" sentence is costless to write and meaningless without scope, named subprocessors and a retention number in days the 12 questions that test a no-training claim.

Triage rule for the reviewer

Do not review every request the same way. Sort by consequence:

Request shapeLikely riskDecision target
Public content, writing help, brainstormingLowApprove in under two days
Internal content, no personal or client dataLow to mediumApprove with conditions in under five days
Client data, personal data, contracts, source codeHighFull review plus legal or privacy sign-off, ten business days
Any consumer account for restricted contentHighestDecline, offer the approved equivalent

The first row exists so that the easy requests clear fast. If your queue is full of brainstorming requests waiting ten days, the policy will quietly lose credibility, and staff will route around it.

Part three: five examples of what not to paste

This is the section that does the most work, and it should be written as examples, not categories. Vague instructions fail because employees cannot map "confidential" onto the document in front of them at 9 p.m. The data flowing into AI tools is not marginal: roughly two in five AI interactions involve sensitive data, counting prompt text, copy and paste actions and file uploads, and staff input sensitive data into AI tools about once every three days on average Cyberhaven's AI adoption and risk findings. The same research finds that a substantial share of usage runs through personal rather than corporate accounts, which is exactly what a bypassable policy produces Cyberhaven on personal account usage.

The five examples below are drawn from published policy guidance and should be adapted to your business, not copied verbatim.

  1. Customer and client personal data. Names plus account numbers, addresses plus dates of birth, and anything that becomes identifiable when combined. Harvard's guidance is direct: remove unnecessary personal, confidential, proprietary or identifying information before sharing content with an AI system Harvard's data protection practices.

  2. Financial and payroll records. Salary bands tied to named employees, bank details, invoices with pricing terms, and unreleased financial results. This is a common paste because people use chat tools to reformat spreadsheets.

  3. Source code and technical assets. Proprietary code pasted into a debug session is the canonical example of well-intentioned exposure, and it is why code deserves its own line even if your approved coding assistant is separate from your approved chat tool Read AI on real leakage incidents.

  4. Contracts and third-party confidential material. Anything under a confidentiality agreement with a client, supplier or partner. Pasted contract text can create a disclosure obligation to a third party, not just an internal security problem Norton Rose Fulbright on confidentiality of inputs.

  5. Credentials and system secrets. Passwords, API keys, connection strings, and internal hostnames. Staff paste these more often than expected when troubleshooting, and no legitimate use case requires it.

Add a sixth line to the section that most drafts miss: meeting recordings and transcripts. If your organization allows AI meeting assistants, say whether participants must be told, because recording and consent rules vary by jurisdiction and by policy Harvard's guidance on meeting tools.

A note on shortcuts that do not work

Opting out of training is not the same as zero retention, and zero retention does not mean zero access. Providers retain content for a period for abuse monitoring and safety review, and some review paths are not optional an operational breakdown of opt-out limits. Under standard consumer terms, input content may be used to maintain and improve the service, and users must opt out formally; enterprise tiers differ, and API content is treated differently again ISACA on security controls for employee ChatGPT use. A policy that treats those tiers as equivalent will be wrong in one direction or the other.

Vendor claims need the same scrutiny. Many vendors now offer enterprise terms under which business data is not used for training by default, but that is a statement about model training, not about storage or human review OpenAI's enterprise privacy commitments. One privacy analysis of training opt-outs lays out the account-type differences plainly, including default retention periods that persist even when training is disabled the training opt-out walkthrough. Write the policy so it does not depend on a marketing sentence.

If you want a scrubbing control rather than a rule, the mechanics are simple: replace identifiers with placeholders before the request leaves your systems, and keep the mapping on your side. The model still answers the question; the sensitive value never travels.

scrubbed, mapping = scrub(user_text)   # "My SSN is [SSN_1]"
response = client.chat.completions.create(
    messages=[{"role": "user", "content": scrubbed}]
)
final = restore(response, mapping)

That pattern is worth a paragraph in the policy's appendix, because it gives engineers a compliant path instead of a prohibition.

Part four: the quarterly review

A policy with no review date is a document that slowly becomes wrong. New tools appear, vendors change terms, and features get switched on inside products you already bought; a vendor can change which data feeds model development when it updates its terms, which is why reviews cannot be skipped GitHub's FAQ on Copilot data use.

Set the cycle on a calendar, not in a habit. Each quarter, the policy owner does five things and records the answers in a short log:

  • Re-check each approved tool's training, retention and subprocessor terms, and update the last-review date in the table.
  • Close out the exception log: which requests came in, how long decisions took, and which were declined. If the same request arrives three times, it should become a policy line, not a repeated decision.
  • Re-read the five examples against the last quarter's near misses and swap in anything staff actually pasted.
  • Test the policy on one real workflow end to end, and time how long approval takes.
  • Publish a one-paragraph change note where staff already look.

Quarterly is not a universal law. Annual review repeats are common in published acceptable-use policies, and they work when the tool list is short and stable ICOM's review requirement. Quarterly is the right cadence while the tool list is still growing and staff are still experimenting, because most of the policy's content changes in the first few cycles.

Publishing, testing, and the first month

Where you publish matters more than how the document looks. Put the one-pager at the top of the wiki page people already open for IT questions, in the onboarding checklist, and in the tool launcher itself. If it only lives in a policy library, it will be read by auditors and nobody else.

Then test it on three real workflows, not hypotheticals. Pick the three tasks where AI use is heaviest (drafting client communication, summarizing internal documents, writing or reviewing code, for example) and walk each one through the policy as if you were the employee. Ask three questions: could I find the rule in under a minute, would I know which list entry applies, and if my tool is missing, would I actually submit the request or just use a personal account? Friction found in that test is cheaper to fix than friction found after an incident.

The first month should be framed as a feedback loop. Announce that the policy is version one, that the exception form is open, and that unclear rules will be rewritten. Then watch the exception queue as your main evidence: it tells you which tools to approve next, and it shows which sentences staff found ambiguous. Resist the urge to lead with enforcement. A policy that pushes usage into personal accounts has failed on its own terms, and the measured share of personal-account usage describes exactly that outcome Cyberhaven on personal account usage.

What "working" looks like after a quarter

You are not looking for zero requests. You are looking for three signals: most usage happens inside approved tools, exception decisions arrive inside the stated deadline, and the number of new requests falls because the list covers the common cases. Those three are measurable from the exception log alone, with no monitoring tool required.

For teams building internal tools on top of models, the policy should also name how new applications get approved, because an internal app that calls a model is a use case like any other. A gateway that puts several models behind one key, with usage billed in US dollars and OpenAI-compatible calls, makes that approval simpler to describe and easier to log; Quanta Inference is one option built for that shape. Where the harder problem is turning the policy into finished, reviewable work across a line of business, a short discovery call is a reasonable way to map the workflows before you write them into the policy.

FAQ

FAQ

How long should the policy be?

One page for the rules, with an appendix that holds the tool table and the exception form. If a rule needs more than three sentences, it probably belongs in a procedure rather than the policy, and the procedure can be linked.

What if leadership wants a stricter policy than the risk justifies?

Strictness that pushes work into personal accounts defeats itself. Measure the exception queue and personal-account usage before tightening rules, and adjust based on what staff actually do rather than what a template says.

Do we need the same rules for internal tools we build?

Yes, but the approval looks different. An internal application is a use case with an owner and a data class, so it enters through the exception path and gets re-reviewed on the same quarterly cycle as purchased tools.

How do we handle a vendor that changes its terms mid quarter?

Treat it as a trigger, not a scheduled item. Re-check the affected tool's terms when the change notification arrives, update the row, and decide whether the content class stays the same.

Who should own the policy?

One named person with the authority to approve tools and the time to run the cycle, supported by security, privacy and legal reviewers who respond inside the decision deadline. Committees own nothing, so name a person.

Sources

Sources

  1. FPF Releases Generative AI Internal Policy Checklist To Guide ...
  2. Best Practices: Using Generative AI - Harvard Information Security
  3. Enterprise privacy at OpenAI
  4. Generative AI (GEN-AI) Acceptable Use
  5. AI Acceptable Use Policy: Template + Key Provisions
  6. AI Acceptable Use Policy for Employees: What to Include
  7. AI Workplace Policy Checklist: 10 Questions for Employers
  8. No Training on Your Data Is Free to Say - 12 Questions That Test It
  9. Sensitive Enterprise Data Is Flowing Into AI Tools at Scale - Cyberhaven
  10. Everyone is using ChatGPT: What does my organization need to ...
  11. The AI Training Data Opt-Out Lie: Why Your Prompts Are Being Used ...
  12. Using Security Controls to Mitigate Privacy Risk When Employees Use ...
  13. GPT-5 Training Data Opt-Out: How to Exclude Your Content from AI ...
  14. FAQ: Privacy Statement update on Copilot data use for model training ...
About the author

About the author

Antonio Evans
Antonio Evans

Antonio Evans is the founder of Quanta Intelligence and a fractional CTO who builds HIPAA-ready AI systems for health and life-science companies. Before that he was technical co-founder of FriendsEAT for twenty years, CEO of Socialdraft, and a data engineer at IBM. Antonio lives with his dog Santino in Lisbon, Portugal.

All articles