Development

Idempotent Writes for AI Agents: Catching a Retried Tool Call

Antonio Evans7 min read

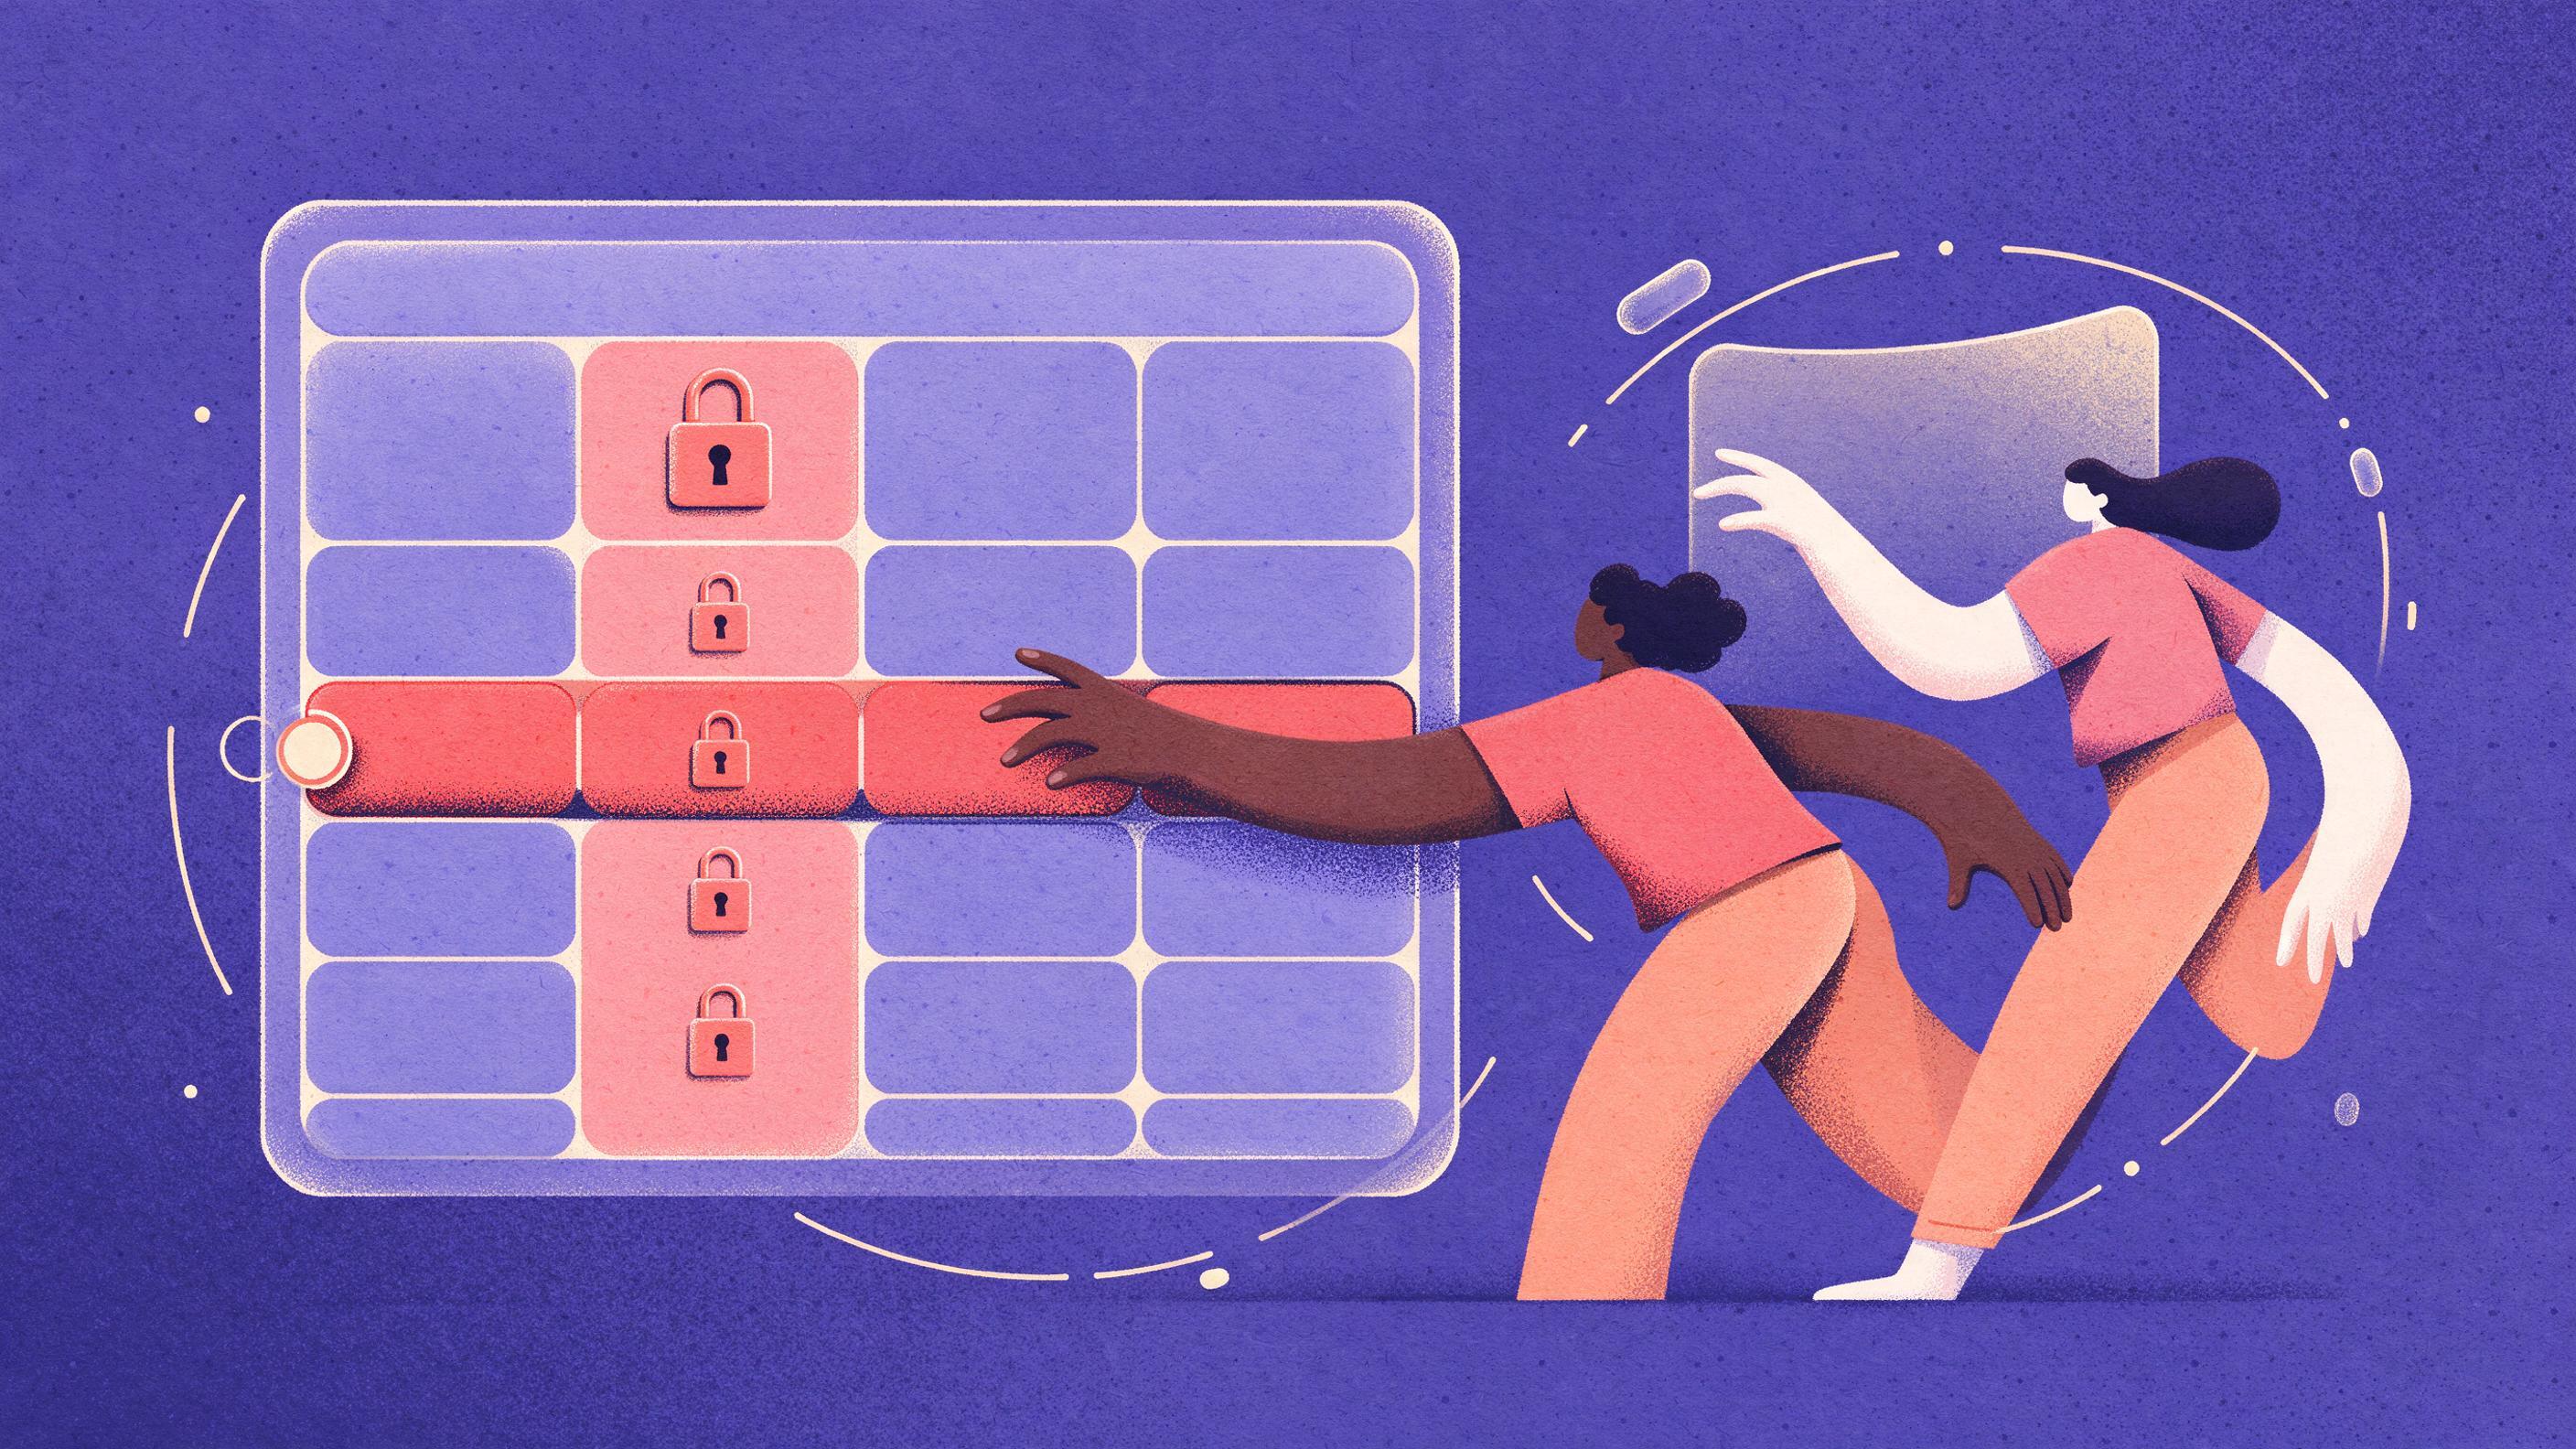
A cutaway view of a database table, with one row highlighted and a small padlock on a column labeled request_key.
Key points

Key points

  1. 1An agent retry after a timeout can execute a payment tool twice because the model only knows it did not see a result, not whether the side effect happened.
  2. 2A stable request key generated before the first attempt, from the tool name, canonical arguments and a caller-supplied request ID, lets the server recognize the retry.
  3. 3Storing the key in a UNIQUE column on the same table the tool writes, inside one transaction, makes the database the arbiter of "first time or replay."
  4. 4Replay handling is its own code path: on a duplicate key the handler returns the stored result instead of running the side effect again.

Why an agent retry duplicates a payment

Every agent framework worth using retries tool calls on transient failure, and that is the right default: dropping a request silently is worse than repeating it. The trouble is where the retry lives. The model sees a timeout, reasons "I did not get a result, so I should try again," and calls the tool a second time. Nothing in that loop knows whether the first call already charged the card or wrote the row in this analysis of agentic tool calling.

The failure window is narrow and easy to picture. The tool commits order 123, then the response is lost on the way back, then the agent retries and the tool commits order 124. The same pattern produces duplicate support tickets from one complaint, double refunds, and stock deducted twice from one order in the same write-up. Prompt engineering does not fix it: an instruction like "only call the payment tool once" cannot help, because the agent genuinely does not know the first call succeeded as described here.

HTTP semantics make this concrete. GET is naturally idempotent, PUT is intended to be, and POST means "create something new," so calling it twice legitimately creates two resources. The server sees no difference between a client retry, a double click and a duplicate request per this idempotency guide. Retries are also not only user-driven: SDKs, reverse proxies, service meshes and SDK backoff all resend requests on their own as listed here.

The decision rule that follows: any tool call with an external side effect (money moves, a row is created, a message is sent) must be idempotent at the tool boundary, because you cannot make the agent layer reliably "call once." Retries are the recovery path you want to keep. The job is to make replaying them harmless.


Designing the request key

The key must be generated once per intended operation, before the first attempt, and reused on every retry. There are two common shapes.

The first is a UUID created by the agent runtime and persisted in the step record. If the agent crashes and resumes, it reads the same key from durable state rather than minting a new one. A workflow-run identifier combined with a step identifier, such as {workflowRunId}:{stepId}, is deterministic: the same key is regenerated on resume according to this practitioner guide.

The second is a hash of the tool name plus the canonical arguments plus a caller-supplied request ID. This is the right choice when the caller (a human, an upstream service, another agent) already has a request identifier, or when you want identical intent expressed twice to collapse onto one key.

Key designGood forFailure mode to avoid
UUID per step, stored in the step recordLong-running agents, crash and resumeRegenerating a new UUID on retry
Hash of tool name plus canonical arguments plus request IDCaller-supplied request IDs, deterministic replayNon-canonical JSON (key order, whitespace, number formats)
Workflow run ID plus step IDDeterministic keys that survive restartsReusing a step ID for a genuinely new operation

Canonicalization is the part teams get wrong. A hash over raw JSON breaks the moment the agent reorders object keys or formats a float differently, because the hash changes and the retry looks like a new request. Serialize arguments with sorted keys and fixed number formatting before hashing, and store the canonical form if you want to debug later.

Whatever the shape, the key needs three properties. It is stable across attempts. It is unique across intents. It is available to the server on every attempt, typically as a header such as Idempotency-Key or a field in the tool payload per this guide. Keys should persist long enough to cover realistic retry windows, commonly between 24 hours and 7 days, and no longer per the same guide.

Storing the key next to the row

The safest place for the key is the same database as the side effect. A separate deduplication store introduces a second system that can disagree with the first; a column on the table the tool writes cannot.

The schema change is small:

ALTER TABLE payments
  ADD COLUMN idempotency_key TEXT,
  ADD COLUMN request_fingerprint TEXT,
  ADD COLUMN result_body JSONB;

CREATE UNIQUE INDEX payments_idempotency_key_idx
  ON payments (idempotency_key);

The handler wraps the whole operation in one transaction. Insert the key and the payment row together, and let the unique index reject the second attempt.

BEGIN;

INSERT INTO payments (idempotency_key, request_fingerprint, amount, currency, status)
VALUES ($1, $2, $3, $4, 'succeeded')
ON CONFLICT (idempotency_key) DO NOTHING
RETURNING id, created_at;

COMMIT;

Two details matter here. First, ON CONFLICT DO NOTHING returns zero rows when the key already exists, which is exactly the signal that this is a replay. Second, request_fingerprint stores a hash of the canonical arguments; if the same key arrives with different arguments, the handler should reject the request with an error rather than return the stored result per this guide.

Transactions give you the atomicity you need. A transaction is a unit of work that either completes entirely or does not run at all as explained here. The payment row and the idempotency key commit together, so there is no window where the row exists without the key or the key exists without the row.

The concurrent duplicate case

Two attempts can arrive at the same instant, for example the agent retries before the first request finishes, or a proxy retries alongside the original. A naive check-then-insert is the classic race: both requests read "key not present," both proceed, one insert fails or both succeed depending on timing. The unique index prevents both from committing, but one of them gets an error rather than a clean replay.

There are two workable answers. The first is to let the second transaction block on the unique index until the first commits, then return the stored result on conflict. This works with INSERT ... ON CONFLICT on PostgreSQL because the conflicting insert waits for the in-flight transaction to finish before deciding whether to skip. The second is to take an explicit lock on a separate deduplication row before doing any work, so the second request waits for the first and then reads the cached response as described here.

Both rely on the same assumption: the database is the arbiter and the application does not try to outthink it. That assumption breaks in one place, and it is worth knowing where.

Connection poolers change what a session sees. In transaction pooling mode, PgBouncer assigns a server connection for the duration of one transaction and returns it to the pool afterwards, and session-based features such as SET, LISTEN, session-level advisory locks and prepared statements do not survive across transactions per the PgBouncer feature map. If your tool relies on a session-level advisory lock to serialize duplicates, transaction pooling will quietly break it. Use a row lock or the unique index instead, which are scoped to the transaction and safe under any pooling mode. Transaction pooling is the recommended mode for most apps precisely because clients rarely run consecutive transactions without idle time between them per this Heroku guidance.

Handling the replay path

The replay path is a real code path, not an edge case, so it deserves the same testing and the same care as the first call. The handler should follow one deterministic order:

  1. Parse the key from the request. Reject immediately if it is missing or malformed.
  2. Compute the canonical fingerprint of the arguments.
  3. Run the transaction: insert the key, side effect and result together.
  4. If the insert returns a row, return a fresh success response with the new row's identifiers.
  5. If the insert returns nothing, select the stored row by key, compare fingerprints, and return the stored result body.
  6. If the key exists with a different fingerprint, return a conflict error.

The result body matters as much as the row. A retried payment call should return the same transaction identifier, status code and response shape as the original, not a fresh identifier for a fresh (nonexistent) charge. Caching the status code and response body alongside the key is the standard approach per this guide.

One decision to make explicitly: what happens if the first attempt is still in flight? Returning "I don't know yet" is better than executing again. Either block on the row until it resolves, or return a 409 with a retry hint so the agent backs off. Silently running the side effect a second time is the only genuinely wrong answer.

Testing the replay

Testing the happy path proves nothing about idempotency. What you need is a test that calls the tool twice with the same key and asserts one row, plus a test that fires two concurrent attempts and asserts the same.

def test_retry_does_not_charge_twice(client, agent_step):
    key = agent_step.idempotency_key
    args = {"amount_cents": 4200, "currency": "USD", "card_token": "tok_visa"}

    first = client.post("/tools/charge", json=args, headers={"Idempotency-Key": key})
    second = client.post("/tools/charge", json=args, headers={"Idempotency-Key": key})

    assert first.status_code == 200 and second.status_code == 200
    assert first.json()["payment_id"] == second.json()["payment_id"]
    assert count_payments(agent_step.workflow_run_id) == 1

The concurrency test is the one that catches the race you will otherwise ship:

def test_concurrent_duplicate_key_charges_once(db, client, agent_step):
    key = agent_step.idempotency_key
    args = {"amount_cents": 100, "currency": "USD"}

    with ThreadPoolExecutor(max_workers=2) as pool:
        futures = [
            pool.submit(client.post, "/tools/charge", json=args,
                        headers={"Idempotency-Key": key})
            for _ in range(2)
        ]
    results = [f.result() for f in futures]

    assert {r.json()["payment_id"] for r in results if r.ok} == set()
    assert db.scalar("SELECT count(*) FROM payments WHERE idempotency_key = %s", (key,)) == 1

Add two more cases: a different fingerprint under the same key must return a conflict, and a new key with identical arguments must produce a second (legitimate) charge. Together these four tests cover the behaviors that matter.

Operating it

Keep an eye on the replay path once it is in production. Log every request as first, replayed or conflict, and alert on the conflict rate: a spike usually means keys are being regenerated on retry, which is the original bug in a new costume.

Auditing the table is easier if you store the fingerprint and the original response alongside the key, which is what makes a replay return the same body. Retention is a judgment call: keys need to outlast the longest retry window you permit, but keeping them forever grows the table and the index. Rows with no activity for a week are usually safe to prune once the workflow is closed.

If your tool calls run across many services, put the key at the agent runtime layer so it never has to be reconstructed downstream. The tool interface should accept the key and pass it through to any external API that supports one as argued here. That way there is exactly one source of truth for "this is the same operation."

FAQ

FAQ

What is the difference between a request ID and an idempotency key?

A request ID identifies one HTTP request, so a retry gets a new one. An idempotency key identifies the intended operation, so every retry of the same intent carries the same key. You can derive the idempotency key from a stable request ID, but you cannot use a per-attempt request ID as the key.

Should the key be generated by the agent or by the server?

The caller generates it, whether that caller is the agent runtime, an upstream service or a human user. The caller is the only party that knows two attempts are for the same intent per this guide. The server's job is to enforce the key and store the result, not to invent one.

What happens if the same key arrives with different arguments?

Treat it as an error. Store a fingerprint of the canonical arguments with the key and compare on every request; a mismatch means something upstream has reused a key for a different operation, and returning the stored result would silently give the caller the wrong answer per this guide.

How long should keys be kept?

Long enough to cover your retry window, which in most systems is between 24 hours and 7 days, and no longer per this guide. Keys that outlive every possible retry are dead weight in the index; keys that expire too soon let a late retry charge twice.

Does a unique index alone make the tool safe?

No. The index stops the second write, but without replay handling the retried call fails with a database error instead of returning the original result, and the agent may retry again with backoff. You need the index plus stored results plus a handler that reads them on conflict.

When you are building the surrounding agent and want the model layer, the tool layer and the storage layer to agree on the same contracts, Quanta is the place to describe what you need and have a specialist build it with you.

Sources

Sources

  1. The Idempotency Problem in Agentic Tool Calling
  2. Implementing Idempotency Keys in REST APIs
  3. Designing Idempotency Keys: How Payment APIs Prevent ...
  4. What write skew looks like
  5. PgBouncer features
  6. PgBouncer Configuration and Best Practices - Heroku Dev Center
About the author

About the author

Antonio Evans
Antonio Evans

Antonio Evans is the founder of Quanta Intelligence and a fractional CTO who builds HIPAA-ready AI systems for health and life-science companies. Before that he was technical co-founder of FriendsEAT for twenty years, CEO of Socialdraft, and a data engineer at IBM. Antonio lives with his dog Santino in Lisbon, Portugal.

All articles