Development

Linking a Prompt Version to Every Model Call

Antonio Evans8 min read

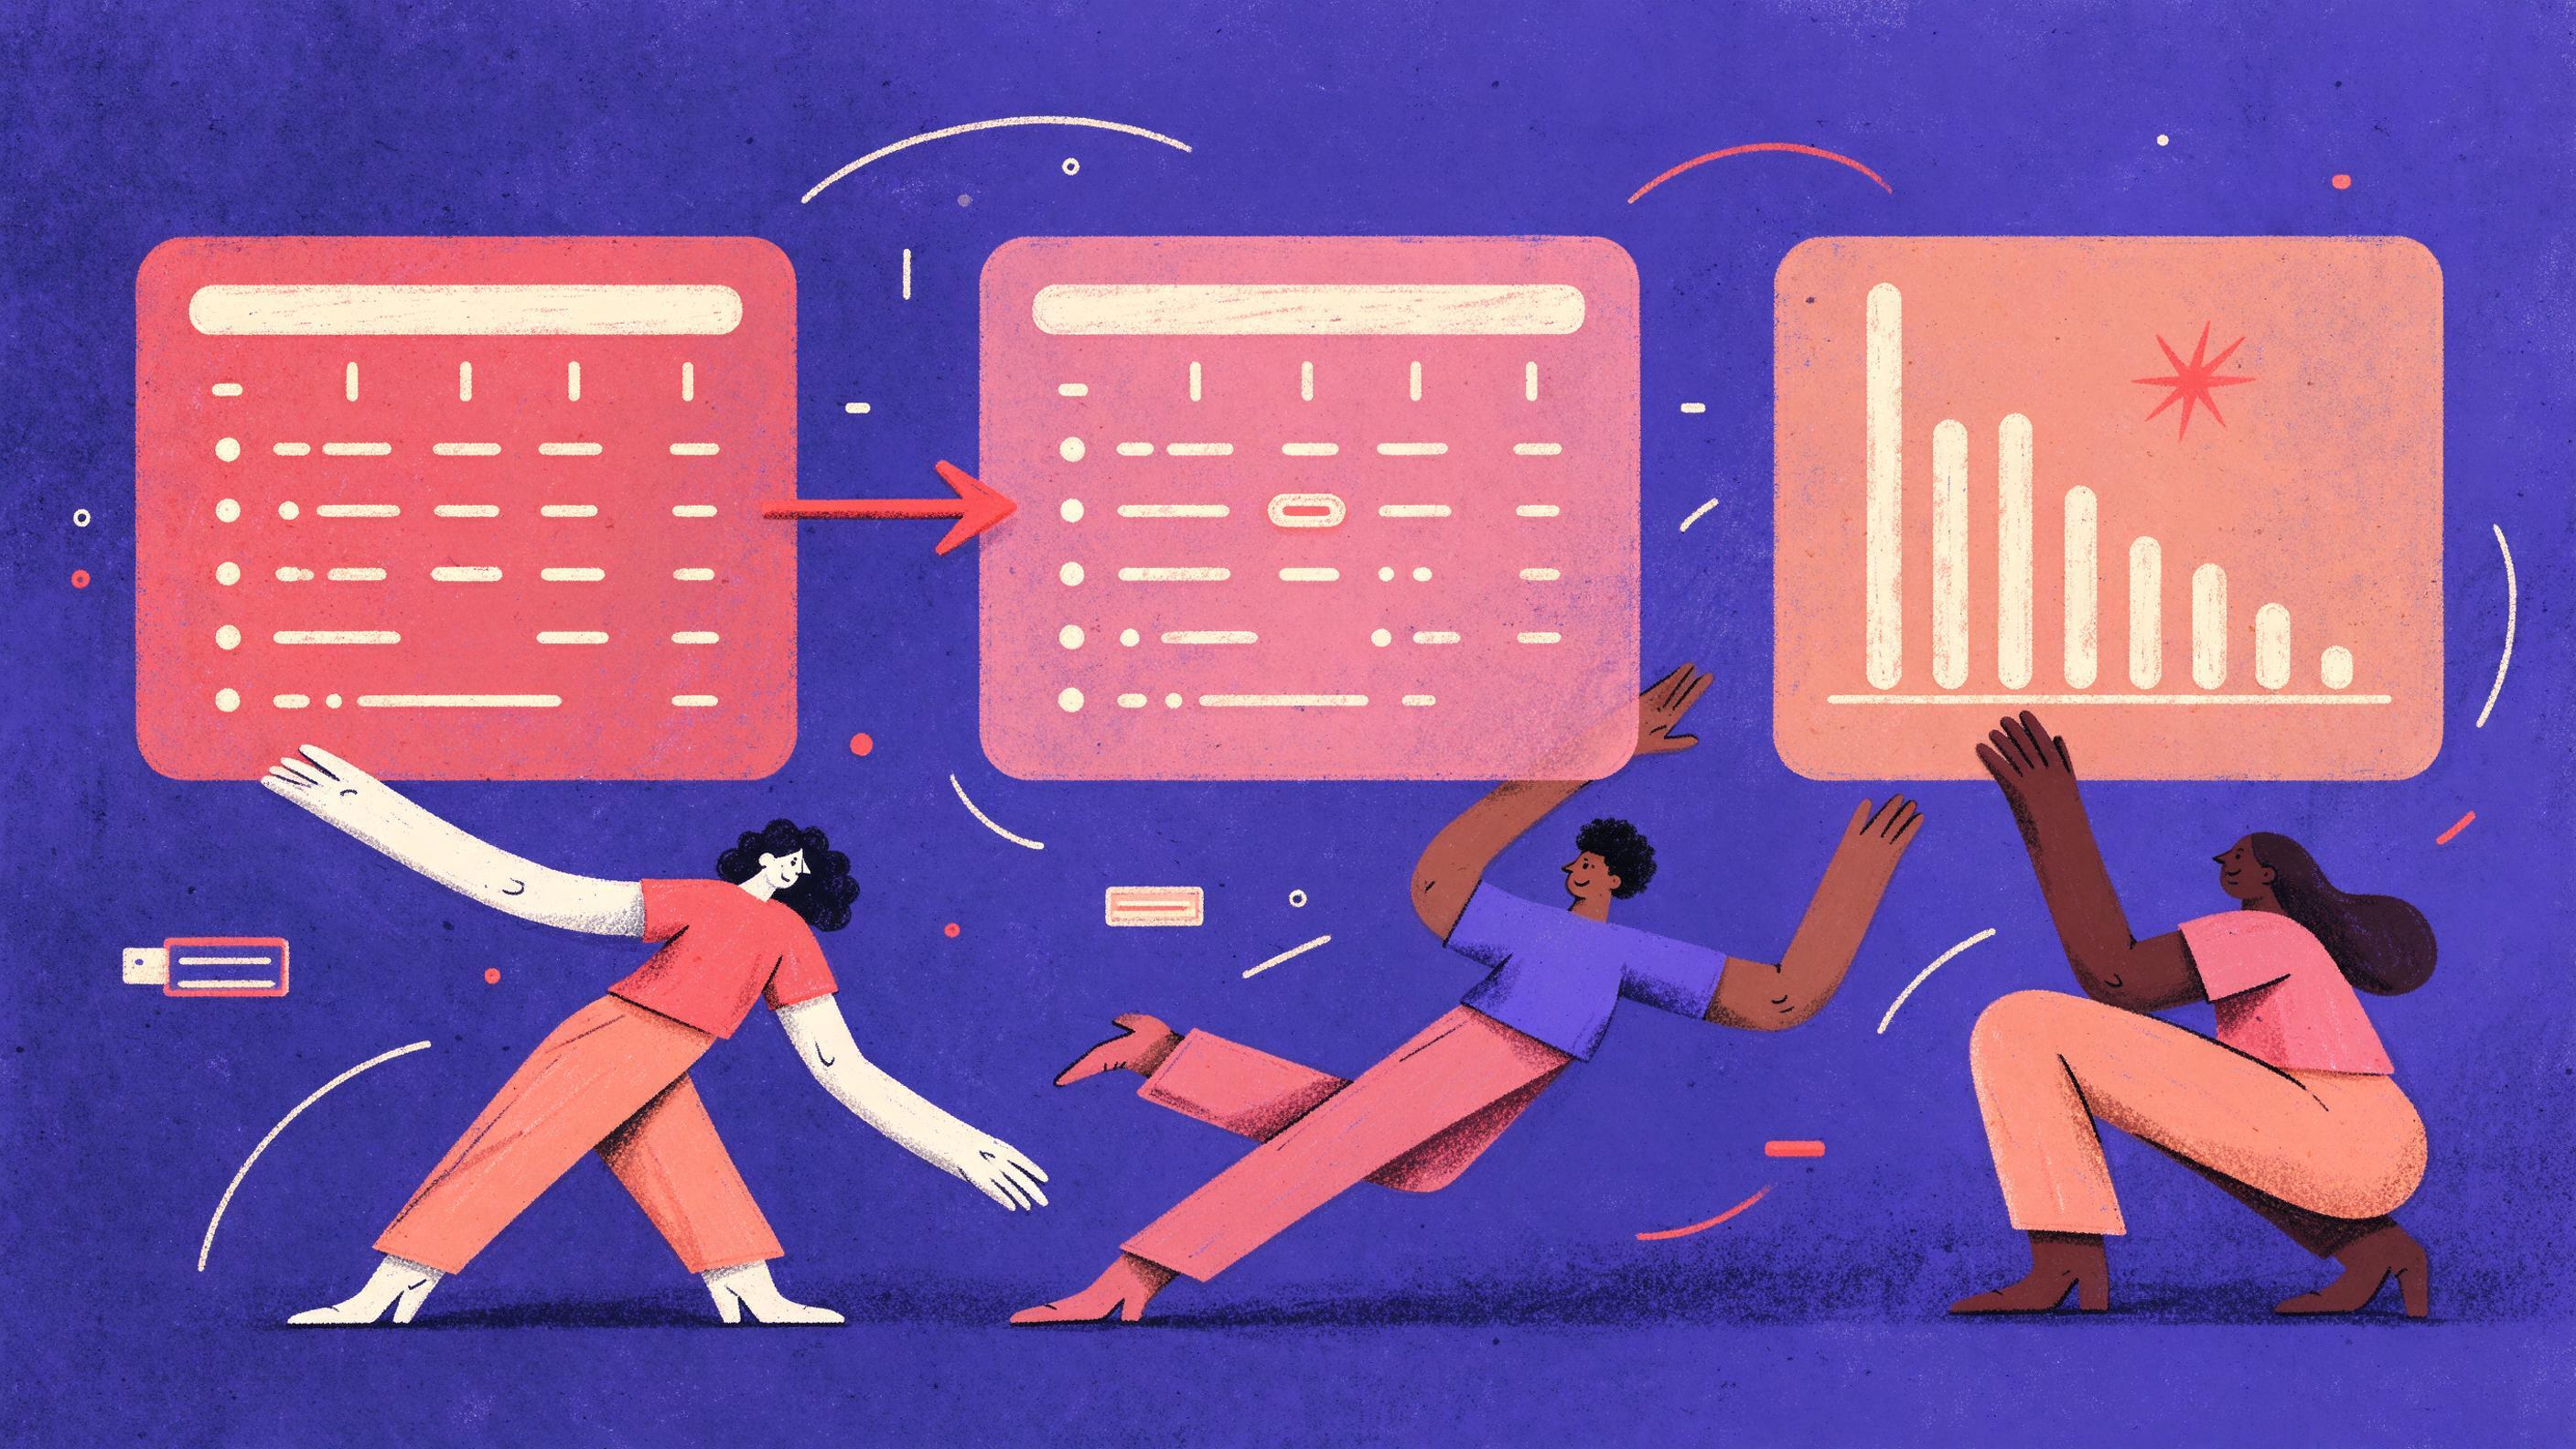
A three panel line diagram: an immutable prompt_templates table, a call_logs table with a prompt_template_id arrow pointing to it, and a bar chart ranking failure rate by prompt version.
Key points

Key points

  1. 1A prompt template's version must be written into the trace context before the model call leaves your service, so the version travels with the request instead of being reconstructed later.
  2. 2An immutable prompt_templates table with one row per version, plus a prompt_template_id foreign key on every call log, gives you a join no timestamp matching can reproduce.
  3. 3Grouping failures by prompt version surfaces a regression that averages hide, because a change that breaks one scenario often leaves the overall failure rate almost flat.
  4. 4Content-addressable or sequential version ids both work, but only if a version row is never edited after the first call uses it.

Why the version has to be in the trace context

The most common failure in prompt tracking is deciding the version after the fact. A team keeps prompts in a Git repository, deploys a change, and then tries to answer "which prompt produced this bad output?" by matching timestamps against deployment records. That works until two prompts for different features ship within the same hour, or until a rollback, a canary, or a per-tenant override puts more than one version in production at once. OpenTelemetry's model for this is clear: a trace is the path of a request through your application, and spans are the units of work inside it, carrying attributes that describe what happened (OpenTelemetry traces). A span is one chapter of a story, capturing an operation such as a vector search or a model inference call with its own attributes, status and timing (span instrumentation). If the prompt version is not an attribute on the span and not a column on the log row, you have no reliable way to attach it later.

There is a second reason to write the version early. The moment a request is composed, your service already knows which template it filled in and with which variables. That knowledge is free at that point. Recovering it downstream means re-deriving intent from a rendered string, which fails as soon as a variable contains text that looks like template syntax or a user pastes in a competing instruction.

The trace context is the right home for the version id because it crosses network boundaries. When you call a model through an HTTP client, instrumentation creates a client span, and context propagation stitches spans from different services into one trace, which is the core mechanism that makes distributed tracing work (OpenTelemetry traces). A version id set as an attribute on a span reaches your backend with the rest of the trace, alongside attributes like model name and token counts (GenAI conventions guide).

One practical warning: prompt and response bodies are deliberately kept out of standard attributes by the GenAI conventions, because they routinely contain personal data (OpenObserve). That is exactly why the version id, a low-cardinality identifier that carries no content, is the thing you should always record. Keep a hash or a redacted preview for inspection and the version id for joining (observability for AI agents).


The schema: immutable templates, one foreign key

The design has two tables and one rule. The rule is that prompt_templates is append-only: no UPDATE, no DELETE, ever. The tables follow from it.

CREATE TABLE prompt_templates (
    id              BIGSERIAL PRIMARY KEY,
    prompt_key      TEXT        NOT NULL,   -- logical name, e.g. 'support_reply'
    version_label   TEXT        NOT NULL,   -- human label, e.g. 'support_reply@v7'
    template_body   TEXT        NOT NULL,   -- the exact text, variables included
    content_hash    CHAR(64)    NOT NULL,   -- sha256 of template_body
    model_default   TEXT        NOT NULL,
    params          JSONB       NOT NULL,   -- temperature, max_tokens, etc.
    created_at      TIMESTAMPTZ NOT NULL DEFAULT now(),
    created_by      TEXT        NOT NULL,
    change_note     TEXT,
    UNIQUE (prompt_key, content_hash)
);

CREATE TABLE call_logs (
    id                  BIGSERIAL PRIMARY KEY,
    trace_id            TEXT        NOT NULL,
    span_id             TEXT,
    prompt_template_id  BIGINT      NOT NULL
                        REFERENCES prompt_templates(id),  -- exact version used
    request_model       TEXT        NOT NULL,
    status              TEXT        NOT NULL,   -- 'ok' or 'error'
    error_class         TEXT,                   -- 'schema_mismatch', 'timeout', ...
    latency_ms          INT,
    input_tokens        INT,
    output_tokens       INT,
    rendered_hash       CHAR(64),               -- hash of the final prompt string
    created_at          TIMESTAMPTZ NOT NULL DEFAULT now()
);

CREATE INDEX ON call_logs (prompt_template_id, created_at);
CREATE INDEX ON call_logs (status, created_at);

A few details carry weight. The UNIQUE (prompt_key, content_hash) constraint means reverting to an earlier prompt text does not create a duplicate version: the insert either finds the existing row or adds a genuinely new one. Because rows are never updated, a foreign key from call_logs to prompt_templates points at a fixed historical fact, which is the property that makes joins trustworthy. This is the same argument the versioning literature makes for immutability: once a version is created it should not change, because logs, traces and evaluations already reference it (Braintrust on prompt versioning). If you prefer a content-addressable primary key, use the hash itself as the id; the join behaves identically and you skip the natural-key uniqueness check.

The rendered_hash column is cheap insurance. It lets you confirm that the template row and the actual rendered string agree, so a bug in your template engine that silently drops a variable does not slip past you as "the same version." Storing a hash rather than the full prompt also keeps sensitive content out of the log table by default (Techlusion).

Writing the version before the call leaves your service

The invariant is simple: no model call is constructed without a resolved prompt_template_id. Resolve it from a cache keyed on prompt_key and the version you intend to use, then attach it to the span and pass it into the logging path.

import hashlib
from opentelemetry import trace

tracer = trace.get_tracer("app.llm")

def render_and_call(prompt_key, version_label, variables, client):
    row = template_repo.get(prompt_key, version_label)  # raises if missing
    rendered = fill(row.template_body, variables)
    rendered_hash = hashlib.sha256(rendered.encode()).hexdigest()

    with tracer.start_as_current_span("llm.chat") as span:
        span.set_attribute("gen_ai.operation.name", "chat")
        span.set_attribute("gen_ai.request.model", row.model_default)
        span.set_attribute("app.prompt.template_id", row.id)
        span.set_attribute("app.prompt.key", row.prompt_key)
        span.set_attribute("app.prompt.version_label", row.version_label)
        span.set_attribute("app.prompt.rendered_hash", rendered_hash)

        try:
            resp = client.chat(rendered, row.model_default, **row.params)
        except Exception as e:
            log_call(span, row, rendered_hash, status="error", error_class=type(e).__name__)
            raise
        log_call(span, row, rendered_hash, status="ok", latency_ms=resp.ms,
                 input_tokens=resp.usage.input, output_tokens=resp.usage.output)
        return resp

Two conventions are worth adopting even at small scale. Name attributes under your own namespace (here app.prompt.*) so they cannot collide with attributes OpenTelemetry adds or renames; the GenAI conventions themselves are split between mature chat attributes and still-evolving agent ones, and the namespace has already moved between repositories (GenAI semantic conventions, semantic-conventions-genai). And put the version id on the span rather than emitting a separate event for it, because a single-valued fact belongs in an attribute: attributes are the cheapest way to accumulate correlating data on one event, and events are for things that can happen more than once (Honeycomb on spans vs attributes). The Span Event API is itself being deprecated in favor of log-based events, which is another reason not to lean on span events for metadata (OpenTelemetry span events deprecation).

If you log to a database as well as exporting traces, write both from the same function and the same resolved row. Never let the two paths resolve the version independently: that is where mismatches creep in.

A query that ranks failures by prompt version

Now the payoff. Group by the version, not by the prompt key, and compute the failure rate per version with enough volume to matter.

WITH per_version AS (
  SELECT
    c.prompt_template_id,
    t.prompt_key,
    t.version_label,
    count(*)                                              AS calls,
    count(*) FILTER (WHERE c.status = 'error')            AS failures,
    count(*) FILTER (WHERE c.error_class = 'schema_mismatch') AS schema_failures,
    count(*) FILTER (WHERE c.status = 'error')::numeric
      / count(*)                                          AS failure_rate,
    percentile_cont(0.95) WITHIN GROUP (ORDER BY c.latency_ms) AS p95_ms
  FROM call_logs c
  JOIN prompt_templates t ON t.id = c.prompt_template_id
  WHERE c.created_at >= now() - interval '7 days'
  GROUP BY c.prompt_template_id, t.prompt_key, t.version_label
)
SELECT
  prompt_key, version_label, calls, failures,
  round(failure_rate * 100, 2) AS failure_pct,
  round(100.0 * schema_failures / nullif(failures, 0), 1) AS schema_share_pct,
  p95_ms
FROM per_version
WHERE calls >= 200
ORDER BY failure_rate DESC, calls DESC
LIMIT 20;

The calls >= 200 filter is the decision rule, and it is the part most dashboards get wrong. A version with 12 calls and 3 failures shows a 25 percent failure rate that means nothing. With 200 calls you can distinguish a real 5 percent regression from noise. Tune the threshold to your volume, but keep it: ranking by raw failure count rewards high-traffic versions even when they are healthy, and ranking without a floor rewards tiny samples.

The schema_share_pct column answers the next question. If a version's failures are mostly schema_mismatch errors, the prompt change broke the output contract, and you should suspect the instructions or the parser. If they are timeouts, the version is probably generating longer outputs than its predecessor, and the token counts will confirm it.

Why not just look at the overall error rate? Because it averages away the thing you care about. Suppose the support_reply prompt key handles 1,000 calls a day at a 2 percent failure rate, and you ship v7, which fails on 12 percent of the requests that hit one rare scenario. If that scenario is 5 percent of traffic, v7 contributes 0.12 x 50 = 6 failures, while the other 950 calls fail at 1.5 percent, or about 14 failures. Overall you go from roughly 20 failures in 1,000 to about 20 failures in 1,000. The aggregate is flat while v7 is twice as bad as it should be. Averages hide this kind of shift, which is also why tail percentiles are the standard lens for skewed latency data (percentiles explained). Percentiles and per-version grouping both exist to defeat the average.

Choosing a version id scheme

There are three common schemes. All of them work; the decision depends on how your team edits prompts and how much you care about deduplication.

SchemeExample idProsConsUse when
Sequential per keysupport_reply@v7Human readable, easy ordering, clear rollback targetNeeds a counter; a revert creates a new numberEditors change prompts one at a time
Content-addressablesha256:9f2c...Identical text maps to one row, no duplicate logicNot human readable, no natural orderingMany authors, frequent reverts, or prompts generated by tooling
Global sequentialpt_20241Simple, unique across keysSays nothing about which prompt it isYou always join through prompt_key anyway

Whichever you choose, the version row should record the model and parameter defaults it was written against. A prompt's behavior depends on more than its text: the model, the temperature, and the tool configuration all change the output (Braintrust). Recording them on the template row means a later investigation can answer "did the prompt change, or did the model behind it change?" without guessing.

A checklist for the rollout:

  • Add the prompt_templates table and backfill from whatever source of truth you have now (Git history is fine).
  • Add prompt_template_id to call_logs as nullable first, so old writes do not break.
  • Deploy the resolve step in the call path; it fails closed if the version is unknown.
  • Backfill recent call_logs by matching rendered_hash where you have it; leave the rest null.
  • Once no nulls appear for a full business cycle, add the NOT NULL constraint.
  • Check the ranking query weekly and alert when any version with enough volume exceeds your failure threshold.

That sequence avoids the classic migration problem where a non-nullable foreign key blocks deploys until every caller is updated.

Joining traces to logs without guessing

The database query gives you the correlation; the trace gives you the explanation. When the ranking points at support_reply@v7, you want to open one failing trace and see the span with the version attribute, the retrieval step, and the model call in order. That is what a trace is for: it shows the inputs and outputs of each step in the order they were invoked, which is exactly what you need when the sequence of steps varies by input (Microsoft Foundry agent tracing).

To make that jump, store the trace id on the call log row, which the sample function does by taking it from the active span. Set the version attribute at the outermost point where you know it and let context propagation carry it to the client span, because propagation is the mechanism that correlates spans across services into one trace (OpenTelemetry traces). If you fetch context from a vector store before the model call, the retrieval span sits in the same trace, and you can see whether a bad answer came from a bad prompt or from poor retrieved passages, the same distinction two-stage retrieval designs are built to manage (Pinecone on rerankers).

A worked example makes the sequence concrete. A retrieval step returns 8 passages, the prompt template inserts them, and the model call fails schema validation. The call log shows status error with error_class = schema_mismatch on support_reply@v7. The trace shows the retrieval span returning 8 passages, the model span consuming 6,200 input tokens, and no retry span. Reading the version row shows v7 added a formatting instruction and raised max_tokens. The next call to make is a rollback to v6 for that key, not a prompt rewrite, because the change is identifiable and reversible. This is the operational loop the schema exists to enable.

If you run several model providers, keeping the same attributes and the same foreign key across all of them means the ranking query does not care which provider served a call. A single OpenAI-compatible endpoint such as Quanta Inference can reduce the number of client integrations you have to instrument, since the version attribute is set by your code regardless of which model answers.

FAQ

FAQ

Do I need a separate table, or can I store the prompt text on each call log row?

You can store the text, but you should not rely on it. Duplicating the full template on every row multiplies storage and, more importantly, gives you no stable identifier to group by and no uniqueness guarantee. Keep the text once in an immutable template row and store the id on the call; the join is cheap and the grouping is exact (Braintrust).

What if a prompt change is only a whitespace fix?

It still gets a new version. Immutability means any modification, however small, produces a new row rather than editing an existing one that logs already point at. If you use content-addressable ids, trailing whitespace changes the hash and therefore the version, which is the correct behavior: you cannot prove the output is identical.

How do I handle per-tenant or per-user prompt overrides?

Treat each override as its own template row, with the overriding tenant recorded in the change note or in a scope column, and point the call log at that row. The alternative, storing a base version plus an override flag, forces every analysis query to reconstruct the effective prompt. One row per effective prompt version keeps the join and the ranking query unchanged.

Should the version attribute be a span attribute or a log event?

A span attribute. A single-valued fact that is true for the whole span belongs in an attribute, and attributes are the cheapest way to accumulate correlating data on an event (Honeycomb). Use log-based events only for things that can repeat, such as retries or individual tool errors, especially since the span event API is being deprecated (OpenTelemetry).

How much call log history does the ranking query need?

Enough per version that the failure rate is not noise. A floor of 200 calls per version is a reasonable starting point, and you should keep at least a few weeks of history so a slow-burning regression shows up before the data ages out. If storage is tight, keep full rows for recent windows and roll older data into a per-version daily summary table with the same foreign key, which also keeps your dashboards fast.

Sources

Sources

  1. Traces
  2. Day 151, Span Instrumentation in OpenTelemetry: The ...
  3. OpenTelemetry GenAI Semantic Conventions: A Practical ...
  4. Observability for AI Agents, Logs, Traces and SLOs You ...
  5. What is prompt versioning? Best practices for iteration without ...
  6. Moved: Generative AI semantic conventions
  7. semantic-conventions-genai - open-telemetry
  8. Span or Attribute in OpenTelemetry Custom Instrumentation
  9. Deprecating Span Events API
  10. P50 vs P95 vs P99 Latency Explained
  11. Agent tracing overview - Microsoft Foundry
  12. Rerankers and Two-Stage Retrieval
About the author

About the author

Antonio Evans
Antonio Evans

Antonio Evans is the founder of Quanta Intelligence and a fractional CTO who builds HIPAA-ready AI systems for health and life-science companies. Before that he was technical co-founder of FriendsEAT for twenty years, CEO of Socialdraft, and a data engineer at IBM. Antonio lives with his dog Santino in Lisbon, Portugal.

All articles