
AI agents

Measuring the Cost of a Missing Fact: Recovery, Refusal, Re-Ask

Antonio Evans10 min read

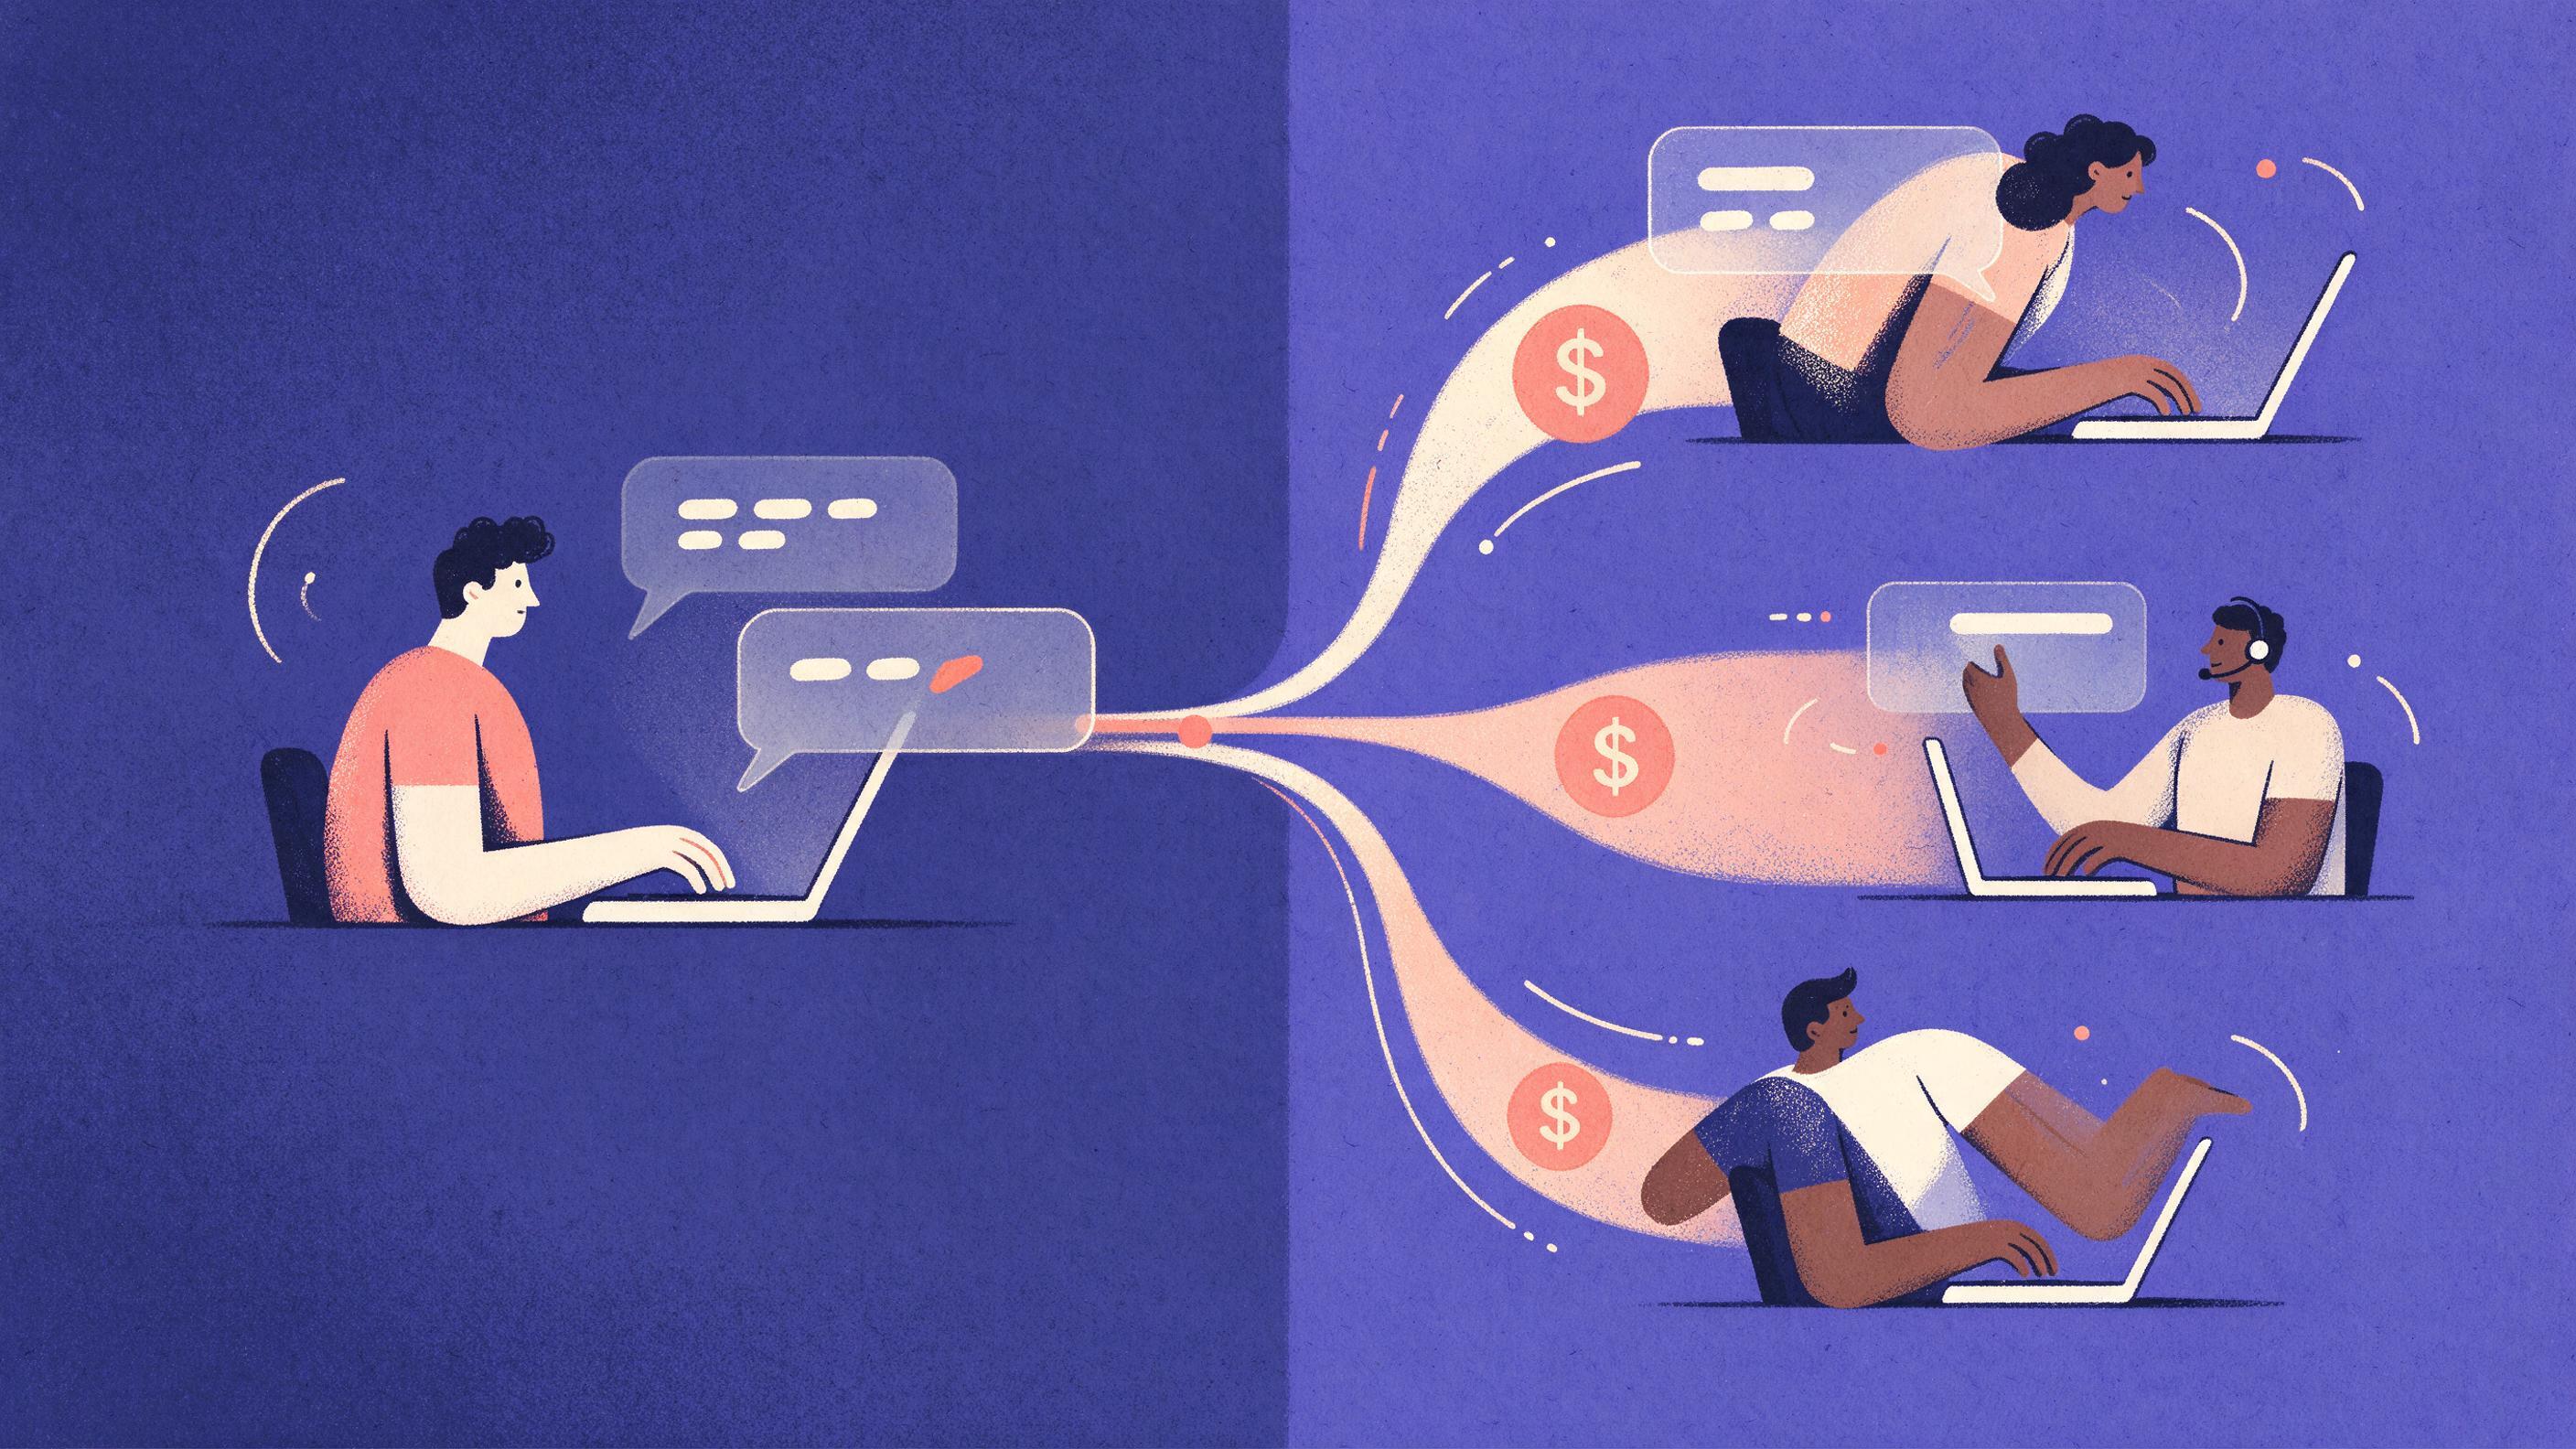
A split diagram: on the left a user types a question and the answer shows a missing fact, and on the right three paths (re-ask, human escalation, churn) each carry a dollar sign and a probability.
Key points

Key points

  1. 1The cost of a missing fact is an expected value: each recovery stage (re-ask, escalation, churn) multiplied by the probability a user takes it.
  2. 2Re-ask cost is mostly user time in minutes times a loaded hourly rate, plus the compute and latency of the extra turn.
  3. 3Escalation cost is the fully loaded price of a ticket or expert minute, and repeat contacts multiply it.
  4. 4Churn cost is customer lifetime value times the change in churn probability caused by the failed session.

Why the break-even math needs a denominator

Most teams can estimate what a memory or retrieval improvement costs per query. Very few can state what a missing fact costs per query, so the comparison never closes. The ratio that matters is simple: cost of the fix divided by cost of the failure. If a retrieval change costs one dollar per thousand queries and each missing fact costs forty cents in recovered user effort, the change pays for itself when it prevents about three misses per thousand queries. Without the failure figure, nobody can approve or reject the work.

The failure itself has a clean definition. A missing fact is any piece of information the system should have surfaced for this turn but did not: a stored preference, a policy number, a prior decision, a customer identifier. The distinction between storage and retrieval matters here. As one memory-engineering write-up puts it, storage answers whether the agent remembered something, while retrieval answers whether the agent used it at the right moment, and most reported memory failures are retrieval failures rather than storage failures (mem0). That is useful because retrieval misses are measurable per query, which makes them pricable.

A second cause of missing facts is quieter: the fact was retrieved but cut or buried. When a prompt overflows its configured window, servers silently truncate, and a passage the server cut is gone from the response with no error field to tell you (ml4devs). Even inside the window, position matters: models are often strongest on information at the beginning or end of the context and degrade when the relevant passage sits in the middle (Lost in the Middle). Reranker research adds a price to that: one distractor passage cut accuracy by 6 to 11 points across models in a cited study, with one small model dropping from 82.6 to 71.5 (Splunk). Both mechanisms produce the same user-visible event: the fact was there, the answer lacked it, and the user has to recover.


The three recovery stages and their costs

Model the recovery path as a sequence of stages with a probability attached to each. A user who hits a miss either re-asks, escalates, or leaves (sometimes in that order, sometimes jumping straight to leaving).

StageWhat happensMain cost componentsHow to measure the probability
Re-askUser retypes, adds the missing fact, or corrects the systemUser minutes at loaded rate, extra turn compute, added latencyCount sessions with two or more user turns containing a correction or restated context
EscalationSupport ticket, chat handoff, or expert consultationFully loaded ticket cost or expert minute cost, plus repeat contactsCount misses that end in a handoff, divided by total misses
ChurnSession abandoned or account cancelledLifetime value times incremental churn probabilityCompare retention of affected sessions or accounts against a matched control

The right way to combine them is expected value:

E[cost per miss] = p_reask * C_reask
                 + p_escalation * C_escalation
                 + p_churn * C_churn

The probabilities do not have to sum to one in your tracker if you allow a user to re-ask and then escalate in the same episode. If you want a single number per episode, either count the episode once at its most expensive stage or sum the stages the user actually took. Write down which convention you chose; mixed conventions are the most common reason two teams report different costs for the same system.

Pricing a re-ask

A re-ask is the cheapest stage, which is why it is usually ignored and why it dominates the total by count. Price it as time plus compute.

Start with the time. A user who has to restate a preference, paste an account number, or reformulate a question that the system should have understood spends somewhere between a few seconds and a few minutes. Multiply minutes by a loaded hourly rate (salary plus benefits plus overhead, not the hourly wage). At a fully loaded rate of $60 per hour, one minute of extra work costs one dollar, and two minutes costs two. That sounds small until you multiply it by the miss rate and query volume, which is the whole point of an expected value.

Then add the compute. A re-ask is an extra turn, and the extra turn carries no conversation context beyond what the user retypes, so it is often a near-repeat of the first prompt at full input token cost. Multi-turn agents already accumulate context quickly: in one worked example, four turns of a research agent with tool results reached roughly 10,000 tokens of state before a follow-up question arrived (mem0). If each extra turn carries that accumulated state, the marginal token cost per re-ask is not trivial at volume.

Two measurement notes. First, instrument the turn, not just the transcript: record request start, retrieval start and end, model start, first output and completion, and trace retries as well as successes, because failed requests that return early can fake a speed improvement (Supermemory). Second, treat the latency part of the re-ask cost as a user-experience cost rather than a token cost; a re-ask that takes twelve seconds converts to escalations at a much higher rate than one that takes two, and that conversion is what you are trying to capture in the escalation probability.

Worked example. Suppose 1,000 sessions per day, 4 percent of sessions contain a missing fact, and 70 percent of those produce a re-ask of two minutes. That is 40 misses per day, 28 re-asks, and 56 user minutes, which at $60 loaded per hour is $56 per day, or about $20,000 per year. Add compute: 28 extra turns at, say, 6,000 input tokens each is 168,000 tokens per day, which is real but an order of magnitude smaller than the time cost at most retail token prices.

Pricing an escalation

Escalation is where the numbers get large enough to change decisions. Published benchmarks vary widely by tier and channel, so pick the one that matches your queue and say where it came from.

A service desk benchmark cited by Maven AGI reports an average cost of $22.50 per resolved incident, with self-service averaging $15 and agent-handled tickets averaging $45 (Maven AGI). The same source reports that escalated requests cost about three times more than first-level resolutions. Moveworks, looking at IT tickets specifically, puts manual resolution of a Tier 1 ticket at around $22, Tier 2 at roughly $60 to $80, and Tier 3 above $104 (Moveworks). A cross-industry summary gives a broader range: $2.70 to $5.60 for retail e-commerce, $18 to $35 for SaaS, and $30 to $60 for B2B support (Lorikeet).

The single most expensive feature of escalation is not the first ticket. It is the repeat contact. The same cross-industry summary notes an average of 2.3 contacts per issue, which means the true cost per issue is 2.3 times the cost per contact, and first-contact resolution predicts total support cost better than handle time does (Lorikeet). This is exactly what a missing fact produces: the user opens a ticket to supply the fact, the ticket gets routed twice because it was filed under the wrong intent, and the issue resolves on the third contact. When you price escalation for a missing fact, use cost per issue, not cost per ticket, or you will halve your own estimate.

A practical allocation for an escalation triggered by a miss is one fully loaded Tier 1 ticket plus a repeat-contact multiplier between 1.5 and 2.3, adjusted to your own contact-per-issue data. At a $22 ticket and a 2.0 multiplier, each escalation costs about $44. If 12 percent of the 40 daily misses escalate, that is 4.8 escalations per day, about $211 per day, and the escalation line now exceeds the re-ask line.

Pricing churn

Churn is the smallest probability and the largest number, so it deserves the most care. The formula is lifetime value times the incremental churn probability attributable to the failed session, and the word incremental does the work.

Get lifetime value for the affected segment first. A common trap is using an average across all accounts when the users hitting misses are concentrated in one plan. Churn rates differ sharply by plan: in a fictional but clearly constructed worked example, a Starter plan showed 6.0 percent monthly customer churn against 3.0 percent for Growth and 1.0 percent for Enterprise, with Starter contributing 78.3 percent of all losses (Cube). Small plans churning faster than large ones is a familiar pattern, and it means the customer who hits a missing-fact loop is often your highest-churn segment.

Then estimate attribution. Do not guess. A defensible method is a matched comparison: take accounts that experienced a failed session in a period and compare their retention at equal tenure against accounts that did not, holding plan and acquisition cohort constant. The Cube workflow makes the same point about attribution hygiene: a segment with high observed churn is a starting point for investigation, not a causal finding, and observed rates should be separated from hypotheses about causes (Cube). If your comparison suggests affected accounts churn 1.5 percentage points more per quarter, and lifetime value in that segment is $400, the churn term is 0.015 times $400, or $6 per affected account per quarter, allocated across the sessions that account ran in that quarter.

Behavioral signals help here at the session level. Usage-priced AI platforms see retention trouble in the usage table weeks before billing notices it: sessions thin out, agent runs stop, and the API key stays valid the entire time (Data Science Collective). That gives you a leading indicator to align with failed sessions, which is far better than waiting for the renewal to not happen.

Assembling the number and using it

Put the three lines together for the worked example. Daily miss volume is 40. Re-asks cost $56 per day in time. Escalations cost about $211 per day. Churn: assume 10 percent of misses come from accounts in a high-churn segment with $400 lifetime value and a 1.5 point quarterly lift, which is roughly $6 per affected account per quarter, or about a penny per session spread over a quarter. Churn lands near $1 per day at this volume. The total is about $268 per day, dominated by escalation, with re-ask second and churn nearly invisible at the per-miss level. That ranking is the insight most first-pass calculations miss: teams obsess over churn and underprice re-asks and repeat contacts, which are where the money actually goes at typical volumes.

Sanity-check the ranking against your own data before trusting it. The pattern holds when escalation rates exceed about 5 percent of misses. If almost nobody escalates, the re-ask line dominates and the fix is cheaper: better retrieval ranking and a shorter, more reliable first response. If escalation is high, the fix is likely the same but the justification is stronger, because you are removing three-times-costlier contacts rather than seconds of user patience.

Two operational rules keep the number honest. First, charge the fix against the same denominator you used for the failure: if you measured misses per session, express the fix as cost per session, not cost per query. Second, rerun the estimate on a fixed question set whenever retrieval, reranking, or context assembly changes, with the same quality criterion, because a smaller candidate set or a new reranker can save latency while quietly dropping supporting evidence (Supermemory). Routing work like this is exactly what budget-tier memory frameworks are built for: a lightweight router picks low, mid, or high tiers per query, and the measured trade-off only makes sense if you know what a miss costs (BudgetMem).

When you have the failure cost, the improvement decision usually settles quickly, and the remaining work is measurement plumbing across several models and vendors. Quanta Inference puts text, image, video, audio and embedding models behind one OpenAI-compatible API key, which makes A/B runs on the same question set cheaper to orchestrate: https://quantaintelligence.ai/inference.

Common measurement mistakes

A checklist to run before anyone signs off on the cost figure.

MistakeWhat it does to the estimateFix
Using cost per contact instead of cost per issueUnderstates escalation by the contact-per-issue multiplier, often 2x or moreMultiply by your measured contacts per issue
Counting only escalationsIgnores the highest-frequency stageTrack re-ask rate from transcript corrections
Averaging stage P95sProduces an end-to-end figure that does not match any real requestTrace complete requests and compute percentiles from them
Attributing all churn to missesOverstates the failure cost and kills good projectsUse matched cohorts and equal-tenure retention
Treating a reranker as free qualityAdds 100-500 ms per turn and can hide misses if candidates shrinkCompare on a fixed question set with an explicit quality criterion
Ignoring truncationMissing facts that were retrieved but cutLog prompt token counts against the served window

The percentile mistake is worth spelling out. You cannot add each stage's P95 and call the sum the end-to-end P95, because slow stages may fall on different requests or overlap; trace complete requests instead (Supermemory). The same logic applies to cost percentiles: a per-request cost distribution with a long tail is more informative than an average, because the costly misses cluster in the tail cases where context overflowed or a reranker picked a distractor.

If your miss analysis keeps pointing at answers that rearranged good evidence badly, the generation layer may deserve the first hour of engineering rather than the retrieval layer; one practitioner audit attributes the majority of RAG failures to the generation phase and reports that prompt fixes moved a faithfulness score far more than months of index tuning (SystemDR). Whatever you change, price the miss before and after on the same question set, or you will not be able to tell whether the fix paid.

FAQ

FAQ

What is the formula for the cost of a missing fact?

The cost is the expected value of the recovery path: the cost of a re-ask times the probability the user re-asks, plus escalation cost times its probability, plus churn cost times its probability. Churn cost is lifetime value times the incremental churn probability caused by the failed session. Decide in advance whether an episode that re-asks and then escalates counts both stages or only its most expensive one, and apply that rule consistently.

How do I measure the re-ask probability without surveying users?

Read the transcripts. Count sessions where a user restates context, pastes an identifier, or corrects the previous answer, and divide by sessions that contained a miss. Instrument per-turn timing alongside the text so you can separate a user pausing to think from a user waiting on a slow response, and trace retries so failed requests do not look like fast successes (Supermemory).

Should I use cost per ticket or cost per issue for escalation?

Use cost per issue. Published benchmarks put a service desk ticket near $22.50 on average and a self-service resolution much lower, but an average of 2.3 contacts per issue means the real cost per resolved issue is more than twice the per-contact figure (Maven AGI, Lorikeet). A missing fact frequently causes the second and third contact, which is precisely the cost you are trying to prevent.

How do I attribute churn to a failed session rather than to price?

Use a matched comparison of accounts that hit a miss against accounts that did not, holding plan and signup cohort constant and comparing retention at equal tenure. Rates differ sharply by plan in most data sets, so an average across segments will mislead you (Cube). Then allocate the resulting lifetime value loss across the sessions those accounts ran, and treat the result as an estimate, not a cause.

Which stage usually dominates, and does that change what I should build?

Escalation usually dominates once more than roughly 5 percent of misses turn into tickets, because ticket and repeat-contact costs are an order of magnitude larger than a minute of user time. Below that threshold, re-asks dominate and faster, better-ranked retrieval is the cheaper fix. Whichever way it lands, the same instrumentation drives both: miss rate per session, stage probabilities, and a fixed question set to re-measure after every retrieval or context change.

Sources

Sources

  1. Memory Retrieval Strategies for AI Agents
  2. How to Budget an LLM Context Window
  3. Lost in the Middle: How Language Models Use Long ...
  4. How to Select the Right Reranking Model
  5. Context Engineering in Multi-Turn AI Agents
  6. Latency Budgets for Memory Retrieval
  7. 15 Cost-Per-Ticket Statistics for Customer Support - Maven AGI
  8. What Does Manual IT Ticket Resolution Really Cost? - Moveworks
  9. Cost Per Support Ticket: Benchmarks and How to Reduce It | Lorikeet
  10. Churn Analysis with AI: Metrics & Workflow
  11. Building a churn risk queue for an AI platform's customer ...
  12. Learning Query-Aware Budget-Tier Routing for Runtime ...
  13. Advanced Prompt Engineering for RAG Pipelines
About the author

About the author

Antonio Evans
Antonio Evans

Antonio Evans is the founder of Quanta Intelligence and a fractional CTO who builds HIPAA-ready AI systems for health and life-science companies. Before that he was technical co-founder of FriendsEAT for twenty years, CEO of Socialdraft, and a data engineer at IBM. Antonio lives with his dog Santino in Lisbon, Portugal.

All articles
