Development

Paging APIs: Keyset vs Offset and How to Change Your Mind Later

Antonio Evans9 min read

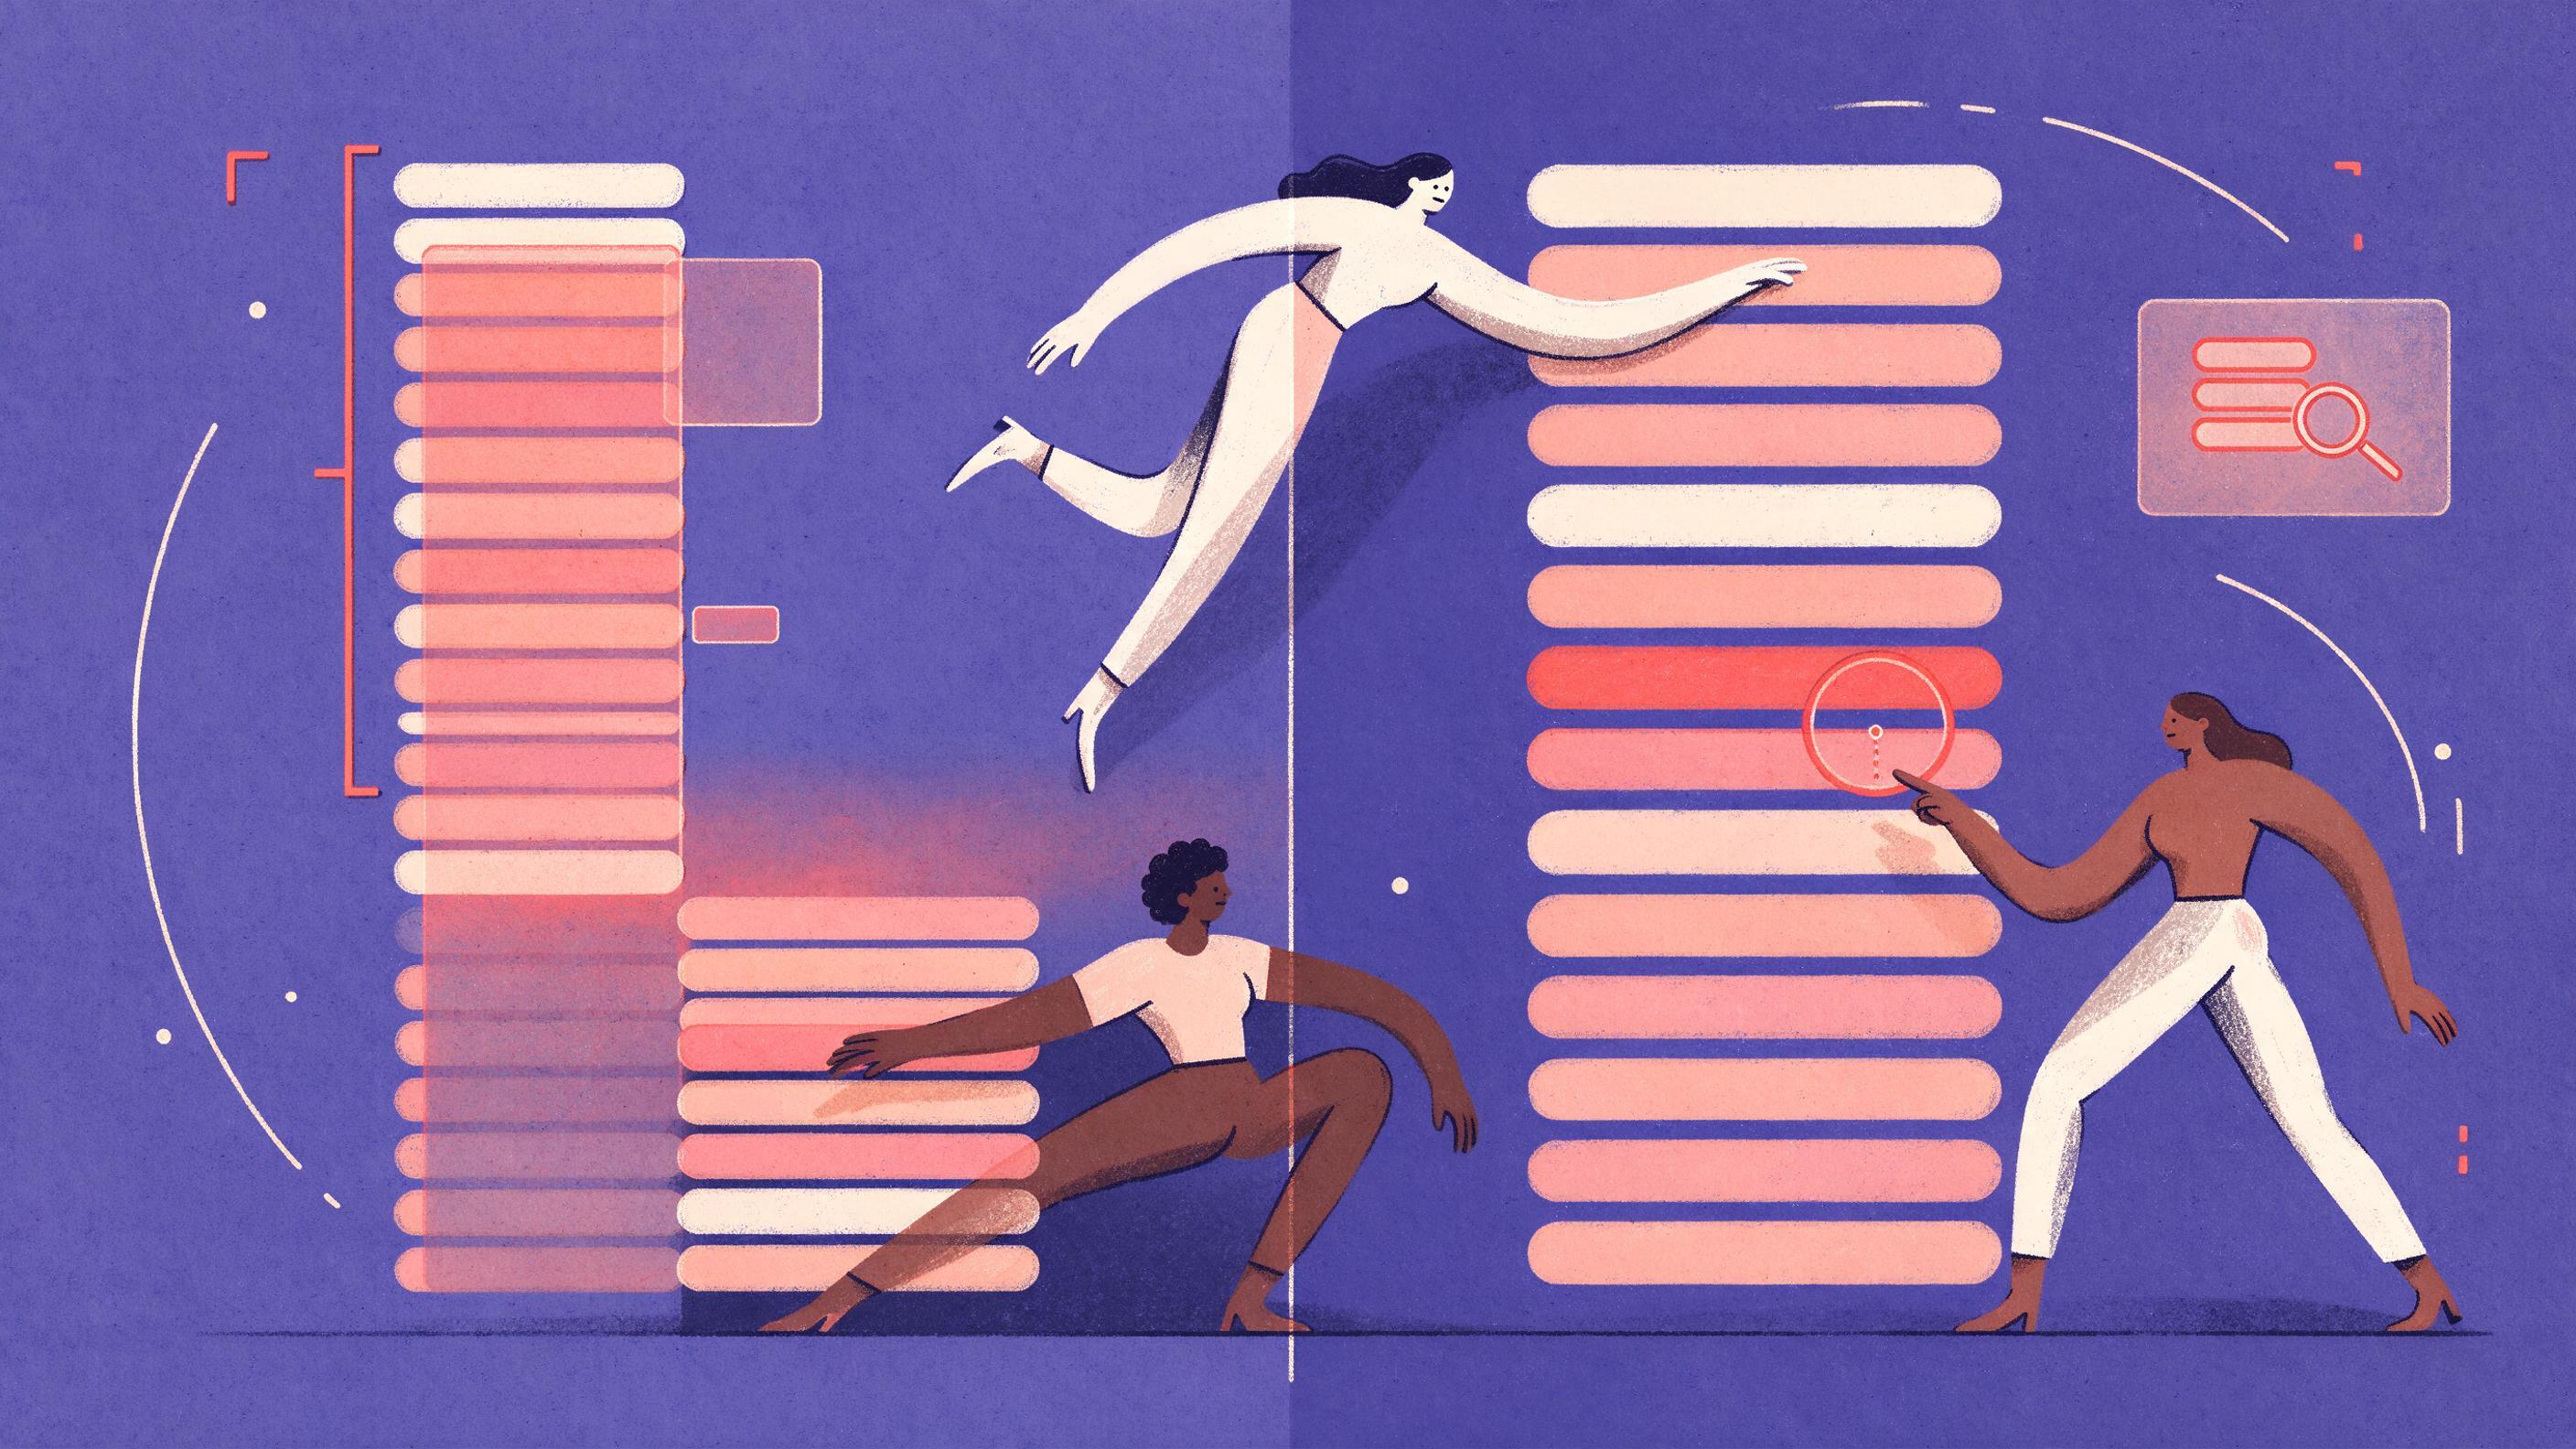
A split diagram: left, numbered rows with an OFFSET 40 LIMIT 20 bracket and a shaded gap where deleted rows shift the list; right, one highlighted row sought by a WHERE clause on its sort tuple.
Key points

Key points

  1. 1Offset pagination translates to LIMIT/OFFSET, which makes the database read and discard every row before the page, so query cost grows with page depth.
  2. 2Keyset pagination seeks to a position with a WHERE clause on the last row's sort key plus a unique tiebreaker, keeping each page roughly the same cost no matter how deep you go.
  3. 3Offset pagination shows duplicate and skipped rows when data changes between requests, because the row at a given offset is not the same row on the next call.
  4. 4If you return an opaque cursor from day one, you can switch the storage strategy behind it later without breaking a single client.

The mechanics of each approach

Offset pagination is the pattern everyone reaches for first. The client sends a page number or a skip count, the server multiplies by the page size, and the database runs something like SELECT * FROM transactions ORDER BY created_at DESC LIMIT 20 OFFSET 40. The math is offset = (page_number - 1) * page_size, which is easy enough that any developer can implement it quickly Gusto's developer guide. The response usually carries a total, so the client can render "page 3 of 250."

Keyset pagination asks a different question. Instead of "skip the first N rows," the client says "give me rows after this one." The last row on the current page supplies its sort value and a unique tiebreaker, and the next request becomes WHERE (created_at, id) > ('2025-09-01T10:00:00Z', 44219) ORDER BY created_at, id LIMIT 20. Because the predicate is anchored on values and the index covers the sort columns, the engine can seek directly to the position. The database never reads the 99,980 rows it does not need the Design Gurus pagination guide.

The distinction in one line: offset counts rows, keyset names a position. That single difference drives almost every behavioral and performance consequence below.

A third family of behavior exists in managed systems. Elasticsearch and OpenSearch use point-in-time snapshots plus search_after parameters, which are effectively keyset pagination with a frozen view of the index the Medium keyset guide. AWS documents all three patterns (offset, keyset, and temporal) for Aurora DSQL and frames cost in terms of distributed processing units consumed, so careless pagination costs real money on a serverless database the AWS Database Blog.

Where offset pagination breaks

Three failure modes matter, and each has a concrete trigger.

Drifting rows. Suppose a user is on page 5 of a transaction list with page size 20, so they are looking at rows 81 through 100. While they read, three new transactions land at the top. When they request page 6 (OFFSET 100), the three new rows have pushed everything down by three, so rows 98, 99 and 100 appear again on the next page. Nothing is corrupted, but the user sees duplicates. Swap inserts for deletes and the same shift causes rows to be skipped entirely. Contentful describes this as data drift and notes it is hard to reason about in near-real-time content environments Contentful's pagination announcement.

Deep-offset cost. OFFSET 10000 does not teleport to row 10,001. The engine scans, evaluates ordering, checks visibility on each candidate row, and throws away the first 10,000. On a large PostgreSQL table, the Design Gurus guide reports a page 1 query at 8 ms and a page 10,000 query at 8,200 ms, with the offset scanning almost 200,000 rows to return 20 the Design Gurus pagination guide. Fetching page 1 can take milliseconds while page 1,000 takes seconds on the same dataset, per Gusto.

The count. SELECT COUNT(*) over millions of rows is expensive, runs on every request, and is stale the moment it returns. Some APIs drop totals altogether, others cache them and accept the staleness Gusto's developer guide. Either way, "page 3 of 250" becomes approximate rather than authoritative.

Unstable sorts. This one bites both patterns. If you order by a non-unique column such as created_at or status, rows with equal values can come back in any order the engine pleases. Under offset pagination that means the same two rows might straddle a page boundary and appear on both pages, or neither. Under keyset pagination it is worse: a WHERE created_at > X predicate has no well-defined way to place rows that share the exact value X, so a group of equal timestamps can be skipped wholesale. The fix is always to add a unique, immutable tiebreaker to the sort, usually the primary key, and order by (created_at, id) the Medium keyset guide.

The decision rule

Here is a rule you can apply in a design review without a benchmark.

SignalUse offsetUse keyset
Row count likely under roughly 10,000YesEither
Data changes between requestsNoYes
Callers need "go to page 47"YesNo
Callers need a total countYesNo (or cache it)
Feed, log, transaction history, activity streamNoYes
Admin table with a mostly static exportYesEither
Deep scrolling is expectedNoYes

Gusto's guide puts the offset comfort zone at roughly under 10,000 records and frames offset as a good fit for admin dashboards with mostly static data and search results where users rarely pass the first few pages Gusto. AWS's DSQL post reaches the same split and adds a batch-processing constraint: keep a working set within the transaction row limit and page through it with keyset the AWS Database Blog.

The rule in words: if the caller needs a number and the dataset is small and quiet, offset. If the caller needs to walk a moving list, keyset. If the caller needs both, return a cursor as the primary navigation and a cached count as a convenience.

Designing a cursor that survives change

The single decision that keeps your options open is to make the cursor opaque from day one. Never expose ?after_id=44219 or ?last_created_at=... as the public contract. Expose ?cursor=eyJ2IjoxLCJrIjpbIjIwMjUtMDktMDFUMTA6MDA6MDBaIiw0NDIxOV19 and treat its contents as server-private.

A workable cursor payload has four parts:

  1. Version. An integer that lets you change the layout later without guessing which format a client holds.
  2. Sort signature. A short hash of the sort order plus the filter set. If a client sends a cursor minted for created_at DESC against a request for title ASC, reject it with a clear error instead of returning garbage.
  3. Position. The last row's sort key values, including the tiebreaker.
  4. Optional snapshot marker. For temporal or point-in-time reads, a timestamp or token that pins the view.

Encoding is your choice; base64url of a small JSON object is enough to start. Sign or encrypt it if you do not want callers to read and hand-edit the values, and validate the sort signature on every request. The Medium keyset guide calls out exactly this: when filters or sort change, invalidate the cursor, and when data changes, deterministic ordering prevents skips and duplicates the Medium keyset guide.

A response shape that leaves room to grow looks like this:

{
  "data": [ ... ],
  "page": {
    "next_cursor": "eyJ2IjoxLC...",
    "prev_cursor": "eyJ2IjoxLC...",
    "has_more": true
  }
}

Keep the envelope flat and stable. If you later add total_estimate, it slots in without disturbing anything. Errors belong in a standard shape too; RFC 9457 defines application/problem+json for machine-readable error details, and Spring's ProblemDetail implements it so you do not hand-roll a format RFC 9457 Spring Framework error responses. A stale cursor is a 400 with a type of something like https://api.example.com/problems/stale-cursor, not a 500.

Migrating without breaking clients

Changing the pagination contract is a breaking change in the strict sense: a client that only knows ?page=3 cannot survive a server that only accepts ?cursor=.... Postman's versioning guide lists renamed and removed parameters as breaking changes, and recommends planning versioning before you ship rather than after Postman's API versioning guide. Speakeasy's versioning guide makes the same point about additive versus breaking changes and notes that external clients may resist migration because of the effort involved Speakeasy versioning best practices.

That frames a three-phase rollout that does not need a version bump at all.

Phase 1, add cursors alongside pages. Accept both ?page=N&limit=M and ?cursor=..., return next_cursor in the envelope for every response regardless of which form the client used, and keep the existing page fields intact. Additive changes are non-breaking Speakeasy. You are now minting cursors on every request, so the translation path exists.

Phase 2, translate in both directions. For each page request, compute the cursor for the last row returned. For each cursor request, you may need to answer "what page number is this?" for clients that mix both. If the underlying storage is offset and the cursor encodes (sort_key, id), you can resolve a page by running a bounded keyset query or by a COUNT(*) WHERE (sort_key, id) < .... Cache those counts; they are the expensive part. Document that the page number for a cursor is approximate the moment data shifts.

Phase 3, switch storage and wait for traffic to drain. Add the composite index on (sort_key, id), flip the query planner to keyset reads, and watch logs for clients still sending ?page=. Sunset the page parameters on a published timetable. Akamai's glossary on API versioning notes that deprecating old behavior is easier when you can mark features deprecated in an older version and migrate consumers deliberately Akamai's API versioning glossary.

Two operational checks make the cutover safer. First, run compatibility tests that assert both request styles return the same row set for a static dataset; xMatters recommends exactly this callback to backward compatibility, with CI failing the build when response schemas drift xMatters API versioning strategies. Second, log which style each client uses and by which API key, so you know who has not migrated.

If you need to change page size later, keep the size out of the cursor's identity. A cursor that encodes position only can be replayed with ?limit=50 instead of ?limit=20 and still works: you resume from the same row and read further. A cursor that encodes "page 4 of 20" cannot. This is another reason position-based encodings age better than page numbers.

The same logic applies when the sort order changes. A cursor for created_at DESC is meaningless for title ASC, so the sort signature check turns a silent corruption into a visible 400. Ask the client to restart the listing.

def paginate(conn, sort_col, tiebreak, last_key=None, last_id=None, limit=20):
    base = f"SELECT id, {sort_col} FROM items"
    if last_key is None:
        sql = f"{base} ORDER BY {sort_col}, id LIMIT %s"
        params = (limit + 1,)
    else:
        sql = (
            f"{base} WHERE ({sort_col}, id) > (%s, %s) "
            f"ORDER BY {sort_col}, id LIMIT %s"
        )
        params = (last_key, last_id, limit + 1)
    rows = conn.execute(sql, params).fetchall()
    has_more = len(rows) > limit
    rows = rows[:limit]
    return rows, has_more

The limit + 1 trick tells you whether another page exists without a count query. You fetch one extra row, check it, and drop it.

Sorting, filtering and tiebreakers in practice

Keyset pagination gets harder when filters and multi-column sorts arrive, but the shape does not change: every column in the ORDER BY must appear in the WHERE comparison in the same order, and the last sort column must be unique.

For a two-column sort, the predicate is a row comparison, which most relational engines support directly. PostgreSQL, for example, accepts (a, b) > (x, y) and can use a composite index on (a, b). For three or more columns with mixed direction, write the comparison out or normalize the direction in the index. AWS's DSQL post emphasizes composite indexes tuned to the exact sort order as the way to keep keyset fast the AWS Database Blog.

Filters interact with cursors in two ways. If a filter is part of the request, it must be part of the cursor's signature, because a cursor minted while filtering by status=open is not valid for status=closed. If a filter is expensive (a search, a join), the index strategy gets harder and you may be better served by a search engine's point-in-time plus search_after rather than a relational scan the Medium keyset guide.

The link between API pagination and broader API design is worth stating: allowing filtering, sorting and pagination is a standard expectation of a REST collection endpoint, and consistent parameters across resources make your API easier to consume the Stack Overflow REST best practices guide. Microsoft's Azure guidance adds that a stateless request model is what makes pagination work at scale at all, since no server needs to remember where a client was Microsoft's RESTful API design guidance.

Cursor design is a small, well-scoped engineering problem, and if your team is short on cycles, describing the contract ("cursor is opaque, position-based, versioned, sort-signature checked") to a specialist is often all it takes to get it right. Quanta Intelligence can pick the endpoint up and build it with you: https://quantaintelligence.ai/.

A worked example and a checklist

Take a payments table with 50 million rows, page size 20, sorted by created_at DESC.

Offset, page 1: OFFSET 0, the index supplies 20 rows, roughly 8 ms in the Design Gurus measurement. Offset, page 1,000: OFFSET 19,980, the engine scans about 20,000 rows, roughly 890 ms. Offset, page 10,000: OFFSET 199,980, roughly 8,200 ms the Design Gurus pagination guide.

Keyset, any page: WHERE (created_at, id) < ('2024-11-03T09:14:22Z', 8812334) ORDER BY created_at DESC, id DESC LIMIT 20, the composite index seeks to the position, and the cost stays close to the page-1 number across the whole list. That is the entire argument in one row of numbers.

Ship checklist:

  • Sort is total: every ORDER BY ends in a unique column, and the table has a composite index matching it.
  • Cursor is opaque, versioned, and carries a sort/filter signature.
  • Response envelope includes next_cursor and has_more; the extra row is fetched and dropped.
  • Stale or mismatched cursors return a documented 400 in application/problem+json.
  • Pagination is documented with request and response examples that match reality, a point Postman's guide makes about keeping documentation executable Postman's REST best practices.
  • A migration path exists from any page-based parameters, with logging to see who has not moved.

The insight most first search results miss is that the choice is reversible only if you make the cursor opaque before anyone depends on its contents. Decide the storage mechanics later; commit to the interface now.

FAQ

FAQ

Can I use keyset pagination if users need to jump to a specific page?

Not directly, because keyset has no notion of page numbers. You can approximate it by resolving a page number to a position with a bounded COUNT(*) WHERE sort_key < ... query, caching the result, and accepting that the mapping drifts as data changes. If page jumping is a hard product requirement, offset or a hybrid endpoint is the simpler answer.

What happens if a client holds a cursor for hours?

It still works, as long as the sort signature matches and the underlying rows have not been deleted. It may not see the most recent items, since it resumes from a fixed position and walks forward from there. If you need a stable snapshot across a long session, add a temporal or point-in-time marker to the cursor, the pattern AWS describes for DSQL the AWS Database Blog.

How do I keep the total count without paying for `COUNT(*)` every request?

Cache it with a short time to live and label it an estimate, or compute it only when a client explicitly asks. Some APIs drop totals entirely when they move to cursors, which removes one of the most expensive query patterns on a large table Contentful. Either choice is fine as long as the response shape tells clients the number may lag.

Is keyset pagination safe when the sort column changes?

It is safe if you treat the sort as part of the cursor's identity. Encode a signature of the sort order and filters in the cursor, compare it on every request, and reject mismatches with a 400 rather than returning rows from the wrong ordering. This converts a silent correctness bug into a visible, debuggable error the Medium keyset guide.

Which pattern should an internal admin dashboard use?

If the table is small and mostly static, offset is simpler and gives the page-number navigation admins expect. Gusto frames offset as well suited to admin dashboards and small datasets under roughly 10,000 records Gusto. Once the table grows or admins start deep-scrolling activity logs, add a cursor endpoint rather than bending the page-based one.

Sources

Sources

  1. A Developer's Guide to API Pagination: Offset vs. Cursor-Based
  2. API Pagination Guide: Cursor vs Offset vs Keyset for High ...
  3. Keyset + filters + sort orders without losing consistency
  4. Pagination patterns in Amazon Aurora DSQL
  5. Why Contentful is moving to cursor-based pagination
  6. RFC 9457: Problem Details for HTTP APIs
  7. Error Responses :: Spring Framework
  8. What is API versioning? Benefits, types & best practices | Postman
  9. Versioning Best Practices in REST API Design - Speakeasy
  10. What Is API Versioning? - Akamai
  11. API Versioning: Strategies & Best Practices - xMatters
  12. Best practices for REST API design - The Stack Overflow Blog
  13. Best practices for RESTful web API design - Azure - Microsoft Learn
  14. REST API Best Practices: A Developer's Guide to Building ...
About the author

About the author

Antonio Evans
Antonio Evans

Antonio Evans is the founder of Quanta Intelligence and a fractional CTO who builds HIPAA-ready AI systems for health and life-science companies. Before that he was technical co-founder of FriendsEAT for twenty years, CEO of Socialdraft, and a data engineer at IBM. Antonio lives with his dog Santino in Lisbon, Portugal.

All articles