Development

Restoring Production Data into Staging Without Leaking It

Antonio Evans9 min read

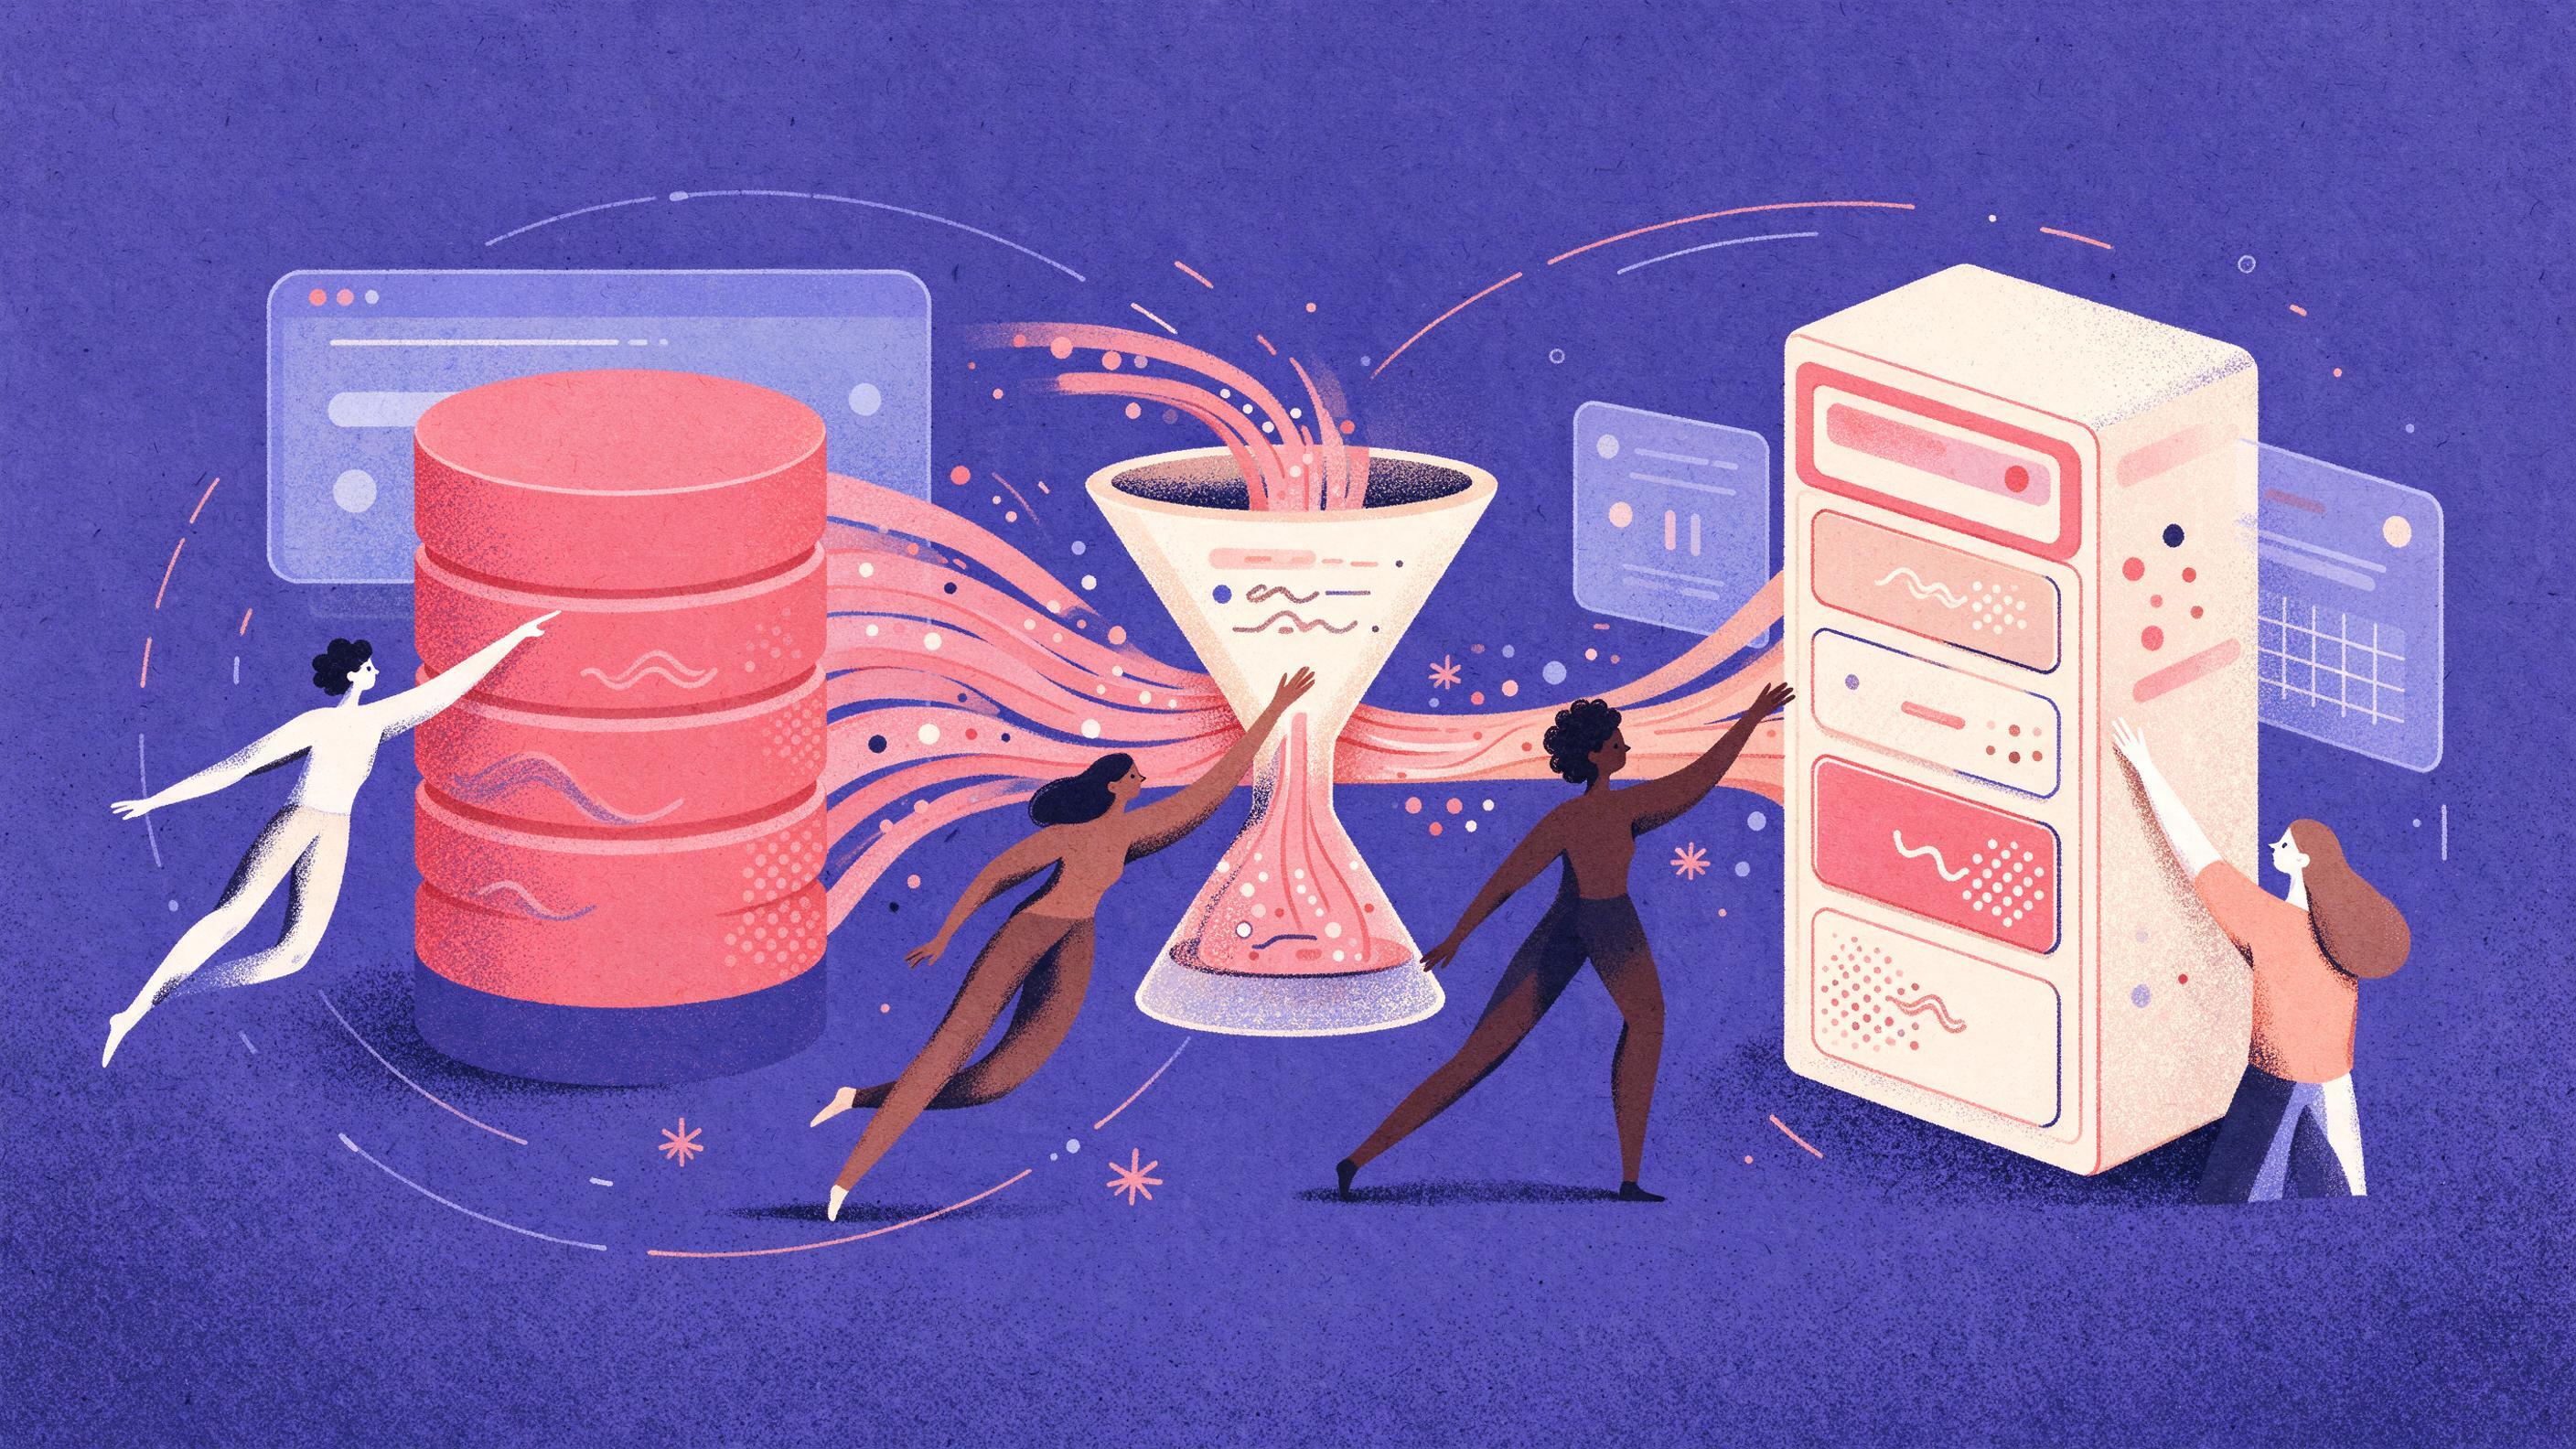
A split scene: on the left, a production database cylinder with a stream of data flowing through a funnel labeled Anonymize and Subset; on the right, a staging server receiving the processed data.
Key points

Key points

  1. 1Anonymize at restore time, not after the fact, so raw production rows never sit on staging disks.
  2. 2Use deterministic transforms (keyed hashes, format-preserving encryption, or a shared pseudonym map) so the same customer ID maps to the same value in every table.
  3. 3Subset rows by foreign-key closure from a small seed set, not by table-by-table row counts, so joins still work.
  4. 4Verification queries are the actual control: a restore that cannot prove zero raw PII remains is a failed restore.

Why staging needs production shapes, not production values

Staging exists to catch integration, performance and sign-off problems before they reach real users, and teams are advised to keep it as close to production as possible: same configurations, same backing services, same volume and variety of data the Northflank staging guide. The Twelve-Factor method makes the same point from the other direction: development, staging and production should use the same type and version of each backing service, because small incompatibilities cause code that passed tests to fail in production the 12factor dev/prod parity chapter.

That argument is about the engine, not the rows. What staging actually needs from data is shape: realistic cardinality, real null and encoding distributions, real cross-table correlations. Synthetic generators such as Faker.js produce plausible names and emails but miss the quirks that cause incidents, including internationalized names, legacy encoding issues and correlations between fields the Xata anonymization write-up. The same piece cites a data point worth internalizing: research from the Technical University of Munich found PostgreSQL cardinality estimates off by 10x or more in 16% of single-join queries and 52% of three-join queries, because real data is correlated and non-uniform Xata, citing the VLDB paper.

So the goal is a restore that keeps distribution and relationships and drops identity. The rest of this article is that procedure, in three phases, with the verification queries that close it out.

Phase 1: Anonymize in place during the restore

The decision that prevents most leaks is where the transform runs. Option A is restore then mask: fast to write, but raw rows existed in staging, in backups, in query logs and in whatever developer ran a SELECT * at the wrong moment. Option B is transform during the dump or load, at the platform or loader layer, so raw values never land. The Xata article makes the case that the most effective anonymization happens at the platform layer during replication Xata.

Pick a transform per column class

Column classTransformWhyWatch out for
Primary and foreign keysFormat-preserving encryption (FF1/FF3-1) or a keyed permutationSame input yields same output, so joins and uniqueness survivePreserve type, width and uniqueness; never use plain RANDOM()
Emails, names, phones, addressesConsistent pseudonym map, generated per schemaKeeps cardinality and uniqueness, reads naturally in the UIMap must be stable across runs or screenshots and testers disagree
Free text, notes, JSON blobsEntity detection plus redaction, then a pseudonym swapPII hides in untyped fieldsScanners miss what they have no pattern for
High-cardinality SHA hashesSHA-256 with a secret saltIrreversible and repeatableUnsalted raw hashes of phone numbers are reversible by brute force
Numbers that must "look real" (SSN, card, account)Format-preserving encryptionOutput passes length and format validationDiscard the key after the restore, or keep it in a separate vault
Analytics-only columnsGeneralize (age bands, postcode prefix)Reduces re-identification riskOver-generalizing destroys test value

Format-preserving encryption is the right tool when downstream systems validate shape: an SSN like 123-45-6789 can become 529-38-1746, a valid-looking value that meets length and format rules but reveals nothing about the original, and FPE stays deterministic so referential integrity holds across tables the Tonic FPE guide. The same guide notes FPE is standardized in NIST algorithms FF1 and FF3-1.

Keep determinism or lose your joins

The single most common mistake is masking with a random function. If customers.id = 123 becomes 456 in one table and 719 in another, foreign keys break and the environment is unusable for testing. The fix is a secret-salted hash (SHA-3 or SHA-256) applied identically everywhere the value appears Xata. A small, boring implementation:

-- Deterministic, salted pseudonym for a stable business key.
-- Replace the salt literal with a secret injected by the loader.
SELECT id,
       'cust_' || substr(encode(hmac(id::text, 'REPLACE_WITH_SECRET', 'sha256'), 'hex'), 1, 12) AS anon_id
FROM customers;

Two rules make this safe in practice. First, the salt is a secret that is never committed and is rotated by re-running the restore, not by editing rows. Second, pseudonyms are generated as a map table during the dump, so a reviewer can diff the map (counts, collisions) without seeing values.

Context preservation

Do not null everything. Nulls break validation logic and hide bugs that real data would catch. Preserve formats while obfuscating content, keep domains for email testing, keep last-four digits on card numbers and keep phone area codes where locality matters Xata. For free text, run entity detection first and log what it found per table, so the verification phase has something to compare against.

Phase 2: Subset rows with foreign-key closure

Most teams try to subset by taking the top N rows per table. That produces orphaned children and broken joins. The workable rule is closure: pick a small seed set, then pull in every row reachable through declared relationships until no new rows appear.

Greenmask's subset feature describes exactly this: a subset_conds filter on a table, after which the tool generates queries from the introspected schema using joins and recursive queries to include all related rows needed to maintain integrity the Greenmask database subset docs. The same page covers three cases that break naive scripts:

  • References without NOT NULL become LEFT JOIN conditions automatically, so null children are not dropped Greenmask.
  • Circular references are resolved with recursive queries, and rows that fail the condition are excluded along with their parents to avoid constraint violations Greenmask.
  • When foreign keys were dropped for performance or live inside JSON, you declare virtual references so the subset engine still sees the relationship Greenmask.

A seed rule that keeps tests meaningful

Pick the seed set by activity, not by size. A concrete recipe:

  1. Select the 5,000 most recently active accounts (by last login or last order) plus 500 accounts older than two years, to keep the "signed up years ago versus yesterday" mix that synthetic data misses Xata.
  2. Include 100 accounts with zero orders and 100 with high order counts, so empty states and list pagination get exercised.
  3. Expand to every order, line item, payment, address and support ticket that references those accounts.
  4. Expand back to lookup and reference tables completely, because they are small and half of the broken joins in staging come from a partially loaded lookup table, the same lookup-versus-fact mismatch discussed in this normalization question this Stack Overflow thread on staging tables and lookup keys.
  5. Freeze the seed list in version control as IDs, so the environment is reproducible and reviewers can reason about coverage.

Sizing this way usually lands between 2% and 10% of production rows on the transactional tables while keeping 100% of lookup and reference data. That is enough volume for realistic plans and enough variety for tests, without copying years of history.

Phase 3: Verify before anyone gets access

Verification is where the procedure earns trust. Run it as an automated job in the restore pipeline, and fail the restore if any check returns a row. Three families of checks cover most leaks.

Check 1: unmasked columns

Build a manifest of tables and columns classified as sensitive, then assert that each one conforms to its declared transform output. Concretely: sensitive emails must not match the domain set of real users, phone columns must not match the production pattern, and free-text columns must not contain any string from a denylist of known PII samples.

-- Any row here is a failed restore.
SELECT 'customers.email' AS column_name, count(*) AS suspect_rows
FROM customers
WHERE email LIKE '%@your-real-domain.com'
UNION ALL
SELECT 'customers.phone', count(*)
FROM customers
WHERE phone ~ '^\+1-\d{3}-\d{3}-\d{4}$'  -- real customers came in unformatted
UNION ALL
SELECT 'customers.address', count(*)
FROM customers
WHERE address IS NOT NULL
  AND address = original_address;  -- column kept by mistake in a join

The UNION ALL form lets one job report every failure instead of stopping at the first, which is what you want when a restore goes wrong at 2 a.m. PostgreSQL's constraint machinery can enforce the same idea going forward: you can add CHECK constraints that reject values in a known-real set, so a future load fails rather than silently shipping PII the PostgreSQL constraints documentation.

Check 2: cross-table re-identification

Anonymization that is correct per column can still leak across columns. Two rows with the same date of birth, postcode and signed-up date are effectively one person. The test is cardinality: if the number of distinct (birth date, postcode, signup month) combinations is close to the row count, your environment is re-identifiable.

SELECT
  count(*)                                                  AS rows_total,
  count(DISTINCT (date_of_birth, postcode_prefix, date_trunc('month', created_at))) AS quasi_id_combos
FROM customers;

A healthy ratio keeps quasi_id_combos well below rows_total. When the ratio is near 1.0, coarsen one field (postcode to a prefix, birth date to a month) and rerun. This is a judgment call, not a compliance test, but it catches the class of mistake that survives a column-by-column review.

Check 3: broken joins and integrity

Foreign keys are the database's own referee: every value in a referencing column must appear in the referenced column, and NOT NULL references reject the row outright the PostgreSQL constraints documentation. So the strongest check is to restore with constraints enabled and see whether the load succeeds. When constraints were disabled for speed, run an orphan query against each declared relationship:

SELECT 'orders.customer_id' AS fk, count(*) AS orphans
FROM orders o
LEFT JOIN customers c ON c.id = o.customer_id
WHERE c.id IS NULL
UNION ALL
SELECT 'order_items.order_id', count(*)
FROM order_items i
LEFT JOIN orders o ON o.id = i.order_id
WHERE o.id IS NULL;

Expect zero rows. A non-zero result means the subset expansion missed a path, or an anonymization transform changed a key in one table but not the other. If constraints are enabled, a failed restore is actually the better outcome, because it stops the pipeline before anyone opens a client.

Ship a restore report

Publish a short report per restore: row counts per table (production versus staging), the subset seed range, transform versions and salts by name only, and the pass or fail line for each of the three checks. Reviewers can then sign off on facts instead of trust. Feature flags can also let testers exercise specific flows on a small, known subset of the staging data without needing identical data for every persona, which further shrinks the surface the Datadog feature flag overview.

Common leaks the checks above actually catch

The hop-by-hop leaks are rarely in the table everyone talks about:

LeakWhere it hidesCheck that catches it
Unmasked free textSupport notes, comments, JSON metadataDenylist scan on sensitive text columns
Raw polygon or address in a joined viewA view defined before masking rolloutManifest includes views, not just tables
Verbose query logsThe loader and application logsLog redaction review plus access audit
Screenshots and exportsTesters, stakeholders, exported CSVsRestore report plus a staging password gate
Re-identification by combinationSeemingly harmless quasi-identifiersCardinality ratio query
Orphan rows from a partial lookup loadReference tables loaded halfwayOrphan query per foreign key
The key that decryptsCI variables copied from productionKey stored outside staging, rotated per restore

Two of these deserve emphasis. First, staging is often protected only by a password and a no-index tag, which is a reasonable minimum but not a substitute for masked data the Marker.io staging guide. Second, log redaction is part of anonymization: if the loader logs row payloads, you have unmasked data sitting in an observability tool that may retain it for a long time. Teams that already mirror production monitoring in staging should apply the same configuration discipline to log fields the Statsig staging best practices.

Testing this procedure on a schedule

A procedure that only runs once is a snapshot, not a control. Run the restore on a schedule (weekly is common) and treat the anonymization manifest and subset seeds as code under review. Preview and per-pull-request environments raise the frequency, so the same pipeline should be able to produce a small masked dataset on demand; the mechanics of spinning up an isolated environment per pull request and tearing it down on merge are well documented for Argo CD setups the Octopus preview environments guide.

The performance of the procedure matters too. A deduplicated load and salted hashing will not be your bottleneck; the subset expansion queries will be, and adding indexes on the foreign-key columns used for closure is usually the whole fix. That is the same reason real data beats benchmarks: plans and estimates depend on distributions, so time the restore against the subset and keep it under your CI budget Xata.

For teams that want a dedicated environment without hand-building the pipeline, provisioning through a platform is a legitimate shortcut: it handles environment creation, secrets and teardown so the work stays focused on the mask and subset rules the Northflank preview platform comparison. If your next step is an assistant that can draft the mask manifest and the verification queries from your schema, a general model endpoint is useful there: Quanta Inference gives you text, image, video, audio and embedding models through one API key, with OpenAI-compatible calls at https://quantaintelligence.ai/inference. Keep it advisory: the queries still get reviewed and run by your pipeline.

FAQ

FAQ

Can I skip subsetting and mask the full database?

You can, but you pay for it in restore time, storage and blast radius. Full-copy masking means every raw row still crossed into staging before the transform ran, and every tester can still see realistic patterns that may be re-identifiable in combination. Subsetting to the recent-plus-old seed set keeps test value and cuts the dataset to a fraction of production.

Is hashing enough to anonymize emails and phone numbers?

Not on its own. An unsalted hash of a phone number or email is reversible by brute force because the input space is small. Use a secret salt with SHA-256 or SHA-3, keep the salt outside the staging environment, and rotate it by re-running the restore. Since the output is deterministic, joins and uniqueness still hold across tables.

Should element IDs in JSON columns be masked too?

Yes. PII hides in untyped fields, and foreign keys that live inside JSON cannot be enforced by PostgreSQL, so a normal foreign key will not protect them. Greenmask's virtual references exist for this case: you declare the referenced table and columns, including a JSON expression, and the subset engine treats it like a relationship Greenmask.

How many rows should staging get?

Aim for the smallest set that reproduces the distributions your tests depend on. A recent-activity seed plus deliberately chosen outliers usually lands between 2% and 10% of transactional rows, with 100% of small lookup tables. Then check the cardinality ratio and the orphan query: if the joins hold and the quasi-identifier ratio is low, the size is defensible.

What does a failed restore look like in the pipeline?

It should look the same as a failed build. The verification step runs after load, returns rows from any check, and exits non-zero. With constraints enabled, most subsetting mistakes fail earlier at load time. Either way, no engineer gets credentials until the restore report shows zero on every check.

Sources

Sources

  1. What is a staging environment? (and how to set one up) | Blog - Northflank
  2. X. Dev/prod parity - The Twelve-Factor App
  3. Anonymization: The Missing Link in Dev Workflows
  4. Real-World Applications of Format-Preserving Encryption
  5. Database subset
  6. Normalize PostgreSQL staging table to existing Foreign ...
  7. Documentation: 18: 5.5. Constraints
  8. What are Feature Flags and How Are They Implemented? - Datadog
  9. What is a Staging Environment? Guide & Best Practices - Marker.io
  10. Staging environment best practices for product teams - Statsig
  11. Create Temporary Argo CD Preview Environments Based On Pull ...
  12. 10 best preview environment platforms in 2026 (frontend ...
About the author

About the author

Antonio Evans
Antonio Evans

Antonio Evans is the founder of Quanta Intelligence and a fractional CTO who builds HIPAA-ready AI systems for health and life-science companies. Before that he was technical co-founder of FriendsEAT for twenty years, CEO of Socialdraft, and a data engineer at IBM. Antonio lives with his dog Santino in Lisbon, Portugal.

All articles