Leadership

Routing Between a Cheap First Pass and an Expensive Second Look

Antonio Evans11 min read

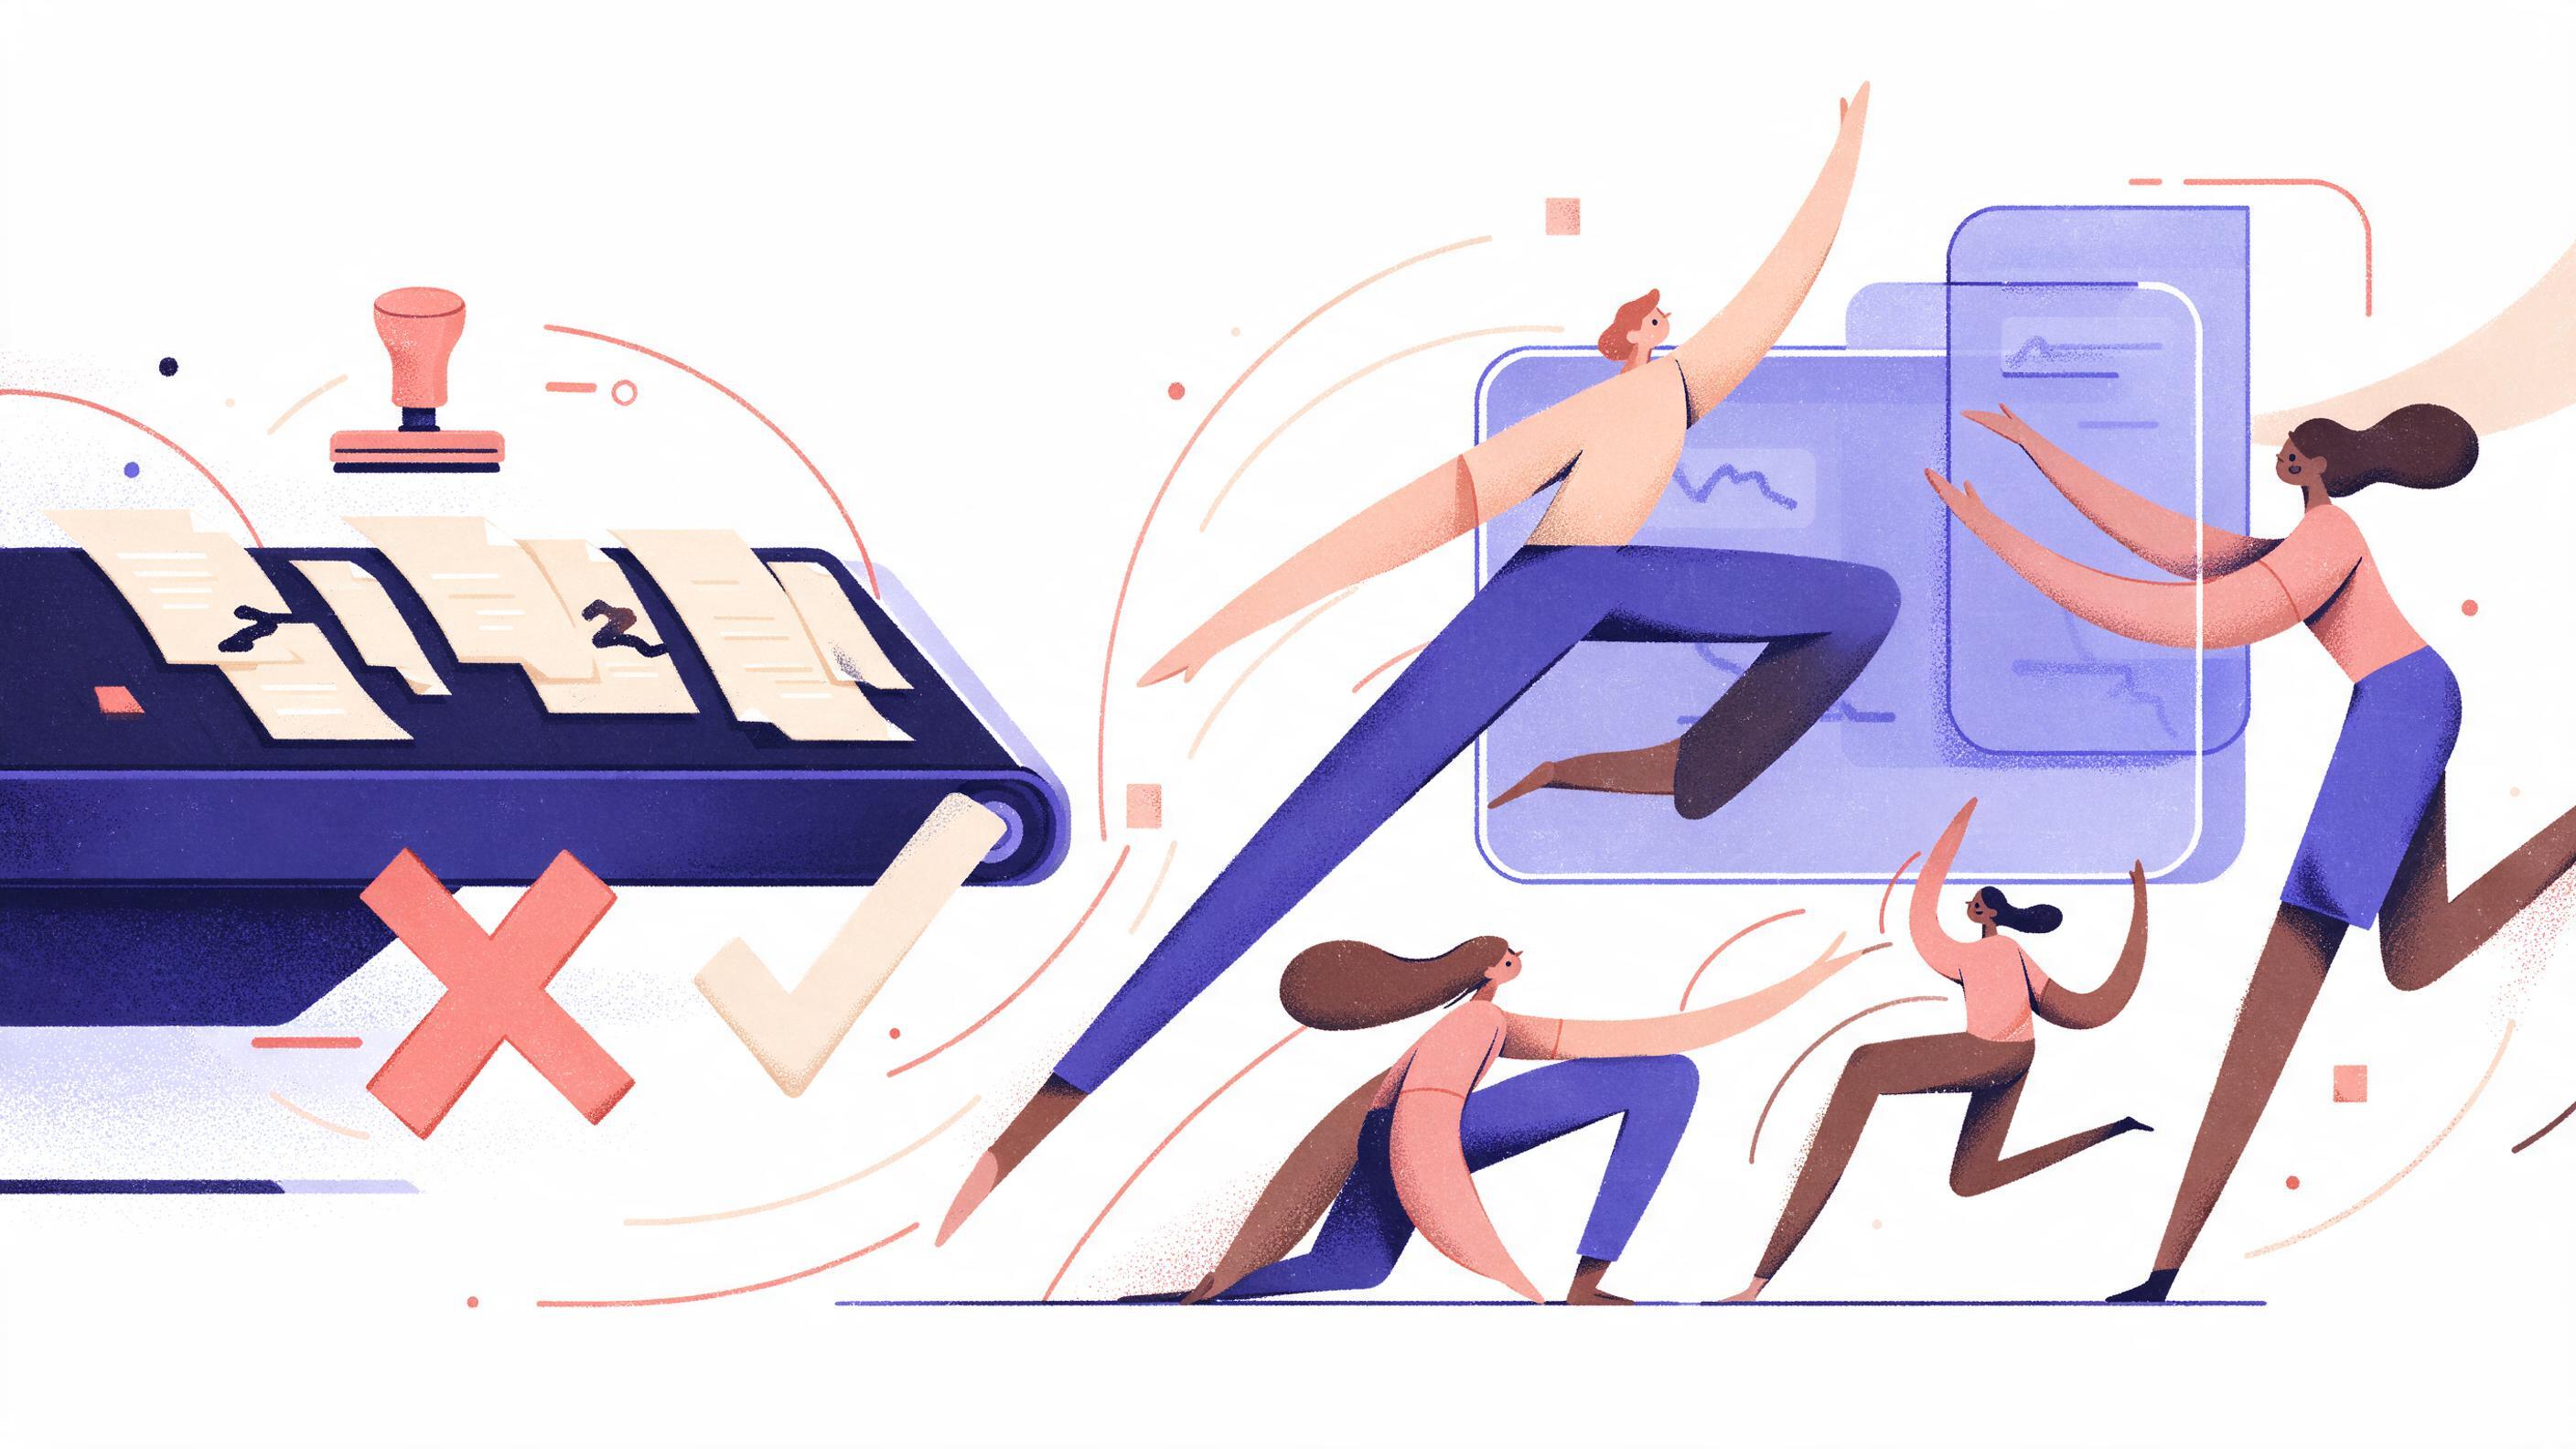
A split scene: on the left, a conveyor belt of documents passes a small stamp labeled 'first pass' with a green check or red X; on the right.
Key points

Key points

  1. 1Grade every output when a missed error is expensive or the error rate is still unknown, and sample only when the rate is stable and grading every call would blow the budget.
  2. 2Set the routing threshold from a small labeled set by picking the score that hits your precision target for "bad" outputs, then send only scores near that line to the expensive second look.
  3. 3A cheap first-pass grader that filters 90 percent of traffic is usually cheaper than an expensive grader on all traffic, even after you pay for both.
  4. 4Sampling misses rare errors and hides drift, so pair any sampled regime with a scheduled full audit and a monitor on the sampled error rate.

The decision that sets your bill

A grader is a model call. Every output you grade costs tokens, adds latency and creates a score someone has to store, chart and eventually trust. The question is not whether to use an LLM judge, because judges now do most of the work that human review used to carry. It is how often the grader runs, and on what.

There are really two graders in most systems, and they have very different prices. The first pass is cheap: a small model, a short rubric, sometimes a deterministic check in front of it. The second look is expensive: a stronger model, a longer rubric, retrieved reference material, or a human. Routing is the logic that decides which outputs get the cheap pass, which get the expensive one, and which get skipped.

The trap is treating this as a binary. Teams either grade 100 percent of traffic with the expensive judge (and then quietly turn it down or off when the invoice lands) or they sample 2 percent (and then find out about a regression three weeks late). The useful middle is a cheap first pass on everything, a threshold that sends only suspicious scores to the expensive judge, and an audit loop that keeps the threshold honest.

LLM-as-a-judge is popular for a reason: it replaces slow, subjective human review with a prompt and an API call, and it handles open-ended text where exact-match metrics fail. Evidently's guide to LLM judges makes the case that judging generated text is tricky precisely because there are many ways to be right. That flexibility is what makes a cheap judge viable, and also what makes it worth calibrating before you trust it.

Grade everything, or sample?

The short answer: grade everything when the cost of a missed error is high, or when you do not yet know the error rate. Sample when the error rate is stable and the cost of grading every call is prohibitive.

That is a decision rule, so let's make it a checklist you can actually run.

SituationDefaultWhy
Regulated, financial or medical outputGrade every output with the expensive judge, cheap pre-filter optionalA missed error has legal or safety consequences
New prompt, model or retrieval change just shippedGrade every output for a burn-in windowThe error rate is unknown and probably moving
Stable, high-volume, low-severity (tone, formatting, length)Cheap judge on all, expensive judge on a threshold bandThe cost of a miss is small and the rate is known
Agent that takes multi-step actions with side effectsGrade every step or every action, not just the final answerFinal-outcome-only grading hides how the agent got there
Costly expensive judge and a tight budgetSample plus a cheap first pass on all trafficYou get coverage on the cheap signal and depth on the suspicious slice

The last row matters more than it looks. A cheap judge on 100 percent of traffic plus an expensive judge on 10 percent costs about a tenth of the expensive judge on everything, assuming the cheap judge is roughly an order of magnitude cheaper per call. You should measure that ratio on your own provider rather than assume it.

There is a literature on spending a fixed query budget well. A 2026 paper on efficient evaluation of LLM performance with statistical guarantees casts benchmarking as finite-population inference and reports up to 5x effective sample size gains over strong baselines by choosing which questions to ask adaptively. That is a research result on benchmark suites, not a production guarantee, but the shape of the idea applies: not all items in a sample are equally informative, and a good selection policy beats uniform sampling at the same spend.

The mirror-image warning also applies. Uniform sampling at 1 percent will, on a 10,000-request day, grade about 100 outputs. If your true error rate is 0.5 percent, you expect roughly half an error in the sample. You will conclude "no errors" on most days. That is not a measurement. That is a coin flip pretending to be a dashboard.

What a threshold actually is

A threshold is a number on the grader's score scale that separates "probably fine" from "look closer." Most judge implementations return a score you can route on. Promptfoo's llm-rubric assertion, for example, asks the model for JSON with a score from 0.0 to 1.0, a pass boolean and a reason, and you can write the rubric so the score is meaningful rather than a vibe. Promptfoo's llm-rubric documentation shows the shape of that output and how to override the grader model with a cheaper one.

Two design choices follow immediately.

First, decide what "bad" means operationally. A threshold is only useful if the score monotonic: higher means better, or higher means worse, consistently. Arize's guide to LLM-as-a-judge evaluators puts it plainly: start with the failure you need to catch, use code for deterministic checks and a judge only where the evaluation requires interpreting meaning. If the failure is "the response cites a refund window that contradicts the document," that is a judge job. If it is "the response is longer than 400 characters," that is a regex, and you should not pay a model to do it.

Second, decide the routing band, not just a line. With a threshold at 0.6, three policies are available:

  • Route scores below 0.6 to the expensive judge and drop the rest. Highest recall on bad outputs, cheapest, but a bad output scored 0.62 slips through.
  • Route a band, say 0.4 to 0.8, to the expensive judge and auto-pass above 0.8. The band buys back the near-misses at a modest cost.
  • Route everything below 0.8 and auto-pass the top. This is close to grading everything once the expensive judge is in play, so check whether the cheap pass is earning its keep.

The band is the insight the first search result usually leaves out. A single threshold optimizes one operating point. A band optimizes cost per caught error, because the errors you actually lose are the near-misses, not the obvious failures the cheap judge already flags.

Setting the threshold from a small labeled set

You need labels, but not many. A few hundred reviewed examples is usually enough to place a threshold, because you are estimating one operating point, not building a classifier from scratch. Label them by hand or with your expensive judge plus human spot-checks, then compute the trade-off at every candidate cut point.

The tools are standard. scikit-learn's precision-recall example defines precision as true positives over true positives plus false positives, and recall as true positives over true positives plus false negatives. When "bad" is the rare class, which it almost always is, precision-recall curves are more informative than ROC curves, for the reason that page gives: class imbalance is exactly when precision and recall diverge.

Here is the worked example. Take 200 labeled outputs, of which 12 are bad (a 6 percent error rate, chosen to make the arithmetic visible). Run the cheap grader. Suppose the results sort like this:

Cheap grader scoreOutputsBadGood
0.0 to 0.31697
0.3 to 0.622220
0.6 to 0.840139
0.8 to 1.01220122

Now ask what each threshold buys.

  • Cut at 0.3: you route 16 outputs, catch 9 of 12 bad, precision 56 percent. Recall on bad outputs is 75 percent, and you pay the expensive judge on 8 percent of traffic.
  • Cut at 0.6: you route 38 outputs, catch 11 of 12, precision 29 percent, recall 92 percent, expensive judge on 19 percent of traffic.
  • Cut at 0.8: you route 78 outputs, catch 12 of 12, precision 15 percent, recall 100 percent, expensive judge on 39 percent of traffic.

The decision rule falls out of your tolerance. If a bad output that reaches a customer costs you roughly as much as ten wasted expensive grades, cut at 0.6. If it costs about as much as three, cut at 0.8. If your team can absorb a few misses and the expensive judge is the bottleneck, cut at 0.3 and let the band from 0.3 to 0.6 go ungraded.

Be honest about the sample size before you trust these numbers. Twelve bad outputs means one example is 8 points of recall. A threshold placed on that is a starting point, not a settled policy. Recut the threshold whenever you have another few hundred labels, and keep the labeled set from a stable period so you are not fitting to an incident.

There is a second calibration step most teams skip: validate the judge before you route on it. Arize's guide says to compare the judge with reviewed examples, inspect missed failures and keep evaluator versions visible when comparing results. If the cheap judge misses a class of bad output entirely, no threshold saves you, because the score never moves.

For rubrics, a good prompt names the failure, gives the score scale meaning at each point, and asks for a reason. Galtea's guide to judge prompts and rubrics covers templates and best practices; the useful habit is to write the rubric so that a mid score means something specific, like "partially supported by the context," rather than "meh."

The two-model pattern, with code

The standard shape of a routed grader is two calls and one decision. The first call is cheap and runs on everything. The second runs only when the first is unconvinced.

def grade(output, context, cheap_judge, strong_judge,
          route_below=0.8, auto_pass_above=0.95):
    first = cheap_judge(output, context)   # returns {"score": 0.0-1.0, "reason": str}
    if first["score"] >= auto_pass_above:
        return {"label": "pass", "score": first["score"], "stage": "cheap"}
    if first["score"] <= route_below:
        second = strong_judge(output, context)
        label = "fail" if second["score"] < 0.6 else "pass"
        return {"label": label, "score": second["score"], "stage": "strong"}
    # the ambiguous band: still worth the expensive look if misses are costly
    second = strong_judge(output, context)
    return {"label": "fail" if second["score"] < 0.6 else "pass",
            "score": second["score"], "stage": "band"}

Three things to notice.

The two thresholds are not the same number and should not be tuned together. auto_pass_above controls how much traffic you skip entirely, and it is set from your precision target on "bad" outputs, not from a general sense of quality. route_below controls how aggressively you send obvious failures straight to the second look, where the strong judge only confirms.

The second judge has its own threshold, and it should be set separately. The cheap model's 0.8 and the strong model's 0.6 are different scales. Copying one to the other is a common and quiet bug.

Log the stage. Without a stage field you cannot tell whether your measured pass rate reflects the cheap judge's decisions or the strong judge's, and your drift monitor will be measuring a mixture.

If you need one API for the cheap and strong judges plus embeddings for retrieval in the same rubric, Quanta Inference puts text, image, video, audio and embedding models behind one OpenAI-compatible key with prepaid dollar pricing, which keeps the routing arithmetic in one place.

What sampling misses

Sampling has three failure modes, and they are not symmetric.

The first is missed rare errors. A 1 percent sample of 10,000 requests sees about 100 outputs. At a true error rate of 0.5 percent, the expected count in the sample is 0.5, and the probability of seeing zero errors is roughly 61 percent by the Poisson approximation. You will ship for weeks believing you are clean. The errors are not rare in aggregate; they are rare per request and plentiful per month.

The second is biased estimates. A random sample gives you an unbiased estimate of the error rate if the sampling is genuinely random. Sample the easy traffic, or the traffic from one route, or the requests that fit in context, and your estimate is biased in a direction nobody wrote down. The 2026 paper on statistical guarantees for LLM evaluation is careful to frame selection policy and validity separately for exactly this reason: choosing which items to grade is fine as long as the estimator and the confidence interval account for the selection.

The third is delayed drift. A sampled dashboard moves slowly. If your prompt, model version, retrieval index or upstream data shifts and the error rate goes from 1 percent to 4 percent, a 1 percent sample needs a lot of requests to separate that from noise. The result is detection lag measured in days, not minutes, and it is worst for high-severity, low-frequency failures, which are exactly the ones you most want to catch fast.

The mitigation is not more sampling. It is a schedule and a monitor.

  • Run a full audit on a fixed cadence, at a volume large enough that the confidence interval is useful. A few hundred graded outputs per audit period is a reasonable starting point for a high-volume system, and the audit should include a stratified slice of each major traffic segment, not just the biggest one.
  • Monitor the sampled rate with an explicit threshold and an error bar, so an alert fires when the upper bound crosses your target, not when the point estimate does.
  • Keep a golden set of reviewed examples and grade it on every deploy. This is the fast signal that catches a regression before the sampled rate has enough data to move.

Evidently's guide to LLM observability in production treats offline and online evaluation as different jobs, and the split is the right mental model here: the golden set is your offline check, the sampled rate is your online monitor, and the full audit is the reconciliation between them.

Keeping the threshold honest

A threshold is a model artifact. It was fit to a labeled set drawn from a particular period, and it decays. Treat it like any other production parameter: version it, date it, and re-fit it when the population changes.

Judge bias is one reason it decays. Judge models show position bias, the tendency to favor a candidate based on where it appears in the prompt, and it varies significantly across judges and tasks rather than being random noise, according to a systematic study of position bias in LLM-as-a-judge. If your judge is comparing two candidate responses, swap the order and check agreement before you route on the result. A judge that changes its verdict when the answers are swapped is a judge whose score is partly measuring prompt layout.

Judge-to-human agreement is another reason. Confident AI's write-up on LLM-as-a-judge cites the widely reported figure that judges agree with human reviewers about 85 percent of the time, sometimes higher than two humans agree with each other. That number is quoted in the blog post rather than measured there, so treat it as a rough prior for your own calibration, not a property of your rubric. Your agreement rate is the number that matters, and it should be measured on the same labeled set you used for the threshold.

For a broader treatment of how judges are deployed and where they fail, the survey of agent-as-a-judge evaluation is useful: it separates single-model judges from multi-agent debate frameworks and notes that agent-based judging complements rather than replaces human oversight. The survey on LLM-as-a-judge covers the improvement strategies and adversarial robustness results in more detail.

A practical re-fit cadence: recompute the precision-recall table from fresh labels after any model, prompt or retrieval change, and on a routine schedule otherwise. If the new threshold differs from the old one by more than the confidence interval on your sample can explain, something changed that you should name.

If the routing logic spans several teams and you want one shared credit pool, a private library of rubrics and an API key per person rather than one shared key on the billing account, Quanta for Teams is built for that shape of work.

FAQ

FAQ

Should I grade every output or sample?

Grade every output when a missed error is expensive, when the error rate is unknown, or when the output has side effects you cannot reverse. Sample when the rate is stable and the cost of grading everything is prohibitive, and pair the sample with a fixed-cadence full audit so the rare errors you cannot see in the sample still surface.

How many labeled examples do I need to set a threshold?

Enough that the precision and recall at your candidate operating points are not one example wide. A few hundred covers most cases if the bad class is reasonably represented, but if bad outputs are 5 percent of the set, a few hundred labels gives you only about 15 positives, and recall moves in large steps. Label more until the recall estimate stabilizes.

What score should the second look run on?

Only scores in the routing band, plus anything the cheap judge scored obviously bad. The expensive judge exists to resolve ambiguity and to confirm failures; running it on outputs the cheap judge already scored cleanly high is where the bill doubles for little coverage gain. Set its threshold separately from the cheap judge's threshold, because the two scales are not comparable.

Does sampling actually miss rare errors?

Yes, and the arithmetic is unforgiving. At a 1 percent sample and a 0.5 percent true error rate, the expected number of errors in the sample is about 0.5, so most periods show zero. That reads as clean on a dashboard while errors accumulate in the unsampled traffic. Add a golden set and a full audit rather than increasing the sample rate.

How often should I re-fit the threshold?

After every change to the model, prompt, retrieval or upstream data, and on a routine schedule in between. Judge behavior also drifts with prompt layout; swapping candidate order changes verdicts often enough that position bias should be tested before you rely on a comparison-based score. If the re-fitted threshold moves more than your sample's confidence interval can explain, investigate before trusting the new number.

Sources

Sources

  1. LLM-as-a-judge: a complete guide to using LLMs for ...
  2. Efficient Evaluation of LLM Performance with Statistical ...
  3. LLM Rubric
  4. LLM-as-a-Judge: Guide & Pre-built Evaluators
  5. Precision-Recall
  6. LLM as a Judge prompts: templates, rubrics, and best ...
  7. A Systematic Study of Position Bias in LLM-as-a-Judge
  8. LLM-as-a-Judge Simply Explained: The Complete Guide to ...
  9. The Rise of Agent-as-a-Judge Evaluation for LLMs
  10. A survey on LLM-as-a-judge
About the author

About the author

Antonio Evans
Antonio Evans

Antonio Evans is the founder of Quanta Intelligence and a fractional CTO who builds HIPAA-ready AI systems for health and life-science companies. Before that he was technical co-founder of FriendsEAT for twenty years, CEO of Socialdraft, and a data engineer at IBM. Antonio lives with his dog Santino in Lisbon, Portugal.

All articles