
Marketing

Routing Signup Risk Alerts to the Right Reviewer

Antonio Evans11 min read

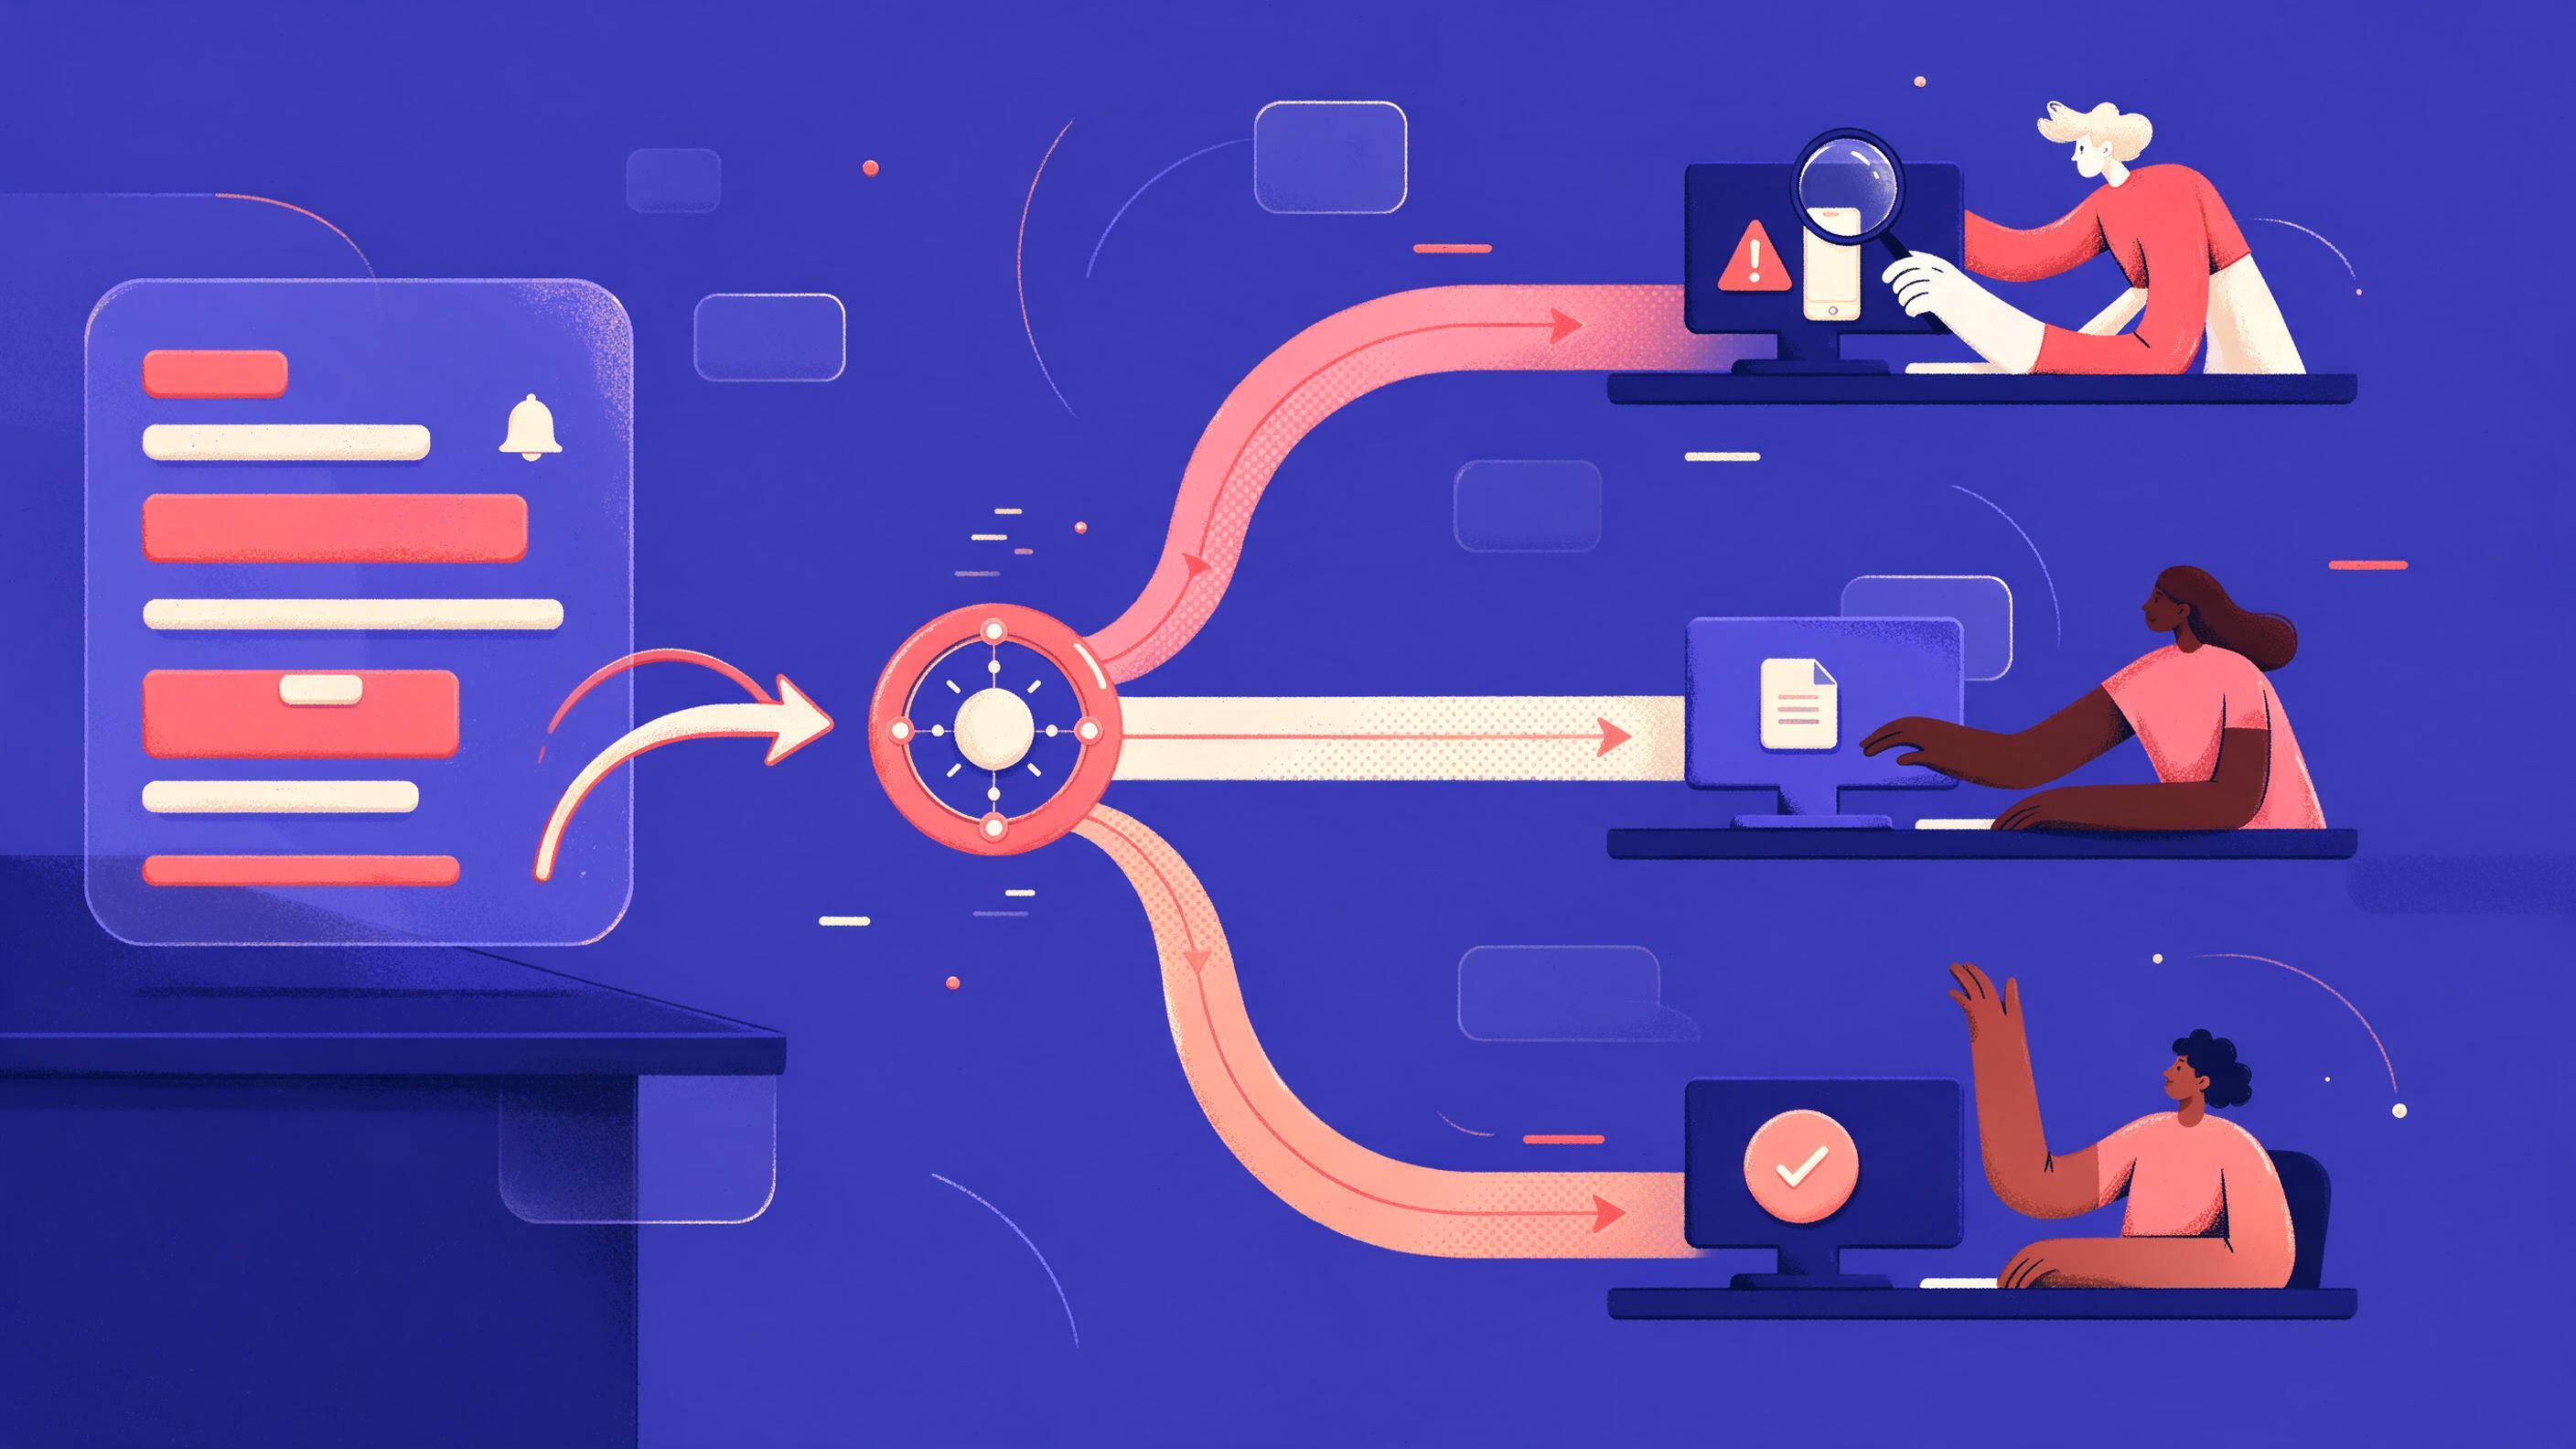
A flat-style diagram of a signup alert arriving at a routing hub, with three labeled lanes leading to different reviewer desks: one desk shows a fraud analyst with a magnifying glass over a phone icon.
Key points

Key points

  1. 1Assign each signup risk alert using a fixed mapping from the signal that fired to the reviewer who owns that skill, then attach the triggering evidence as tags.
  2. 2Reviewers who cannot judge a case reassign it, so routing by skill removes the most common cause of rework in risk queues.
  3. 3Queue rules, not people, should make the first assignment, because rules are auditable and consistent while ad hoc triage drifts under pressure.
  4. 4Manual review only works while the queue clears faster than it fills, so thresholds and aging limits belong in the design from the start.

Why skill-matched routing beats a single shared queue

A shared risk queue looks fair and simple: every alert goes in, whoever is free pulls the next case. In practice it fails in two measurable ways. First, reviewers pull cases they cannot judge, spend time reading, then reassign them, and the case has now consumed two people's attention without moving forward. Second, the reviewer who does have the context returns from lunch to a list of handoffs and a growing backlog.

This is a queue discipline problem before it is a tooling problem. A manual review step only functions as a control while the team's decision capacity keeps pace with the volume of cases routed to it; when volume exceeds capacity, the control degrades into backlog management and risk decisions arrive too late to prevent the action they were meant to gate as this peak-time analysis explains. Any routing design should assume the queue can saturate and should protect the cases that matter most when it does.

There is also a cost argument. Merchants have historically reviewed a large share of orders by hand, and reducing manual review remains a stated goal for a substantial minority of fraud managers according to the MRC data cited by Ravelin, which also notes that manual review is a cost that is often overlooked compared with chargebacks and false positives in Ravelin's analysis. If you are paying for human minutes, you want each minute spent by the person most likely to reach a correct call on first touch.

Rework and handoff are different problems, and it helps to separate them:

Failure modeWhat it looks likeWhat fixes it
Skill mismatchA reviewer opens a case, cannot interpret the signal, reassigns itSignal-to-skill mapping
Context gapThe reviewer can judge the signal but cannot see what triggered itEvidence tags on the case
Ambiguous guidelinesTwo reviewers reach different calls on similar casesWritten decision rules per signal type
Over-routingMost reviewed cases turn out to be good customersThreshold and feature tuning upstream
Queue saturationCases age past the point where a decision still protects anythingAging limits and severity tiers

The distinction between the first two rows matters most. People often describe a routing problem when the real problem is that the case arrived without its evidence. A reviewer who can see the device hash collision, the email domain age and the failed card checks at a glance does not need to chase them through four systems.


Build the signal-to-skill mapping table

Start by listing every signal that can place a signup in review, then name the single skill that best resolves it. Do not name a person; name a skill or specialization, and attach people to skills separately. This keeps the table stable when staff change and makes it reusable across time zones.

Here is a worked mapping you can adapt. The signal column lists what fired; the skill column names who owns the judgment; the evidence column lists the tags that should travel with the case.

Signal typeTypical sourceReviewer skillEvidence tags to attach
Shared device fingerprint across many new accountsDevice intelligenceDevice and multi-accountingDevice hash, count of accounts on device, first-seen date
Emulator, rooted device or automation indicatorsDevice integrity checksDevice and multi-accountingIntegrity flags, OS build anomalies, attestation result
Disposable or high-risk email domainEmail risk scoringIdentity and contact verificationDomain age, domain reputation, MX record status
Syntax-valid but unreachable phonePhone validationIdentity and contact verificationLine type, carrier, reachability status
Card issuer mismatch with stated countryPayment riskPayments and card testingIssuer country, IP country, billing country, attempt count
Velocity spike across linked accountsRules or modelCoordinated abuse and ringsLinked account count, time window, shared attributes
Document or selfie anomaliesIdentity verificationDocument forensicsLiveness score, document type, tamper flags
Edited or reused media in an applicationMedia forensicsDocument forensicsAuthenticity score, metadata, hash history

Two rules keep this table useful. First, each signal maps to exactly one primary skill. If you find yourself wanting to send a signal to two teams, the signal is probably two signals that need splitting. Second, the evidence tags are mandatory, not advisory: a case that arrives without its tags is a case that will be reassigned.

The device row deserves emphasis because device signals are unusually decisive for signup fraud. Device fingerprinting combines hardware, browser and network attributes into a persistent identifier that survives cookie deletion and private browsing, and cross-account link analysis can connect separate profiles operating from the same hardware fingerprint to catch multi-accounting and card testing per Seon's guide. Fraudsters try to evade this by clearing caches, switching browsers, using virtual machines and running emulators, which is exactly why a reviewer who reads those patterns daily will outperform a generalist as Plaid explains. Sumsub's breakdown of canvas, WebGL, audio and TLS techniques is a good reference for what the reviewer is actually looking at in its device fingerprinting guide, and Stytch covers the same ground from an authentication angle in its explainer.

For email and phone signals, the tags do most of the work. A domain age and MX status from an email risk tool tell a verification specialist in seconds what a generalist would spend ten minutes discovering. Abstract's email risk checker documentation shows the categories of signal available, including domain age and reputation, which are cheap to attach as tags at signup time on the tool page.

Write queue assignment rules that use evidence tags

Queue assignment rules in most platforms follow the same shape: a rule set, one or more conditions, and an action that routes the work item to a queue. Oracle's service documentation describes this pattern directly, including the example of routing all requests with a certain product code to one queue or sending high-severity items to a critical queue in its queue assignment rules guide. Salesforce describes the same idea for order management, adding that more specific conditions take priority over less specific ones and that a default queue is effectively a rule with all conditions empty in its queue assignment rules help. Fortinet's SOAR documentation shows the operational prerequisite: queues must exist and be marked queueable before assignments can run against them in its queue management guide.

The insight most teams miss is that rule order is a risk decision. If the first matching rule wins, then the rule you place first is the one that captures the most cases. Put your highest-severity, least-ambiguous signal first, and your catch-all last.

A practical rule set, expressed as pseudo-configuration:

assignment_rules:
  - name: coordinated_ring
    when: evidence_tags contains "ring_cluster" or linked_accounts >= 5
    queue: coordinated-abuse
    sla_minutes: 30
  - name: device_multi_accounting
    when: evidence_tags contains "device_reuse" and accounts_on_device >= 3
    queue: device-review
    sla_minutes: 120
  - name: identity_documents
    when: evidence_tags contains "doc_tamper_flag" or liveness_score < threshold
    queue: document-forensics
    sla_minutes: 240
  - name: contact_quality
    when: evidence_tags contains "disposable_email" or "unreachable_phone"
    queue: contact-verification
    sla_minutes: 480
  - name: default
    when: always
    queue: general-risk
    sla_minutes: 1440

Three design notes on the above. The linked_accounts count comes from link analysis, and reviewers who get those cases need network context, which is why graph-based investigation tooling emphasizes relationship-aware reasoning rather than isolated scores as TigerGraph demonstrates in its fraud investigation session. The SLA minutes are not decoration: they are how you detect saturation before it becomes a service failure. And the default rule must exist, because a case with no matching rule and no default queue simply disappears.

Keep the rules data-driven. Conditions should read from tags the scoring pipeline already emitted, not from free-text fields a human typed. Every rule change should be versioned and reviewed by the queue owners, since a rule that fires too broadly is the most common cause of an unexplained queue spike, a pattern Sardine documents in its explanation of why a rising review queue is usually a threshold or feature problem rather than a staffing one in its manual review overview.

If you want the scoring that emits these tags to run across several model types without separate integrations, an OpenAI-compatible gateway such as Quanta Inference keeps text, image and embedding calls behind one key, which simplifies attaching evidence tags at signup time.

Set thresholds so the queue does not pile up

Thresholds decide how many cases reach the table. Set them too tight and reviewers drown in good customers; set them too loose and real abuse passes. The control variables are few, and they should be watched together: review rate as a share of signups, queue latency against SLA, inter-reviewer agreement on similar cases, and decision accuracy checked against later outcomes such as chargebacks or confirmed abuse per Sardine's list of review metrics.

A worked example makes the arithmetic concrete. Suppose you take 20,000 signups a day and route 4 percent to review, which is 800 cases. If a reviewer clears 40 cases a day, you need 20 reviewer-days per day just to stay level. Now tighten a rule and the rate rises to 5 percent, or 1,000 cases, and you need 25 reviewer-days. The difference of five reviewer-days is the real cost of that threshold change, and it is invisible if you only look at the percentage.

The same logic applies to time. If your SLA is 4 hours and cases arrive evenly across a 24-hour day, you need enough coverage in every window, not just daytime. Weekend coverage is where most queues break, because capacity is fixed while signup volume often is not as the peak-time analysis notes.

Aging limits are the simplest safeguard. Attach a maximum age to each queue tier: 30 minutes for coordinated rings, two hours for device cases, four hours for identity documents, a working day for contact quality. When a case passes its limit, escalate it to the queue owner rather than letting it sit. This turns a silent backlog into a visible exception.

Reviewer throughput also depends on how many systems the reviewer must touch. Reducing the number of interfaces per case is one of the highest-leverage changes available, and linking directly from a data point to its related history saves a few seconds per clue, which compounds across hundreds of cases as the fraud review practice guide explains. If a case needs four tabs, the routing table has failed even if the queue assignment was correct.

Provide recent and historical link analysis in the same view as the case. When a reviewer can click a device hash and see every account and every order attempt attached to it, the case resolution time drops and the reviewer's confidence rises. Link analysis and drill-down tools are named as a top tip for exactly this reason in the same guide on manual review performance.

Choose the right reviewer for the evidence type

Fraud detection work splits by evidence type, and the split is not arbitrary. A payments specialist reads issuer and card-testing patterns fluently but will not know what a canvas hash anomaly implies. A document forensics specialist reads tamper flags and liveness scores but will not spot a mule network.

The following decision rule holds up well in practice. Route by the evidence that would change the decision, not by the signal with the highest score. If the deciding fact is "is this device shared with twelve other accounts," route to device review even if an email signal also fired. If the deciding fact is "is this document altered," route to forensics even if the device is clean. The score tells you the case is worth a look; the evidence type tells you who should look.

For insurance and claims-adjacent signup flows, media evidence adds a category. Deepfake detection examines photos, video, audio and documents before manipulated content changes a decision, and insurers are advised to treat authenticity scoring as investigative triage while trained adjusters and special investigations staff own the final call according to Adaptive Security's insurance guide. That is the same principle: the tool produces a signal with a score, and the routing table sends it to the human whose skill matches the evidence.

Automation can carry more of the load than many teams assume. An agent that runs across the life of a case, rather than scoring once at intake, can keep assembling evidence and summarizing developments so that the human reviewer starts from a prepared file rather than a raw alert. A broader survey of AI agent applications in fraud detection covers how these systems process diverse data sources and reduce false positives in Leewayhertz's overview. The same lesson appears in insurance fraud work, where long-horizon agents assemble investigator-ready referral packets with citations and exhibits instead of producing a one-shot score as Layerup describes. That cuts the context-gathering part of review, which is where much of the handoff cost lives.

One caution: the threat is not static. Research on collaborative LLM agents simulating financial fraud found that malicious agents can adapt to environmental interventions such as content warnings and monitoring, which means your routing table and thresholds need a review cadence, not a one-time build per this arXiv study on colluding agents. Schedule a quarterly review of which signals actually predicted confirmed abuse, and retire the ones that did not.

If your team does not have specialists for every evidence type, that is a legitimate reason to buy expertise rather than train it. Quanta Experts is built around specialists that read your context and hand back finished work, which fits the evidence-tag and case-summary layer of this workflow.

Operate and tune the routing over time

A routing system is a live control, so instrument it. Log every assignment with the rule that fired, the tags present, the reviewer, the time to first action, the time to decision, and whether the case was reassigned. Then report on four numbers weekly.

MetricDefinitionHealthy signalWarning sign
First-touch resolutionShare of cases decided by the reviewer who first opened themHigh and stableFalling means routing is drifting
Reassignment rateShare of cases moved to another reviewerLowRising means skill mismatch or missing tags
Time to first actionMinutes from case creation to first reviewer actionWithin tier SLAOutside SLA means capacity shortfall
Override rateShare of automated suggestions the reviewer reversedModerateVery high or very low suggests threshold miscalibration

Treat a rising reassignment rate as a bug report against your mapping table. Pull twenty reassigned cases, read the tags, and ask which reviewer should have received them and why they did not. In most cases you will find either a missing evidence tag or a rule ordered too late.

Pair this with periodic calibration. Have two reviewers independently decide the same batch of resolved cases and compare calls. Low agreement means the guidelines are unclear, not that one reviewer is wrong, and the fix is a written decision rule per signal type as Sardine notes on inter-analyst agreement. Write those rules in the same place as the mapping table so the two stay in sync.

Finally, close the loop. Every reviewed case is a label. Feed decisions back into the scoring that emits your signals, so that the cases reaching human review become genuinely ambiguous ones rather than a steady stream of easy calls per the same review overview. Over time this shrinks the queue without lowering the bar, which is the only sustainable way to reduce manual review cost.

FAQ

FAQ

What is the difference between a queue assignment rule and an evidence tag?

A queue assignment rule is the logic that chooses a destination queue based on conditions; an evidence tag is a fact attached to the case that those conditions read. The rule decides where the case goes, and the tag explains why. You need both, because a rule with no tags can only route on scores, and a tag with no rule does not move anything.

How many queues should I create?

Start with one queue per skill in your mapping table, plus a default. That is usually four to six queues for a signup risk function. More queues fragment coverage and make staffing harder, while fewer queues recreate the shared-queue problem you are trying to solve.

What should happen when no rule matches a case?

It must land in a default queue with a named owner and an SLA. A case with no matching rule and no default is effectively dropped, and dropped cases are the ones that become confirmed abuse later. Review the default queue weekly to see whether a new rule is needed.

How do I know if my thresholds are too tight?

Watch the composition of the queue rather than its size. If most reviewed cases turn out to be good customers, you are routing too aggressively and burning analyst time on safe traffic as Sardine explains. Tighten the upstream signal rather than adding reviewers.

Can automated agents make the first assignment?

Yes, provided the routing remains rule-based and auditable. Automated preparation of case files, with citations and exhibits attached, shortens the human review step without changing who owns the decision as described for insurance SIU workflows. Keep the assignment rules deterministic even when a model writes the summary.

Sources

Sources

  1. What breaks when manual fraud review is the main control ...
  2. How much is manual review costing your business?
  3. Device Fingerprinting: How It Works for Fraud Detection
  4. How device fingerprinting improves fraud prevention
  5. How Device Fingerprinting Detects and Stops Fraud in 2026
  6. What is device fingerprinting, and how does it work? - Stytch
  7. Free Email Risk Checker: Score Any Address Instantly
  8. How do I set queue assignment rules? - Oracle Help Center
  9. Queue Assignment Rules - Salesforce Help
  10. Defining Queues | FortiSOAR 8.0.0 - Fortinet Document Library
  11. Fraud Investigation with Agentic AI Live Demo Autonomous ...
  12. What Is Manual Review? Stop Queue Growth Before ...
  13. Five Tips for Increasing Speed and Performance with ...
  14. Deepfake Detection Tools for Insurance
  15. AI agents for fraud detection: Applications, benefits and ...
  16. AI Fraud Detection for Insurance & SIU
  17. Financial Fraud Risks by Collaborative LLM Agents on ...
About the author

About the author

Antonio Evans
Antonio Evans

Antonio Evans is the founder of Quanta Intelligence and a fractional CTO who builds HIPAA-ready AI systems for health and life-science companies. Before that he was technical co-founder of FriendsEAT for twenty years, CEO of Socialdraft, and a data engineer at IBM. Antonio lives with his dog Santino in Lisbon, Portugal.

All articles
