AI agents

Subagent Prompts: What the Orchestrator Sends and What Comes Back

Antonio Evans11 min read

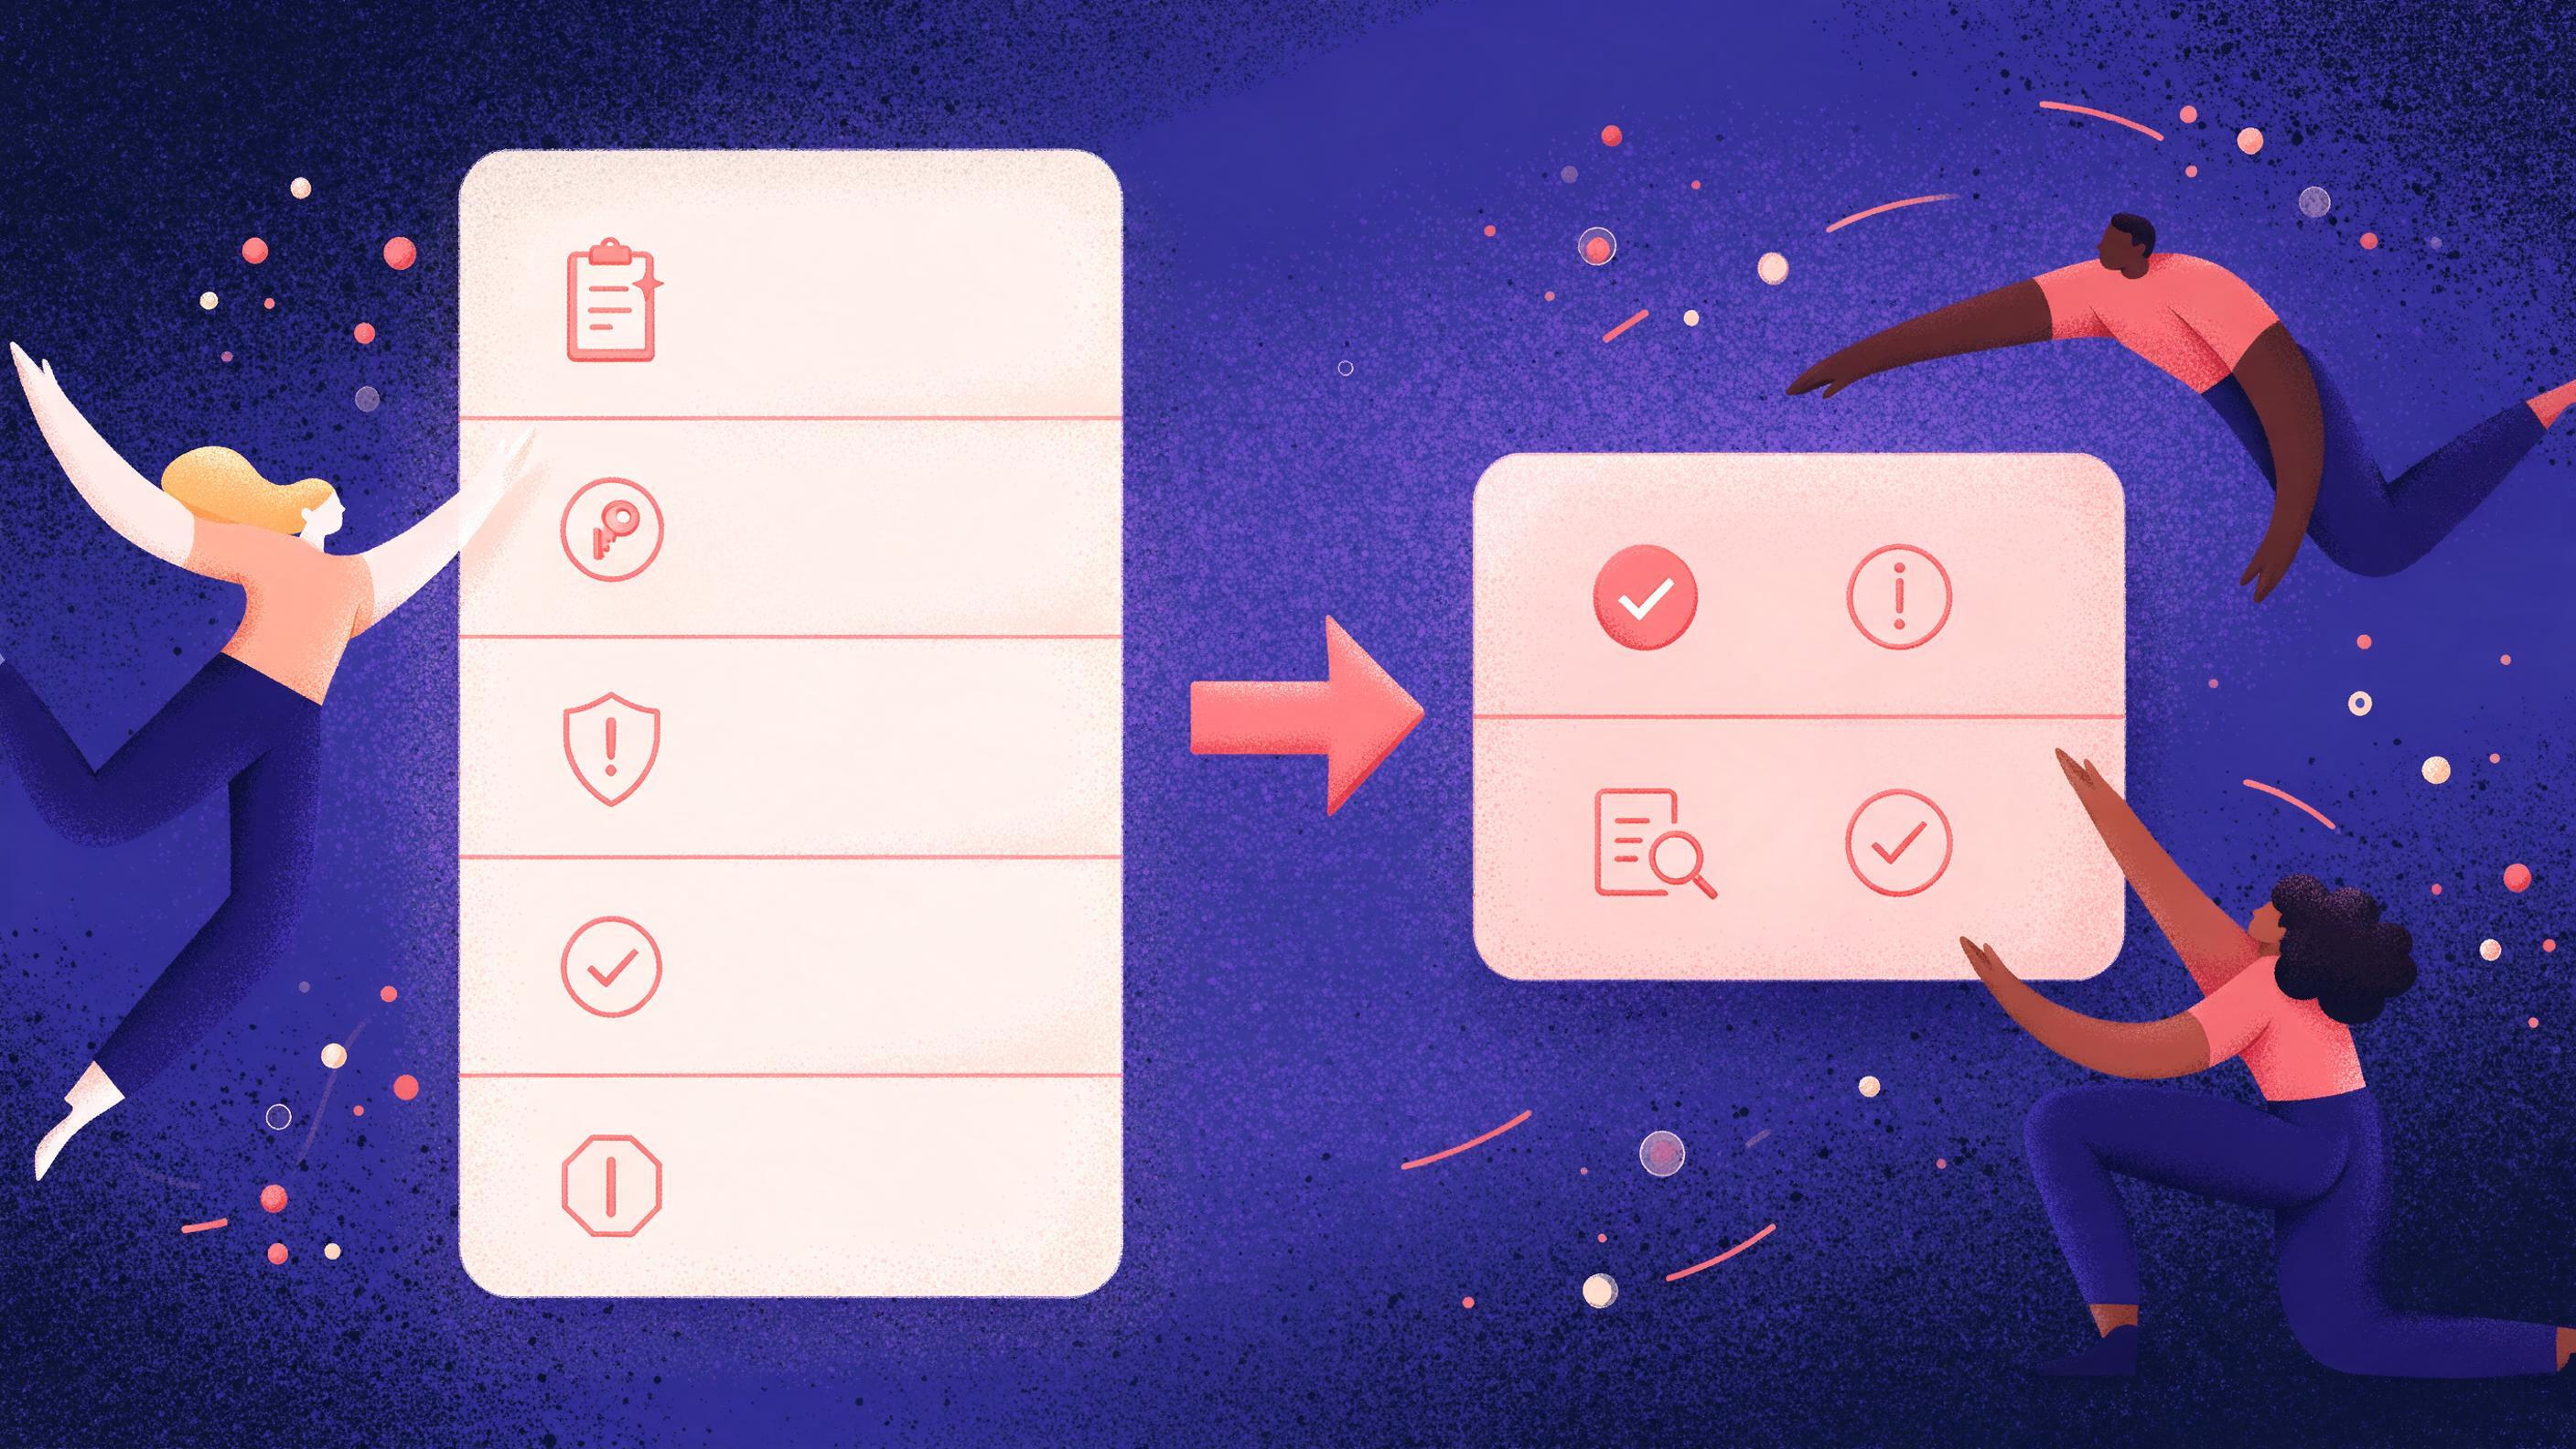
A two-panel flat diagram: an Instruction form on the left with fields for task, inputs, constraints, acceptance criteria and stop conditions, an arrow to a Return form on the right with status, result.
Key points

Key points

  1. 1A subagent prompt has two halves that must be designed together: the brief the orchestrator sends and the contract the subagent returns.
  2. 2The brief names the task, lists exact inputs, states constraints and acceptance criteria, and defines stop conditions.
  3. 3The return contract fixes a schema: status (done, partial, blocked), the result, supporting evidence, and the caller's next action.
  4. 4Most dead-end handoffs come from a missing input field or an unstated accept criterion, not from a weak model.

Why one handoff interface matters more than the whole topology

Most writing about agents argues about the shape of the network: orchestrator-worker, swarm, hierarchy, debate. That debate is real, and the choice changes latency, cost and failure modes. Microsoft's architecture guidance puts coordination overhead, added latency and new failure modes squarely on the multi-agent side, and advises using the lowest level of complexity that meets the requirement the Azure architecture guide. Anthropic, which runs a production orchestrator-worker system, reports that multi-agent setups consume about 15 times the tokens of a chat interaction, and that they suit tasks with heavy parallelization rather than tightly interdependent work such as most coding Anthropic's engineering write-up.

Both facts point at the same engineering surface. If the topology is expensive and only pays off when subtasks are independent, then every subtask must be genuinely self-contained. And self-containment is not a property of the graph. It is a property of the prompt. A subagent with a fresh context window sees only two things: the string the orchestrator wrote, and whatever its own tools return. Everything the parent knows and does not restate is lost.

That is the isolation boundary described in LangChain's survey of multi-agent patterns: in the subagents pattern the supervisor calls workers as tools, workers stay stateless, and all routing passes through the main agent LangChain's architecture guide. The practical implication is that you should design a single, reusable interface, one brief in and one result out, before you design anything else. Get that interface right and topology becomes a scheduling decision. Get it wrong and no amount of routing sophistication rescues you, because the subagent is answering a question you did not actually ask.

The rest of this article is about that interface. It is narrower than the coordination question on purpose: one handoff, described in enough detail to implement today.

The instruction: what the orchestrator sends

A delegation prompt that works has five labeled parts. Label them in the prompt itself, in plain text, because the model reading it is also the model that has to follow it under its own reasoning load.

  1. Task statement: one sentence, imperative, with the deliverable named.
  2. Inputs: the exact material the subagent needs, inline or by pointer, with enough detail that it never has to guess or re-fetch.
  3. Constraints: what must not happen, including tool restrictions, formats, length and scope boundaries.
  4. Acceptance criteria: the checks the caller will run on the returned result.
  5. Stop conditions: when to halt early, and what to do instead of pressing on.

The Claude Code subagent guide states the failure mode bluntly: the only channel from parent to subagent is the prompt string written at delegation, so any file path, error message, branch name or already-made decision has to be in that prompt, because nothing else crosses the boundary the subagent orchestration guide. The same page notes that a subagent can finish without doing something it was clearly asked to do, which is why explicit acceptance criteria belong in the brief rather than in the caller's head.

Inputs are where handoffs die

The most common silent failure is an under-specified input. The subagent does not know it is missing something. It fills the gap with a plausible assumption and returns a confident result built on it.

The fix is to treat inputs like function arguments. Name them, give their types informally, and show a small example. If a path is needed, write the path. If a decision was already made upstream ("we chose the Postgres schema, not the Mongo one"), restate the decision and its reason in one line. If the subagent needs a corpus, either paste the relevant slice or give a retrieval tool and say explicitly what to search for.

A useful test before sending: read the brief as if you had no memory of the conversation. Every pronoun should have an antecedent inside the brief. Every reference to "the file" should name the file. The fresh-context property that makes subagents cheap also makes them literal, and the AOrchestra work on automated sub-agent creation formalizes this as a four-part tuple of instruction, context, tools and model that the orchestrator concretizes at each step the AOrchestra paper.

Constraints and the permission boundary

Constraints do two jobs. Some are content constraints ("quote numbers at four significant figures," "cite only sources from the provided list"). Others are capability constraints: which tools the subagent may use at all. The second kind should be enforced in configuration, not in prose. LangChain's pattern description and the Claude Code guide both describe subagents locked to narrow tool sets, so a research worker cannot edit files and an auditor can read but never write; the boundary is enforced by configuration rather than by hoping the model complies LangChain's architecture guide the subagent orchestration guide. Write the prose constraint anyway, because the model plans around it, but do not rely on it as the only guard.

Microsoft's decision guidance reinforces the point from the governance side: one legitimate reason to split into multiple agents at all is crossing security and compliance boundaries, where separate processing environments limit the blast radius of an incident Microsoft's single vs. multi-agent guidance. If your subagent's tool access is narrower than the parent's, say so in one line so the subagent plans within it instead of burning turns on tools it cannot use.

Stop conditions, including the one people forget

Every brief needs an explicit exit for the case where the task cannot be completed as stated. Without it, subagents do the agentic equivalent of padding: they keep searching, keep retrying, and eventually return something plausible rather than admitting the wall.

Write three stop conditions into the brief:

  • Success: the acceptance criteria are met, return the result.
  • Hard limit: a budget of tool calls, pages read, files opened or minutes elapsed; on hitting it, return what you have with status partial.
  • Blocked: a required input is missing, contradictory or inaccessible; stop immediately and return status blocked with the specific missing item.

The blocked case is the one teams forget, and it is the most valuable. A subagent that reports "customer ID 8841 has no billing record in the provided export, so the duplicate-charge check could not run" gives the orchestrator a decision. A subagent that guesses gives the orchestrator a defect it will discover three steps later. Anthropic's system description notes that agents must operate for many turns and decide which directions to pursue, which is exactly when an unstated exit turns into unbounded wandering Anthropic's engineering write-up.

The return contract: what comes back

The return contract is a schema. Not a formatting preference, a schema with required fields and enumerated values, so the caller can branch on the result without reading prose. Modern APIs will enforce this for you: the OpenAI structured outputs guide describes supplying a JSON Schema so the model always produces responses that adhere to it, with no omitted required key and no invalid enum value, and notes that this removes the need for strongly worded formatting prompts OpenAI's structured outputs guide. The Strands SDK docs show the same pattern at the agent level: define a model, pass it to the invocation, and read the validated object off the result the Strands structured output docs.

Four fields carry almost all the value:

  • status: one of done, partial, blocked. This is the routing signal. It must be honest, which is why the brief's stop conditions define what each value means.
  • result: the payload itself, shaped to the acceptance criteria. For a research subagent, a list of findings each with a claim and a source. For a code subagent, a diff plus the test command that was run.
  • evidence: the receipts. File paths, URLs, line numbers, query strings, test output. This field is what lets the orchestrator spot-check without redoing the work.
  • next_action: one sentence from the subagent about what the caller should do. It is advisory, not authoritative, but it reliably surfaces the cases where the subagent knows the result is shaky.

You can add fields for cost, elapsed time or confidence, but only if the caller actually branches on them. Every required field is a chance for the subagent to produce a technically compliant but useless value, so keep the schema small.

A schema that works in practice

{
  "type": "object",
  "required": ["status", "result", "evidence", "next_action"],
  "additionalProperties": false,
  "properties": {
    "status": { "enum": ["done", "partial", "blocked"] },
    "result": {
      "type": "object",
      "required": ["summary", "findings"],
      "properties": {
        "summary": { "type": "string", "maxLength": 600 },
        "findings": {
          "type": "array",
          "items": {
            "type": "object",
            "required": ["claim", "source"],
            "properties": {
              "claim": { "type": "string" },
              "source": { "type": "string" }
            }
          }
        }
      }
    },
    "evidence": { "type": "array", "items": { "type": "string" } },
    "next_action": { "type": "string", "maxLength": 240 }
  }
}

Two design choices in that schema are worth calling out. First, additionalProperties: false prevents the subagent from burying a caveat in an undeclared field the caller never reads. Second, the maxLength values are load-bearing: they force compression, and compression is the whole reason the subagent exists. Anthropic describes subagents as facilitating compression, condensing the most important tokens from a large exploration into something the lead agent can use Anthropic's engineering write-up. An unbounded summary field defeats that.

Worked example: a billing investigation

Take a support triage orchestrator with three subagents. The billing subagent receives this brief:

Task: Determine whether order 12345 was charged twice. Inputs: order id 12345; customer id 8841; payments export at /data/payments_q3.csv (columns: order_id, customer_id, amount_cents, captured_at, status); refund policy: duplicate captures are refunded in full within 30 days of capture. Constraints: read-only access to /data; do not contact the payment provider; quote amounts in cents; cite the exact rows you used. Acceptance criteria: a duplicate determination with row-level evidence, and the refund amount in cents if a duplicate exists. Stop conditions: if the export has no rows for this order, return blocked with the reason. If you have opened 200 rows and cannot decide, return partial.

A compliant return might read: status done, summary "two captures of 4900 cents on the same order 6 minutes apart, duplicate confirmed, refund of 4900 cents due," evidence naming the two CSV rows, next action "initiate refund and confirm with customer."

Now the counterfactual. If the brief had omitted the refund policy line, a competent subagent might still find the duplicate but return "refund amount unclear, needs policy." The orchestrator burns a round trip. If the brief had omitted the blocked condition, a subagent finding zero rows would likely return status done with an empty findings list, which the caller cannot distinguish from "no duplicate found." That distinction is the difference between a refund and a chargeback.

Comparing weak and strong handoffs

The table below is the checklist to run against an existing subagent definition. Each row is a failure mode with its symptom and its fix.

SignalWeak handoffStrong handoffFix
Inputs"Look at the relevant files"Named paths, columns, ids pasted inlineRead the brief with no memory; resolve every reference
ScopeOpen-ended "research the market"One question with a named deliverableCut to a single answerable question
ConstraintsAbsent or prose-onlyProse plus enforced tool permissionsRestrict tools in config, restate in prompt
AcceptanceImplicit in the caller's headWritten checks the caller will runMove the checks into the brief
ExitsSuccess onlySuccess, budget limit, blockedAdd budget and blocked cases with status values
Return shapeFree-form paragraphValidated schema, enumerated statusEnforce with structured outputs
EvidenceOptional or absentRequired, row or line levelMake it a required field
Next actionAbsentOne sentence, advisoryAdd and use it to flag shaky results

The symptom column matters for diagnosis. A subagent that returns beautifully written paragraphs that the caller cannot parse has a contract problem, not a capability problem. A subagent that returns valid JSON full of wrong answers usually has an inputs problem. A subagent that returns blocked on tasks you know are doable has a constraints problem, usually a tool permission that does not match the brief.

Failure modes and the decision rule

Four failures account for most broken handoffs. Each has a specific repair.

The re-fetch loop. The subagent lacks a path or id and spends its budget searching for it. Repair: paste the identifier. If it changes often, pass it as a parameter in the delegation call so the orchestrator cannot forget.

The optimistic done. The subagent cannot meet the criteria but reports success. Repair: define done as meeting the acceptance criteria, not as finishing the attempt, and add a required evidence field that would be empty if the work was not actually done. The orchestrator should validate the schema and, where cheap, one evidence item.

The context dump. The subagent returns everything it read. Repair: bound the result fields, and state that the orchestrator will not read anything outside the schema.

The platform-error black hole. Concurrent subagents hit rate limits or a model outage. Beam AI's production write-up describes exactly this for fan-out patterns, where each agent is within limits individually but the collective load is not, and recommends planners that cap concurrency Beam AI's orchestration patterns. Repair: treat a transport failure as a fourth status the orchestrator assigns, with a retry policy, so the subagent's blocked keeps its meaning: the work cannot be done, not the call did not complete.

The decision rule that ties this together: sending is cheap, returning is expensive. A thorough brief costs tokens once. A vague return costs the orchestrator a re-read, a re-delegation, or worse, a wrong action taken on bad information. When you are unsure whether to include a detail in the brief, include it. When you are unsure whether to add a field to the return, leave it out unless the caller branches on it. The asymmetry is the whole design principle.

A second rule for sequencing: design the return contract first, then write the brief backwards from it. The schema tells you what the subagent must know to fill it. If a field in the schema cannot be filled from the inputs you were planning to send, you have found the missing input before you burned a run.

Instrumenting the handoff

A handoff you cannot observe is a handoff you cannot fix. The minimum telemetry per delegation is the brief, the raw return, the schema validation result, wall-clock time, tokens in and out, and which branch the orchestrator took on status. Anthropic's own analysis found that token usage alone explained 80 percent of performance variance on a browsing benchmark, with tool-call count and model choice accounting for the rest, which is a strong argument for logging consumption per subagent rather than per session Anthropic's engineering write-up.

For teams running several subagents, the practical move is a small evaluation set of handoffs: ten to twenty briefs paired with the return you would accept. Replay them whenever you change the brief, the schema or the model. The Arize comparison of orchestrator-worker frameworks lists seamless handoffs, error handling and context propagation among the recurring engineering challenges across frameworks, which suggests you should measure these directly rather than assume a framework has solved them Arize's framework comparison.

If you are running subagents across more than one model family, one API key for text, image, video, audio and embedding models removes a class of plumbing work: Quanta Inference (https://quantaintelligence.ai/inference) is OpenAI-compatible and priced in US dollars, so the handoff schema and the logging stay the same when the model behind a subagent changes.

FAQ

FAQ

What is the difference between a subagent prompt and a system prompt?

The system prompt defines the subagent's persistent role, tools and defaults and is written once per agent definition. The delegation prompt is the per-task brief written at call time, and it is the only channel that carries task-specific inputs across the context boundary. Both matter, but the brief is where most handoff failures originate.

Should the return contract be a JSON schema or a Markdown template?

Use a JSON schema when the caller branches programmatically on the result, because schema enforcement eliminates missing keys and invalid values. Use a labeled Markdown template when a human reads the output directly. If both audiences exist, return the schema and render the human-readable view from it.

How do I stop a subagent from returning partial work as done?

Define done as meeting the acceptance criteria rather than as finishing the attempt, require an evidence field that lists the specific rows, files or sources used, and have the orchestrator validate at least one evidence item. A subagent that reports done with no evidence is a signal to reject and retry with a sharper brief.

How much detail should the orchestration brief carry?

Enough that a reader with no memory of the conversation could act on it. Restate paths, ids, prior decisions and the reason for constraints, and paste the relevant slice of any document rather than pointing at a repository. Detail in the brief is cheap; a re-delegation is not.

When should a task not be delegated to a subagent at all?

When the subtasks are not genuinely independent, or when the whole job fits comfortably in one context window. Anthropic reports that multi-agent setups use roughly 15 times the tokens of a chat interaction and suit parallelizable, information-heavy work more than interdependent work such as most coding Anthropic's engineering write-up. Microsoft's guidance makes the same point from the other direction: start at the lowest complexity that reliably meets the requirement the Azure architecture guide.

Sources

Sources

  1. AI Agent Orchestration Patterns - Azure Architecture Center
  2. How we built our multi-agent research system - Anthropic
  3. Choosing the Right Multi-Agent Architecture - LangChain
  4. Claude Code Subagents and Multi-Agent Orchestration ...
  5. AOrchestra: Automating Sub-Agent Creation for ...
  6. Choosing Between Building a Single-Agent System or Multi-Agent ...
  7. Structured model outputs | OpenAI API
  8. Return structured output
  9. 6 Multi-Agent Orchestration Patterns for Production (2026) - Beam AI
  10. Orchestrator-Worker Agents: Comparing Agent Frameworks
About the author

About the author

Antonio Evans
Antonio Evans

Antonio Evans is the founder of Quanta Intelligence and a fractional CTO who builds HIPAA-ready AI systems for health and life-science companies. Before that he was technical co-founder of FriendsEAT for twenty years, CEO of Socialdraft, and a data engineer at IBM. Antonio lives with his dog Santino in Lisbon, Portugal.

All articles