
AI agents

Subagent Tool Scoping: Limiting What a Delegated Task Can Touch

Antonio Evans8 min read

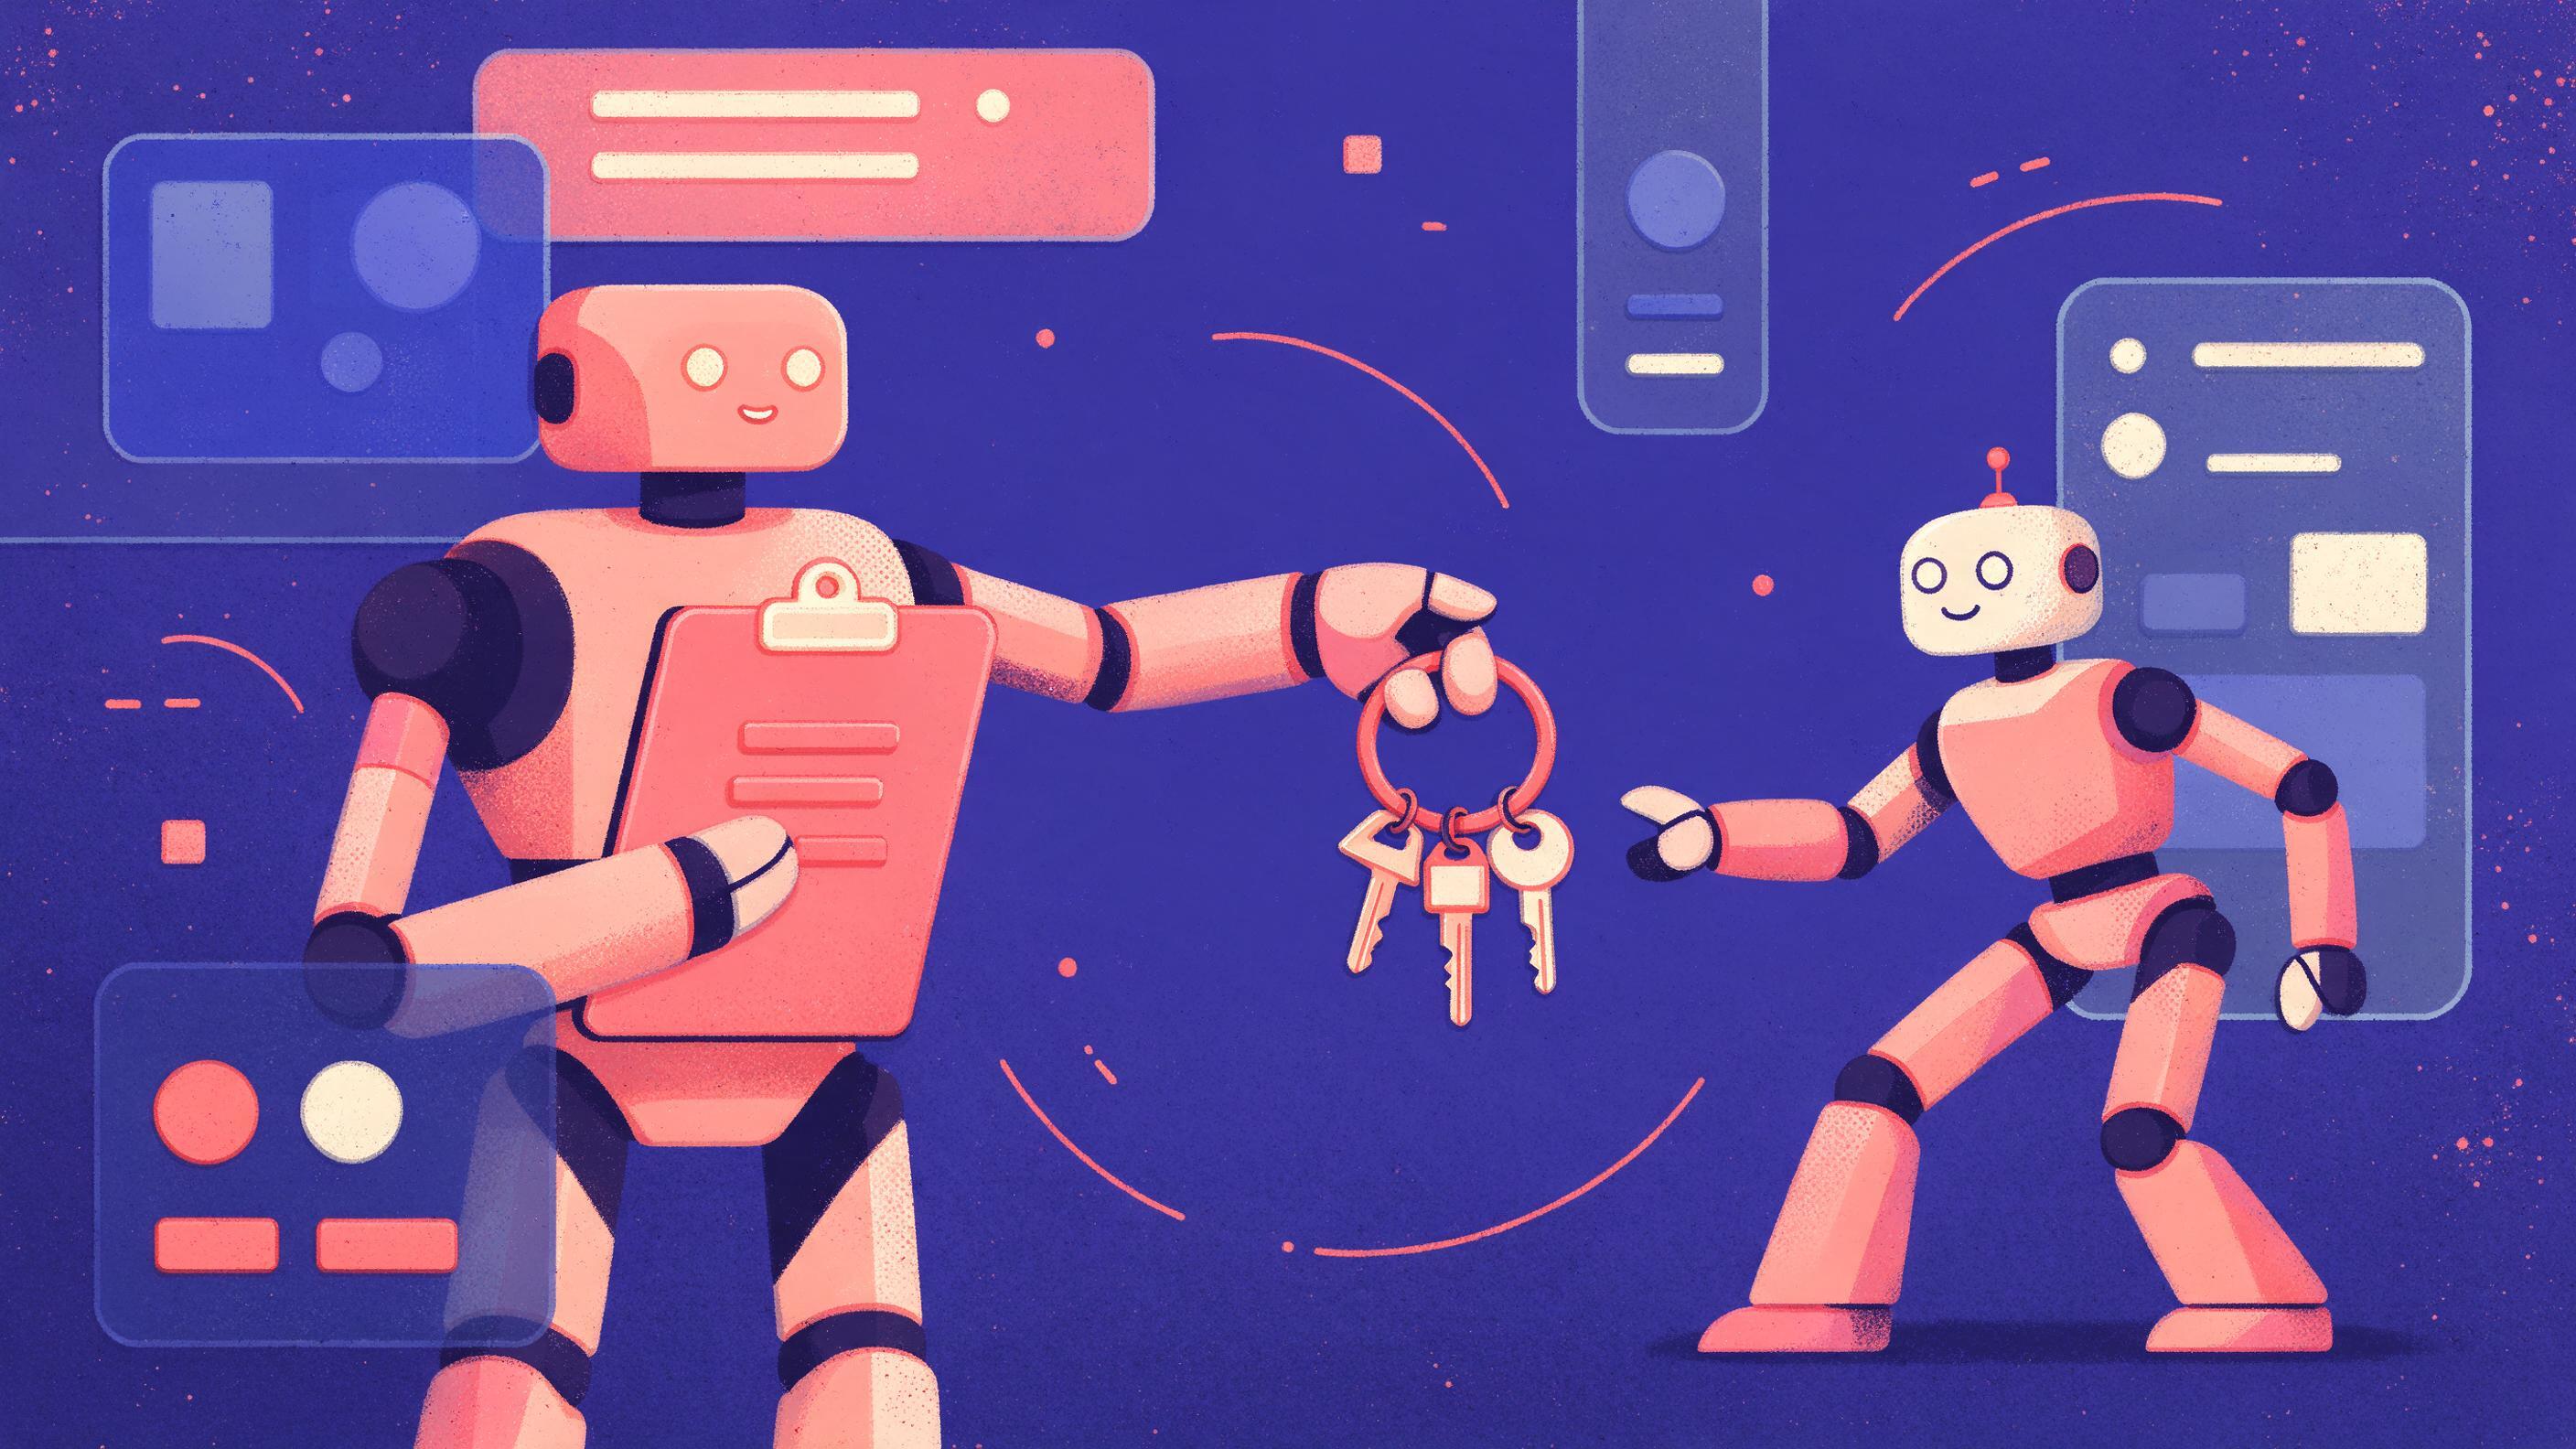
A split scene: on the left, a parent agent (a simple robot icon) holds a clipboard labeled 'Risk Profile: Medium' and hands a smaller robot a key ring with only three keys labeled 'read_file', 'search', and 'fetch_url'.
Key points

Key points

  1. 1A subagent is a separate principal with its own task risk, so it should never inherit the parent's full tool set or credentials by default.
  2. 2Author permission policy as a reviewable, testable artifact listing allow, deny and require-approval decisions per tool and argument pattern.
  3. 3Derive the child's effective scope at spawn time from three inputs: data sensitivity, action reversibility and blast radius.
  4. 4Enforce the scope with short-lived scoped credentials, an argument validation wrapper and fail-closed defaults, then log every decision.

Why delegation changes the permission model

The permission question people ask is "can the agent call this tool?" The question they should ask is "can this specific child, for this argument, now, under whose consent, for how long?" Those are different questions with different answers, and conflating them is the most common source of runaway agents.

A parent agent runs inside a session that already holds user context, an OAuth token, and a configured list of reachable tool servers. A spawned subagent is a new execution principal with narrower instructions and often a different risk profile. Treating it as a clone of the parent collapses the trust boundary described in Permit's analysis of subagent tool permissions. When a child inherits a write-capable token because it shares a workflow, a read-only reporting task can silently perform writes nobody consented to.

This is not theoretical. A bug report against a coding agent described exactly this failure: a user had blocked Bash in their settings, approved a single subagent launch, and the children then ran dozens of shell commands, including reads of SSH keys and shell history, with no per-command gate reported in this issue thread. The deny rule existed. The delegation path bypassed it.

The architectural reason is straightforward. Multi-agent designs distribute control across cooperating processes, each of which may have its own tools, memory and decision-making as JetBrains describes in its comparison of single and multi-agent systems. Once control is distributed, authority has to be distributed deliberately. Otherwise authority leaks along with the delegation.


Decide first whether you need a subagent

Tool scoping is cheaper than it looks only if the child needs to exist. Microsoft's guidance is to use the lowest level of complexity that reliably meets the requirement, and to justify multiagent orchestration through prompt complexity, tool overload or genuine security boundaries per the Azure Architecture Center. If your reason for spawning a child is "the prompt got long," scoping is paperwork on top of an unnecessary problem.

The decision rule I use:

SituationUse a subagent?Why
Task needs the same tools as the parentNoScope would equal parent, so no boundary is gained
Task needs fewer tools than the parentYesYou can actually shrink the effective surface
Task needs a different credential classYesSeparate principal maps to separate token
Task is read-only analysis of parent outputOften noA single tool call or a structured prompt suffices
Task must run against a regulated systemYesIsolated identity makes the audit trail clean

Multi-agent setups carry coordination overhead, latency and their own failure modes, and fan-out patterns multiply concurrent requests against the same rate limits per Beam's production write-up of orchestration patterns. If the only thing you gain from a subagent is a permission boundary, that is often still worth it. If you gain no boundary, reconsider.

Build the declarative policy

A permission policy is a data file, not a function buried inside agent setup. Putting rules in a separate, reviewable artifact is the pattern the AI SDK documents for its OPA-based tool approvals: rules live in .rego files, are testable in CI with opa test, and can be edited without a code deploy per the AI SDK policy documentation.

The policy should answer three questions per tool call: which tool, which argument shape, and what decision. Keep decisions to three states, which map directly onto the approval statuses that SDK uses: allow runs the tool, deny returns a denied result the model can reason about, and requires approval pauses for a human response.

# tools.policy.yaml
version: 3
defaults:
  decision: deny          # fail closed for anything unmatched
tools:
  search_tickets:
    - decision: allow
      args: {query: {type: string, max_length: 200}}
  read_customer_record:
    - decision: allow
      args: {customer_id: {pattern: "^cust_[0-9]{6}$"}}
      data_class: [internal, pii]
  send_email:
    - decision: require_approval
      args: {to: {required: true}}
      reason: "outbound mail always needs a human"
  refund:
    - decision: allow
      args: {amount: {max: 0}}
    - decision: require_approval
      args: {amount: {min: 0.01, max: 50}}
    - decision: deny
      args: {amount: {min: 50.01}}
      reason: "refunds above 50 need finance, not an agent"

Three details make this file useful rather than decorative. First, defaults.decision: deny inverts the usual posture. The AI SDK notes that an unmatched rule normalizes to not-applicable, which the SDK treats as allow, so you must add an explicit default deny to your policy to get fail-closed behavior per the same documentation. Second, argument patterns carry as much weight as tool names: allowing refund without a ceiling is not scoping. Third, the decision should be able to consult history, not just the current call. A rule like "deny a second irreversible action in the same run" requires the policy input to include prior calls, which the AI SDK exposes through the full message and tool-call history.

Policy enforcement is strongest on deterministic checks: scopes, thresholds, allowlists, counts and running totals. Content judgments such as "block hostile language" are best-effort and easy to bypass, so keep those in a classifier and let policy handle the deterministic gate around it per the AI SDK guidance.

Derive the scope from the parent's risk profile

The policy says what could be allowed. The risk profile says what this child gets. Three inputs do most of the work.

Data sensitivity. What class of data does the child's task touch? A child summarizing public documentation should not hold a credential that reads customer records, even if the parent session can. Classify the input data and map classes to permitted tools.

Action reversibility. Reads are free, writes are not. Deleting a row, sending an email, pushing to a main branch and issuing a refund are all irreversible in the sense that a human will notice and a rollback is expensive. Irreversible actions should default to approval regardless of how privileged the parent is.

Blast radius. How many resources can the child touch if it goes wrong? A query scoped to one tenant is small. A credential that lists every bucket in an account is large. Blast radius is often better controlled by the credential than by the tool name.

Put these together as a derivation function that runs before spawn:

def derive_scope(parent_ctx, task):
    level = 0
    if task.touches_pii or task.touches_secrets:
        level = max(level, 2)
    if not task.reversible:
        level = max(level, 2)
    if task.resource_count > 10:
        level = max(level, 1)
    # level 0: read-only tools; 1: scoped writes; 2: writes gated on approval
    return {
        "tools": TOOLSET_BY_LEVEL[level],
        "credential_ttl_seconds": [900, 600, 300][level],
        "approval_required": level == 2,
        "tenant": parent_ctx.tenant,
        "trace_id": parent_ctx.trace_id,
    }

The result of this function is the child's task envelope. It travels with the spawn call and is the only source of truth for what the child may do. The parent's own permissions are never consulted by the child at runtime.

A worked example with numbers clarifies the tradeoff. Suppose the parent orchestrator can call 14 tools. A spawned "summarize support tickets" child needs two of them. If you inherit wholesale, the child's effective surface is 14 tools and one write-capable token; if one in twenty delegated calls is misrouted, four of every five hundred children get a surface far beyond their task. If you derive scope, the child gets two tools and a 900-second read-only token. The failure is still possible, but it is bounded to reading tickets for fifteen minutes.

Enforce at spawn, not in the prompt

Telling the child in its instructions to avoid certain tools is a suggestion. Enforcement means the child literally cannot reach them. Three mechanisms do that work.

Scoped credentials. Mint a child-bound token rather than passing the parent's token downward. The distinction between token inheritance and a token broker is central: inheritance passes existing OAuth material down, while a broker mints child-bound, scope-minimized, time-bounded credentials tied to a delegated approval event per Permit. Treat scope minimization as a property of the credential, not of the tool.

Argument validation wrapper. Every tool call passes through a wrapper that loads the policy, evaluates the call, and either runs it, returns a denied result, or raises an approval request. The wrapper must never fall through to allow. Where the framework supports a policy decision point outside the model, put the check there rather than in application code, because every control that depends on best-effort prompt instructions will eventually be bypassed per Permit's audit trail guidance.

Fail-closed timeouts. An approval request that nobody answers must resolve to denial, not to a stalled child. Name the denial reason so the parent can recover deterministically. Silent stalls are a distinct failure mode from denials, and operators need to tell them apart per Permit.

For teams running agents against production systems, this is where Quanta Inference fits as the credential-free layer: text, image and embedding models behind one OpenAI-compatible endpoint, so the model call itself holds no tool authority and the scoping work stays in your wrapper. Details are at Quanta Inference.

Trace the scope so the decision is provable

An audit trail for an agent action is not the same thing as a tool trace. A tool trace tells you a function was called. An authorization record tells you whether that call was permitted, for which agent, on whose behalf, against which resource, under which policy version, with what outcome per Permit. Auditors sample for the second.

Carry the trace context across the delegation boundary. Context propagation exists precisely so signals can be correlated across process and network boundaries, and the default propagator uses W3C TraceContext headers per OpenTelemetry's context propagation documentation. Those headers follow a defined format, version-trace-id-parent-id-trace-flags per the W3C Trace Context specification.

Agent boundaries break this in known ways. When an orchestrator enqueues work for a worker, there is no HTTP request to carry traceparent, so the worker starts its own root span and the causal link is severed; the standard fix is to extract the context, serialize it into the message payload, and reattach it on the consumer side per TianPan's write-up on tracing across agent service boundaries. The same problem applies to model context protocol calls, where the calling agent must inject the header at the invocation site.

An in-flight proposal for agent-to-agent tracing makes the gap concrete: the SDK creates spans locally, but there is no standard mechanism to inject traceparent into a delegated message and extract it on the other end, so each delegation produces a disconnected trace per this A2A issue. That proposal also declines to propagate baggage in its first version, on the grounds that baggage travels in plaintext to all downstream services and creates a leakage vector in multi-tenant deployments per the same issue. The lesson for scoping is direct: do not put scope in anything that fans out indiscriminately.

Record at minimum, per decision: agent identity, parent task or delegation chain, tool and arguments, resource, policy ID and version, decision and reason, approval record if any, timestamp, trace ID, and outcome. That is the evidence package that lets an auditor reconstruct the decision later per Permit. Deny records matter as much as allow records, because they prove the gate is active.

A checklist before you ship

CheckPass condition
Default decisionUnmatched calls deny, not allow
Argument patternsWrite tools have ceilings or allowlists
CredentialChild-bound, scope-minimized, short TTL
InheritanceNo parent token reaches the child
ApprovalsExplicit escalation event, timeout fails closed
TraceChild spans attach to parent trace ID
Deny loggingDenials recorded with reason and policy version
CIPolicy tests run on every change
History rulesRepeated irreversible actions blocked

Two rows deserve emphasis. The credential row is the one teams skip, and it is the one that survives a buggy policy evaluation: if the child's token cannot write, a policy error cannot cause a write. The history row is the one teams forget: a policy that evaluates only the current call will happily approve the same destructive action ten times in a row, which is why the input should carry prior tool calls per the AI SDK documentation.

If your team is standing up this pattern across many workflows, the fastest route is often to have someone build the policy layer, wrapper and trace plumbing alongside you rather than after an incident. Quanta specialists can take a described requirement and hand back working deliverables, starting from Quanta.

FAQ

FAQ

What is the difference between tool scoping and runtime authorization?

Tool scoping answers what could ever be called from a given configuration. Runtime authorization answers what is allowed right now, for this child, this action, these arguments and this consent state. You need both: the allowlist defines possible connectivity, and a permission gate decides each call per Permit.

Should a subagent inherit the parent's OAuth token?

No. Inheritance passes existing credential material downward and lets a narrow child act with the parent's full scope. A token broker mints a child-bound, scope-minimized, time-bounded credential tied to a delegated approval event, which bounds damage from any single misrouted task per Permit.

How do I make policy enforceable rather than advisory?

Put rules in a separate artifact evaluated by a wrapper or policy decision point before each tool dispatch, and set the default to deny. The AI SDK documents that unmatched rules normalize to not-applicable, which it treats as allow, so the explicit default deny is required for fail-closed behavior per the AI SDK.

What should an approval timeout do?

Deny, with a named reason. A stalled child that never resolves leaves the orchestrator hung and operators unable to tell denial from non-review. Configure an explicit escalation channel, a timeout that fails closed, and a recovery path visible to the parent per Permit.

How do I prove after the fact which tool a subagent was allowed to use?

Log an authorization decision record at the gate, not just a tool trace. Capture agent identity, delegation chain, tool and arguments, resource, policy version, decision and reason, approval record, timestamp, trace ID and outcome, so the decision can be reconstructed later per Permit.

Sources

Sources

  1. When AI Subagents Call MCP Tools, Who Owns ...
  2. BUG Sub-agents bypass permission deny rules and per ...
  3. Single Agent vs Multi-Agent Systems: When to Use Each - JetBrains
  4. AI Agent Orchestration Patterns - Azure Architecture Center
  5. 6 Multi-Agent Orchestration Patterns for Production (2026) - Beam AI
  6. Policy-Based Tool Approvals
  7. AI Agent Audit Trail: Proving What an Agent Did and Why
  8. Context propagation - OpenTelemetry
  9. Trace Context - W3C
  10. Distributed Tracing Across Agent Service Boundaries - TianPan.co
  11. Proposal: Distributed Tracing Semantic Conventions for A2A #2103
About the author

About the author

Antonio Evans
Antonio Evans

Antonio Evans is the founder of Quanta Intelligence and a fractional CTO who builds HIPAA-ready AI systems for health and life-science companies. Before that he was technical co-founder of FriendsEAT for twenty years, CEO of Socialdraft, and a data engineer at IBM. Antonio lives with his dog Santino in Lisbon, Portugal.

All articles
