
Security

Turning a Compensating Control Into a Test That Fails CI

Antonio Evans10 min read

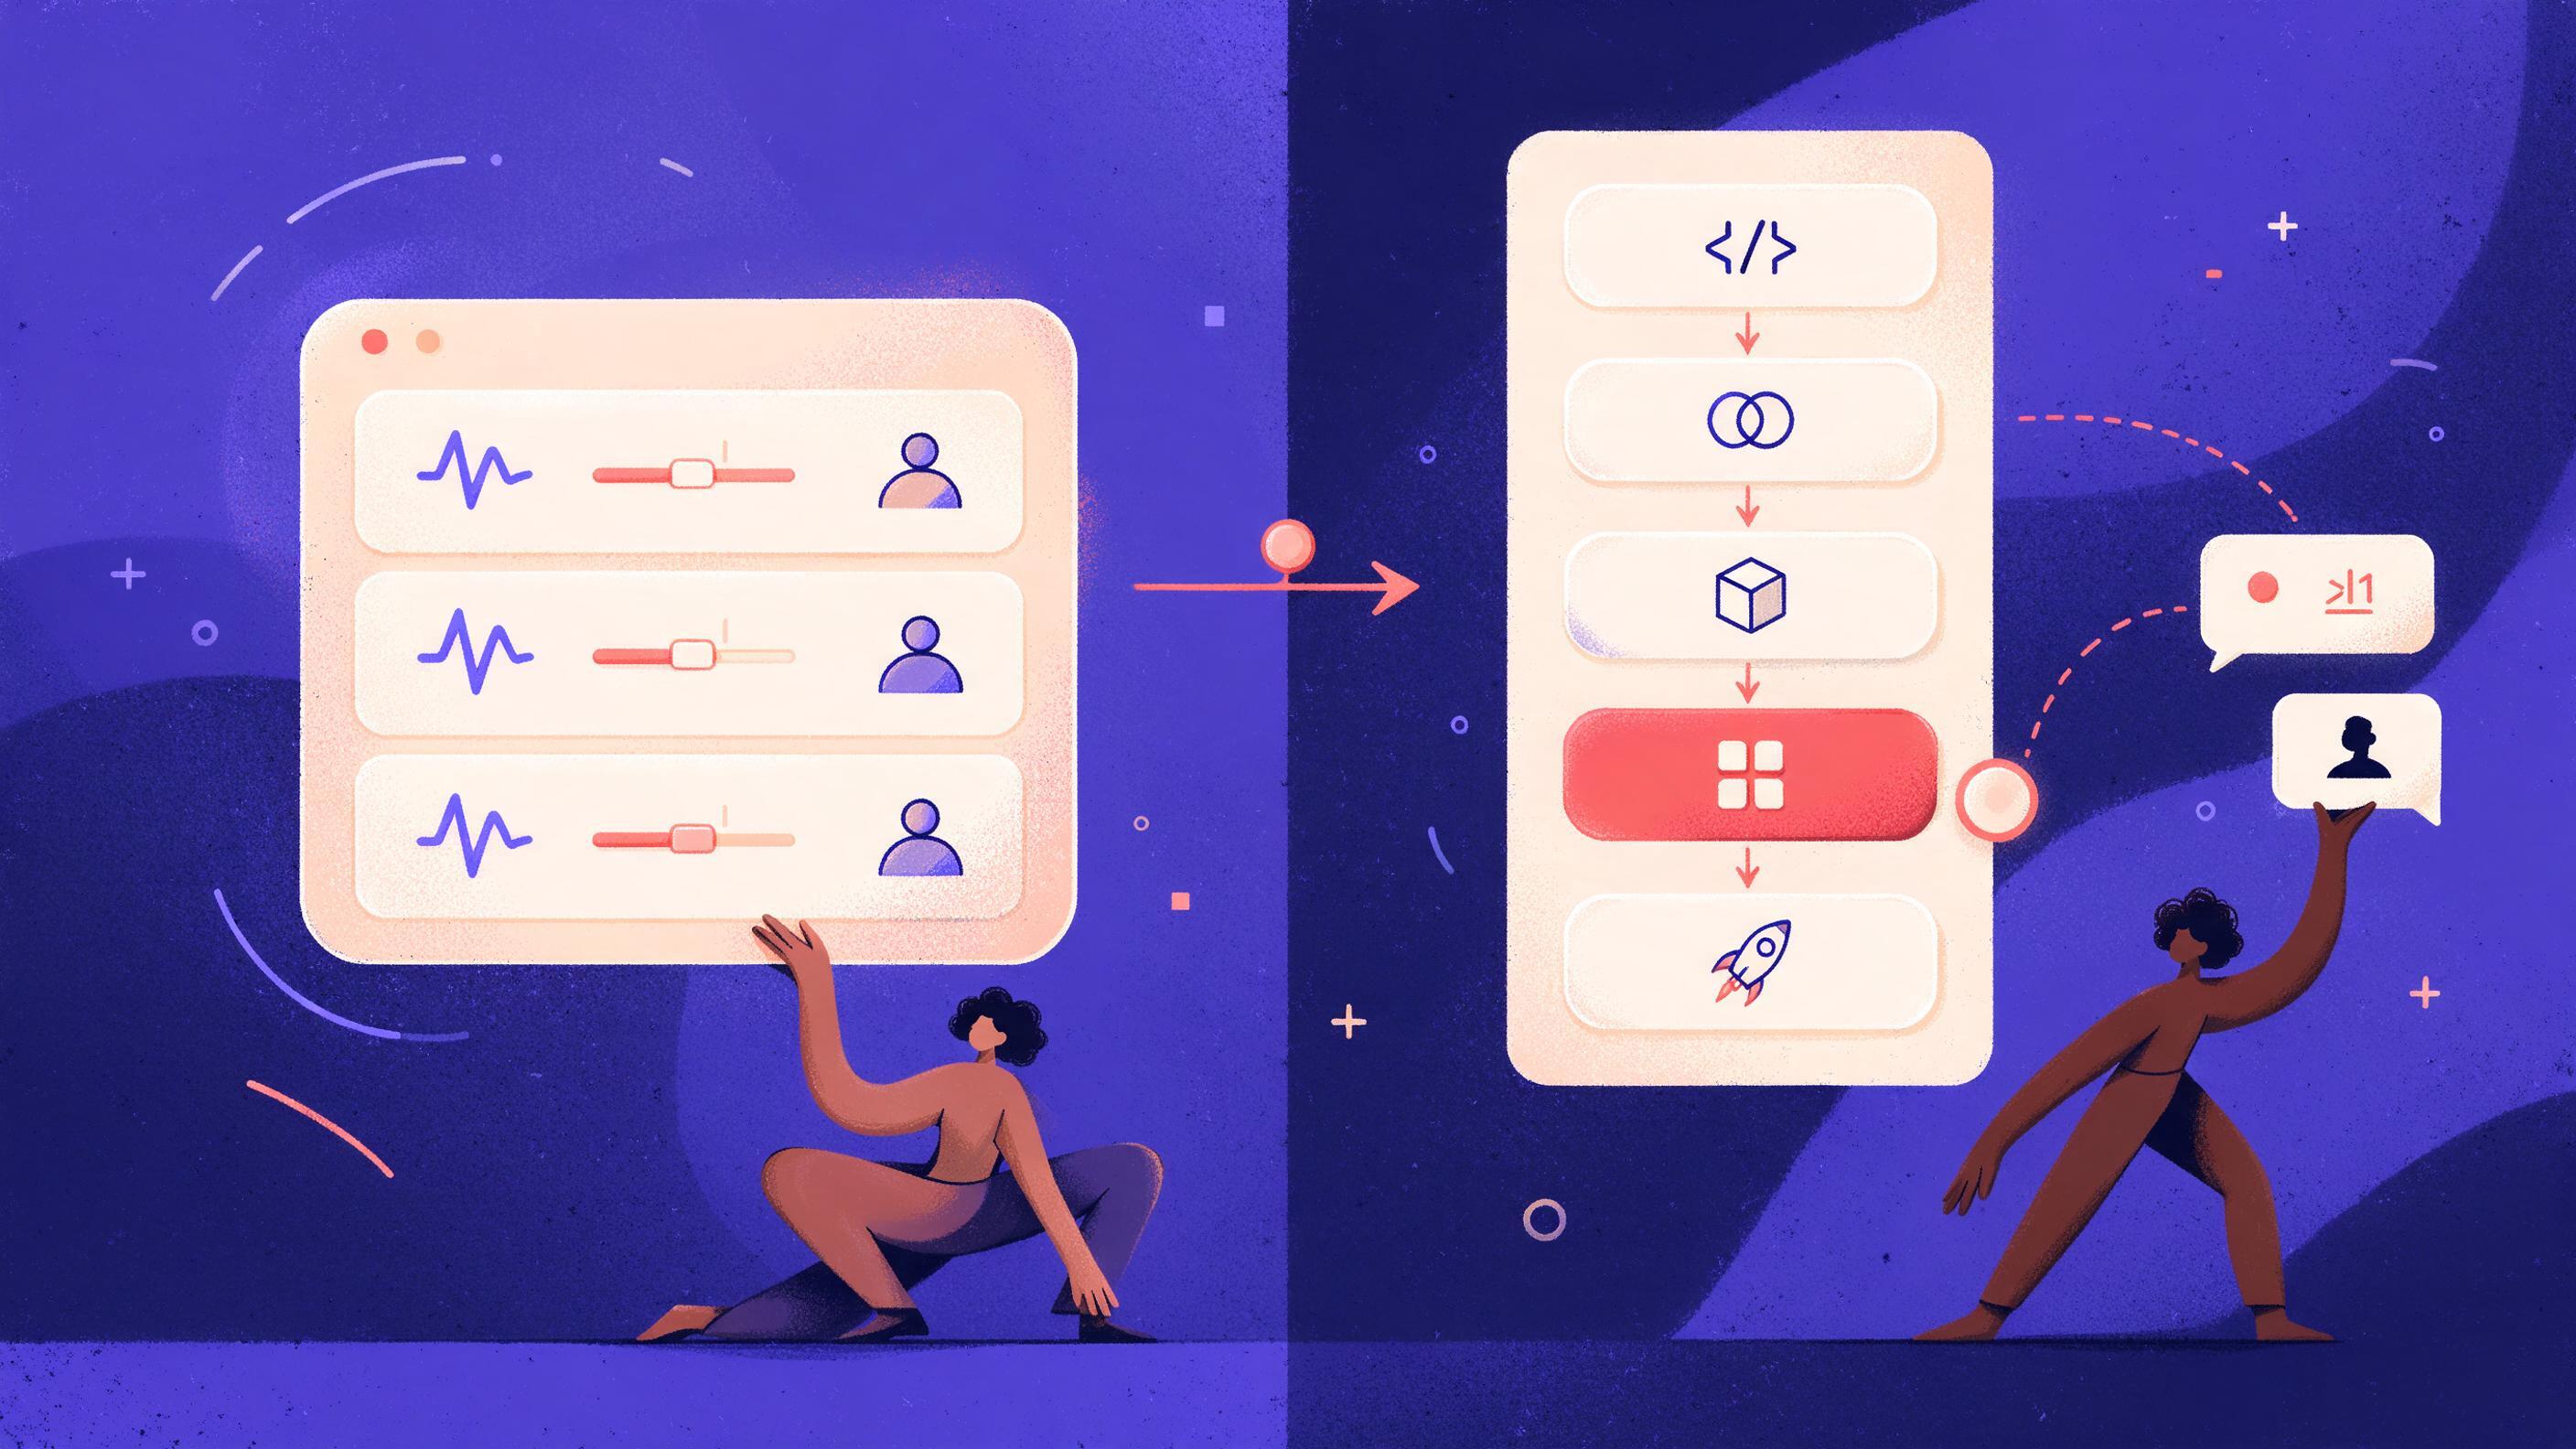
A split scene: on the left, a control record card with fields for signal, threshold and owner; on the right, a CI pipeline with a red failing test step connected by an arrow to an alert notification sent to the owner.
Key points

Key points

  1. 1A compensating control only counts if its signal, threshold and owner are written down in a form a machine can compare against live state.
  2. 2The test reads the control's actual signal, compares it to the recorded threshold, and fails the build when the two diverge.
  3. 3Wiring that test into the existing CI suite makes drift block merges before a reviewer has to notice it by hand.
  4. 4Failure has to route to the named owner in the control record, or the check becomes a red badge nobody acts on.

Pull the signal, threshold and owner out of the control record

Most compensating controls live in a document: a gap statement, a list of alternative safeguards, a residual risk rating and an expiry date. The minimum fields for a good exception record are a service name, a business and technical owner, the control being bypassed, the reason it cannot be met, a plain-language risk statement, the compensating controls, an expiry date, an approval authority and evidence of review on expiry. That is a governance artifact. None of it is executable.

The bridge is to extract three things and discard the rest for testing purposes:

  • Signal. The measurable state the compensating control produces. Not "network segmentation exists" but "the count of egress flows from the isolated subnet to the database tier." Not "monitoring is enabled" but "days since the last successful ingestion from the log pipeline."
  • Threshold. The boundary the signal must stay inside for the control to still be doing what the acceptance record claims. This is a number with units and a direction.
  • Owner. The named accountable person or role in the record. This is the routing target for failure, not a distribution list.

Documentation guidance for compensating controls is specific about why the artifact reference matters: "a control with no artefact reference cannot be tested." The firewall policy name, rule ID, configuration flag or feature toggle is what the test reads. If the control record names a safeguard but not the artifact that enforces it, the record is incomplete and the test cannot be written.

A trap to avoid: the signal must be observable from outside the control, not a restatement of its configuration. "The WAF rule is enabled" is configuration. "Requests matching the exploit pattern reached the origin" is a signal. The first passes even when the rule is bypassed, because the test reads the intent rather than the behavior. Automated control testing reads the control's actual state from the system that enforces it and compares it with an expected state written down in advance, and any difference is treated as an exception to resolve.


Write the control's expected state as data before you write the test

NIST SP 800-53A Rev. 5 Appendix F describes the mechanism plainly: the organization writes the desired state as data, the assessment compares it with actual state, and a mismatch indicates a defect, with the worked example being a policy that locks accounts after three failed logons against a device configured to allow five, which points at a problem with AC-7, AC-2 or CM-2. That is the same shape as a unit test, and it means the first artifact you write is not code. It is a record.

A workable control record for testing carries six things, which line up with the six items a test definition records: the control and the requirements it maps to, the scope and system of record, the expected state as a rule, a frequency matching how fast the evidence changes, the owner who acts on failure, and a version with the name of whoever approved that version. The last item matters more than it looks, because a test whose rule can be changed without approval can be made to pass.

Here is a filled-in example. A team cannot enforce phishing-resistant MFA for a set of administrative accounts on a legacy platform, so the acceptance record names an alternative: a named-admin allowlist, just-in-time elevation, session logging and a monthly access review, with the residual exposure accepted until a remediation milestone. The worked vendor example shows the same shape with concrete conditions: remediation in 60 days, final implementation in 120, monthly evidence, immediate escalation after any privileged-account incident, and automatic expiry at 120 days unless a fresh decision is approved.

For CI purposes, that memo collapses into:

FieldMemo saysTest reads
Signalsession logging on elevated accountscount of elevation events in the identity provider with no matching session log record
Thresholdmonthly evidence, no unexplained gapszero unexplained elevation events in the last 24 hours, and at least one review record in the last 31 days
Ownernamed residual risk ownerthe on-call rotation that pages that owner
Expiry120 days from decision datea date literal the test compares against the system clock
Artifactallowlist ID, elevation policy namethe actual policy object ID in the IdP
Versionapproval authoritya hash or commit SHA of the record file

Two design decisions follow from this table. First, the expiry is a test, not a calendar reminder. An expired acceptance should fail the build the same way a broken control does, because both mean the organization is carrying risk it has not re-approved. An annual review tests whether the compensating control still matches the current system, threat and business context, and the conditions that justified a workaround drift over time. Second, the threshold has a second boundary. "Zero unexplained events" catches the control breaking. "At least one review record in the last 31 days" catches the control going quiet, which is how a manual review process dies without anyone noticing.

A note on evidence freshness. NIST SP 800-53A gives each determination one of two findings, satisfied or other than satisfied, and notes that other than satisfied can also mean the assessor could not obtain enough information to decide. Keep the distinction: a control that failed and a control nobody could read need different owners and different responses. A dashboard that counts an undecided result as a pass looks greener than the environment behind it.

Write the test so it fails loudly and specifically

The test has three jobs: fetch the signal, compare against the threshold, and produce a failure message a human can act on without opening a dashboard. Keep it in the same language and framework as the rest of the suite so it inherits the existing runner, reporting and retry behavior.

A minimal check, in the shape most suites already accept:

import datetime
import os
import sys
import requests

CONTROL = {
    "id": "CC-014-privileged-elevation",
    "signal": "elevation_events_without_session_log",
    "max_value": 0,
    "min_value": 0,
    "evidence_max_age_days": 1,
    "review_max_age_days": 31,
    "owner": "identity-platform-oncall",
    "expires_on": datetime.date(2026, 3, 14),
}

def fetch(path):
    r = requests.get(f"{os.environ['EVIDENCE_API']}{path}",
                     headers={"Authorization": f"Bearer {os.environ['EVIDENCE_TOKEN']}"},
                     timeout=30)
    r.raise_for_status()
    return r.json()

def test_compensating_control_holds():
    if datetime.date.today() > CONTROL["expires_on"]:
        sys.exit(f"FAIL {CONTROL['id']}: acceptance expired on {CONTROL['expires_on']}. "
                 f"Re-approve or remediate. Owner: {CONTROL['owner']}")

    data = fetch("/elevation/summary")
    event_count = data["unexplained"]
    evidence_age = data["hours_since_read"]
    review_age = data["days_since_last_review"]

    problems = []
    if event_count != CONTROL["max_value"]:
        problems.append(f"{event_count} elevation events with no session log "
                        f"(threshold {CONTROL['max_value']})")
    if evidence_age > CONTROL["evidence_max_age_days"] * 24:
        problems.append(f"evidence stale by {evidence_age}h")
    if review_age > CONTROL["review_max_age_days"]:
        problems.append(f"last access review {review_age}d ago "
                        f"(max {CONTROL['review_max_age_days']})")

    if problems:
        sys.exit(f"FAIL {CONTROL['id']}: " + "; ".join(problems) +
                 f". Owner to notify: {CONTROL['owner']}")

Three details are deliberate. The failure exits with a message that names the control, the measured value, the threshold and the owner, so the build log alone is enough to route the alert. The evidence-freshness check is separate from the value check, because a stale feed returning yesterday's clean number is the most common way a control test silently passes. And the expiry check runs first, so an expired acceptance cannot be masked by a passing signal.

Resist the temptation to make the interlock write to production. The test reads; a human or the owner's workflow changes state. Back-porting a fix closes the CVE so no exception paperwork is needed, and the same principle applies here: the best long-term result of a failing compensating-control test is usually the underlying fix, not a renewed exception.

Wire it into the suite so failure blocks the merge

A control test that runs on a nightly schedule reports drift after it has already shipped. A control test that runs in the pull-request pipeline blocks the change that caused the drift from reaching production. The pipeline already has the gates; the control test just needs to sit inside one of them.

The CI stage runs automated tests on every commit or pull request, and if something fails at that stage the developer is notified right away, which is the feedback loop you want: the person who changed the elevation policy finds out in minutes, with context still fresh, rather than a reviewer finding it in a diff. Two practical constraints apply. First, latency: a test suite that takes 45 minutes to run defeats the purpose of continuous integration, so a control check that calls three APIs should be its own job that runs in parallel, not a step bolted onto the slow end-to-end block. Second, flakiness: an API timeout is undecided, not failed, and should retry or report separately so the owner does not learn to ignore the check.

Two triggers, two jobs:

  • On pull request. Run the control test when the diff touches any file the control depends on (the policy definitions, the identity configuration, the evidence pipeline config). A path filter keeps it fast and keeps the signal scoped to changes that could plausibly move it.
  • On schedule. Run it once a day regardless of code changes, because a control can break from an out-of-band console change that never appeared in a diff. This is the check that catches drift from working.

Make the required-status check branch-protecting. If the control test is advisory, it will be merged past, and the acceptance record will keep claiming coverage on a control that no longer holds. A test whose rule can be changed without approval can be made to pass, so protect the control record file itself with a CODEOWNERS entry that maps to the approving authority named in the memo.

Route the failure to the owner, not to a channel

The failure message is only half the alert. The other half is where it lands. Three channels, in order of how directly they reach the accountable person:

  1. The pull request itself. The required check fails, the author sees the message, and the merge button is disabled. This reaches whoever caused the change, which is usually the fastest path to a fix.
  2. A direct page or ticket to the named owner. The owner field in the control record maps to an on-call rotation or a queue. When a test fails, an exception opens with a named owner and a due date, and it is linked to the risk it affects, and the ticket stays linked through the retest.
  3. The risk register. A failure that is not fixed within the exception window becomes a register entry with a fresh decision, because the original acceptance did not contemplate a broken compensating control.

The routing rule matters because of what happens without it. Unless controls are documented and reviewed, the organization cannot show what exception was approved, why the primary control was waived, or what specific safeguard was accepted in its place, and the practical consequence is that teams treat an exception as permanent even when it was meant to be temporary. A failing check routed to a general security channel produces exactly that outcome: everyone sees it, nobody owns it, and it stays red until the branch protection is quietly disabled.

A worked failure makes the routing concrete. The elevation summary API returns three unexplained elevation events at 09:14. The pull request that added a new admin to the allowlist fails the required check with the message from the code above. The author cannot merge. The check also opens a ticket assigned to the identity platform on-call, linked to CC-014 and to the risk it maps to in the register. The reviewer who would otherwise have approved the diff on the strength of "the allowlist is still there" never sees it, because the merge is already blocked. An hour later the cause is found: the new admin's session logging was misconfigured because the allowlist entry was added to the IdP but not to the logging policy. The fix is a second commit, the check re-runs, the count returns to zero, and the exception closes with a retest record attached.

That is the whole point. A compensating control is only as useful as its tested status, and listing compensating controls without stating whether they have been tested, what period they cover and whether any deficiencies exist tells the signer that coverage exists, not that coverage works. The CI test is what converts the second claim into the first.

A decision rule for what to automate first

Not every compensating control deserves a CI test. Score each one on two axes and pick the high-high corner first.

CriterionAutomate nowDefer
Signal is machine-readableQuery, API, log count, config object IDRequires a human to read a screenshot
Signal changes without a code changeConsole changes, expiring certificates, review cadencesOnly changes when a specific repo changes
Failure is silentControl decays quietly, no incident firesA control failure produces its own alert already
Residual exposure is highBroad scope, sensitive data, privileged accessNarrow scope, low sensitivity
Expiry is fixed and nearAcceptance expires within the review cycleOpen-ended, no date set

The minimum fields for an exception include an expiry date and a plan for closure or renewal, and exception governance rules that prevent decay require every renewal to carry evidence that the underlying blocker still exists. A CI test is the cheapest possible way to produce that evidence on a rolling basis: the passing check is the renewal evidence, dated, versioned and attached to a commit.

One more rule that keeps the program honest. If a compensating control has no artifact the test can read, that is not a reason to skip the test. It is a finding about the control. A compensating control must achieve the same security outcome or reduce risk to an acceptable level, as validated through documented risk assessments, and a control nobody can measure has not been validated. Send it back to the owner to name the enforcing artifact before the next review.

If you are building this across many controls and several teams, the shared plumbing (a private library of control checks, one place to hold the evidence credentials, and per-person keys so failures route to the right owner) is where team plans usually pay off: Quanta for Teams covers the shared credit pool, private skill library and admin controls. If you would rather design the control-testing approach against your own acceptance records first, a free 30-minute discovery call is a reasonable place to start.

FAQ

FAQ

Can I test a compensating control without an API for its signal?

Yes, but you have to introduce a signal. If the only evidence is a person reading a screenshot, replace it with something a machine can read: a count exported from the system of record, a config object ID fetched from the enforcing platform, or a signed attestation record with a timestamp. Until then the control is untestable, which is itself a finding worth raising at the next review.

What is the difference between a failing control test and an expired acceptance?

A failing test says the compensating control is not currently doing what the acceptance record claims, so the residual risk is larger than the signer approved. An expired acceptance says nobody has re-approved the decision, so the risk may be the same but the authority to carry it has lapsed. Both should block, but they route differently: the failure goes to the control owner for a fix, the expiry goes to the approving authority for a decision.

How often should the check run?

Match the frequency to how fast the evidence can change. A configuration object that only moves when a pull request merges can run per pull request with a daily sweep. An access review cadence of 31 days needs a daily check that the last review record is inside the window, because the failure mode is silence rather than an event. The test definition should record the frequency alongside the threshold so it can be reviewed with the rest of the record.

Does a passing control test mean the compensating control is equivalent to the primary control?

No. It means the specific signal the record names stayed inside the threshold for the period tested. The memo does not claim that compensating controls are equivalent; it records why the residual exposure is temporarily within the authorized boundary. Equivalence is a judgment about design, made by a human, and it is exactly the judgment the automated test does not make.

What happens when the acceptance expires while the check is failing?

Treat the two as one incident rather than two tickets. The failing check means the compensating control is degraded, and the expiry means nobody currently has authority to carry the degraded exposure, so the path is: open one exception linked to both, assign the control owner to fix the signal and the approving authority to decide whether to renew, and keep the merge blocked until both are resolved or the residual risk is re-accepted with fresh evidence.

Sources

Sources

  1. Risk Acceptance, Exceptions, and Decision Records
  2. What to Document When You Apply a Compensating ...
  3. Automated Control Testing in Continuous Control Assurance
  4. Vendor Security Risk Acceptance Memo Template
  5. What breaks when CISO-approved compensating controls ...
  6. CI/CD Automation Testing: Essential Strategies for Faster ...
  7. Writing a risk acceptance record the accepting executive ...
  8. A Practical Guide to Designing and Applying Compensating Controls
About the author

About the author

Antonio Evans
Antonio Evans

Antonio Evans is the founder of Quanta Intelligence and a fractional CTO who builds HIPAA-ready AI systems for health and life-science companies. Before that he was technical co-founder of FriendsEAT for twenty years, CEO of Socialdraft, and a data engineer at IBM. Antonio lives with his dog Santino in Lisbon, Portugal.

All articles
