AI coding

What an Agent May Do to a Database: Grants, Roles, Read-Only

Antonio Evans9 min read

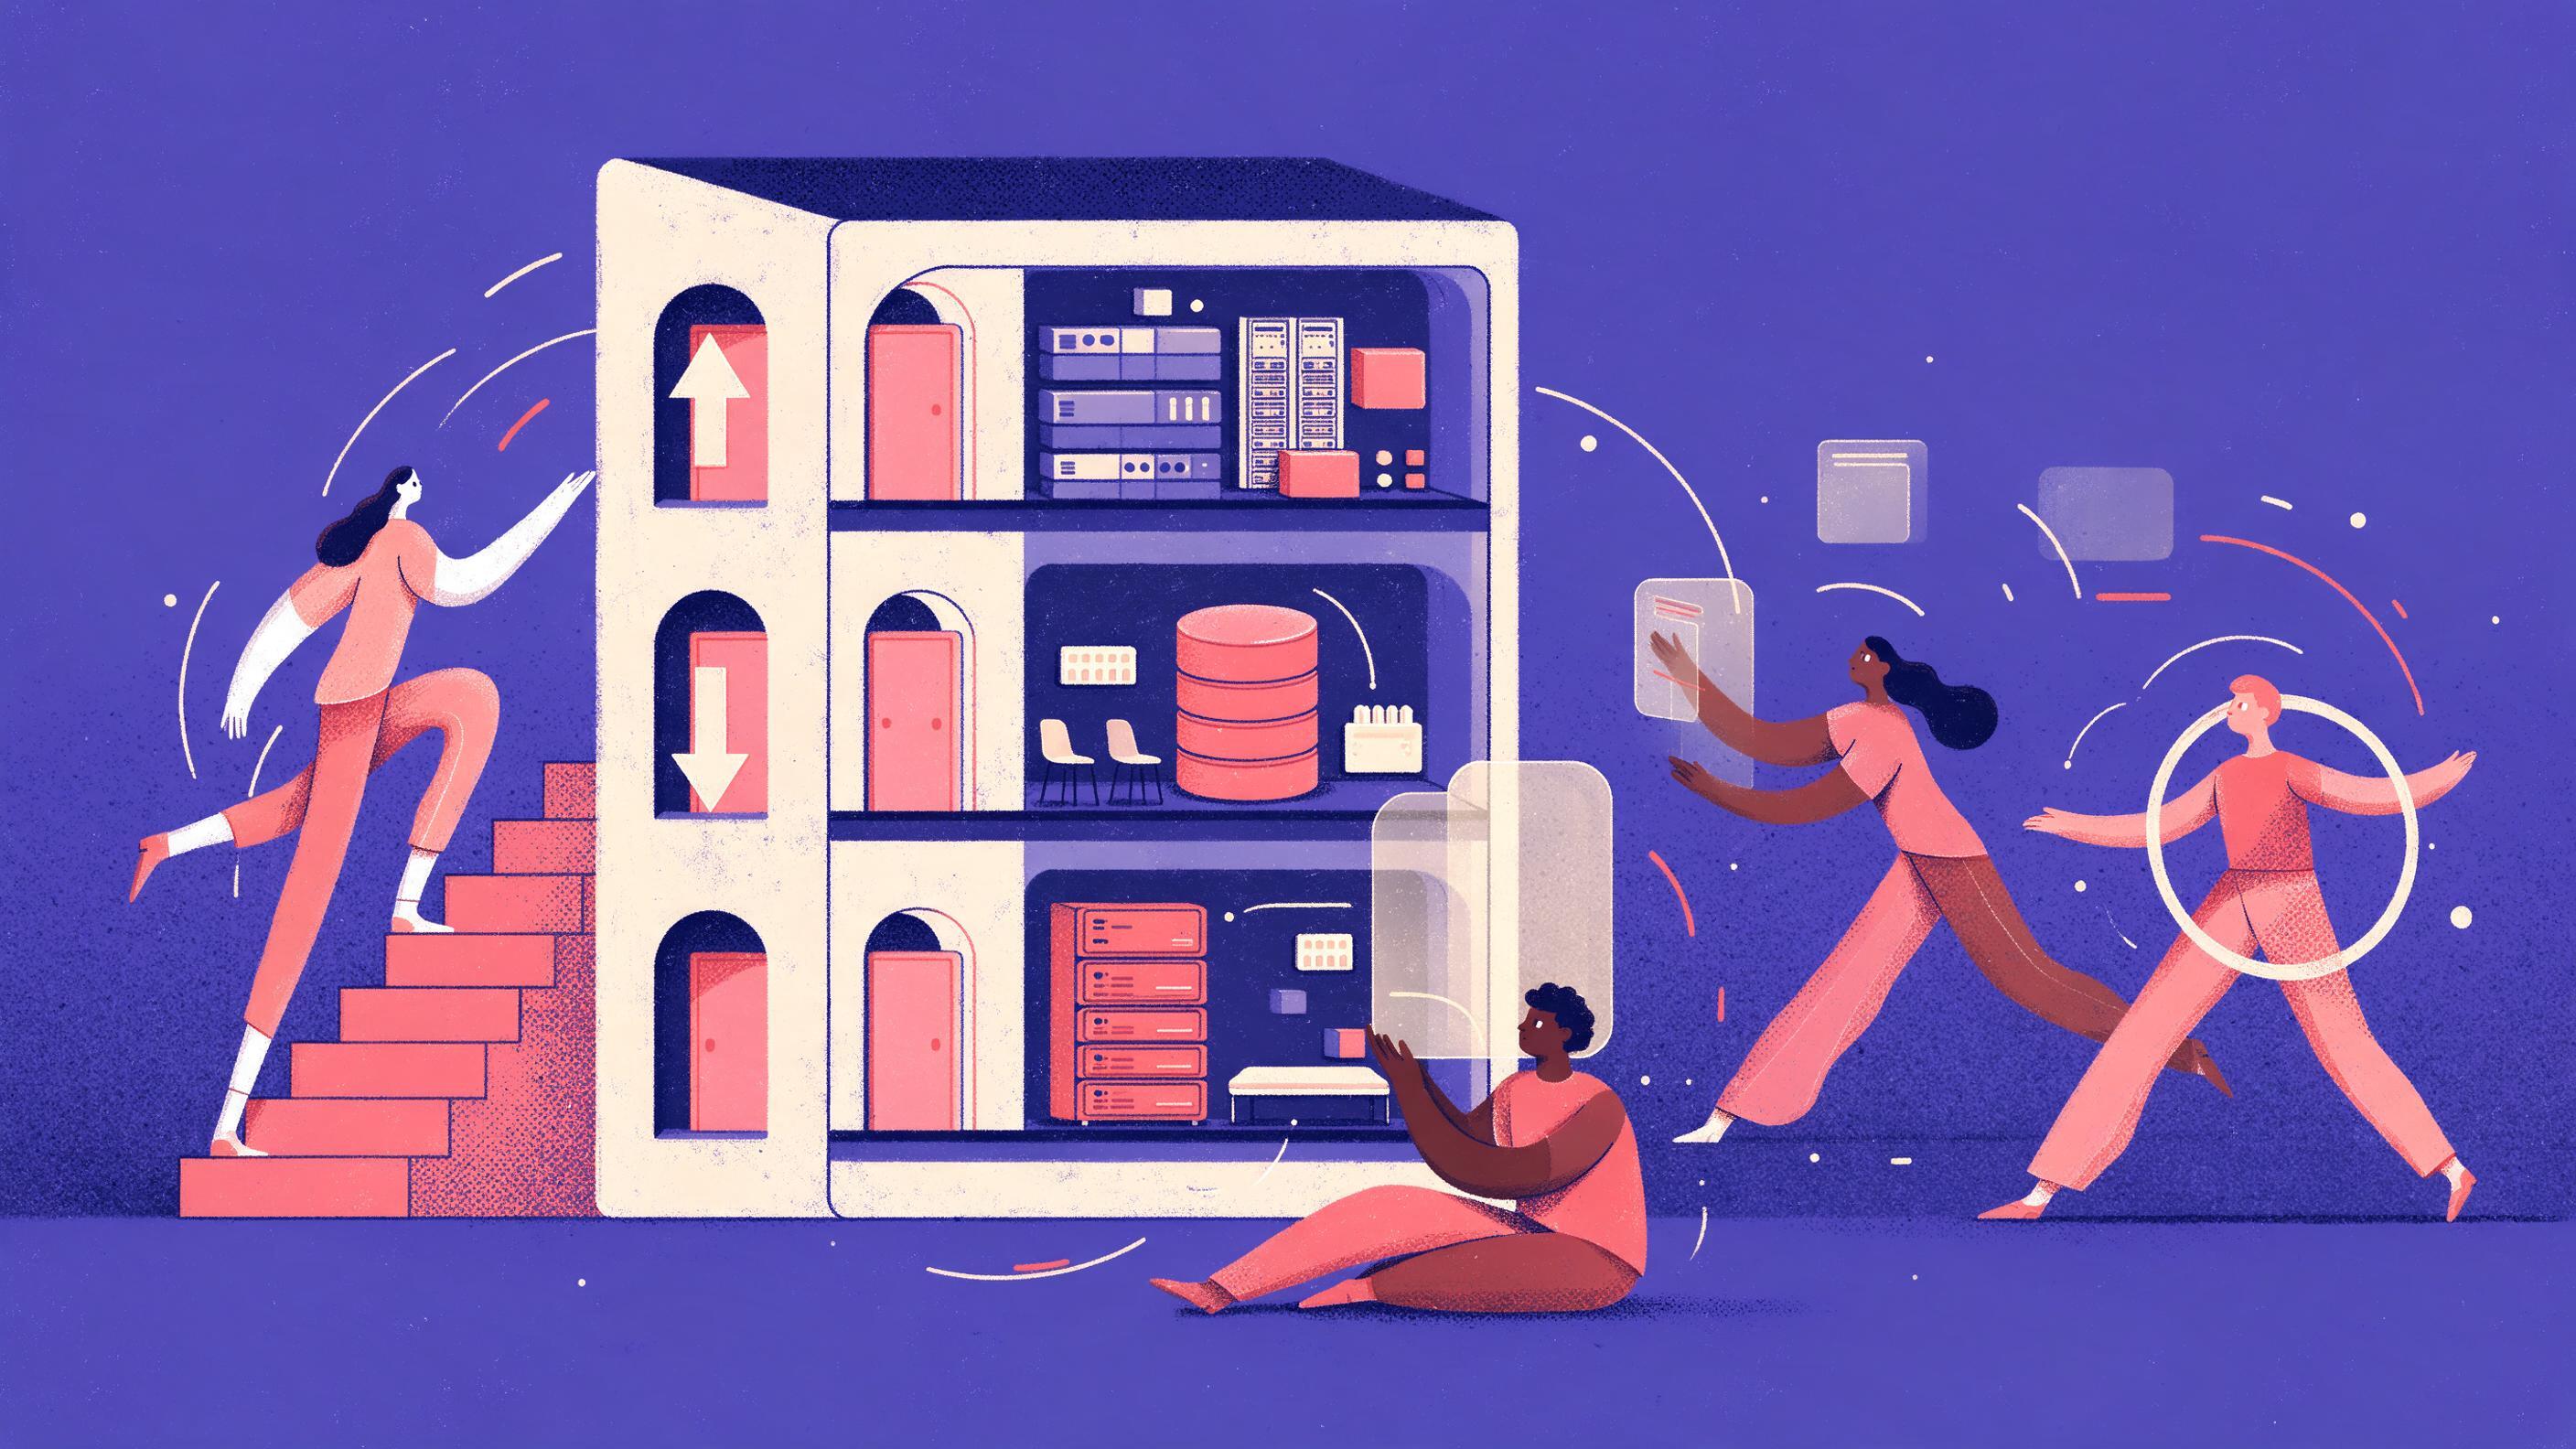
A cutaway view of a database server drawn as a building with labeled doors.
Key points

Key points

  1. 1Create a separate login for each agent and grant it only the verbs and tables its task needs.
  2. 2Keep DDL (CREATE, ALTER, DROP, TRUNCATE) in a role that a human holds, and make sure the agent cannot become that role.
  3. 3For retrieval and analytics work, make a dedicated read-only user rather than reusing a read-write one.
  4. 4Add a statement timeout and statement logging, so a bad query fails fast and leaves a record you can review.

The default is too much access

A coding agent that connects to your database does so with the credentials you hand it. Many teams hand it the application's own connection string, because that is the one already sitting in the environment file. Those are usually owner-level credentials, and an owner can run ALTER TABLE, DROP TABLE and TRUNCATE. One confused migration, or one instruction injected through a file the agent reads, is then enough to reshape production data.

This is not a hypothetical class of failure. Prompt injection is treated as a common and dangerous risk in agent deployments, with malicious text pushing agents toward unintended actions including data exfiltration through downstream tool calls, and NIST frames the same problem as agent hijacking, a form of indirect prompt injection hidden in content an agent consumes per this review of sandbox practice. The defensive conclusion most teams reach is the same: assume the model can be manipulated and limit what happens when it is. OpenAI's safety guidance argues exactly this, that the goal cannot be perfect detection of malicious input, so the system should constrain the impact of manipulation even when it succeeds, as summarized in the same Penligent analysis of coding agent sandboxes.

Sandboxes address the filesystem and network boundary. They rarely address the database boundary, because the agent reaches the database over the network using a credential, and the database enforces its own rules. That makes grants the place where you set what an agent may do to the data.

How the grant model actually works

PostgreSQL's privilege system is an allow list: roles get no access to database objects except what has been explicitly granted per Prisma's guide to managing privileges. This is good news for scoping agents, because it means a fresh login starts with nothing and you add only what the task requires.

The GRANT statement has two forms. One grants privileges on a database object (table, column, sequence, schema, database), and the other grants membership in a role per the PostgreSQL GRANT documentation. Table privileges include SELECT, INSERT, UPDATE, DELETE, TRUNCATE, REFERENCES and TRIGGER per the PostgreSQL GRANT reference. Note that TRUNCATE sits in that same list as an ordinary table privilege, which is one reason a read-write agent login needs care: TRUNCATE is not a schema change in PostgreSQL, so granting broad write access can let an agent empty a table even without DDL rights.

Working through a concrete case makes it clearer. In the Neon tutorial, a new role joe is created with LOGIN and a password, then a query on candidates fails with permission denied for table candidates. After GRANT SELECT ON candidates TO joe, the same query returns an empty result set instead of an error, and an INSERT still fails until INSERT, UPDATE and DELETE are granted per Neon's GRANT tutorial.

MySQL uses similar verbs but a coarser scope. The reference idiom moving from MySQL to PostgreSQL is GRANT ALL PRIVILEGES ON mydatabase.* TO 'myuser'@'localhost', which grants across every table in the database at once, whereas PostgreSQL requires object-level grants per this Stack Overflow comparison of the two models. If you are porting an agent workflow from MySQL, the instinct to grant at database scope will undo the whole exercise.

Role membership is what lets you keep a human-held destructive role out of the agent's reach. Roles with the INHERIT attribute that are members of other roles gain those privileges automatically, without a SET ROLE call per Prisma's privilege guide. Every role is a member of PUBLIC by default, which makes PUBLIC synonymous with everyone when you are writing grants per the same Prisma guide. So the two levers are membership and inheritance: grant a role to the agent login and decide whether that login inherits it.

A worked scoping recipe for Postgres

The recipe below builds three task roles and two agent logins. The human operator holds the DDL role; the agent logins are members of narrower roles and do not inherit by default.

-- 1. Shut the default door
REVOKE ALL ON SCHEMA public FROM PUBLIC;
REVOKE CREATE ON SCHEMA app FROM PUBLIC;

-- 2. Task roles carry verbs, not people
CREATE ROLE agent_read NOLOGIN;
GRANT USAGE ON SCHEMA app TO agent_read;
GRANT SELECT ON app.orders, app.customers, app.tickets TO agent_read;

CREATE ROLE agent_write NOLOGIN;
GRANT agent_read TO agent_write;
GRANT INSERT, UPDATE ON app.tickets TO agent_write;
GRANT USAGE ON SEQUENCE app.tickets_id_seq TO agent_write;

-- 3. DDL role, held by humans only
CREATE ROLE ddl_owner NOLOGIN;
GRANT CREATE ON SCHEMA app TO ddl_owner;
-- ownership of existing tables stays with the human admin login

-- 4. A login per agent, no inheritance surprises
CREATE ROLE agent_triage LOGIN PASSWORD :'pw' NOINHERIT;
GRANT agent_write TO agent_triage;
ALTER ROLE agent_triage SET statement_timeout = '5s';
ALTER ROLE agent_triage SET idle_in_transaction_session_timeout = '60s';

CREATE ROLE agent_answers LOGIN PASSWORD :'pw2' NOINHERIT;
GRANT agent_read TO agent_answers;
ALTER ROLE agent_answers SET statement_timeout = '15s';
ALTER ROLE agent_answers SET default_transaction_read_only = on;

Four decisions in that script carry most of the weight.

First, the REVOKE ... FROM PUBLIC lines. Because every role belongs to PUBLIC per Prisma's privilege guide, leaving PUBLIC with schema usage or create rights hands every future agent login a floor of access you did not choose.

Second, sequence privileges. A role that can INSERT into a table with a serial or identity column also needs USAGE on the backing sequence, which is granted with the ON SEQUENCE form of GRANT per the PostgreSQL GRANT documentation. Miss this and the agent's writes fail with a confusing permission error on an object it never named.

Third, NOINHERIT. Without inheritance, membership in a role does not automatically confer its privileges, and the session has to switch into that role to use them, which is the attribute the Prisma guide contrasts with the automatic inheritance path per Prisma's privilege guide. For an agent this is a feature: you can grant a role for later use without exposing it in the default session.

Fourth, default_transaction_read_only. This makes the analytics login refuse writes at the session level, which catches the case where someone later grants a write verb to agent_read by mistake. Combine it with the explicit SELECT-only grant rather than relying on either one alone.

The read-only user deserves its own paragraph. Retrieval and question-answering tasks need to scan tables an agent will never write, and they benefit from a login that physically cannot write. Build it as a role with SELECT only, membership in it for exactly the logins that do retrieval, and default_transaction_read_only = on. If the retrieval service uses a connection pool, check that the pool does not reset session settings per connection in a way that drops your defaults.

Choosing the right scope for each agent task

The useful question is not "read-only or read-write" but "which verbs on which tables". Use the table below as a decision aid when a new agent task lands.

Task typeVerbs neededObject scopeDDL?Timeout posture
Answer questions from data (RAG, reporting)SELECTNamed tables or views onlyNoBounded (seconds to low tens of seconds)
Triage and enrich ticketsSELECT, INSERT, UPDATEOne or two operational tablesNoShort
Backfill a column with computed valuesSELECT, UPDATETarget table plus lookupsNoMedium, run in batches
Apply a schema migrationFull DDLOne schemaYes, human holds itLong, human-supervised
Local development and testsSELECT, INSERT, UPDATE, DELETE, DDLA disposable branch databaseYes, on the branchGenerous

Two rules fall out of this. A schema migration is a different kind of act from a data write, so it runs under a different role and normally a different database entirely. And any task that only reads should be given the read-only login even if it is "probably" going to need writes later, because widening a grant is a one-line change and recovering deleted rows is not.

This is also where database branching fits. Rather than let an agent run migrations against shared state, give each agent task its own copy-on-write branch of the database, so a failed ALTER TABLE affects only the branch it ran on and the parent is structurally unchanged per the PingCAP write-up on TINE. The same write-up names the failure modes that a shared database produces under agent iteration: schema drift from a partial migration, irreproducible state where nobody can reconstruct which code, schema and environment produced an output, and rollback gaps where reverting a commit does not revert the ALTER TABLE per the PingCAP write-up. Grants and branches solve different halves of the problem: branches bound the damage of legitimate schema experiments, grants bound the damage of everything else.

A branch is not always available or affordable. The practical substitute is a per-task local database or a throwaway copy made from a seeded parent, created when the task begins and deleted when its pull request closes, with the connection string passed in DATABASE_URL per SpecStory's explanation of branching and seeding. The same guide is explicit that a branch runs the same engine and version as its parent, so an in-memory substitute such as SQLite in the tests of a PostgreSQL application can accept queries that production rejects per SpecStory. When the minimum is a fresh schema and seed script, that is enough to keep an agent out of shared state.

Test isolation interacts with grants

Teams that already wrap tests in transactions have a head start, because a rolled-back transaction cannot leave committed damage. Spring's test framework runs a test method inside a transaction that is rolled back by default, and warns that a preemptive timeout which moves the test onto another thread takes its work outside the test-managed transaction, so the actions commit even though Spring rolls back per the Spring Framework transaction management docs. That warning matters for agents: if the harness kills a test on timeout, the writes from the test may be the ones that survive.

The performance case is real, too. One team replaced truncation-based cleanup with per-test transaction rollback and reported their suite dropping from 447 tests in 245.87 seconds to 2.84 seconds, with per-test cleanup cost falling from roughly 40 to 60 milliseconds of truncate operations, sequence resets and connection overhead down to about 2 to 4 milliseconds of transaction start and rollback per this write-up on transaction rollback for test suites. Cheap cleanup means agents can iterate quickly without you relaxing their grants to make tests pass.

The decision rule: if the agent's job includes running the test suite, it needs write access only to the test database, never to a database that shares data with production. If the test database is a branch of production, that is acceptable because the branch is disposable; see the earlier practice of creating a branch when the task starts and deleting it with the pull request per SpecStory's branching guide.

Verify the boundary, then watch it

A grant you have not tested is a hope. Two checks catch most mistakes, and both are cheap.

The first is impersonation. Connect as the agent login and attempt a write the role should not have:

-- run as agent_answers
SET ROLE agent_answers;
INSERT INTO app.tickets (subject) VALUES ('should fail');
-- expect: permission denied for table tickets
SET ROLE ddl_owner;
-- expect: permission denied to set role "ddl_owner"

The second is a query against the catalog, run as the agent login, to list the tables and verbs it actually holds rather than the ones you intended. Run both checks as part of the provisioning script, not once by hand.

Then turn on auditing so that a future grant mistake shows up as a log line rather than an incident. PostgreSQL's pgAudit extension builds on native logging and can track changes to specific databases and tables, record the user who made the change, and redact sensitive values such as cleartext passwords from the logs per the AWS documentation for pgAudit. Point your alerting at schema changes executed by any login that is not the human DDL role, at writes from the read-only login, and at queries that hit the statement timeout.

If you run agents under a harness, make the database grant part of the agent's definition so it is provisioned the same way each time. A declarative configuration that names its credential source is easier to audit than a connection string copied into a shell profile, and the same holds for tools that already treat agent runs as first-class jobs with their own storage permissions: Windmill's volumes, for example, can be set to owner, read-only or read-write access per user or group, and a job with no permission on a volume fails per Windmill's sandbox documentation. Apply the same framing to the database: no permission, no job.

Where this fits with the rest of your stack

The boundary this article describes is only one of several. Sandboxing keeps an agent's filesystem and network reach small, and the isolation debate is worth understanding: software isolation, where a separate application intercepts system calls, differs from hardware isolation using virtualization features such as VT-x or AMD-V, and several high-profile agent incidents involved software isolation rather than hardware-level separation per Solo.io's guide to agent sandboxes. Teams running agents in VMs or microVMs still need database grants, because the database sits outside the sandbox.

For agents whose work is more about orchestration than raw access, the same least-privilege logic applies to whatever layer holds credentials on the agent's behalf. If you are choosing how to run the model side of an agent, a single API that covers text, image, video, audio and embedding models from one key keeps credential sprawl down: Quanta Inference is OpenAI-compatible and prepaid in US dollars, which makes it straightforward to give a task its own key and budget separately from the database credentials.

The shortest version of the whole article: the agent gets a login, the login gets a role, the role gets verbs on named tables, and the destructive verbs live in a role that only a human can assume. Everything else (timeouts, auditing, branches, test rollback) is reinforcement of that one idea.

FAQ

FAQ

Does a read-only Postgres user still need access to sequences?

No. A role that only runs SELECT does not need USAGE on a sequence, because it never requests a next value. Sequence grants matter for logins that insert into tables with serial or identity columns, since those inserts consume sequence values per the PostgreSQL GRANT documentation. Grant USAGE on the specific sequence to the write role and leave the read role without it.

Why did my agent login still have access after I revoked a grant?

Check PUBLIC first. Every role is a member of PUBLIC by default, so privileges granted to PUBLIC apply to every login including the new one per Prisma's privilege guide. Then check role membership and inheritance: a login with INHERIT that is a member of a broader role automatically holds that role's privileges per the same Prisma guide. Revoke from PUBLIC and audit membership before assuming the grant itself was wrong.

Is TRUNCATE covered by a DDL role or a data role?

In PostgreSQL, TRUNCATE is a table privilege listed alongside SELECT, INSERT, UPDATE and DELETE per the PostgreSQL GRANT reference. That means a broad read-write grant can include the ability to empty a table. Treat TRUNCATE as destructive in your role design and do not put it in the same role as everyday row updates.

What statement timeout should an agent login use?

Short enough that a runaway query cannot hold a connection, long enough that the task's legitimate queries finish. A retrieval or question-answering login is a good candidate for a tight bound, while a backfill that processes rows in batches needs longer. Set it per role with ALTER ROLE ... SET statement_timeout so every session that logs in inherits the same limit, and pair it with an idle transaction timeout so an open transaction does not block others.

Can the same grant design work for MySQL?

The verbs are similar but the scope is not. MySQL's familiar idiom grants at database scope with the mydatabase.* form, while PostgreSQL applies object-level grants per this Stack Overflow comparison. If your agent connects to MySQL, enumerate the tables explicitly and avoid the wildcard form, then apply the same rule: the agent's login gets the row verbs it needs, and account-level and DDL rights stay with a human.

Sources

Sources

  1. Sandboxes for Coding Agents - Penligent
  2. Managing privileges in PostgreSQL with grant and revoke
  3. PostgreSQL: Documentation: 9.1: GRANT
  4. PostgreSQL GRANT Statement
  5. Grant privileges for a particular database in PostgreSQL
  6. Database Branching for AI Agents: TINE Solves Schema ...
  7. What is database branching? | AI coding agents
  8. Transaction Management :: Spring Framework
  9. How Database Transaction Rollback Revolutionized Test ...
  10. Using pgAudit to log database activity - AWS Documentation
  11. AI sandboxes & volumes: isolated environments for coding agents
  12. What Is an Agent Sandbox? A Guide to Isolated Execution for AI Agents
About the author

About the author

Antonio Evans
Antonio Evans

Antonio Evans is the founder of Quanta Intelligence and a fractional CTO who builds HIPAA-ready AI systems for health and life-science companies. Before that he was technical co-founder of FriendsEAT for twenty years, CEO of Socialdraft, and a data engineer at IBM. Antonio lives with his dog Santino in Lisbon, Portugal.

All articles