
Marketing

When a Model Should Refuse to Edit a Row Instead of Guessing

Antonio Evans11 min read

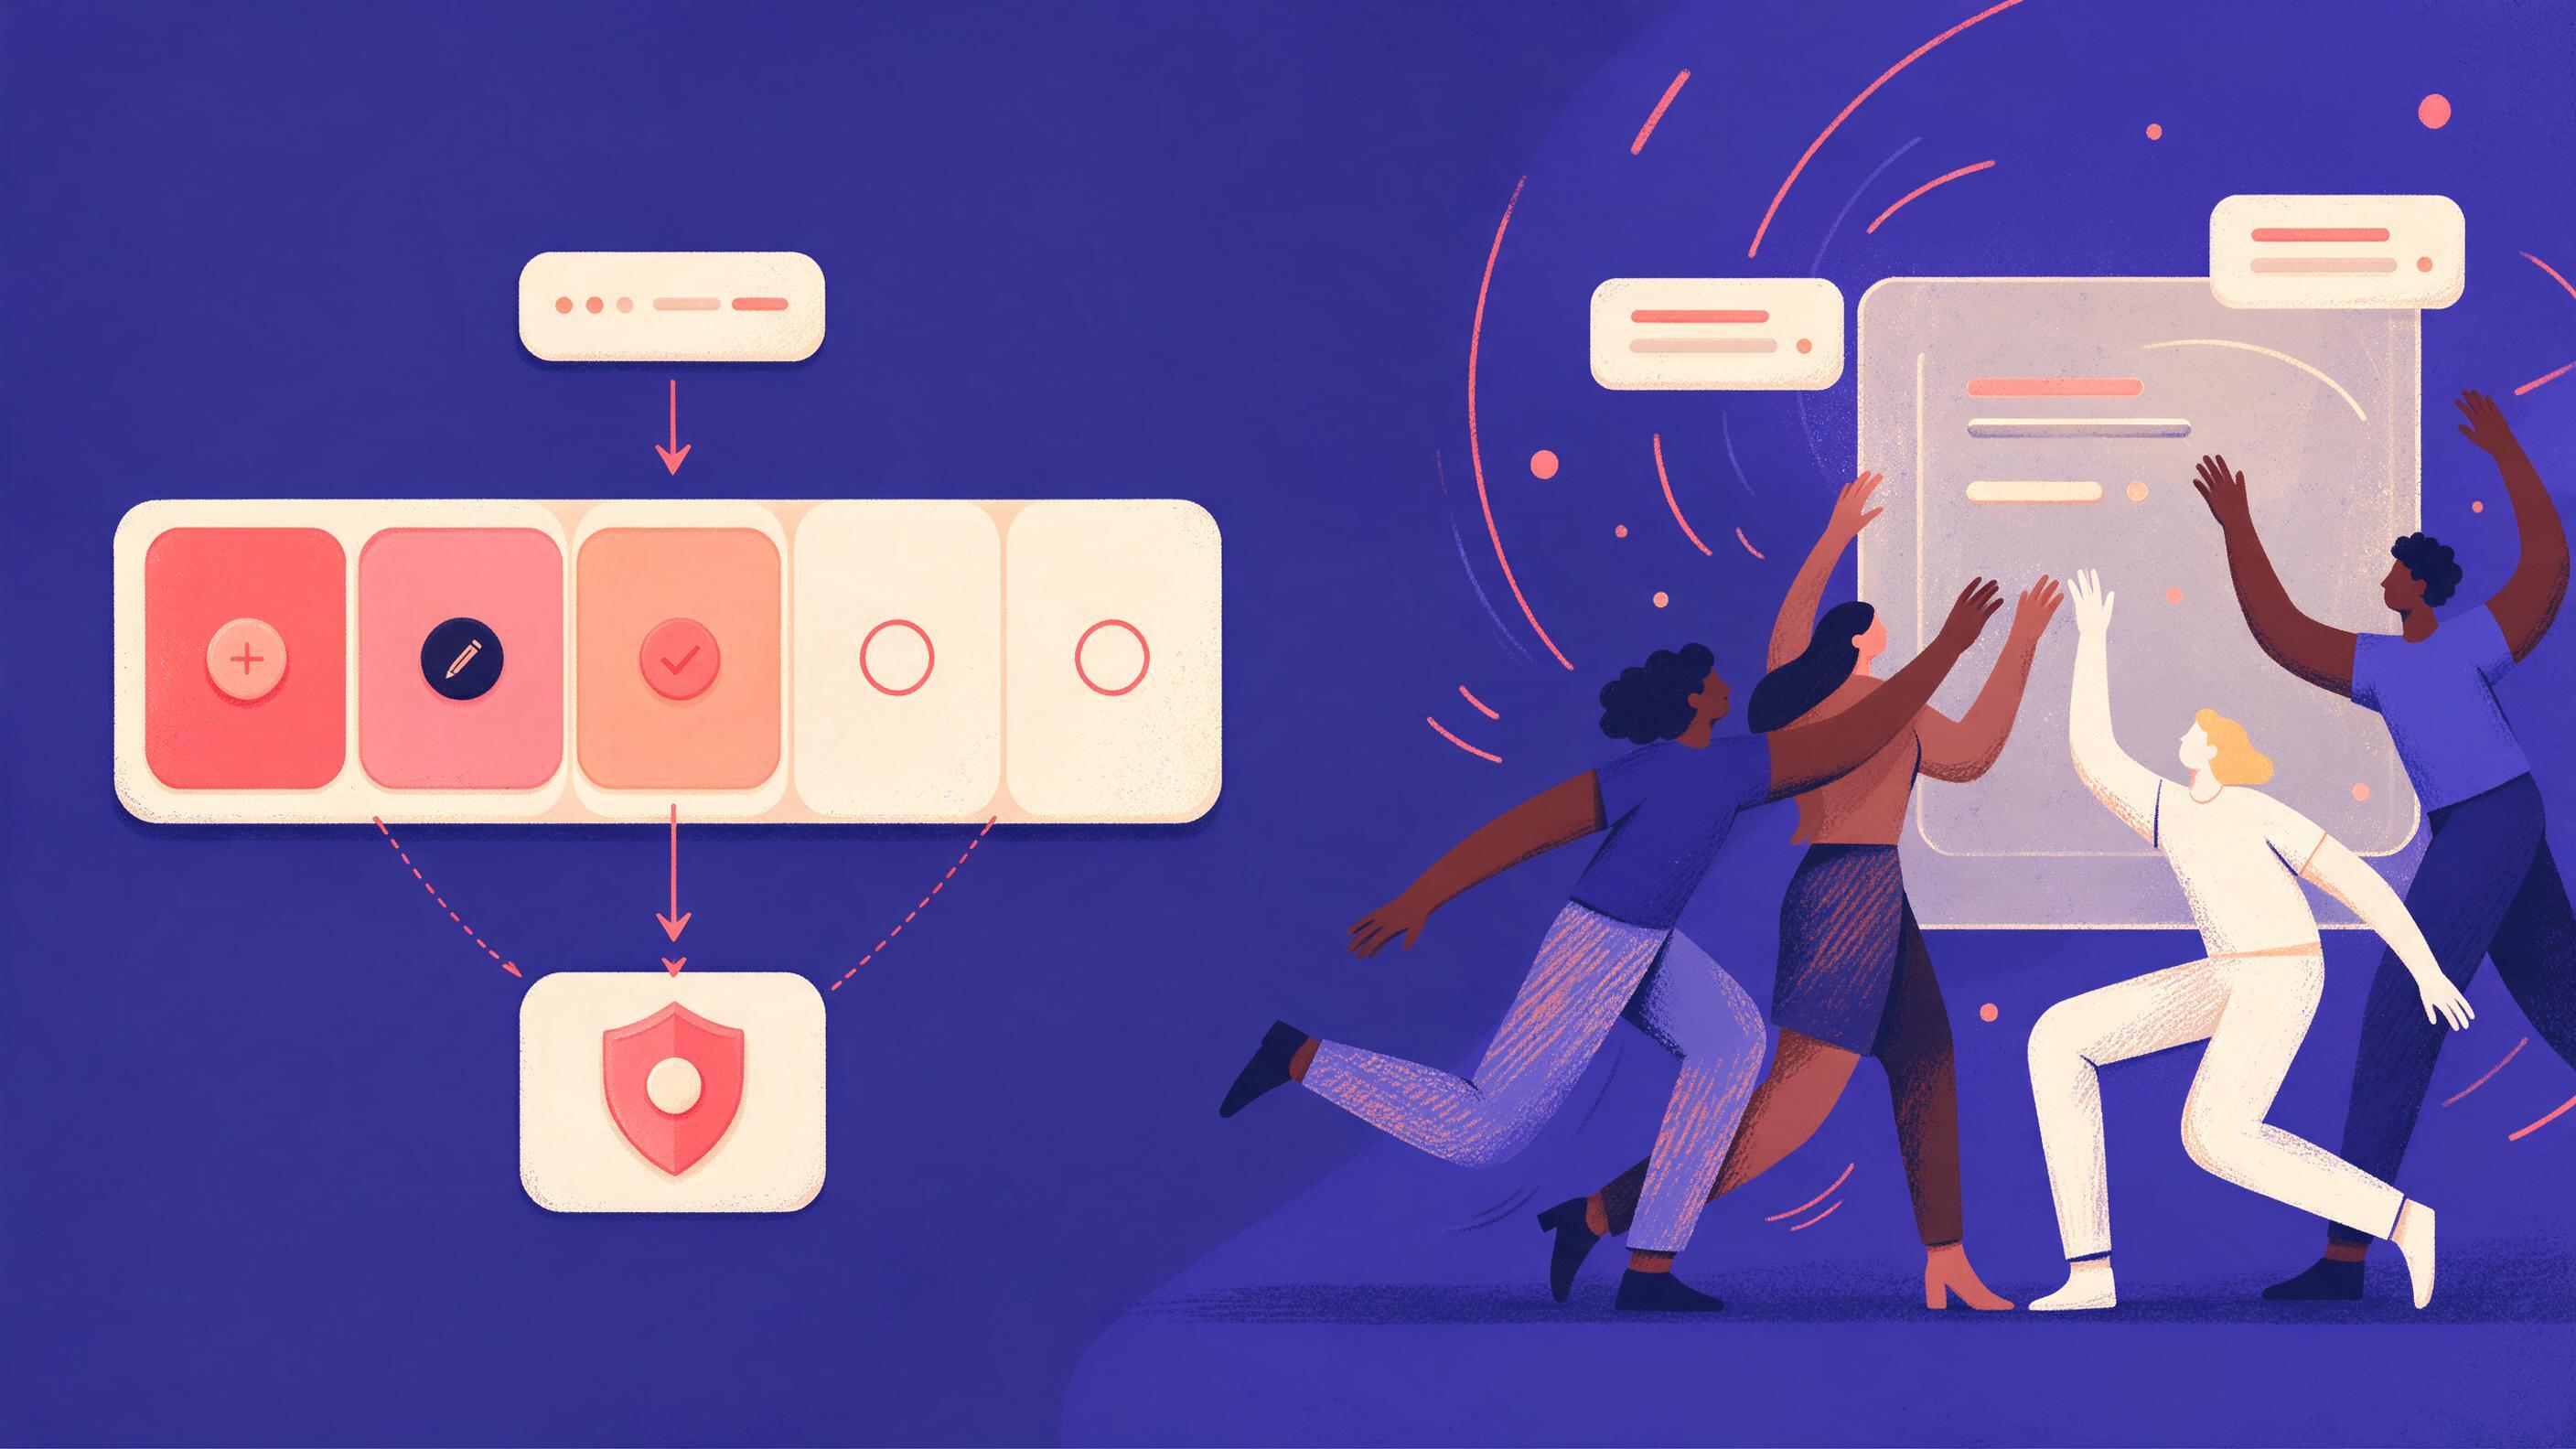
A split-panel diagram: on the left, a table row where three cells show edits and two show a hollow circle labeled no change, fed by a model box with a shield icon; on the right.
Key points

Key points

  1. 1A revision prompt that demands a value for every field leaves the model no way to say "the source does not support this," so it fills the gap with plausible text.
  2. 2Give every field three allowed outcomes: a value, an explicit no_change, or low_confidence, and require a per-field confidence score.
  3. 3Calibrate the acceptance threshold on a few hundred hand-labeled fields by plotting precision against threshold, then set it where precision stays above your tolerance for wrong values.
  4. 4Treat silent wrong edits and silent missed values as two separate failure modes with two separate review samples, because a refusal review that only checks wrong edits will let the missed values through.

Why a forced revision prompt manufactures errors

The failure is structural, not a model defect. When the output schema says every field must contain a string, and the source text runs out of evidence, the model has one legal move left: produce something that looks like the answer. Language models pick the most likely continuation given what they have seen, which is why confident, clean grammar arrives attached to invented content. Editors of AI drafts describe exactly this pattern: hallucinated statistics delivered with total confidence, and citations to sources that do not exist, each one hard to spot because the prose around it reads well (the AI content editing checklist).

In a chat window a human reads the paragraph and notices the number feels off. In a batch job that touches ten thousand rows, nobody reads anything. The invented value is written to the database, it validates because it is the right type, and it becomes indistinguishable from the values a human typed. The schema evolution literature calls this silent data corruption: data that appears valid but carries incorrect values, which is far more expensive than a loud deserialization failure because nothing alerts you (Conduktor's schema evolution guide).

There is a second reason forced prompts fail. Models are tuned to produce the kind of answer raters reward, and OpenAI's own researchers noted early that the resulting models "can overly hedge" or, in the opposite direction, over-commit when an instruction implies commitment (Leap on hedging in AI text). Your prompt is the instruction. "Fill in every field" is a commitment order.

The fix is to change the contract from "produce a value" to "produce a value or a justified refusal." Structured output is the mechanism, because a fixed schema with named fields and types is what lets downstream code treat a refusal as a first-class result rather than a parsing accident (PromptQuorum on structured output and JSON mode).


The decision rule: when to return no change

Write the rule once, state it in the system prompt, and check the model against it in evaluation. The rule has three branches per field:

  1. Return a value when the source text contains a passage that entails that exact value for that field, and you can point to it.
  2. Return no_change when the source text is silent, ambiguous, or contains a value that conflicts with the current record in a way the source does not resolve. Silence includes the case where the field is mentioned but the specific fact is not stated.
  3. Return low_confidence with a candidate value when the model has a candidate but the evidence is thin. This is different from no_change: it preserves the guess for a reviewer while preventing it from being auto-applied.

The distinction between branches two and three matters because they route differently. A no_change usually closes the item. A low_confidence opens a review task with a suggested answer attached, which is far cheaper for a human to adjudicate than a blank field.

Situation in the source textRecommended outcomeWhy
Field value stated explicitly and unambiguouslyValue, high confidenceDirect entailment, safe to automate above threshold
Field mentioned, specific fact absentno_changeAny value would be invented
Two conflicting statements, no resolution ruleno_change, flaggedThe model cannot know which wins; a human can
Candidate implied but not statedlow_confidence with candidatePreserves the lead without writing it to the row
Source value conflicts with current record, source is newerValue, with the conflict recordedLegitimate update, but log the overwrite
Field genuinely empty in the source and empty in the recordno_changeConfirming a non-change is not an edit

The last row is the one teams forget. If the model outputs an empty string to mean "no value here," you cannot tell it apart from "I found nothing and gave up," and you cannot tell it apart from a deliberate clear. Keep three distinct representations: a value, a no_change marker, and a null that means the field was cleared on purpose.

Designing the schema so no change is not empty

JavaScript's null represents the intentional absence of a value, and MDN notes that JSON can represent it faithfully, which is exactly why it is tempting to reuse it for refusals (MDN on null). Resist that. A null in a payload tells you nothing about why. SQL has the same ambiguity: a NULL means the value does not exist, is not known, or is missing, and those three cases call for different actions (Wikipedia on null in computing).

Here is a per-field envelope that keeps the cases apart:

{
  "field": "contract_end_date",
  "status": "value",
  "value": "2025-03-31",
  "confidence": 0.94,
  "evidence": "Term runs through 31 March 2025.",
  "reason": null
}
{
  "field": "contract_end_date",
  "status": "no_change",
  "value": null,
  "confidence": 0.88,
  "evidence": null,
  "reason": "Source mentions renewal but gives no end date."
}
{
  "field": "contract_end_date",
  "status": "low_confidence",
  "value": "2025-04-01",
  "confidence": 0.55,
  "evidence": "Term of twelve months from April 2024.",
  "reason": "Start date inferred from signature block."
}

Three properties of this envelope do the work. status is an enum, so downstream code branches on a closed set rather than guessing from missing keys. evidence is required for any value, which forces the model to ground the answer and gives reviewers a one-glance check. reason is required for any refusal, which is what makes the review sample useful rather than a wall of empty markers.

RepresentationMeaningDownstream action
status: valueModel asserts this value, above thresholdApply the edit, log it
status: value, below thresholdModel asserts a value but is unsureRoute to review with the candidate
status: no_changeNo evidence in source supports an editClose, but include in sampling
status: low_confidenceWeak candidate existsRoute to review, candidate prefilled
Deliberate clear (separate field or flag)The field should be emptiedApply only with human approval

Schema design discipline matters here the same way it does in streaming systems, where adding an optional field with a default is a compatible change but renaming a required one breaks every consumer (MLJAR's schema evolution prompt). If you ever change what a status string means, treat it as a breaking change with a migration, not a quiet edit to a prompt. Guidance on versioning and compatibility modes applies to the model's output contract as much as to a message queue (Conduktor's compatibility modes).

Calibrating the threshold from a labeled sample

Raw confidence scores are not probabilities. A reported 0.95 may be right 99 percent of the time on one field and 88 percent on another, because the score is relative to the model's own distribution, not to reality (human review and confidence calibration). The only way to know what a score means for your data is to measure it against known correct answers.

The procedure, in order:

  1. Build a labeled sample. Pull a few hundred fields from real records, stratified by field type and by source document type, and have a human record the correct outcome for each, including "no correct value exists." Two or three hundred fields per field type is a reasonable starting point; fewer than a hundred gives thresholds that jump around.
  2. Run the model and record the scores for each field exactly as production will receive them.
  3. Plot precision against threshold. For each candidate cutoff, count accepted edits above it and compute the share that match ground truth. Precision, not recall, is the metric that matters here, because accepted edits are the ones that write to the row.
  4. Pick the threshold where precision stays above your tolerance. If a wrong contract date costs a legal dispute, your tolerance might be 99.5 percent. If a wrong tag on a marketing list costs a bad email, 95 percent may be fine. The threshold is a business decision, not a model setting.
  5. Set a second, lower cutoff for the review queue. Fields between the two cutoffs go to human review with the candidate prefilled; fields below both return no_change and close.

A worked example makes the trade visible. Suppose you score 300 date fields and sort into bands:

Confidence bandFields in bandCorrectPrecision
0.90 to 1.0012011999.2%
0.80 to 0.90706795.7%
0.70 to 0.80554683.6%
below 0.70553156.4%

If your tolerance is 99 percent, the auto-accept threshold is 0.90: 120 fields apply unattended, 125 go to review, and 55 close as refusals. If your tolerance is 95 percent, you accept 190 fields and review 110. Notice what the table also reveals: 55 fields scoring below 0.70 were right 56 percent of the time, so refusing all of them costs you 31 correct edits. That is the price of safety, and it should be a number you chose, not one the default settings imposed.

Two warnings from the research. First, calibration is not uniform across methods: a study of seven models found self-reported confidence better calibrated than self-consistency voting, with average expected calibration error of 0.166 versus 0.229, despite the voting method costing five times the inference (When Can We Trust LLM Graders). Second, scores are strongly top-skewed, creating a confidence floor: if almost nothing scores below 0.7, a threshold at 0.75 will look precise in the sample and accept everything in production. Check the distribution before you trust the cutoff.

A worked walkthrough: invoice dates from messy receipts

Take a plumbing firm extracting invoice dates. The calibration literature presents a version of this case with numbers: across a mixed corpus the system reports 97 percent overall accuracy, but standard invoices hit 99.5 percent on dates while handwritten receipts reach 60 percent, poor OCR scans 72 percent, and international formats 45 percent (human review and confidence calibration).

The aggregate hides the disaster because standard invoices dominate the volume. This is the same trap as a single precision number computed across all fields. Fix it by calibrating per segment, not per system. A date field on a standard invoice might carry an accept threshold of 0.85; the same field on a handwritten receipt might need 0.97, or might simply route every instance to review because no score in that segment has ever calibrated above 90 percent.

The per-row pattern generalizes. Sigma's AI columns run a prompt against every row and return either text or structured JSON, with a preview on the first hundred rows before the prompt applies to the whole table (Sigma AI columns). That preview step is your free calibration sample: if you label the hundred previewed rows, you have a first cut at thresholds before a single production row changes. The same preview discipline applies to any batch enrichment, whether it writes to a warehouse column or a CRM field.

When you need the same extraction across text, scans, and transcripts, routing each through a single endpoint keeps the envelope and the confidence field consistent across modalities, which is what makes one calibration table possible; Quanta Inference exposes text, image, audio and embedding models through one OpenAI-compatible key (https://quantaintelligence.ai/inference).

Reviewing the refusals: two samples, not one

A refusal path that nobody audits becomes a place where correct edits go to die. There are two failure modes and they hide from each other:

  • Wrong edits: the model said value and the value is incorrect. These corrupt data. You find them by sampling accepted, above-threshold edits.
  • Missed values: the model said no_change and a correct value was available in the source. These stall data. You find them only by sampling refusals.

Sampling only one direction is the standard mistake. Teams that audit accepted edits catch corruption and never learn that half their refusals were lazy. Teams that audit refusals catch laziness and ship corrupted values. The calibration guidance is explicit that high-confidence items deserve sampling too, precisely because nobody looks at them and a novel error pattern can settle in unnoticed (human review and confidence calibration).

Run a weekly loop with fixed sample sizes:

  1. Draw 50 random refusals. For each, have a reviewer read the source and answer one question: was a correct value available? Track the miss rate per field and per source type.
  2. Draw 50 random accepted edits above threshold. Check each against its evidence string. A value whose evidence does not actually support it is a grounding failure, not a confidence failure.
  3. Re-check every no_change where the reason is generic. Reasons like "not stated" on a document type that usually states the fact are a prompt problem, not a data problem.
  4. Sort the queue by uncertainty, not arrival. Reviewers should see the lowest-confidence fields first, then ambiguous source documents, then document types with historically poor accuracy; an even spread wastes capacity on fields the model handles well.
  5. Feed findings back into the prompt and the thresholds, and log the change. If refusal rates spike after a prompt edit, you have evidence the edit loosened the rule.
SampleWhat a hit looks likeFix it points to
RefusalsCorrect value was in the sourceLower the threshold for that field, or improve the prompt's evidence rule
Accepted editsValue contradicts its own evidence stringGrounding failure, tighten the evidence requirement
Accepted editsValue right but evidence emptyModel is guessing and passing; require evidence or refuse
Low-confidence queueReviewer agrees with candidate nine times in tenThreshold too high for that field; recalibrate
Any statusRefusal rate above 40 percent on a field you know is well populatedPrompt is over-refusing; check the rule wording

Putting it together in the prompt

The prompt itself is short once the schema carries the weight. State the three outcomes, the evidence requirement, and the bias toward refusal, and nothing else about formatting, because structured output enforces the shape (how to prompt for structured output). Practitioners building against strict schemas report that field names and descriptions in the schema do real work alongside the system instruction, so name fields for what they mean and describe the refusal values in the schema text (getting structured output from LLMs).

The bias statement is the part most teams omit. Write it plainly: when evidence is missing, returning no_change is the correct answer and is scored as a success, not a failure. Without that sentence, the model reads every field as a request to fill and behaves accordingly. The editing literature makes the same point from the other side: AI drafts fail by sounding confident when the substance is thin, and the fix is to demand sourced specifics rather than accept the fluent default (the AI content editing checklist).

Two operational notes close the loop. Keep the reason and evidence fields in your storage, not just in the transient response, because they are what makes the review loop possible six months later. And version the prompt alongside the schema, so a change in refusal behavior can be traced to a change in instructions rather than blamed on the model.

When the review loop outgrows a spreadsheet, a specialist can wire the envelope, the calibration table, and the two-sample review queue into your actual pipeline; Quanta experts take your context and hand back finished deliverables (https://quantaintelligence.ai/agents).

FAQ

FAQ

What exactly should the model output when it has no evidence for a field?

It should output an explicit status of no_change with a null value and a reason string, never an empty string or a bare null. Empty values are indistinguishable from deliberate clears and from parsing failures, so keep the three cases in separate representations. The reason string is what lets a reviewer decide whether the refusal was correct without re-reading the whole source.

How many labeled fields do I need before setting a threshold?

A few hundred per field type, stratified across source document types, is a practical starting point. Fewer than a hundred tends to produce thresholds that shift sharply when you add data. The goal is not a perfect curve but enough points per confidence band that you can see whether precision holds above your tolerance, and the band sizes should be printed alongside the precision so a thin band is obvious.

Is a model's self-reported confidence score trustworthy?

Only after calibration. Raw scores are relative, and the same number can mean very different accuracy on different fields. Research comparing methods found self-reported confidence better calibrated than self-consistency voting across seven models, with average expected calibration error of 0.166 versus 0.229, but both are far from perfect and scores cluster at the top. Calibrate against labeled data before you gate any write on a score.

Why not just review every field a human might care about?

Reviewer capacity is the binding constraint, and spreading it evenly wastes it on fields the model handles reliably while leaving uncertain fields waiting. Route by uncertainty: lowest confidence first, then ambiguous documents, then document types with poor historical accuracy. Sample the high-confidence accepted edits as well, because nobody looks at them in normal operation and that is where a systematic error hides (human review and confidence calibration).

What is the fastest way to tell whether the refusal path is working?

Compare refusal rates and miss rates per field over time. A refusal rate that climbs while the sampled miss rate stays near zero means the model is correctly declining rather than guessing. A refusal rate that falls while the miss rate rises means the prompt or threshold loosened too far. Track accepted-edit precision from the second sample alongside these, because one number alone can improve while the other degrades.

Sources

Sources

  1. AI Content Editing Checklist: 15 Steps Before You Publish
  2. Schema Evolution: 8 Kafka Best Practices
  3. Hedging Words in AI Text: Why 'It's Important to Note' Flags | Leap
  4. Structured Output & JSON Mode in LLMs: When to Use, Examples
  5. null - JavaScript - MDN Web Docs
  6. Null
  7. Schema Evolution Strategy AI Prompt - Data Engineer
  8. 5.5, Human Review & Confidence Calibration | AI Cert Guides
  9. When Can We Trust LLM Graders? Calibrating Confidence for ...
  10. Introducing AI Columns
  11. How to effectively prompt for Structured Output
  12. Getting Structured Output from LLMs: Guide to Prompts, Parsers, and Tools
About the author

About the author

Antonio Evans
Antonio Evans

Antonio Evans is the founder of Quanta Intelligence and a fractional CTO who builds HIPAA-ready AI systems for health and life-science companies. Before that he was technical co-founder of FriendsEAT for twenty years, CEO of Socialdraft, and a data engineer at IBM. Antonio lives with his dog Santino in Lisbon, Portugal.

All articles
