Business

When the Review Sample Is Too Small to Trust

Antonio Evans9 min read

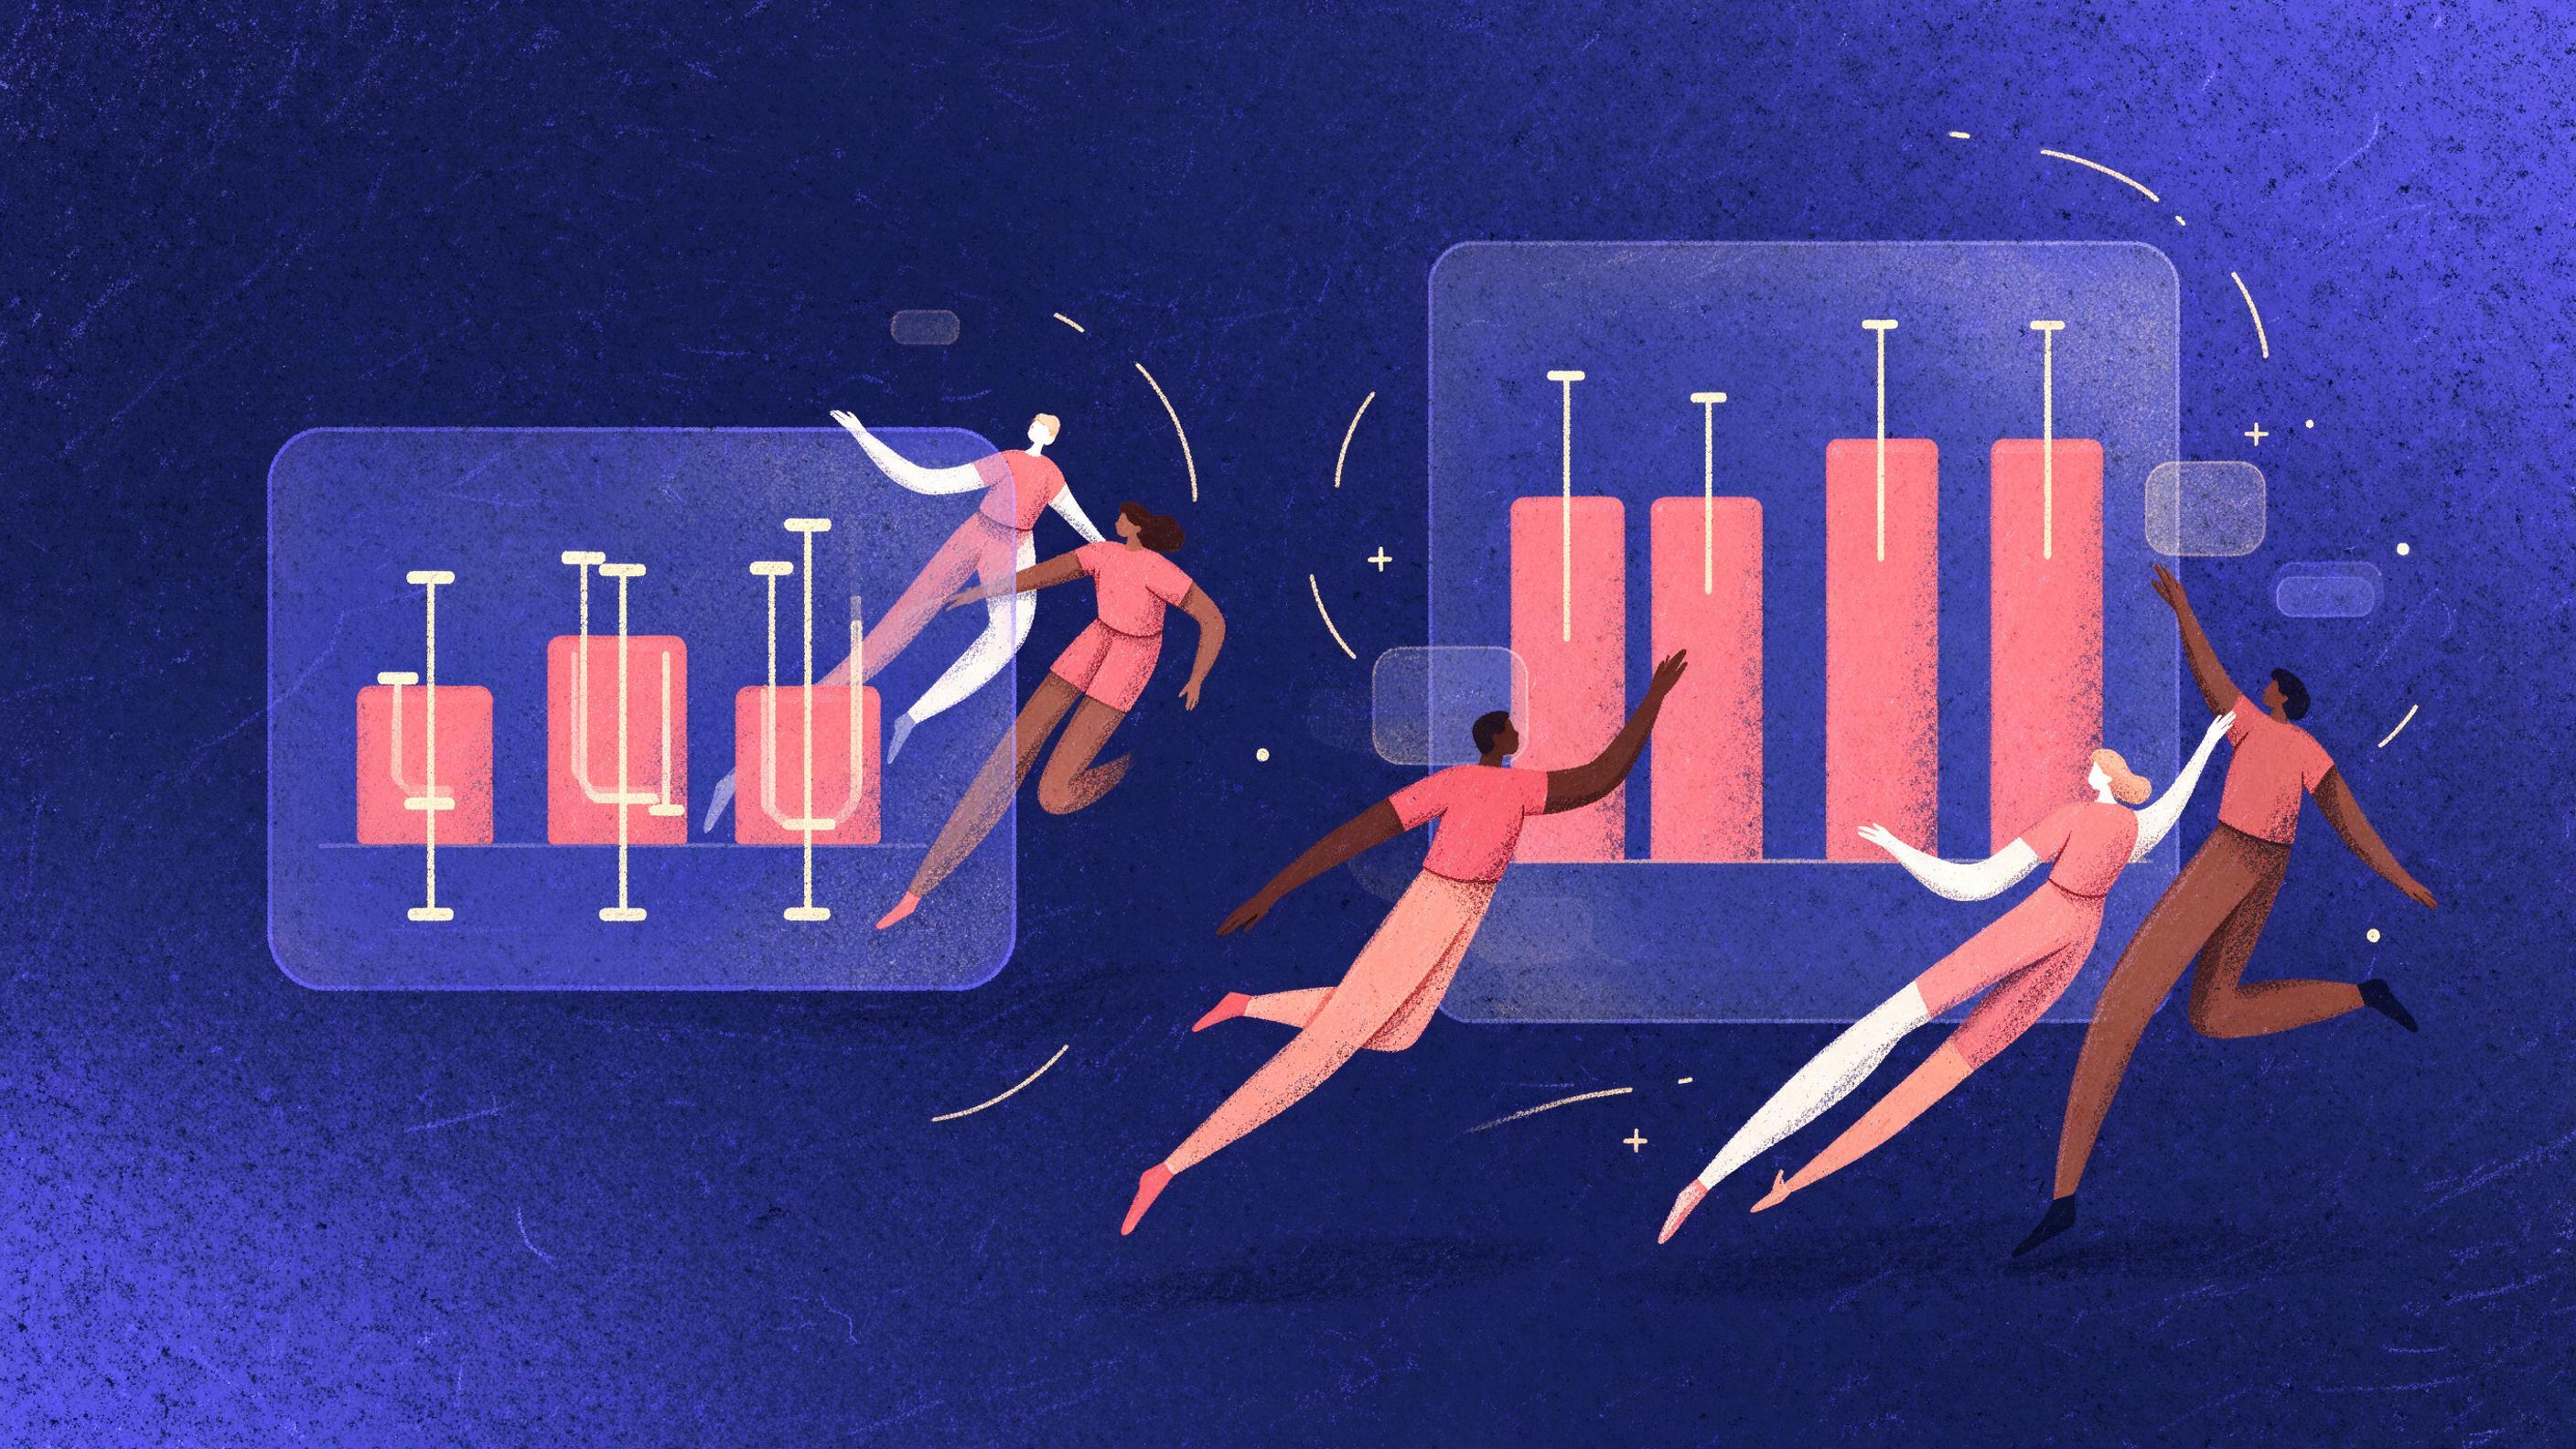
A split scene: on the left, a tiny bar chart with three bars and error bars so wide they overlap, labeled 'small sample'; on the right, a larger bar chart with narrow error bars and a clear gap between groups.
Key points

Key points

  1. 1A review sample is too small to trust when the reported difference between groups is smaller than the uncertainty implied by its sample size.
  2. 2Red flags include missing sample sizes, percentages without raw counts, and averages reported with no measure of spread.
  3. 3Computing a 95% confidence interval for the difference takes one formula and tells you whether an apparent improvement could be sampling noise.
  4. 4Pair the interval with a preregistered decision rule so the sample size, endpoint and stopping condition are fixed before data collection.

Start with the uncertainty, not the headline

Most review reports lead with the average. "The new flow scored higher, so it is better." That sentence can be true and still be useless, because it hides the number that decides whether the gap means anything: how much the individual scores varied.

Sampling noise is the reason. Any sample is a draw from a larger population, and a second draw would give different numbers. The confidence interval is the standard way to express how much a statistic would bounce around under repeated sampling: it is a range around the point estimate, built from the standard error, and the 95% level is the most common convention in applied reporting Hazra's overview of confidence intervals. The width is driven by three things: the confidence level you choose, the sample size, and the variability in the sample. A 99% interval is wider than a 95% interval for the same data the same editorial.

The decision rule falls out of that. If the interval for the difference between two groups includes zero, the data are consistent with no real difference at all. A review that reports a gap but never the interval is asking you to trust a point estimate that may be mostly noise.

There is a second reason to ask for the interval rather than the p-value. A p-value tells you whether a difference is detectable under assumptions; the interval tells you how large the difference plausibly is. When the choice is whether to ship a change, the size matters as much as the existence Hazra on clinical importance versus statistical significance.

A diagnostic checklist for underpowered reviews

Run this list against any review report, internal or external, before you act on its conclusion. Each row is a check you can complete in a few minutes.

CheckFailing signalWhat good looks like
Sample size stated"Dozens of users", no group countsExact n per arm, plus recruited versus analyzed
Variance reportedMean or percentage onlyStandard deviation, standard error, or a confidence interval
Raw counts behind percentages"42% preferred X", no denominators21 of 50, with the denominator visible
Stopping rule declaredAnalysis ends when a nice result appearsEndpoint and sample size fixed before collection
Null results shownOnly the winning subgroup is discussedAll comparisons reported, including ones favoring the control
Selection describedNo note on who was includedEligibility, exclusions and dropouts listed
Decision tied to a threshold"Looks better"A pre-set margin the interval must clear

Two rows deserve emphasis. First, percentages without denominators are the most common way small samples get dressed up as big findings: "60% of reviewers preferred the new interface" sounds firm until you learn it was 3 of 5. Second, a missing stopping rule turns a small sample into an unreliable one, because optional stopping lets a team keep adding cases or re-cutting subgroups until something crosses the threshold. The fix is preregistration, specifying the research plan in advance and submitting it to a registry so planned and unplanned analyses can be told apart the Center for Open Science. Its guidance notes that the same data cannot be used both to generate and to test a hypothesis without reducing the credibility of the result the same page.

Why small samples widen everything

There are two separate mechanisms, and conflating them causes most confusion.

The first is arithmetic. The standard error of a mean is the sample standard deviation divided by the square root of n, so uncertainty shrinks with the square root of sample size. Quadruple the sample and you roughly halve the width of the interval. This is why halving a survey's margin of error approximately quadruples the required sample under the usual proportion formula a sample-size planning guide with the formula and worked values. That page gives a concrete planning number: at 95% confidence with an anticipated proportion of 50% and a margin of plus or minus 5 percentage points, the large-population calculation is 384.16, rounded up to 385 completed responses same source. The same page warns that the margin covers sampling uncertainty under the stated design and does not include leading questions, missing coverage or systematic nonresponse, so a precise estimate of a biased group can still mislead same source.

The second is distributional. With small samples and unknown population standard deviation, substituting the sample standard deviation into a normal-based formula is no longer valid, and the standard fix is Student's t distribution with n minus 1 degrees of freedom, which has heavier tails a worked treatment of small-sample confidence intervals. That switch matters in practice: it makes the interval wider, which is exactly the correction a small review needs. The t interval assumes the underlying values are roughly normal, so with very small samples also check for extreme outliers that would break that assumption same source.

One terminology caution. A pilot or feasibility study is not designed to estimate an effect precisely; it exists to test whether the design, measures, recruitment and procedures will work at scale, and its sample size should be justified by that goal rather than by a formal power calculation Kunselman's overview of pilot studies. Reviewers frequently cite a pilot's apparent effect as if it were a confirmatory result. It is not, and a common warning is that pilot effect estimates are unreliable inputs for powering the main study same source. If a review is explicitly a pilot, judge it on feasibility questions, not on the size of the gap it reports.

Worked example: 8 reviewers against 8

Suppose an internal review compares two onboarding flows. Group A (current) has 8 reviewers; Group B (redesign) has 8. Each reviewer completes a timed task, and the outcome is seconds to completion. The summary: Group A mean 100 seconds, standard deviation 20 seconds; Group B mean 88 seconds, standard deviation 22 seconds. The reported "12% faster" looks like a win.

Compute the 95% interval for the difference in means. With small samples and unknown population standard deviations, the standard error of the difference is the square root of (s1 squared over n1 plus s2 squared over n2):

s1 = 20, n1 = 8   ->  s1^2 / n1 = 400 / 8  = 50.0
s2 = 22, n2 = 8   ->  s2^2 / n2 = 484 / 8  = 60.5
sum = 110.5  ->  standard error = sqrt(110.5) = 10.51 seconds

difference = 100 - 88 = 12 seconds

For a small-sample interval, use the t critical value. A conservative choice is degrees of freedom equal to the smaller group size minus one, which is 7; the 97.5th percentile of t with 7 degrees of freedom is about 2.365. A more precise approach uses the Welch-Satterthwaite approximation to the degrees of freedom, which lands near 14 and gives a critical value near 2.16. Take the conservative one:

margin = 2.365 * 10.51 = 24.9 seconds
interval = 12 +/- 24.9 = (-12.9, 36.9) seconds

The interval runs from about 13 seconds in favor of the redesign to about 37 seconds in favor of the current flow. It contains zero. Under the usual reading, this review has not shown a difference: the data are consistent with the redesign being meaningfully faster, slightly slower, or identical. Reporting "12% faster" as a conclusion is exactly the error the checklist is designed to catch.

Now the decision rule. Suppose the team agreed in advance that the redesign would ship only if the lower bound of the interval showed at least a 5 second improvement. The observed lower bound is negative, so the rule says do not ship, and the honest follow-up is a larger sample, not a reinterpretation. To halve the margin from roughly 25 seconds to roughly 12.5, you need about four times the observations per group under the square-root relationship, so plan for around 32 per arm. That number is a planning approximation from the formula above, not a guarantee. The right way to set it is a power calculation that states the effect you care about detecting, the alpha level and the target power. Power is the probability of detecting a difference that genuinely exists; a study with too few subjects is underpowered and may miss a real effect a primer on power analysis and its role in replicability. Sample size planning tools make the arithmetic routine by letting you set anticipated means, variance, alpha and power ClinCalc's sample size calculator. The drivers are the same everywhere: rarer outcomes, higher variance and smaller effects all demand more subjects the same calculator's explanation.

One more subtlety worth knowing before you argue about a result. Choosing the sample size after seeing the data is not a fix; it converts a planned test into an unplanned one. If you must collect more, treat it as a new study with its own preregistered plan, or model it explicitly as a sequential design, which preregistration guidance treats as a distinct case from optional stopping the Center for Open Science.

Reading a review report in ten minutes

A short routine keeps the diagnosis consistent across reviewers and vendors.

  1. Find the denominators. Write down n per group and the number analyzed after exclusions. If either is missing, stop and ask.
  2. Find the spread. Locate the standard deviation, standard error or interval. If only means or percentages appear, request the raw data or the variance.
  3. Compute the interval for the difference yourself. Use the conservative t value if group sizes are small; the t table entry for the relevant degrees of freedom is the number you need the small-sample interval walkthrough.
  4. Check whether the interval clears your pre-agreed margin, not just zero. A result that excludes zero but sits far below your practical threshold is detectable and operationally irrelevant.
  5. Check the analysis history. Was the endpoint fixed before collection? How many subgroups were examined? Every extra comparison raises the chance that one looks impressive by luck.
  6. Record the verdict as one of three: usable, underpowered but informative for planning, or uninterpretable.

That third category is not a failure of the review. It is a finding about the review's design, and it should route to the same kind of structured learning that incident reviews use: a blameless postmortem produces a written account of what happened and a list of steps to prevent recurrence, and its value comes from institutionalizing continuous improvement rather than assigning fault PagerDuty's guide to postmortems. The same framing applies to AI-assisted reviews, where a structured postmortem with a standard format, tracked action items and dissemination beyond the immediate team is what turns an incident into organizational learning, with a note that timing matters because too soon and emotions interfere while too late and memory fades Pertama Partners on AI incident postmortems. An underpowered review that is documented as underpowered, with the specific numbers and the sample size needed next time, saves the next team from repeating it.

Where this gets harder: reviews of AI-assisted work

Reviews of model-assisted workflows add two wrinkles that inflate the risk of a too-small sample.

The first is variance. Model outputs vary run to run and prompt to prompt, so the spread within a group can be much larger than reviewers expect from human-only work. Higher variance widens intervals and demands more observations for the same precision ClinCalc's explanation of the drivers of sample size. A review that ran each prompt once per reviewer is measuring the reviewers, not the system's variability.

The second is iteration. Agentic workflows produce intermediate steps, tool calls and retries, and each of those can be a place where an evaluation quietly becomes exploratory. Teams building agents already have to engineer for cost and observability, tracing every reasoning step and tool call across an execution cycle, precisely because the loop's behavior is not visible from the final output Oracle's description of the agent loop. That tracing is also what makes a review auditable: if you cannot see how many steps ran and which tools fired, you cannot tell whether the sample was comparable across arms.

A third wrinkle is scope. Autonomy is a spectrum, and more autonomy is not automatically better; useful autonomy is bounded by permissions, budgets, approvals and explicit stopping rules a guide to autonomous agents. A review that compares a bounded configuration against an unbounded one is comparing two different systems, and the difference in outcomes may reflect the guardrails rather than the model. Fix the configuration and the stopping condition before you sample, or the interval you compute will be measuring the wrong thing.

When a team needs to run these reviews across text, image and audio models without rebuilding the evaluation harness for each provider, one option is a single OpenAI-compatible endpoint with prepaid, dollar-denominated billing, which keeps the sampling and logging code identical across model types: Quanta Inference.

FAQ

FAQ

How small is too small?

There is no universal cutoff, but two practical markers help. With small samples and an unknown population standard deviation, the normal approximation stops being valid and you should use the t distribution, which widens the interval the small-sample interval walkthrough. More decisive than any number is the interval itself: if it includes zero, the sample is too small to support the claimed difference.

Can I just report a p-value instead of an interval?

A p-value answers a narrower question than most decisions need. The interval gives you both the direction and the plausible range of the effect, which is what tells you whether the change is worth shipping; Hazra notes that clinical importance is best inferred from the effect size, that is how large the actual change is Hazra on confidence intervals. Reporting both is better than either alone, and the interval is the one that survives a small sample intact.

Does a pilot study need a power calculation?

Usually not, and treating it as if it does causes trouble. Pilot studies exist to test feasibility of designs, measures, recruitment and procedures, and their sample size should be justified by those goals Kunselman's overview. Using a pilot's effect estimate to power the main trial is specifically warned against, because small-sample estimates are unstable same source.

How do I stop a team from re-cutting the data until something looks significant?

Fix the plan before collection. Preregistration specifies the research plan in advance, distinguishes planned from unplanned work, and minimizes false positives the Center for Open Science. Sequential designs where you check data partway through are legitimate, but they must be declared as such rather than used as an escape hatch when the first result disappoints same source.

What sample size should I plan for a review I intend to trust?

Start from the effect you care about, the variability you expect and the confidence you need, then compute. Planning formulas make the trade-off explicit: for a proportion, halving the margin of error roughly quadruples the sample Sopact's calculator and formula, and for means the drivers are variance, effect size, alpha and power ClinCalc. If the number is unaffordable, shrink the scope of the claim rather than the rigor of the interval.

Sources

Sources

  1. Using the confidence interval confidently - PMC - NIH
  2. Preregistration - Center for Open Science
  3. Survey Sample Size Calculator: Responses, Precision and ...
  4. How to Construct a Confidence Interval With a Small ...
  5. A brief overview of pilot studies and their sample size ...
  6. Conducting Power Analyses to Determine Sample Sizes in ...
  7. Sample Size Calculator
  8. What is an Incident Postmortem?
  9. AI Incident Post-Mortem: Templates and Best Practices
  10. What Is the AI Agent Loop? The Core Architecture Behind ...
  11. Autonomous AI Agents: How They Work
About the author

About the author

Antonio Evans
Antonio Evans

Antonio Evans is the founder of Quanta Intelligence and a fractional CTO who builds HIPAA-ready AI systems for health and life-science companies. Before that he was technical co-founder of FriendsEAT for twenty years, CEO of Socialdraft, and a data engineer at IBM. Antonio lives with his dog Santino in Lisbon, Portugal.

All articles