Marketing

Writing an Intent Labeling Guide Two Raters Can Apply

Antonio Evans10 min read

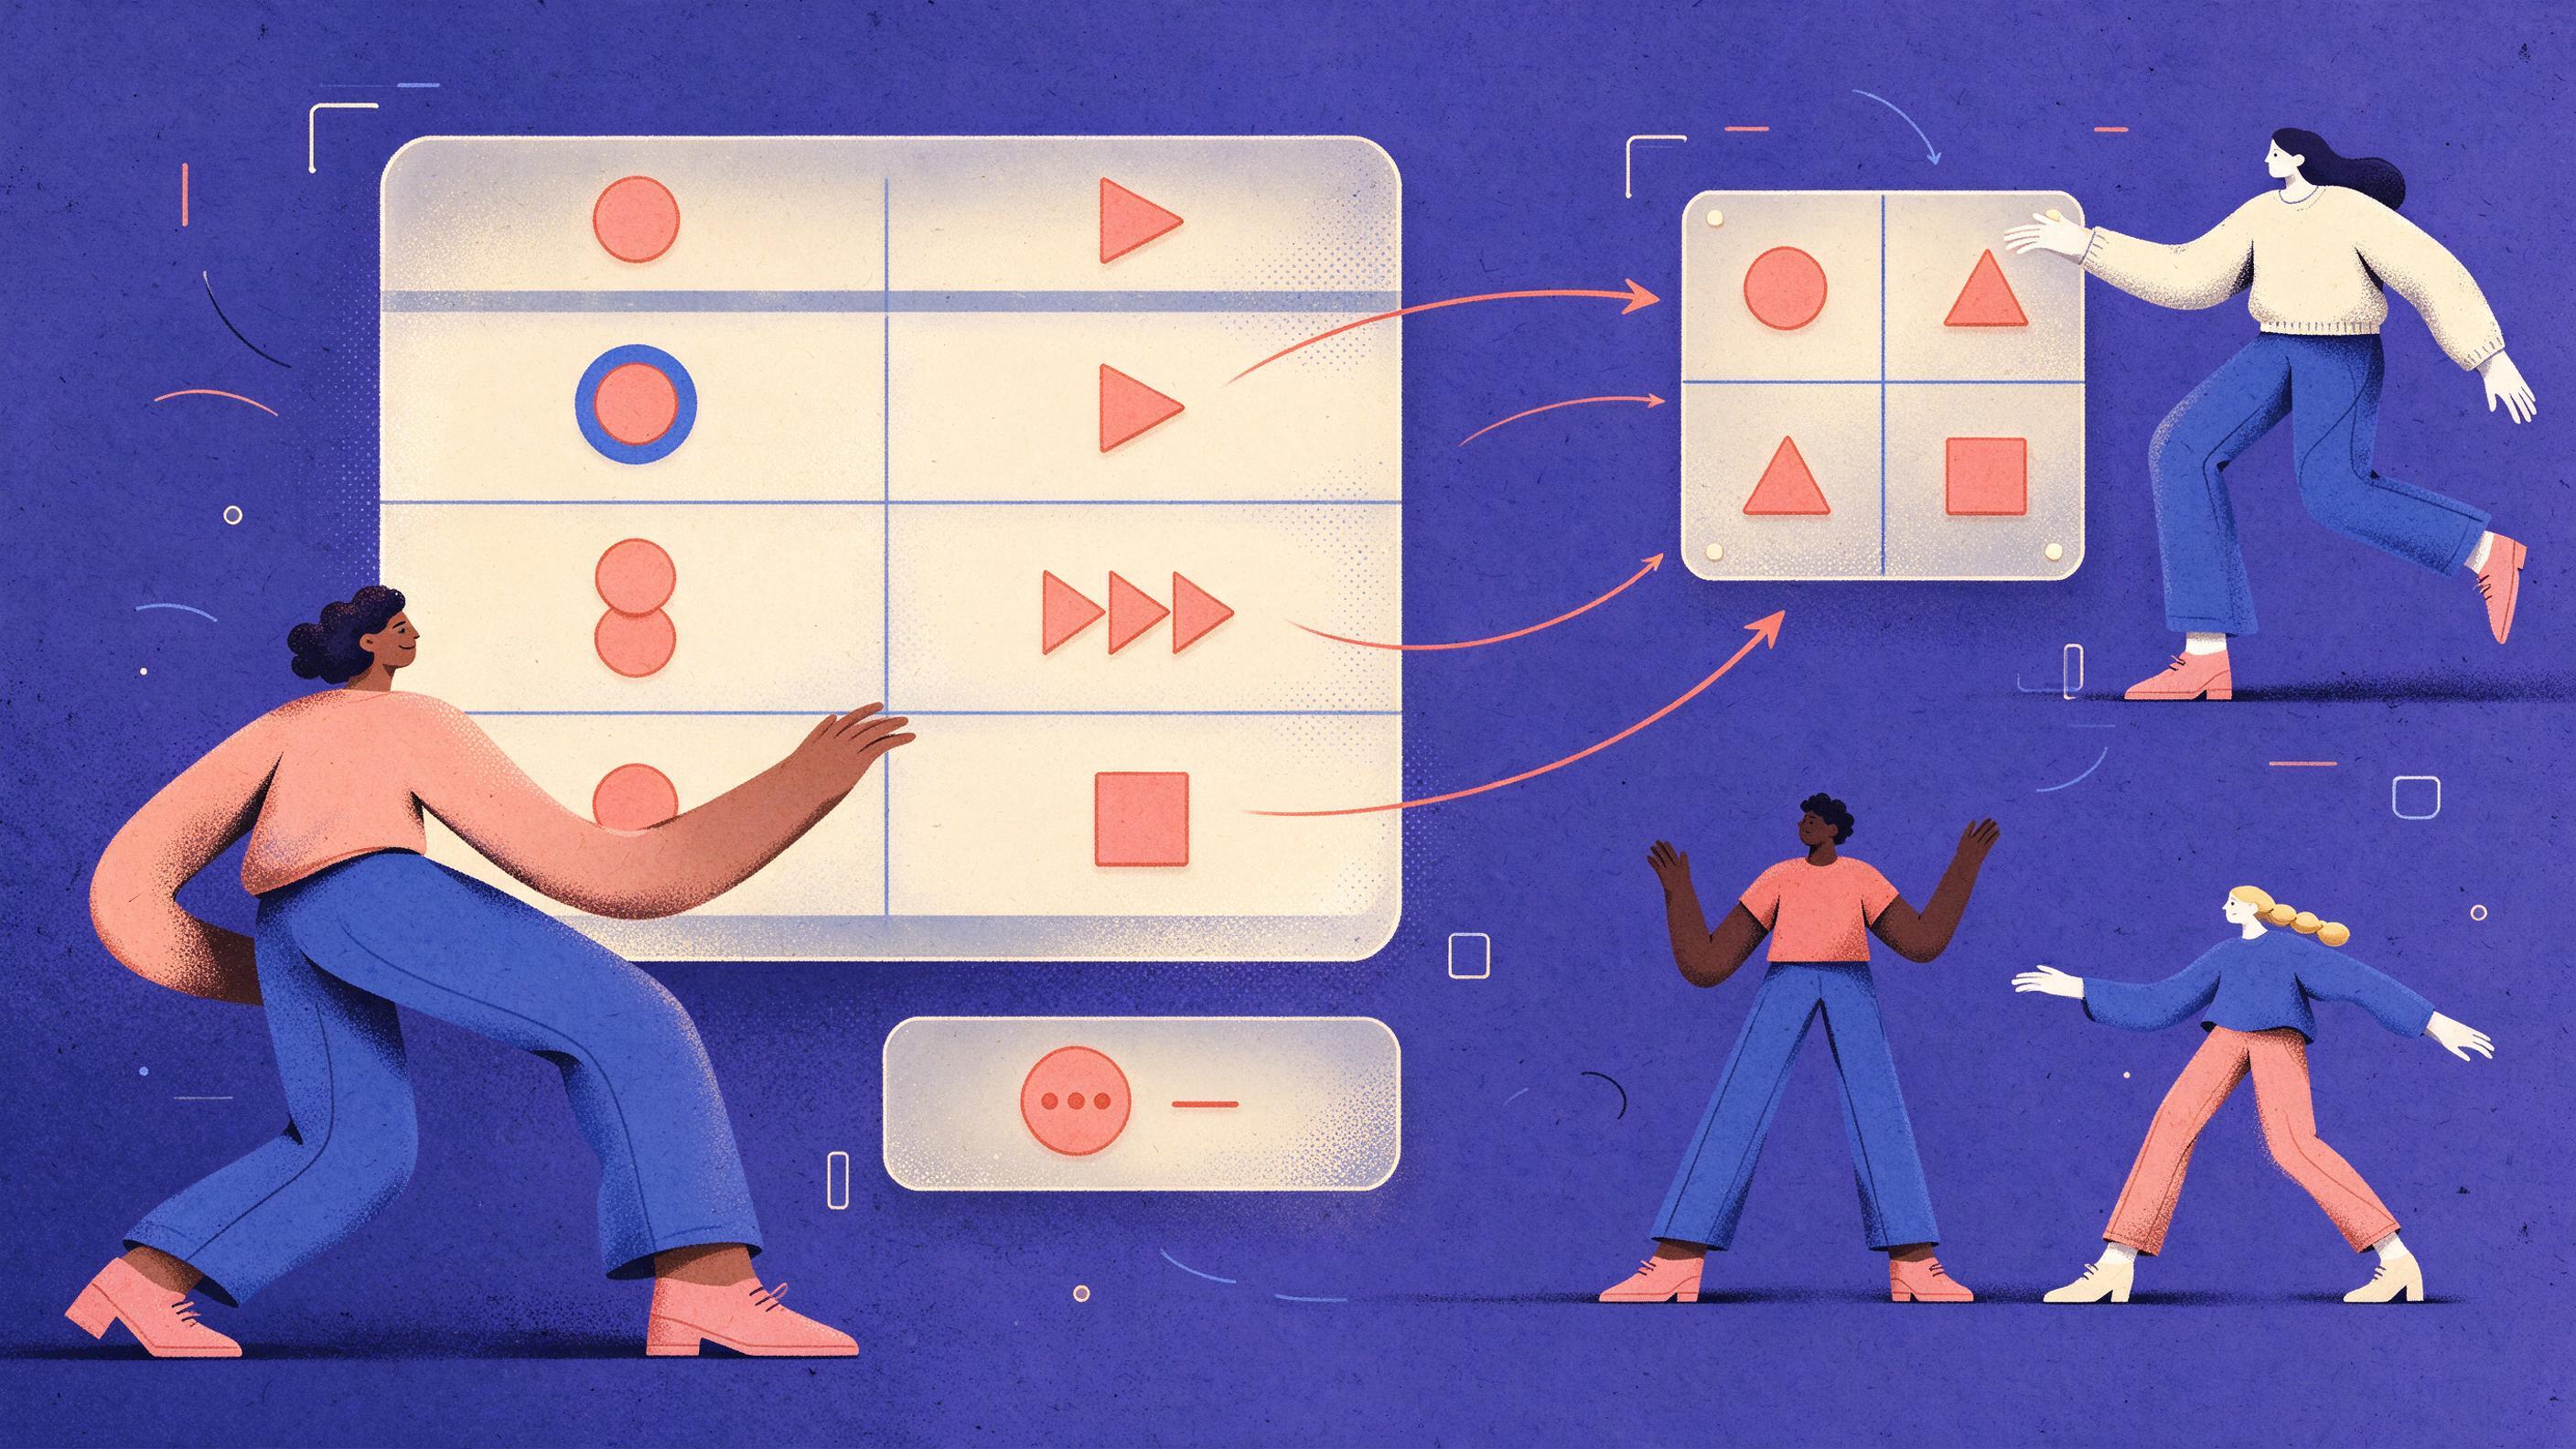
A two-column rules table on the left (condition, action, and a tie-breaker note) beside a small 2x2 agreement matrix on the right, with arrows from three rows of the table to the cells where raters disagreed.
Key points

Key points

  1. 1A labeling guide works like a prompt for people: an intent needs a one-line definition, inclusion cues, one exclusion and a tie-breaker, not a pile of examples.
  2. 2Two raters label a pilot batch independently, then you compare percent agreement against Cohen's kappa to see whether the guide or the chance distribution is doing the work.
  3. 3Set the target agreement before the pilot starts, because a threshold chosen after seeing the numbers is a threshold bent to fit the numbers.
  4. 4When kappa falls short, find the single rule that produced the split, rewrite it and rerun on fresh messages rather than relabeling the same batch.

Start with the decision rule, not the example list

Intent classification asks what a user wants to accomplish with a message, which is a step beyond keyword matching per AmICited's overview. That gap is exactly where two raters diverge: a message containing "refund" can be a request to start a return, a question about refund timing, or a complaint that a refund never arrived. A guide built from examples will show each of these once and let raters guess the rest. A guide built from rules tells them which signal wins.

The old approach to intent work was a long list of hand-written rules and logic, which scales badly once you have thousands of messages as Lucidworks describes. That does not mean rules are wrong. It means a rulebook has to be small, ordered and testable, and it needs a measurement loop so you can tell whether a new rule helped. The same logic applies to machine categorizers, which is why query classification research keeps circling back to how coarse category definitions lose detail in the Modelling paper on semantic intent identification. Human raters hit the same wall.

Your guide has four layers per intent:

  1. One-line definition. What the user is trying to do, in their words.
  2. Three inclusion cues. Observable features in the text (verbs, nouns, punctuation, whether an order number appears).
  3. One exclusion. The closest neighboring intent this one must not absorb.
  4. One tie-breaker. The rule that resolves the specific co-occurrence you expect to see.

The tie-breaker is the layer most guides skip, and it is the layer that moves kappa. Write tie-breakers as ordered precedence: "If a message contains both a purchase request and a shipping-date question, label it transactional, because the order is the user's goal and the date is a constraint." Raters can apply precedence rules consistently. They cannot consistently apply "use judgment."


A worked guide for twelve support messages

Take a support inbox with four intents: Order Status, Returns, Billing Dispute, and Product Question. Here is the rules table as a single portable block. Note that every row carries a precedence number, so a message that matches two rows has a fixed answer.

PriorityIntentOne-line definitionInclusion cuesExclusionTie-breaker
1Billing DisputeUser says a charge is wrong, duplicated or unrecognizedNames a dollar amount; uses "charged", "double", "didn't order"A refund request for a returned item is ReturnsBilling wins over Returns when money is contested
2ReturnsUser wants to send an item back or get a refund for a delivered item"return", "send back", "refund", order numberBilling Dispute if the charge itself is questionedReturns wins over Order Status when the user asks to send it back
3Order StatusUser asks where a placed order is"where is", "hasn't arrived", "tracking", order numberProduct Question if no order existsOrder Status wins over Product Question when an order number is present
4Product QuestionUser asks about features, compatibility or stock before buying"does it work with", "what size", "in stock"Any message with an order numberProduct Question only when no order number and no complaint appears

Now the pilot batch. Twelve messages, labeled independently by Rater A and Rater B using only the table above, with no discussion between them.

#Message (abbreviated)Rater ARater B
1"Charged twice for order 88213, need one reversed"Billing DisputeBilling Dispute
2"Where is my order? It's been 9 days"Order StatusOrder Status
3"Can I send back the blue one, size is wrong"ReturnsReturns
4"Does the lid fit the 20oz bottle?"Product QuestionProduct Question
5"I never ordered this, why is it on my card"Billing DisputeBilling Dispute
6"Refund for order 44120 still not showing"Billing DisputeReturns
7"Is the green version in stock in large?"Product QuestionProduct Question
8"Order 55109 arrived broken, want my money back"ReturnsReturns
9"Return started last week, where is the refund"ReturnsBilling Dispute
10"What's the difference between the two pack sizes?"Product QuestionProduct Question
11"Tracking says delivered but nothing came"Order StatusOrder Status
12"You charged me for shipping twice on 77301"Billing DisputeBilling Dispute

Eight of twelve match. That is 66.7 percent agreement, and the four misses are all in the Returns and Billing Dispute boundary, which is exactly where the tie-breaker was written too loosely.

Computing percent agreement and Cohen's kappa by hand

Percent agreement is the count of matching labels divided by the total. Here it is 8 / 12 = 0.667. That number alone is misleading, because some categories get used far more often than others. Cohen's kappa corrects for agreement that would happen by chance given each rater's distribution of labels as the Wikipedia entry on Cohen's kappa sets out.

Build the confusion table first. Rows are Rater A, columns are Rater B.

B: BillingB: ReturnsB: Order StatusB: Product QA total
A: Billing41005
A: Returns12003
A: Order Status00202
A: Product Q00022
B total532212

Observed agreement is the diagonal sum over N: (4 + 2 + 2 + 2) / 12 = 0.833. That is higher than the crude match count suggested, because both raters spread their labels the same way overall.

Expected agreement is the sum of each category's row total times its column total, divided by N squared:

pe = (5*5 + 3*3 + 2*2 + 2*2) / (12*12)
   = (25 + 9 + 4 + 4) / 144
   = 42 / 144
   = 0.2917

kappa = (0.833 - 0.2917) / (1 - 0.2917)
      = 0.5417 / 0.7083
      = 0.765

A kappa of 0.765 sits in the "substantial" band of the Landis and Koch interpretation table, which labels 0.61 to 0.80 as substantial and 0.81 to 1.00 as almost perfect per the kappa interpretation summary. Clinical fields often require 0.80 or above, and that same source warns that the labels are conventions, not laws. If your target was 0.80, this guide fails. If it was 0.70, it passes with room.

The distinction between percent agreement and kappa matters more than the arithmetic. A worked example from the same reference shows 90 percent agreement collapsing to a kappa near 0.33 once you account for a lopsided distribution. When one intent dominates your inbox, raw agreement will look flattering and kappa will expose it.

Setting the target before you start

Pick the threshold and write it into the guide document before the first message is labeled. Three inputs set it:

  • Downstream cost of a wrong label. If labels feed a routing rule that sends a message to the wrong queue, the cost is a delay. If labels train a classifier you will ship, errors propagate.
  • Category count. Kappa gets harder to move as categories increase, because chance agreement falls and near-miss confusions multiply.
  • How close the intents genuinely are. Returns and Billing Dispute share vocabulary by nature. Two intents that share words will never reach the ceiling that two unrelated intents reach.

A practical working bar is 0.80, with a documented fallback: if kappa lands between 0.70 and 0.80 and every remaining disagreement traces to one identifiable message pattern, accept the guide, log the pattern, and monitor. If kappa is below 0.70, stop and rewrite.

The logic is the same one used for confidence thresholds in AI systems, where the cutoff is a business decision layered on top of a model score, not a property of the model per LlamaIndex's explanation of confidence thresholds. Their guidance applies directly to human labeling: measure your baseline error before you tune, because a false positive in one domain is not the same cost as in another.

Record the decision in a one-line table so nobody relitigates it later.

TargetDecisionAction
kappa 0.81 or aboveShipFreeze the guide, start production labeling
0.70 to 0.80ConditionalShip if every disagreement traces to one logged pattern
0.61 to 0.69ReviseRewrite the failing rule, rerun on fresh messages
0.60 or belowStopThe intent set itself is probably wrong; merge or split intents

That last row is the insight most guides miss. Very low kappa usually means your taxonomy is broken, not your wording. If raters cannot separate Returns from Billing Dispute even after a clear tie-breaker, the two intents may not be separate concepts in the data.

Reading the table to find the failing rule

Do not average away the disagreement. Read the off-diagonal cells one at a time and ask which rule would have decided the message.

Here, all four misses are between Billing Dispute and Returns, in both directions. Messages 6 and 9 are the reverse of each other, which is a strong signal: the two raters are not biased, they are reading the same tie-breaker differently. Message 6 reads "Refund for order 44120 still not showing." Rater A applied priority 1 because money is contested. Rater B applied priority 2 because the word "refund" appears. The tie-breaker as written says Billing wins when money is contested, which is vague: a refund is money.

The fix is to make the trigger lexical and observable rather than conceptual:

  • Old: "Billing wins over Returns when money is contested."
  • New: "Billing Dispute requires an assertion that a charge is wrong, duplicate or unrecognized, stated with a specific amount or the word 'charged'. A refund that is merely delayed belongs to Returns."

Under the new rule, message 6 is Returns and message 9 is Returns, because neither asserts a wrong charge. Message 1 stays Billing because "charged twice" is an assertion. Message 12 stays Billing for the same reason.

This is the discipline that separates a guide from a vibe. Every rewrite should change one rule, name the specific messages it reclassifies, and leave the rest alone so you can attribute the next kappa to that change.

The revision log and the rerun

Keep a revision log next to the guide. It is the audit trail that makes the next pilot comparable.

RevChangeTriggering messagesPredicted effectRerun result
1Initial guide, four intents, precedence tablenonenonekappa 0.765 on 12
2Tie-breaker 1 rewritten to require an assertion of a wrong charge6, 9both go Returnskappa to be measured
3Order Status exclusion tightened: "delivered but missing" stays Order Status11confirm both raters agreeto be measured

Rerun on fresh messages, not the pilot batch. Raters who have just discussed messages 6 and 9 will label them correctly from memory, and your second kappa will be inflated by recall rather than by the guide. Draw a new sample from the same distribution, same size, same independence rule. For real reliability work, put 50 to 100 messages in each pilot so a handful of confusions does not swing the number; that range also gives you enough off-diagonal cells to see a pattern rather than a coincidence. Inter-rater reliability work in annotation projects makes the same point: low agreement signals that instructions or training need refinement before the dataset moves forward per Ultralytics on inter-rater reliability.

If you are computing this repeatedly, a short script beats a spreadsheet and removes arithmetic from the list of suspects:

from collections import Counter

def agreement(a, b):
    n = len(a)
    pairs = list(zip(a, b))
    po = sum(x == y for x, y in pairs) / n
    ca, cb = Counter(a), Counter(b)
    pe = sum(ca[k] * cb[k] for k in set(ca) | set(cb)) / (n * n)
    kappa = (po - pe) / (1 - pe) if pe < 1 else 1.0
    return po, pe, kappa

rater_a = ["billing","status","returns","product","billing","billing",
           "product","returns","returns","product","status","billing"]
rater_b = ["billing","status","returns","product","billing","returns",
           "product","returns","billing","product","status","billing"]
print(agreement(rater_a, rater_b))  # po 0.833, pe 0.292, kappa 0.765

One caveat worth knowing before you quote kappa in a review: the statistic is unreliable when one category is rare, because expected agreement gets dominated by the majority class. If an intent appears in fewer than a handful of pilot messages, report the per-category confusion counts alongside the overall number and say so explicitly. Fleiss' kappa extends the same correction to more than two raters, which matters once you add a third labeler or a model as a tie-breaker as the Imerit guide to annotator agreement notes.

Applying the same guide to a model

Once two humans clear the bar, the guide becomes the specification for an automated classifier, and the pilot set becomes a regression test. The practical sequence is unchanged: run the model on messages the humans labeled, build the same confusion table with the model in the column position, and compare. A model scoring well below the human kappa is not automatically wrong; it may be picking up signals your raters discounted, or your raters may be applying an unstated rule. The gap is the conversation.

Two operational notes save money here. First, the guide itself is a stable prefix you send with every classification request, so it is worth structuring it as a fixed block ahead of the variable message; providers price repeated prefixes at a discount, and Anthropic's documentation describes a 5-minute default cache lifetime with refreshes at no extra cost on reuse per the Claude prompt caching docs. Second, classification jobs that nobody is waiting on can run asynchronously for a large discount; OpenAI's and Anthropic's batch endpoints both advertise a 50 percent discount for async processing with results within 24 hours per NeuralTrust's batching guide. Labeling 40,000 historical tickets to enrich a training set is exactly that workload. Live inbox routing is not.

If you want one key across text, image and embedding models for this pipeline, Quanta Inference exposes them through an OpenAI-compatible endpoint.

FAQ

FAQ

How many messages do two raters need to label before kappa means anything?

Fifty to one hundred messages per pilot is a workable range. Below that, a few confusions move the number by several points and an unlucky sample can push a good guide under the bar. The important constraint is not the exact count but that every category appears often enough to produce off-diagonal cells, so aim for at least five examples of each intent in the batch.

Does high percent agreement mean the guide is fine?

Not on its own. Percent agreement ignores how often each rater used each label, so a dominant intent inflates it. Cohen's kappa subtracts expected chance agreement using the observed marginals as the kappa entry explains, which is why a 90 percent match can correspond to a kappa near 0.33. Report both numbers, and report the confusion table too.

What do we do when the two raters cannot agree even after a rewrite?

Treat it as evidence about the taxonomy rather than about the wording. If two intents produce confusion in both directions after a clear precedence rule exists, the data may not contain the distinction you are asking for. Merge the pair, label the combined intent, and rerun. Splitting later, once you have real examples, is cheaper than forcing raters to invent a boundary.

Should the model be a third rater in the pilot?

Only after the humans clear the target. Adding a model to a pilot where the human guide is still unstable muddies the diagnosis, because you cannot tell whether a three-way disagreement is the guide or the model. Run the human pilot, fix the guide, then run the model against the frozen human labels as a regression check.

How do we keep the guide from drifting after launch?

Keep the revision log alive and require one new pilot every time a rule changes. Rotate a small sample of already-labeled messages back through fresh raters periodically to catch intra-rater drift, where the same person applies the guide differently over time as Ultralytics distinguishes from inter-rater reliability. When drift shows up, it is usually a rule that was never written down.

For teams that would rather hand the pipeline to someone who has run this loop before, Quanta Experts takes your context and returns finished deliverables, including a tested labeling guide and its agreement report.

Sources

Sources

  1. Query Intent Classification: AI Intent Analysis & ...
  2. How Does Query Intent Classification Work?
  3. Intent Identification by Semantically Analyzing the Search ...
  4. Cohen's kappa
  5. Cohen's Kappa Table: Interpretation, Values & Critical Values
  6. Understanding Confidence Threshold in AI Systems - LlamaIndex
  7. Inter-Rater Reliability: Measuring Annotation Agreement
  8. A Guide to Inter-rater Reliability and Annotator Agreement ...
  9. Prompt caching - Claude Platform Docs
  10. LLM Batching & Async Inference: Cut Costs on High- ...
About the author

About the author

Antonio Evans
Antonio Evans

Antonio Evans is the founder of Quanta Intelligence and a fractional CTO who builds HIPAA-ready AI systems for health and life-science companies. Before that he was technical co-founder of FriendsEAT for twenty years, CEO of Socialdraft, and a data engineer at IBM. Antonio lives with his dog Santino in Lisbon, Portugal.

All articles