
Founders

How to Log a Decision So a Model Can Review It Later

Antonio Evans9 min read

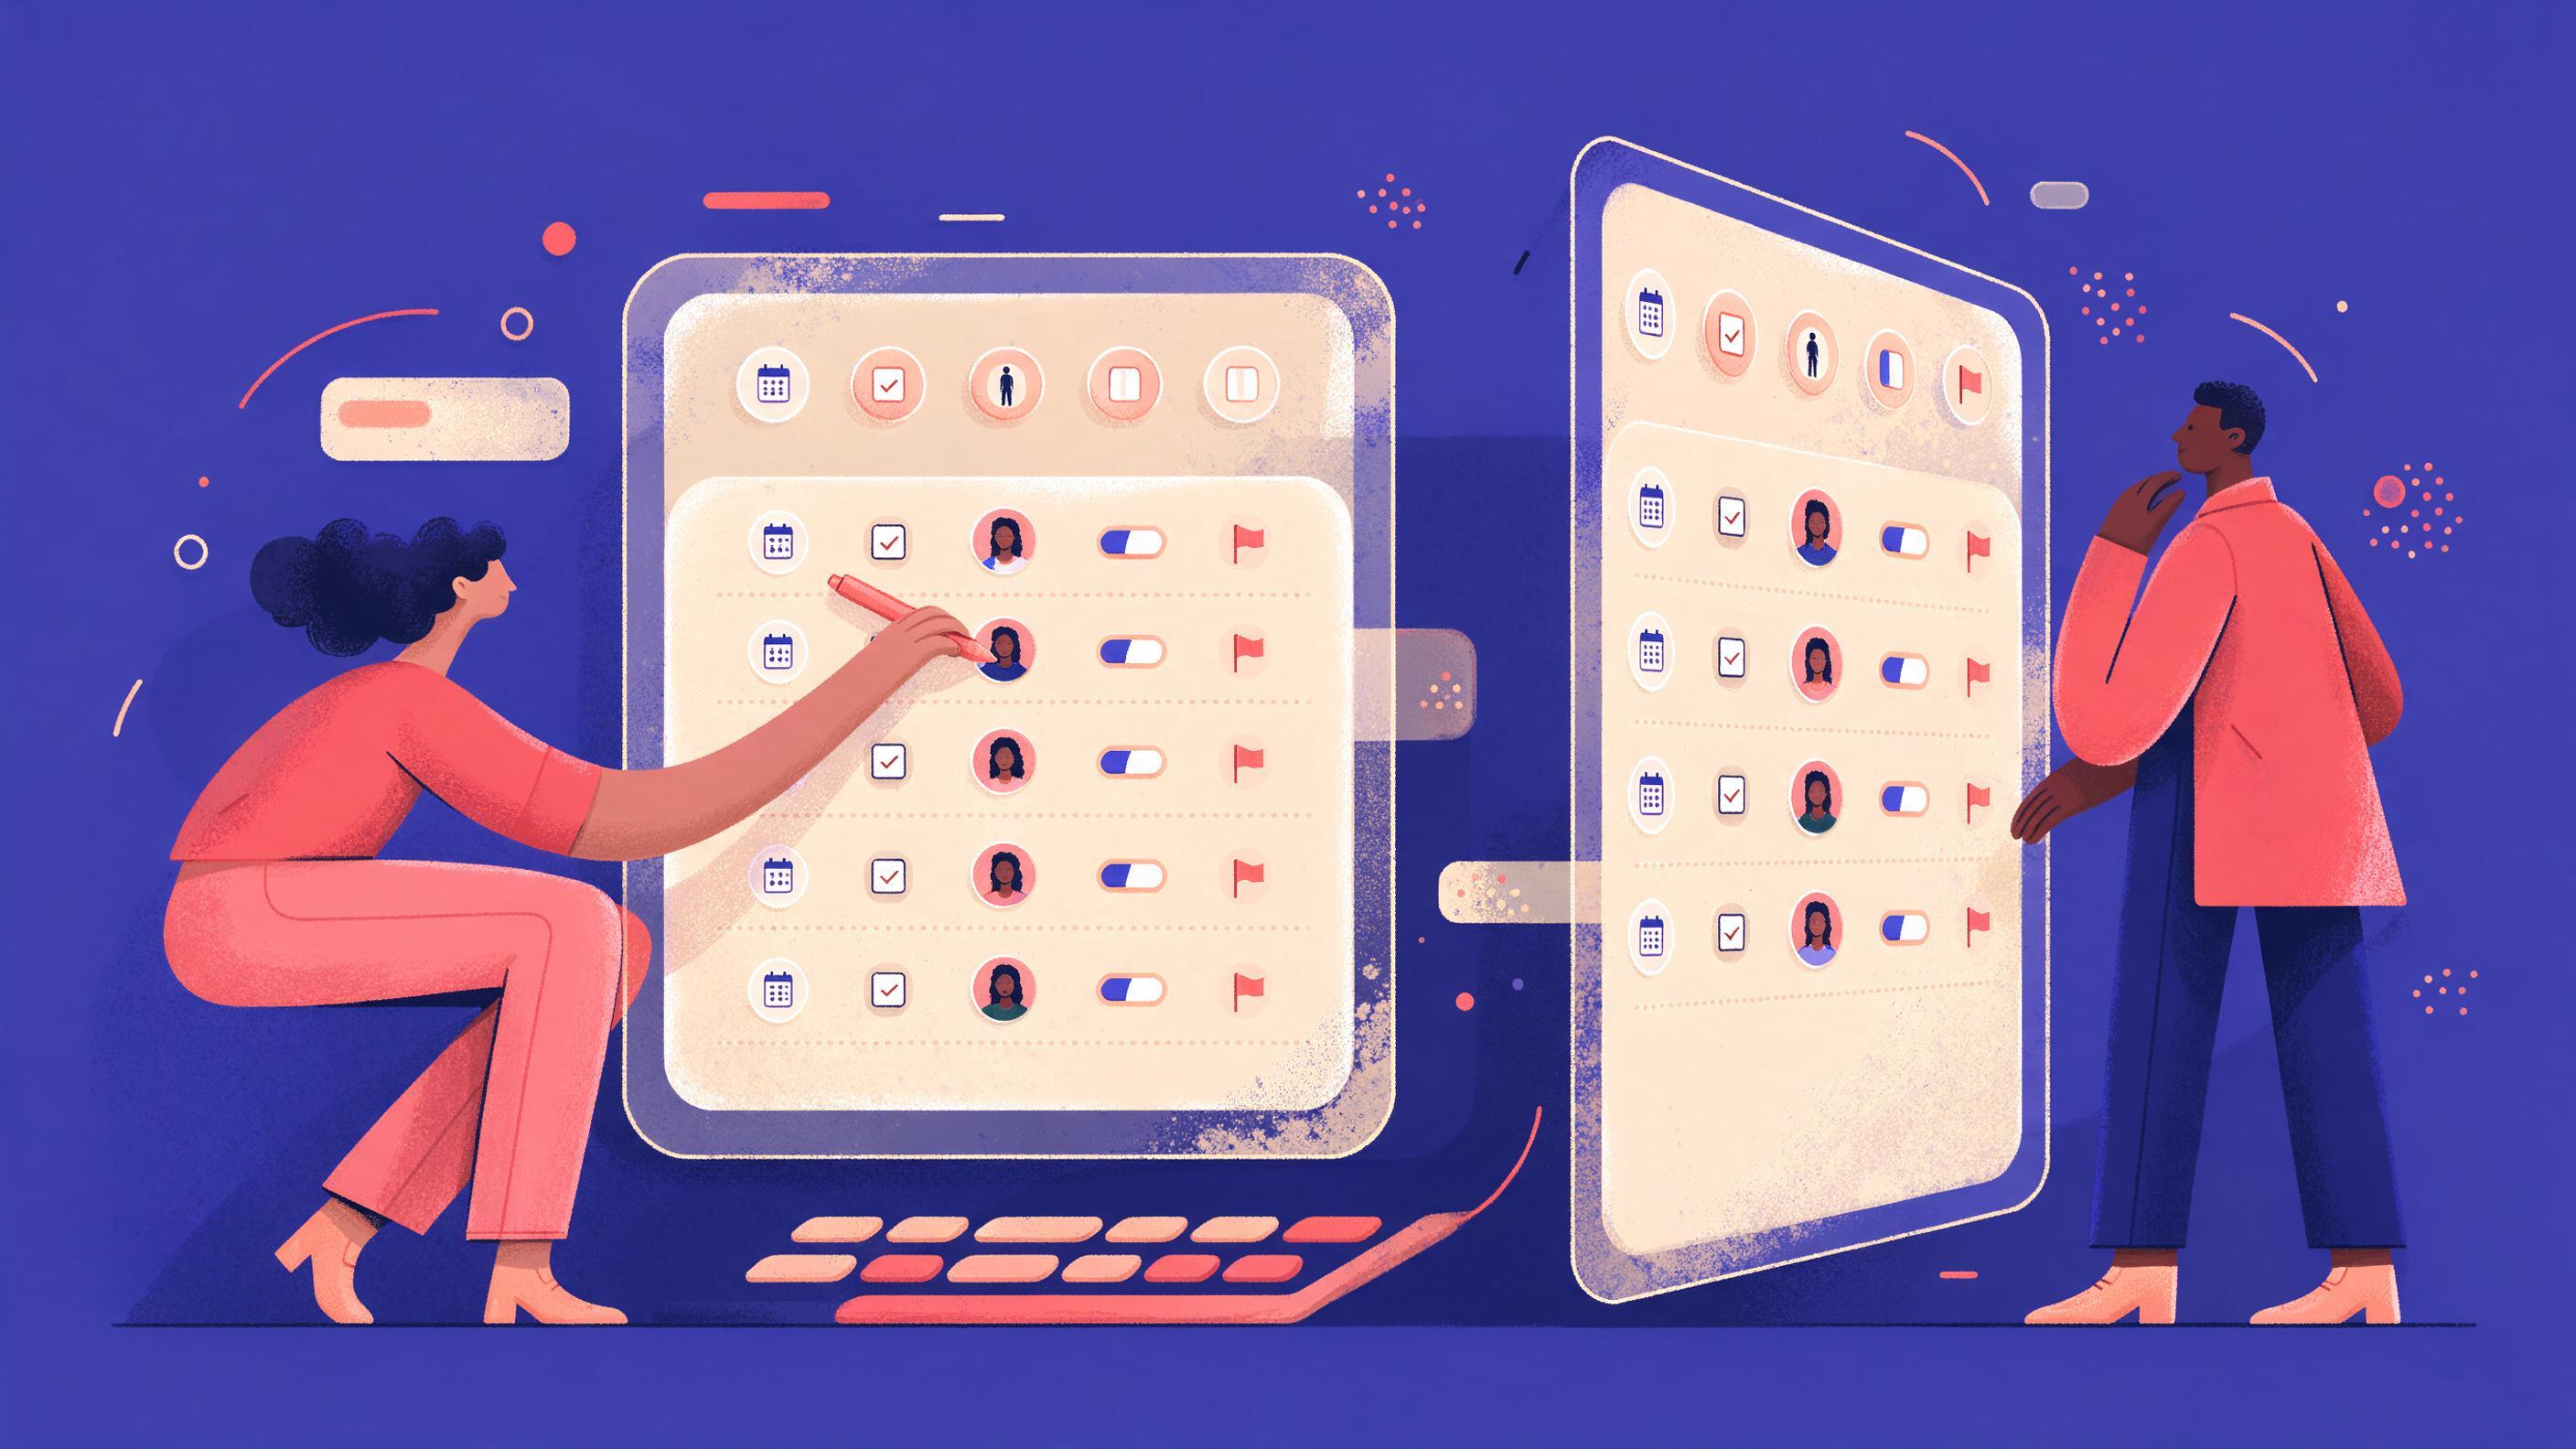
A split-scene illustration: on the left, a person writes in a structured digital log with visible fields (date, decision, owner, status, reversal flag); on the right, a model icon reviews the same log on a screen.
Key points

Key points

  1. 1A model can only review a decision if the record states the decision, the alternatives, the evidence, the owner, the status, and the condition that would reopen it.
  2. 2Reversals and stalled calls are detectable only when each entry carries a reversal link and a next review date, because a later entry has to point back at the one it overrides.
  3. 3Store entries as append-only JSON or a fixed-column table so the model reads the same field names every time and cannot silently rewrite history.
  4. 4The review prompt should ask for specific verdicts per decision ID, and a human owner should accept, reject or defer each one before anything changes.

Why a decision log fails without a machine-readable shape

Most teams already keep some version of a decision log. The usual failure is not that nobody writes anything down. It is that the record mixes context, reasoning and outcome into one paragraph, which makes it hard to quote in a project update and easy to misread later. A useful template keeps the decision sentence separate from the context and lists options, evidence, owner, date, outcome and a revisit trigger as distinct fields the Boardmix template. That separation matters twice over when a language model is the reader, because a model reviewing prose has to guess where the decision ends and the justification begins.

The practice of keeping a decision log is not new. Guidance for founders working alone recommends it because major decisions "can happen too quickly and too privately," and because a written record of what you decided, why, what evidence you had and what would cause you to revisit the decision forces you to separate facts from assumptions the Techstars thread. A decision log also helps advisors, mentors and future team members understand how a company arrived where it is. That is the human case. The machine case is a superset: a model needs the same fields, plus enough structure to compare entries against each other.

Project management vendors describe the same core components. A decision log is a structured record of what was chosen, why, who was involved, what alternatives were weighed and what outcomes were expected, kept as a single source of truth so teams do not rely on memory or scattered documents the monday.com guide. The gap between that and a log a model can actually audit is mostly about consistency: the same field names, the same date format, and an explicit link from a new decision to the old one it changes.

There is a technical reason to be careful about direction as well. Language models trained on a statement of the form "A is B" do not reliably generalize to "B is A", a finding documented across model families and sizes the Reversal Curse paper. The paper notes that when the relationship appears in context, models can deduce the reverse. That is the design lesson for a decision log: never make the model infer a reversal from two entries that merely look related. Write the reversal into the entry, with the ID of the decision being replaced.

One more distinction is worth settling before you build. A decision log is not the same artifact as a task tracker or a prioritization grid. An Eisenhower Matrix sorts tasks by urgency and importance into four boxes and points each box at a different action the Asana explainer. That is a tool for deciding what to do next. A decision log records what was already decided and why, so a later reader can check whether the reasoning still holds. Keep them separate, or your log fills with tasks and stops being reviewable.
The fields a review model needs

A minimal schema covers ten things. Each one exists because a reviewer, human or model, needs it to answer a specific question.

FieldWhat it holdsQuestion it answers for the reviewer
idUnique, stable identifierWhich decision is this?
decided_atDate and time, one formatWhen was it made, and how long has it been open?
decisionOne sentence naming the option and scopeWhat exactly was chosen?
contextProblem, goal, constraints at the timeWhat was true when this was decided?
alternativesOptions considered, each with the reason it lostWas a real choice made?
evidenceLinks to data, research, customer inputIs the rationale grounded in anything checkable?
ownerOne accountable personWho acts if this is wrong?
statusproposed, approved, rejected, implemented, supersededIs this live, dead or pending?
reversal_ofID of the earlier decision plus a one-line reasonDoes this contradict something earlier?
review_byDate the decision should be re-examinedIs it overdue?

Two fields do the heavy lifting for the review you want. reversal_of makes reversals explicit rather than inferred, and review_by turns "stalled" from a feeling into a comparison between two dates. The status vocabulary matters too: if a decision sits at proposed past its review_by date, that is a stalled call, and a model can count it without judgment.

Guidance on writing the decision itself is worth following literally. Prefer a testable statement with a scope, a reason to review and a measurable follow-up over a value judgment ("X is the best tool"), because the testable version survives being read out of context months later the Boardmix template. The same source suggests writing unresolved objections as risks with an owner rather than transcribing every comment. That keeps the entry short enough for a model to read hundreds of them in one pass.

The distinction between a decision log and related artifacts is also worth knowing. An architecture decision record captures a single technical choice with its context and consequences, and a RAID log tracks risks, assumptions, issues and dependencies. A decision log is the broader record that can reference both the monday.com guide. For model review, the broader log is the better target because reversals and stalls usually cross project boundaries.

A worked example entry

Here is one entry in JSON, the format most likely to survive a copy between tools. The fields are the same ones in the table above.

{
  "id": "DEC-0042",
  "decided_at": "2026-03-11T14:30:00Z",
  "decision": "Route all customer-support triage through a single vendor's classification endpoint for the next two quarters, scoped to inbound email only.",
  "context": "Two vendors trialed for six weeks. Inbound email volume rose 22 percent quarter over quarter. The team has one engineer on integrations.",
  "alternatives": [
    {"option": "Keep both vendors and split traffic", "rejected_because": "Doubles integration maintenance for a one-engineer team."},
    {"option": "Build an in-house classifier", "rejected_because": "Estimated three months of work; no labeled dataset exists yet."}
  ],
  "evidence": ["trial-results-2026-q1.csv", "support-volume-report"],
  "owner": "priya.n",
  "status": "implemented",
  "reversal_of": null,
  "review_by": "2026-09-11"
}

And a later entry that reverses part of it, with the link written in rather than implied:

{
  "id": "DEC-0057",
  "decided_at": "2026-08-29T09:15:00Z",
  "decision": "Move inbound email triage back to the in-house classifier and retire the vendor endpoint for email.",
  "context": "The vendor raised per-call pricing twice. The in-house dataset now has eleven months of labeled tickets.",
  "alternatives": [
    {"option": "Renegotiate the vendor contract", "rejected_because": "Two increases in six months; no volume commitment available."}
  ],
  "evidence": ["vendor-invoices-2026", "labeled-ticket-count"],
  "owner": "priya.n",
  "status": "approved",
  "reversal_of": "DEC-0042",
  "reversal_reason": "Cost trajectory changed and the blocking constraint (no dataset) no longer holds.",
  "review_by": "2027-02-28"
}

That second entry is the kind a model can flag or excuse with evidence. Note what makes it reviewable: the reversal names the ID it replaces, gives a reason tied to a changed constraint, and cites files. A log where the second entry simply said "switching vendors" and left the first entry untouched would force the model to infer a contradiction from two unrelated-looking records, which is exactly the situation the reversal research warns about.

If you would rather keep the log in a table, the same fields work as columns and the alternatives become a delimited list or a second sheet. Consistency beats elegance. Pick one shape and keep every entry in it.

Writing the review prompt

The prompt is where most of the value is won or lost. A vague request like "review these decisions" gets a summary. A structured request gets findings you can act on. Four rules make the difference.

First, give the model the whole log, not a filtered view, and tell it the date to treat as "now." Second, define the two things you want found. A reversal is an entry whose reversal_of is set, or whose decision contradicts an earlier entry that is still marked active. A stalled call is an entry still proposed or approved past its review_by date, or one that is implemented with no follow-up record after a stated interval. Third, require output keyed to decision IDs so every finding is traceable. Fourth, instruct the model to say when it is guessing.

You are reviewing a decision log. Today's date is 2026-10-01.

Definitions:
- REVERSAL: an entry whose reversal_of field is set, OR whose decision
  contradicts an earlier entry that is still marked active.
- STALLED: status is proposed or approved and review_by is before today,
  OR status is implemented with review_by passed and no later entry
  referencing this id.

Return a JSON list. One object per finding:
{"id": "...", "finding": "reversal|stalled|clean", "evidence_ids": [...],
 "why": "one or two sentences quoting the relevant fields",
 "confidence": "high|medium|low"}

Rules: cite field values verbatim. Do not invent entries. If two entries
only look contradictory because context is missing, mark confidence low
and say what field is missing. Do not recommend a course of action.

The last instruction is deliberate. Models are good at spotting patterns across many records and bad at knowing your constraints. Separating detection from judgment keeps the output useful and keeps the decision with the person who owns it.

A prompt built this way also protects against a subtle failure. If you ask a model to "review for inconsistencies" without definitions, it will often flag entries that differ only in wording, and a reviewer who chases those stops trusting the tool. Named criteria and a confidence field make the noise visible and manageable.

Handling the output in a human oversight loop

Treat the model's list as a set of tickets, not verdicts. A workable loop has four steps.

  1. Triage by confidence. High-confidence reversals and stalls go to the owner of the affected decision. Low-confidence items go to whoever maintains the log, usually to add the missing field.
  2. Ask one question per finding: is the record wrong, or is the review date wrong? A stalled call is often just an entry whose review_by was set and forgotten, which is a log-maintenance fix, not a decision change.
  3. Record the response in the log itself, as a new entry or a status change with a timestamp. Append-only history means the original stays, marked superseded and linked to the new record, which preserves the history of the choice and avoids two current-looking versions the Boardmix template.
  4. Close the loop on the next cycle by checking whether the model's findings produced a change or a dismissal, and why.

This mirrors how people already use regular review rituals. A weekly review exists to compare what you planned against what happened, read a few numbers, and commit to one priority, on the argument that a business rarely dies from a single bad decision but drifts one unexamined week at a time the founder weekly review template. A model reading the decision log is a cheaper form of the same checkpoint, run over the decisions rather than the metrics.

The oversight design matters more than the model choice. A review that occasionally misses a reversal is survivable if a named owner signs off on every status change. One that silently edits the log is not, because it destroys the record that made the review possible. Keep the model in a read-only role and let humans write.

There is a bias to watch for in step one. People consistently favor time-sensitive work over work that matters more but carries no deadline, an effect researchers call the mere-urgency effect the Todoist guide. A model's output can trigger the same reflex: the newest finding feels most pressing. Sorting by confidence and owner rather than by recency keeps the review from becoming a fire drill.

If your team wants a second pair of eyes on the decisions themselves rather than the formatting, Quanta Consulting runs a free 30-minute discovery call to map your goals to a recommendation: https://quantaintelligence.ai/calendar.

How to keep the log reviewable as it grows

Three habits keep a decision log usable at scale, and all three are cheap.

Normalize the fields before you have many entries. Fix the date format, fix the status vocabulary, and decide whether alternatives is a list or a paragraph. A model reading a hundred entries in mixed formats will produce mixed results, and you will not be able to tell whether a missed reversal is the model's fault or the log's.

Summarize at the boundaries. Keep the full log as the source of truth and generate a compact index weekly: one line per entry with ID, date, status, owner and review_by. Ask the model to review the index first and pull full entries only for the IDs it wants to examine. This keeps prompts short and makes the model state which records it actually read.

Watch for duplicate questions. If the same debate keeps returning, that is the signal to record the decision and the conditions under which it should be revisited, rather than re-litigating it each time the Boardmix template. A model can surface these recurring themes by grouping entries with similar alternatives, which is a useful side effect of a consistent schema.

A decision log is also a form of institutional memory, and that has a cost worth naming. A log that only captures successes is a highlight reel; one that captures reversals with reasons is a learning record. The monday.com guidance frames the goal as turning scattered rationale into a searchable asset that survives people joining, moving or leaving the monday.com guide. A model reviewing that asset is doing the same job a diligent advisor would do, asking what was decided, why, and whether that is still true.

FAQ

FAQ

How many fields does a decision log need to be model-reviewable?

Ten fields are enough: a unique ID, date and time, decision statement, context, alternatives, evidence, owner, status, reversal link, and next review date. Teams that already keep a decision log often have six of these and are missing the reversal link and the review date, which are the two that make model review possible.

Will a language model spot contradictions on its own?

It can, but not reliably when the contradiction depends on direction. Models trained on "A is B" do not automatically learn "B is A" the Reversal Curse paper, so a log that only implies a reversal through two similar entries will produce inconsistent results. Writing the reversal link and reason into the new entry removes the ambiguity.

What is the difference between a decision log and a meeting record?

A decision log focuses on the final decision and the reasoning, while minutes provide a chronological transcript of discussion. The monday.com guide draws the same line, noting that minutes and logs serve different purposes the monday.com guide. For model review, the log is the better input because it is structured and comparable across entries.

Should the model be allowed to change a decision's status?

No. Keep the model read-only and let the owner write status changes with a timestamp. An append-only history where the original entry is marked superseded and linked to its replacement preserves the trail of why a choice changed, and a model that edits the log erases the evidence its next review depends on.

How often should the log be reviewed?

Match the cadence to the shortest review_by interval in the log, and review at least as often as your planning cycle. A weekly pass is common because it is short and forces reality back into the work the Techstars thread, and a decision log plus a weekly review cadence is a small amount of structure that reduces a structural risk.

Sources

Sources

  1. Decision Log Template: Fields, Examples and Follow-up
  2. Techstars в X: „4. Use a “who, not how” map. Solo founders often ask ...
  3. Decision log: template, examples, and best practices 2026
  4. The Reversal Curse: LLMs trained on “A is B” fail to learn “ ...
  5. The Eisenhower Matrix: Prioritizing tasks and to-do lists - Asana
  6. Founder Weekly Review Template (With a Worked Example) - 100 Tasks
  7. Avoid the "Urgency Trap" with the Eisenhower Matrix - Todoist
About the author

About the author

Antonio Evans
Antonio Evans

Antonio Evans is the founder of Quanta Intelligence and a fractional CTO who builds HIPAA-ready AI systems for health and life-science companies. Before that he was technical co-founder of FriendsEAT for twenty years, CEO of Socialdraft, and a data engineer at IBM. Antonio lives with his dog Santino in Lisbon, Portugal.

All articles
