Fintech

How to Test a Metering Pipeline Before It Bills Anyone

Antonio Evans8 min read

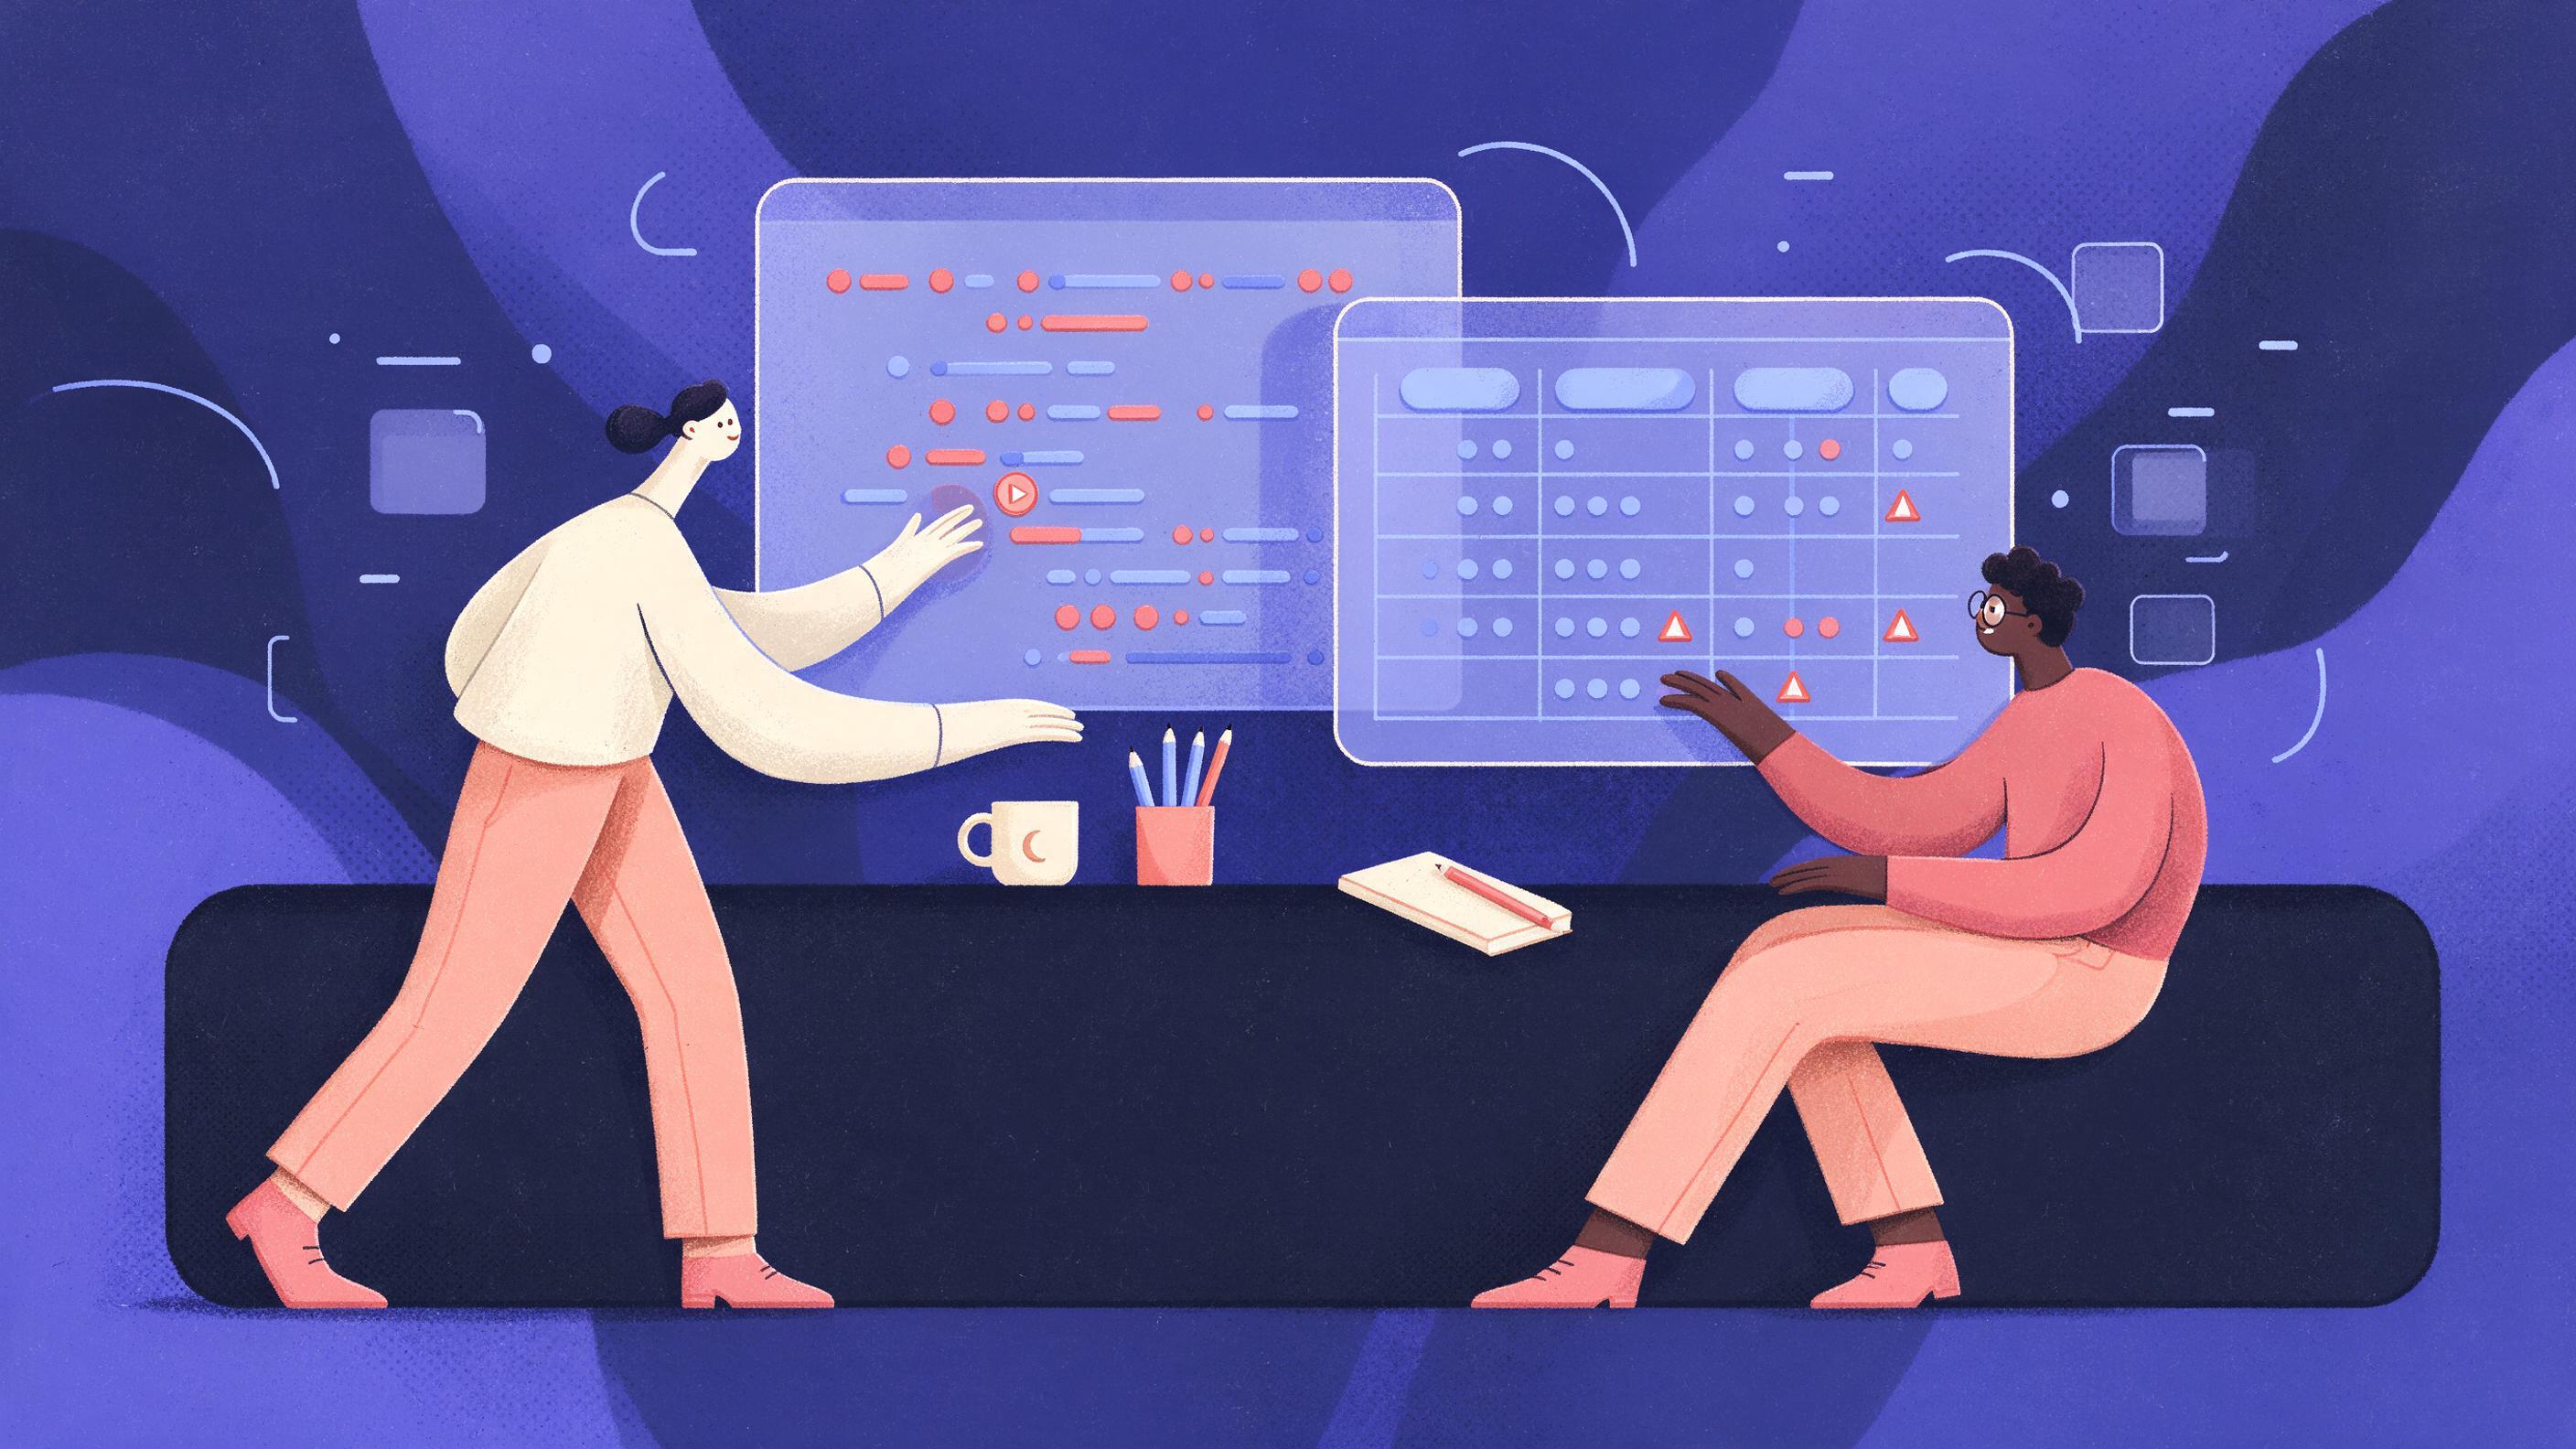
A developer's desk with two monitors: one shows a stream of event IDs and a replay button, the other shows a table comparing expected and actual counts with mismatches marked in red.
Key points

Key points

  1. 1Capture every billable action in an append-only log with a stable, source-generated event ID so duplicates can be folded at ingestion and the raw history can be replayed after any logic change.
  2. 2Build golden test cases where you compute the expected count or sum by hand, then assert the pipeline output against that number instead of against last run's output.
  3. 3Inject faults (duplicate deliveries, retries, late and out-of-order events, mid-cycle restarts) and prove the final billed quantity is unchanged.
  4. 4Reconcile three independent numbers, source, pipeline and billed, with a separate shadow ledger, and alert on the gap before an invoice goes out.

Why metering is not analytics

The instinct carried over from analytics pipelines is that small losses and small duplications wash out. In a funnel chart a duplicated click nudges a percentage. In a meter a duplicated event charges a customer twice, and the customer who spots a double charge is the one who churns, as the usagebox writeup on idempotent metering puts it (idempotent usage metering). The two failure modes are symmetric:

  • Over-counting comes from at-least-once delivery: client retries on a timeout, queue redelivery after a consumer crash, a webhook firing twice.
  • Under-counting comes from dropped events and events that arrive after the billing cutoff.

The discipline of a billing test suite is to make over-counting structurally impossible and to make under-counting detectable and recoverable. That framing comes from the same source, and it should drive your test plan: every test you write targets one of those two directions.

A useful consequence: your tests are not checking "does the code do what it says" but "is the number that reaches the invoice defensible in a dispute." A forum analysis of metered API billing makes the same point, that invoices must stand up to audit and dispute, which is why flat request counts are not enough and why events must be immutable and replayable (metered API billing).

Usage-based billing itself is now mainstream enough that metering bugs are a revenue line item, not a curiosity. Stripe cites a January 2025 survey in which 85% of SaaS companies had adopted usage-based pricing, with 78% of those adoptions happening between 2020 and 2025 (Stripe on usage-based pricing). Other sources put adoption lower, around 46% of SaaS companies per OpenView data cited by m3ter (m3ter's usage-based pricing guide), which is a good reminder to check the survey behind any adoption number before you quote it to your board.
Step 1: Build a replayable, append-only event log

Before you can test aggregation, you need a log you can feed back through the aggregator deterministically. Three properties matter.

Immutable and append-only. Store raw events, never overwrite them. A practical architecture piece on metering recommends raw storage plus periodic rollups, and warns that discarding raw events costs you the ability to reprocess after an aggregation bug, which turns a recoverable engineering mistake into an unrecoverable revenue problem (metering infrastructure). A hybrid of raw plus rollups keeps read costs low while preserving exact replay.

A stable identifier generated at the source. The identifier only works if the same logical event carries the same identifier across every retry. This is the rule teams get wrong most often: if you mint a fresh UUID inside the HTTP client's retry loop, every retry looks like a new billable event. Mint the ID where the billable action happens, make it deterministic where a natural key exists (request ID, job ID, inference call ID), and never encode mutable state into it, per the usagebox guidance (idempotent usage metering).

Schema discipline. An event needs at minimum a customer identifier, metric name, quantity, effective timestamp and the ID. m3ter's ingestion guide lists schema validation and evolution as one of the core hard problems of usage ingestion, alongside volume, deduplication, late events and multi-tenancy (m3ter ingestion guide).

A minimal schema you can test against:

{
  "event_id": "3f9c...uuid-or-hash",
  "customer_id": "cus_8812",
  "metric": "api_requests",
  "quantity": 1,
  "effective_at": "2026-03-04T11:02:31Z",
  "received_at": "2026-03-04T11:02:33Z",
  "schema_version": 2
}

Keep effective_at separate from received_at. Tests that do not distinguish them cannot check late-arrival behavior.

Step 2: Adopt exactly-once processing, not exactly-once delivery

Exactly-once delivery across a network is generally treated as impractical, and Kafka's own documentation walks through why producer retries lead to duplicates, brokers can fail after writing but before acking, and correct semantics need cooperation between the messaging system and the client application (Confluent on exactly-once semantics). OpenMeter's stated trade-off is blunter and better for your design review: report usage twice and filter duplicates later rather than under-report.

So the testable contract is:

  1. Clients retry aggressively.
  2. Ingestion deduplicates ruthlessly on the stable ID.
  3. The resulting billable quantity is identical whether an event arrived once or five times.

A comparison of how established systems express the same idea:

SystemDedup fieldDedup window
Stripe meter eventsidentifierRolling period of at least 24 hours
OpenMeterCloudEvents id + source32 days by default
Lagotransaction_idPer event pipeline, paired with timestamp

These behaviors are summarized in the usagebox comparison of metering systems (idempotent usage metering). The decision rule that follows: your dedup window must be longer than your worst-case retry horizon. If a client can retry for 40 days (offline mobile agents, for example), a 24-hour window is a bug, not a policy.

For the mechanics of rejecting duplicates at the edge, a worked implementation pattern stores the event ID in an idempotency table in the same transaction as processing, then short-circuits on the next sighting (idempotency in event processing). For append-only sinks where an upsert is not available, deduplicate at read time with a window function, partitioned by the natural key and ordered by ingestion time (idempotency in streaming pipelines).

Step 3: Design golden test cases for counts and aggregations

A golden test case is a small, hand-verified input that produces a known, hand-calculated output. Never derive the expected value by running the code. Write it in a spreadsheet first, then freeze it in the test.

The aggregation function determines what "correct" means, and each one needs its own golden cases. Ordway's breakdown of event metering lists six functions: count, sum, unique count, max, latest value and weighted sum (event metering for usage-based billing). Here is a worked example for a customer on a graduated plan, 7.2 million API calls in a month, with 1 million included and graduated rates of $0.30 per thousand for the next 4 million and $0.25 per thousand above that:

BandUnitsRate per 1,000Charge
Included1,000,0000$0
1,000,001 to 5,000,0004,000,000$0.30$1,200
5,000,001 to 7,200,0002,200,000$0.25$550
Total7,200,000$1,750

Now compute the same usage under volume pricing, where the rate for the highest tier reached applies to all units. If the tier covering 5,000,001 and above is $0.15 per thousand, the volume bill is $1,080. The usage is identical; the rule moves the number. Lago makes this point with its own example, where the same usage produces $2,650 under graduated overage and $2,050 under volume pricing, a $600 difference from the pricing rule alone (Lago's usage-based billing guide).

Your golden suite should include at least:

CasePurpose
Tier boundary, exactly at the cutoffOff-by-one in band assignment
One unit above the cutoffRate switch correctness
Zero usageEmpty aggregate, no null crashes
Single huge quantity eventQuantity vs event count confusion
Unique count with repeated IDsDistinct semantics
Late event inside the grace windowAccepted and billed to the right period

Each case gets an input file, the hand-calculated expected quantity and charge, and a tolerance of exactly zero, not a percentage.

Step 4: Inject faults and verify idempotency

This is where most suites are thin. You have golden cases for the happy path; now break the pipeline on purpose and assert the bill does not move.

Build a fault harness with these scenarios, each with a defined expected outcome:

  • Duplicate delivery. Send the identical event N times with the same ID. Expected: billed quantity unchanged, N-1 marked duplicate.
  • Retry after acknowledged write. Simulate a lost ack: the pipeline succeeded but the client retried. Expected: no double count.
  • Mid-stream consumer restart. Kill the consumer after processing but before committing. Expected: replay happens, dedup absorbs it.
  • Out-of-order arrival. Deliver effective timestamps out of sequence. Expected: aggregation by effective time produces the same total.
  • Late event inside the grace window. Expected: counted in the current period. The practical architecture guidance recommends a grace window, typically 24 to 72 hours, and billing on effective timestamp, not ingestion timestamp (metering infrastructure).
  • Late event outside the grace window. Expected: bucketed to the next period or flagged, never silently dropped.
  • Poison event. A malformed payload. Expected: quarantined with an alert, not a silent skip and not a pipeline stall.

The property to assert across all of them is a single number: the aggregate output must equal the golden value. Write the assertion once, parameterized over the fault scenario, so adding a fault does not mean writing a new checker. That is the practical form of idempotency testing, and Streamkap frames it the same way: idempotency means producing the same result however many times the operation is applied, which is why it beats chasing guarantees you cannot get (idempotency in streaming pipelines).

If your team builds the metering layer alongside an AI product and needs the model calls themselves working before metering matters, Quanta Inference gives you text, image, video, audio and embedding models behind one OpenAI-compatible key, priced in US dollars, so you can exercise the pipeline with real traffic (https://quantaintelligence.ai/inference).

Step 5: Reconcile against a shadow ledger

Golden tests prove the logic is right for the inputs you thought of. Reconciliation proves the running system agrees with itself on inputs you did not think of. Build it as a separate service with its own alerting, independent of the billing service, so a bug in one does not blind the other.

Three numbers, compared every period before invoicing:

ComparisonGap meansAction
Source count vs pipeline countPipeline loss or ingestion bugInvestigate before close
Pipeline count vs billed countRating or aggregation logic errorBlock the invoice
Shadow ledger total vs invoiced totalDrift between the two computationsFreeze and reconcile line by line

The source count comes from application logs or a secondary event sink. The recommended alert threshold in the architecture guidance cited above is any discrepancy above 0.1 percent, which is a reasonable default to adopt and tune (metering infrastructure). A QA framework piece describes the failure this catches in the wild: a metering database and invoicing system disagreeing by just under 2% for a quarter, with no way to tell whether it was uncollected revenue, double billing or both (usage-based billing testing).

Run the shadow ledger as a second, deliberately naive computation: plain counts from raw events, no rollups, no optimization. If the fast path and the slow path disagree, the slow path is the one you can defend in a customer conversation.

Step 6: Stage the pre-launch checklist

Before the first real invoice, run a full dress rehearsal on a fixed dataset with known answers:

  1. Load a synthetic month of raw events, including duplicates, late arrivals and out-of-order timestamps, with the expected total computed by hand.
  2. Replay it through the production aggregation code, not a test double.
  3. Replay it again with the rollups deleted, and confirm the total is identical.
  4. Run the shadow ledger against the same dataset and confirm all three counts match.
  5. Change one aggregation rule, replay, and confirm you can explain the entire delta.
  6. Send the invoice to a sandbox billing system and reconcile the invoice lines back to raw events, event by event.

If any step requires reading code to explain a discrepancy, you are not ready. The test suite should be able to explain the delta without a human.

FAQ

FAQ

How many events do I need in a golden test case?

Five to twenty. Small enough that a person can count the expected output by hand and defend it in a spreadsheet, large enough to cross at least one tier boundary. Volume lives in load tests, correctness lives in golden cases.

Do I need exactly-once delivery to bill correctly?

No, and trying to get it is usually the wrong investment. Aim for at-least-once delivery with exactly-once processing: aggressive client retries plus deduplication on a stable identifier at ingestion. Test that the bill is unchanged when the same event arrives five times.

How do I test late-arriving events?

Record the effective timestamp separately from the receipt timestamp, define a grace window (24 to 72 hours is a common range), and write two tests: one event inside the window that must be counted in the current period, and one outside that must be routed to the next period or flagged. Never let either case be silently dropped.

What is the difference between a golden test and reconciliation?

A golden test proves your aggregation logic is correct for an input you designed. Reconciliation proves the live system's three counts agree on inputs you did not design. You need both, and the reconciliation job must run independently of the billing service.

When should I bring in outside help for this?

When metering correctness is blocking revenue recognition and you do not have a dedicated owner for the seam between the metering pipeline and the billing platform, which is where most of the leakage happens. A free 30-minute discovery call can scope whether the gap is ingestion, aggregation or reconciliation before you commit engineering time (https://quantaintelligence.ai/calendar).

Sources

Sources

  1. Idempotent Usage Metering: Safe Retries, Dedup & Late Events
  2. Metered API billing: where telemetry, idempotency and invoices meet
  3. What Is Usage-Based Pricing? - Stripe
  4. Usage-based pricing: The ultimate guide - m3ter
  5. Usage-based pricing: the metering infrastructure nobody talks about
  6. Usage Data Ingestion for SaaS Usage-Based Billing - m3ter
  7. Exactly-Once Semantics Are Possible: Here's How Kafka ...
  8. Idempotency in event processing - Medium
  9. Idempotency in Streaming Pipelines: Exactly-Once Without ...
  10. How to Implement Event Metering for Usage-Based Billing - Ordway Labs
  11. Usage-Based Billing: How It Works, Models & Examples (2026) - Getlago
  12. Usage-Based Billing Testing: A QA Framework for SaaS
About the author

About the author

Antonio Evans
Antonio Evans

Antonio Evans is the founder of Quanta Intelligence and a fractional CTO who builds HIPAA-ready AI systems for health and life-science companies. Before that he was technical co-founder of FriendsEAT for twenty years, CEO of Socialdraft, and a data engineer at IBM. Antonio lives with his dog Santino in Lisbon, Portugal.

All articles