
Marketing

How to Write a Revision Prompt That Returns a Diff, Not a Rewrite

Antonio Evans10 min read

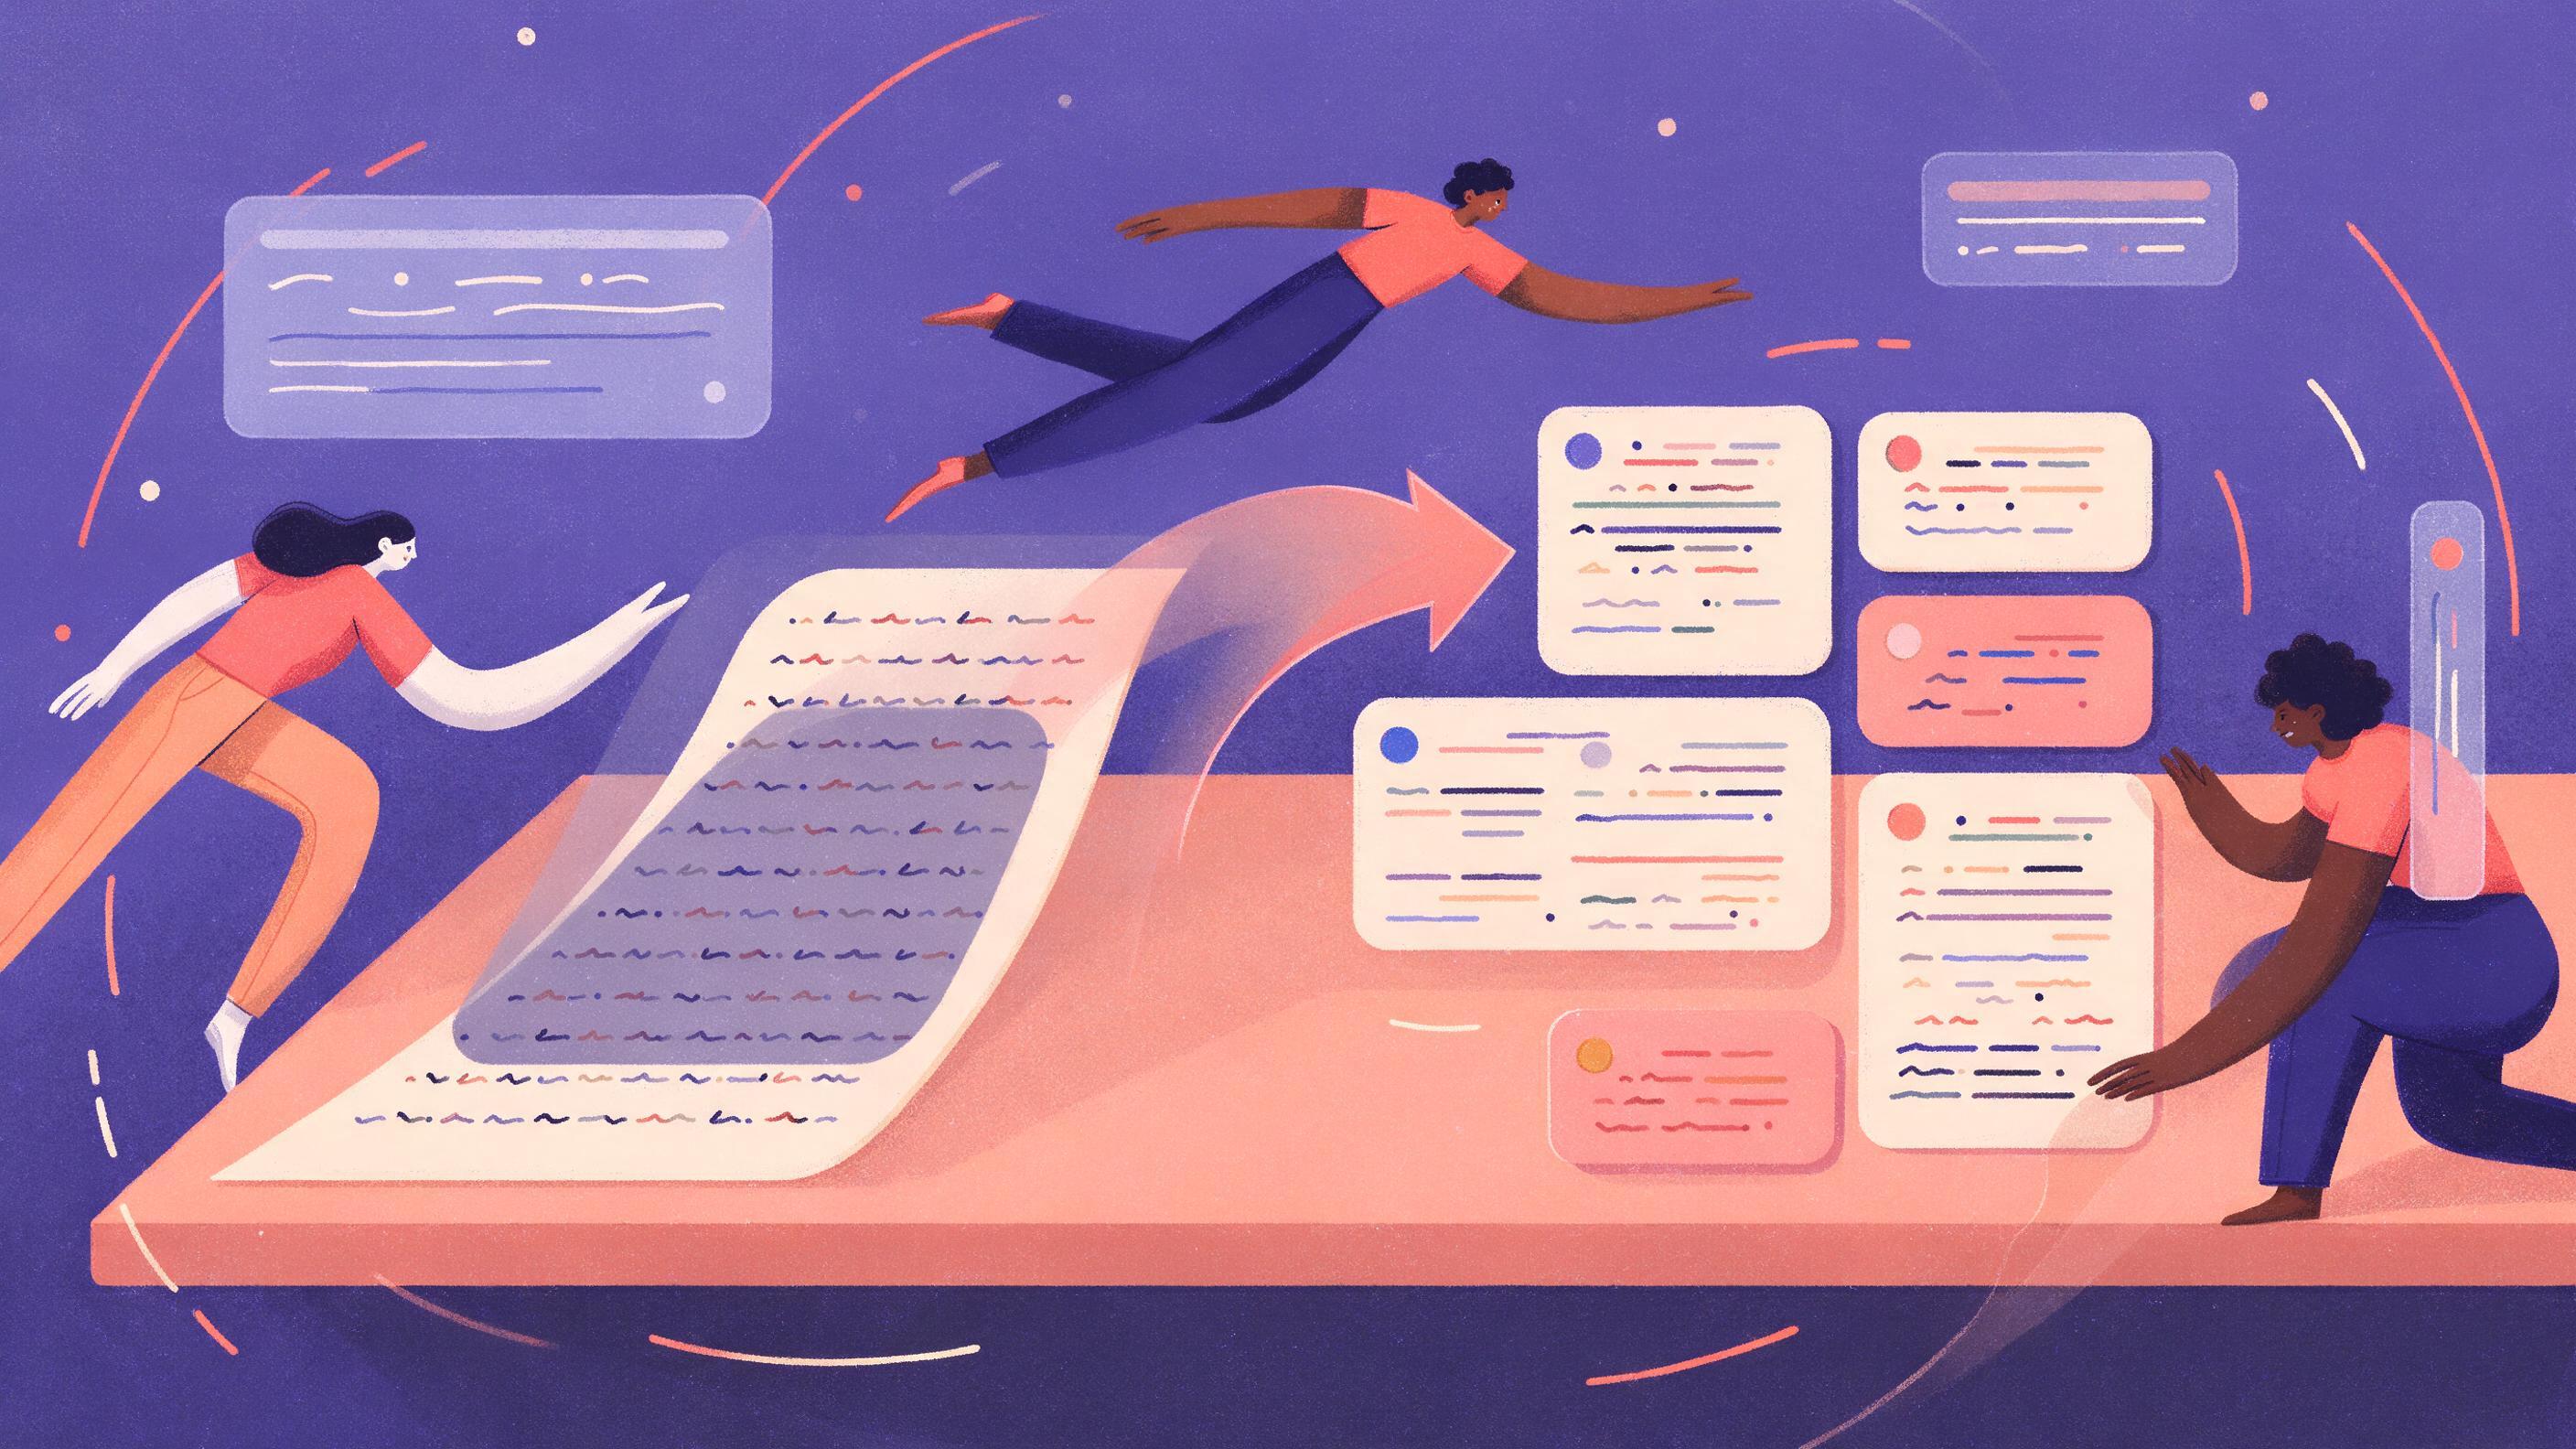
A split scene on a desk: on the left, a long dense draft page with a heavy gray highlight over the whole block; on the right, the same page chunked into numbered cards.
Key points

Key points

  1. 1A rewrite prompt hands back a whole new text that you must reread, while a revision prompt hands back a numbered list of edits you approve one at a time.
  2. 2The revision prompt needs three parts: the source text, a narrow goal that bounds what may change, and a schema where each item quotes the exact original sentence plus its replacement.
  3. 3Review becomes a sequence of yes or no decisions by item number, and a spot check confirms that nothing outside the list was altered.
  4. 4Two metrics tell you whether the pattern works: review time per thousand words and the share of proposed edits you accept.

Why a rewrite hides the meaning shifts

A full rewrite looks like progress. The prose comes back cleaner, the sentences are smoother, and the whole thing is grammatically tighter than what you sent. The problem is that a rewrite is a swap, not an audit. You get one new document and no record of what changed between the old one and the new one, so every semantic drift has to be caught by rereading both versions side by side.

Meaning shifts are exactly the kind of change a fluent model produces without flagging. Editors who work on AI drafts note that the writing arrives grammatically perfect but built on shaky foundations, so the polish itself suppresses scrutiny: the clean surface makes readers assume the substance was checked too (Briefer's editing checklist). A model told to "improve this paragraph" will happily soften a firm claim into a hedge, drop a qualifier, or promote a correlation into a cause, and nothing in the output marks those moves as decisions.

The hedging habit is a concrete example. Chat models hedge by default because human raters rewarded cautious-sounding answers during training, and OpenAI's own researchers noted early that the model could "overly hedge" even when one answer was clearly right (Leap on hedging in AI text). Ask for a rewrite and you inherit that caution silently. Ask for a diff and the hedge shows up as item 4, with the original sentence printed next to it, and you can reject it in two seconds.

There is also an accountability argument. Once you publish, you are responsible for every claim in the text, and a model's assurance that it "preserved meaning" is not evidence. Regulators already treat AI involvement in content as something a reader may need to know about, and the FTC applies its existing deception rules to AI-generated material without carving out an exemption (FTC advertising and marketing guidance). A numbered edit list is the artifact that shows what you actually approved.

The structural habits of model prose make this worse. Models tend to produce symmetrical sections, heavy bullet use, and recaps that restate earlier points, and those patterns survive editing at the word level because the skeleton is never touched (Louis-François Bouchard on cleaning up AI drafts). If your revision process operates on whole paragraphs, you are accepting the skeleton along with the words. Operating on sentences keeps the skeleton visible.

The shape of a revision prompt: scope, schema, constraints

Three components do the work. Scope says what the edit is for and, just as important, what it is not for. Schema says what each output item must contain. Constraints say what the model may not do, including the rule that everything unchanged is omitted.

Scope should be one sentence and should name a single goal. "Tighten wordy sentences in the methods section without changing any factual claim" is a scope. "Make this better" is an invitation to rewrite. When you leave scope open, the model will fix things you did not ask it to fix, and you will not see those fixes because they arrive inside a new draft rather than as a numbered item.

Schema should be strict enough that a parser could read it. Structured output is the practice of requiring a fixed format, such as a numbered list or JSON with named fields, so downstream tools can process the result without manual cleanup (PromptQuorum on structured output and JSON mode). You do not need an API-level JSON mode to benefit, though it helps: the discipline of naming fields forces you to decide what an edit actually is.

Constraints are where the safety lives. The non-negotiable ones are: quote the original sentence exactly and character for character, give the replacement in full, change nothing that is not listed, and omit every sentence you are not changing. Add a rule that the model may not merge or split sentences, because merging two short sentences into one long one is the most common quiet meaning shift and it becomes invisible if the unit of change is a paragraph.

Here is a prompt you can paste and adapt. It assumes a single block of source text and a single goal.

You are revising a document. Do not rewrite it.

GOAL: [one sentence, e.g. remove hedging language without changing any claim]

SOURCE TEXT:
"""
[paste the full text here]
"""

RULES
1. Change only sentences that the GOAL requires you to change.
2. Do not merge, split, reorder or delete sentences.
3. Do not change any number, name, date, quotation or citation.
4. If a sentence needs no change, do not mention it.
5. If the GOAL cannot be met without changing meaning, say so in NOTES
   instead of making the change.

OUTPUT FORMAT
Return a numbered list. Each item has exactly four lines:
N. REASON: [one short clause naming the change, e.g. "cuts hedge"]
   OLD: [the original sentence, copied exactly]
   NEW: [the replacement sentence]
   RISK: [none | meaning | fact | tone]

After the list, add:
NOTES: [anything you declined to change and why, or "none"]

Two lines in that prompt earn their keep. The RISK field forces the model to classify its own edit, and items marked "meaning" or "fact" are the ones you read closely. The NOTES field gives the model a place to put refusals, which reduces the temptation to make a change it should not make and bury it in the body of the list.

If you are calling a model through an API, encode the same schema as JSON so the structure is enforced rather than requested. Community discussion of structured output makes the point that the schema description and the system instruction should reinforce each other rather than duplicate each other, with the field description explaining what belongs in that field (OpenAI community thread on structured output). A description like "OLD: the original sentence copied verbatim from the source, no edits of any kind" does more work than repeating the whole instruction set.

A worked example with numbers

Take a 60-word paragraph from a product announcement.

We are excited to announce that our new reporting dashboard is now available. It is important to note that the dashboard may help teams to identify trends more quickly. However, results can vary depending on data quality. Customers who used the beta reported that they saved time, and some said the export feature was useful. Ultimately, the right approach depends on your workflow.

Ask for a rewrite and you get something polished that keeps all five sentences and reads like the same paragraph wearing a suit. Ask for a revision with the goal "remove hedging language and stock openers, change no claims" and you get items you can judge individually.

#ReasonOld (excerpt)New (excerpt)Risk
1Cuts stock openerWe are excited to announce that our new reporting dashboard is now available.The new reporting dashboard is available.tone
2Cuts hedgeIt is important to note that the dashboard may help teams to identify trends more quickly.The dashboard helps teams identify trends more quickly.meaning
3Keeps as isHowever, results can vary depending on data quality.(not listed)none
4Cuts vague attributionCustomers who used the beta reported that they saved time, and some said the export feature was useful.Beta customers reported saving time; several praised the export feature.none
5Cuts reflexive closeUltimately, the right approach depends on your workflow.(not listed)none

Read item 2 closely. The original says the dashboard may help; the replacement says it helps. That is a meaning shift, it is flagged as such, and you reject it. Item 3 is deliberately absent from the list, which proves the model followed the omission rule. Item 4 is a compression that keeps the attribution ("beta customers reported") intact, so it is safe to accept even though the wording moved.

Now the numbers. Suppose the paragraph is 1 of 25 in a 1,500-word page. If a full rewrite takes 20 minutes to reread and verify against the original, the rewrite path costs 20 minutes for that page. The revision path produces roughly 25 to 40 items for a page of that length, and at 10 to 15 seconds per item (read old, read new, accept or reject) that is 4 to 10 minutes, plus 3 to 4 minutes for the spot check described below. The saving is real but modest on one page; it compounds because the accepted items become a review record you can hand to a second reader without them rereading the whole document.

The acceptance rate is the number that tells you whether your prompt is calibrated. If you accept fewer than half the items, your goal statement is too broad or the model is over-editing, and you should tighten scope before running it again. If you accept nearly everything without reading, you have rebuilt the rewrite problem with extra steps.

Approve by number, then check for off-list edits

Treat the list as a pull request. Read each item, decide, and record the decision by number: accept 1, reject 2, accept 4. Applying the accepted items is mechanical if you have the exact OLD strings, because a script can find each one and replace it. That is the practical reason the prompt insists on exact quotation: exact strings make the apply step deterministic instead of a judgment call.

The spot check is the step most teams skip. After applying the accepted items, diff the result against the original and confirm that every changed sentence appears in your accepted list. A sentence that changed but does not appear in the list is a rule violation, and it means the model edited outside its brief. Two cheap ways to run the check:

  • Sentence-level diff. Split both texts into sentences, compare, and print any pair where the original sentence is not identical to a NEW value you accepted. Expect a short list of zero to three lines.
  • N-gram scan. Hash every 8-word window in the original, hash every window in the output, and list windows that appear in one and not the other. This catches small word swaps inside otherwise identical sentences, which the sentence-level check will miss if you compare loosely.

The second check matters more than it sounds. Hedging edits are often one word. A model that swaps "can vary" for "varies" has changed a hedge into a claim inside a sentence that is otherwise byte-identical, and a sloppy comparison will wave it through. Editors who work on model prose report that hedge removal is one of the highest-value edits precisely because hedges carry information when they are real and carry nothing when they are reflexive (Leap's editing guidance). You want to see each one.

The apply-and-check loop is worth scripting once. A short Python sketch, assuming the model returns the four-line format:

import re

def parse_items(text):
    items = {}
    for block in re.split(r"\n(?=\d+\. REASON:)", text):
        m = re.match(r"(\d+)\. REASON: (.*?)\n\s*OLD: (.*?)\n\s*NEW: (.*?)\n\s*RISK: (.*)", block, re.S)
        if m:
            items[int(m.group(1))] = {"old": m.group(3).strip(), "new": m.group(4).strip()}
    return items

def apply(text, items, accepted):
    for n in accepted:
        if items[n]["old"] not in text:
            raise ValueError(f"item {n}: OLD not found verbatim")
        text = text.replace(items[n]["old"], items[n]["new"], 1)
    return text

The raise is the point. If the OLD string does not appear exactly as given, the item is not applicable, and you want to know that before it silently does nothing.

Metrics: review time and edit acceptance

Two metrics are enough to run this as a process rather than a preference.

Review time per thousand words. Record the start and end of review for each document. A useful target is a steady decline over the first ten documents as reviewers learn to read the four-line format quickly, then a plateau. If review time does not fall, the item count is probably too high, which points back to an over-broad goal.

Edit acceptance rate. Count accepted items divided by proposed items. Track it alongside a quality check: for each rejected item, note whether the rejection was because the edit was wrong (a meaning shift or a factual change) or because it was unwanted (a style preference). A rising share of wrong-edit rejections means the model is drifting outside the goal; a rising share of unwanted-edit rejections means your goal statement is too vague.

MetricHow to measureWhat a bad reading means
Review time per 1,000 wordsTimestamp at start and end of reviewItem count too high; narrow the goal
Acceptance rateAccepted items / proposed itemsBelow 50 percent, the goal is too broad
Wrong-edit shareRejections due to meaning or fact / all rejectionsModel is overreaching; tighten constraints
Off-list changesSentences changed but absent from the accepted listModel ignored the omission rule; re-run with a stronger constraint
Time to applyMinutes to apply accepted itemsOLD strings not verbatim; fix the prompt

Track one more number for the business case: the share of documents that need a second human reader. A clean edit list gives the second reader something to review instead of a whole draft, and that is where the time savings usually show up, not in the first reviewer's stopwatch.

When a diff is the wrong tool, and how to scale it

The revision pattern fits editing with a stated goal: hedging, clarity, tone, house style, plain-language conversion. It fits badly when the task is genuinely generative, such as restructuring an argument or writing a section that does not exist yet, because there is no original sentence to quote. In those cases you are drafting, not revising, and the diff format will either force the model into awkward sentence-level surgery or produce a list of items that add up to a rewrite anyway. Decide which task you are doing before you write the prompt.

The pattern also fits badly when the source is short enough that a full reread takes less time than reading the list. Below roughly 200 words, just read the output.

Above that, the pattern scales well because the list is machine-readable. If you process documents in bulk, one model call can produce the edit list and a second call can adjudicate items flagged as "meaning" or "fact", which is a natural place for a single API across model families, such as Quanta Inference, rather than stitching providers together yourself. For teams that want the whole revision loop handled as a finished deliverable, with a specialist reading the document rather than a template, Quanta Experts runs that kind of work end to end.

One more scaling note: keep the prompt versioned alongside your style guide. When the house style changes, the goal sentence changes, and the acceptance-rate history tells you whether the new goal is calibrated before it reaches every document in the queue.

FAQ

FAQ

Why not just ask the model to output the full revised text and track changes?

Because a full revised text gives you one artifact to compare and no record of intent. You cannot tell whether a changed sentence was a deliberate edit or a side effect, and every drift must be caught by reading both versions. A numbered list makes each change a separate, labeled decision.

What if the model refuses to quote the original sentence exactly?

That is a signal, not a nuisance. An inexact OLD string usually means the model paraphrased instead of copying, which breaks your apply step, so the correct response is to re-run with a stricter instruction and reject the malformed item. If it happens repeatedly, lower the temperature and put the exact-copy rule as the first constraint rather than the third.

How many items should a revision prompt return for a 1,000-word document?

It depends on the goal, but a useful working range is one item per 40 to 80 words, so roughly 12 to 25 items per thousand words for a focused goal like hedge removal. Far more than that suggests the goal is too broad; far fewer suggests the model is being lazy and you should check for off-list changes.

Which risk categories are worth having?

Three are enough for most teams: meaning, fact and tone. Meaning covers any change to what the sentence asserts, fact covers numbers, names, dates and citations, and tone covers voice and register. Items marked meaning or fact deserve a full read; tone items can be skimmed.

Does this pattern work for structured or regulated content?

It works better there than a rewrite does, because every change is attributable and reviewable, but it does not replace legal review. Regulators apply existing truth-in-advertising and disclosure rules to AI-assisted content, and the FTC expects claims in advertising to be truthful and evidence-based (FTC advertising and marketing basics). Keep the approved edit list as your record of what changed and who accepted it.

Sources

Sources

  1. AI Content Editing Checklist: 15 Steps Before You Publish
  2. Hedging Words in AI Text: Why 'It's Important to Note' Flags | Leap
  3. Advertising and Marketing | Federal Trade Commission
  4. How to Clean Up AI-Generated Drafts Without Sounding Like ChatGPT
  5. Structured Output & JSON Mode in LLMs: When to Use, Examples
  6. How to effectively prompt for Structured Output
About the author

About the author

Antonio Evans
Antonio Evans

Antonio Evans is the founder of Quanta Intelligence and a fractional CTO who builds HIPAA-ready AI systems for health and life-science companies. Before that he was technical co-founder of FriendsEAT for twenty years, CEO of Socialdraft, and a data engineer at IBM. Antonio lives with his dog Santino in Lisbon, Portugal.

All articles
