
Development

Isolation Levels: Picking One and Testing Your Code Tolerates It

Antonio Evans9 min read

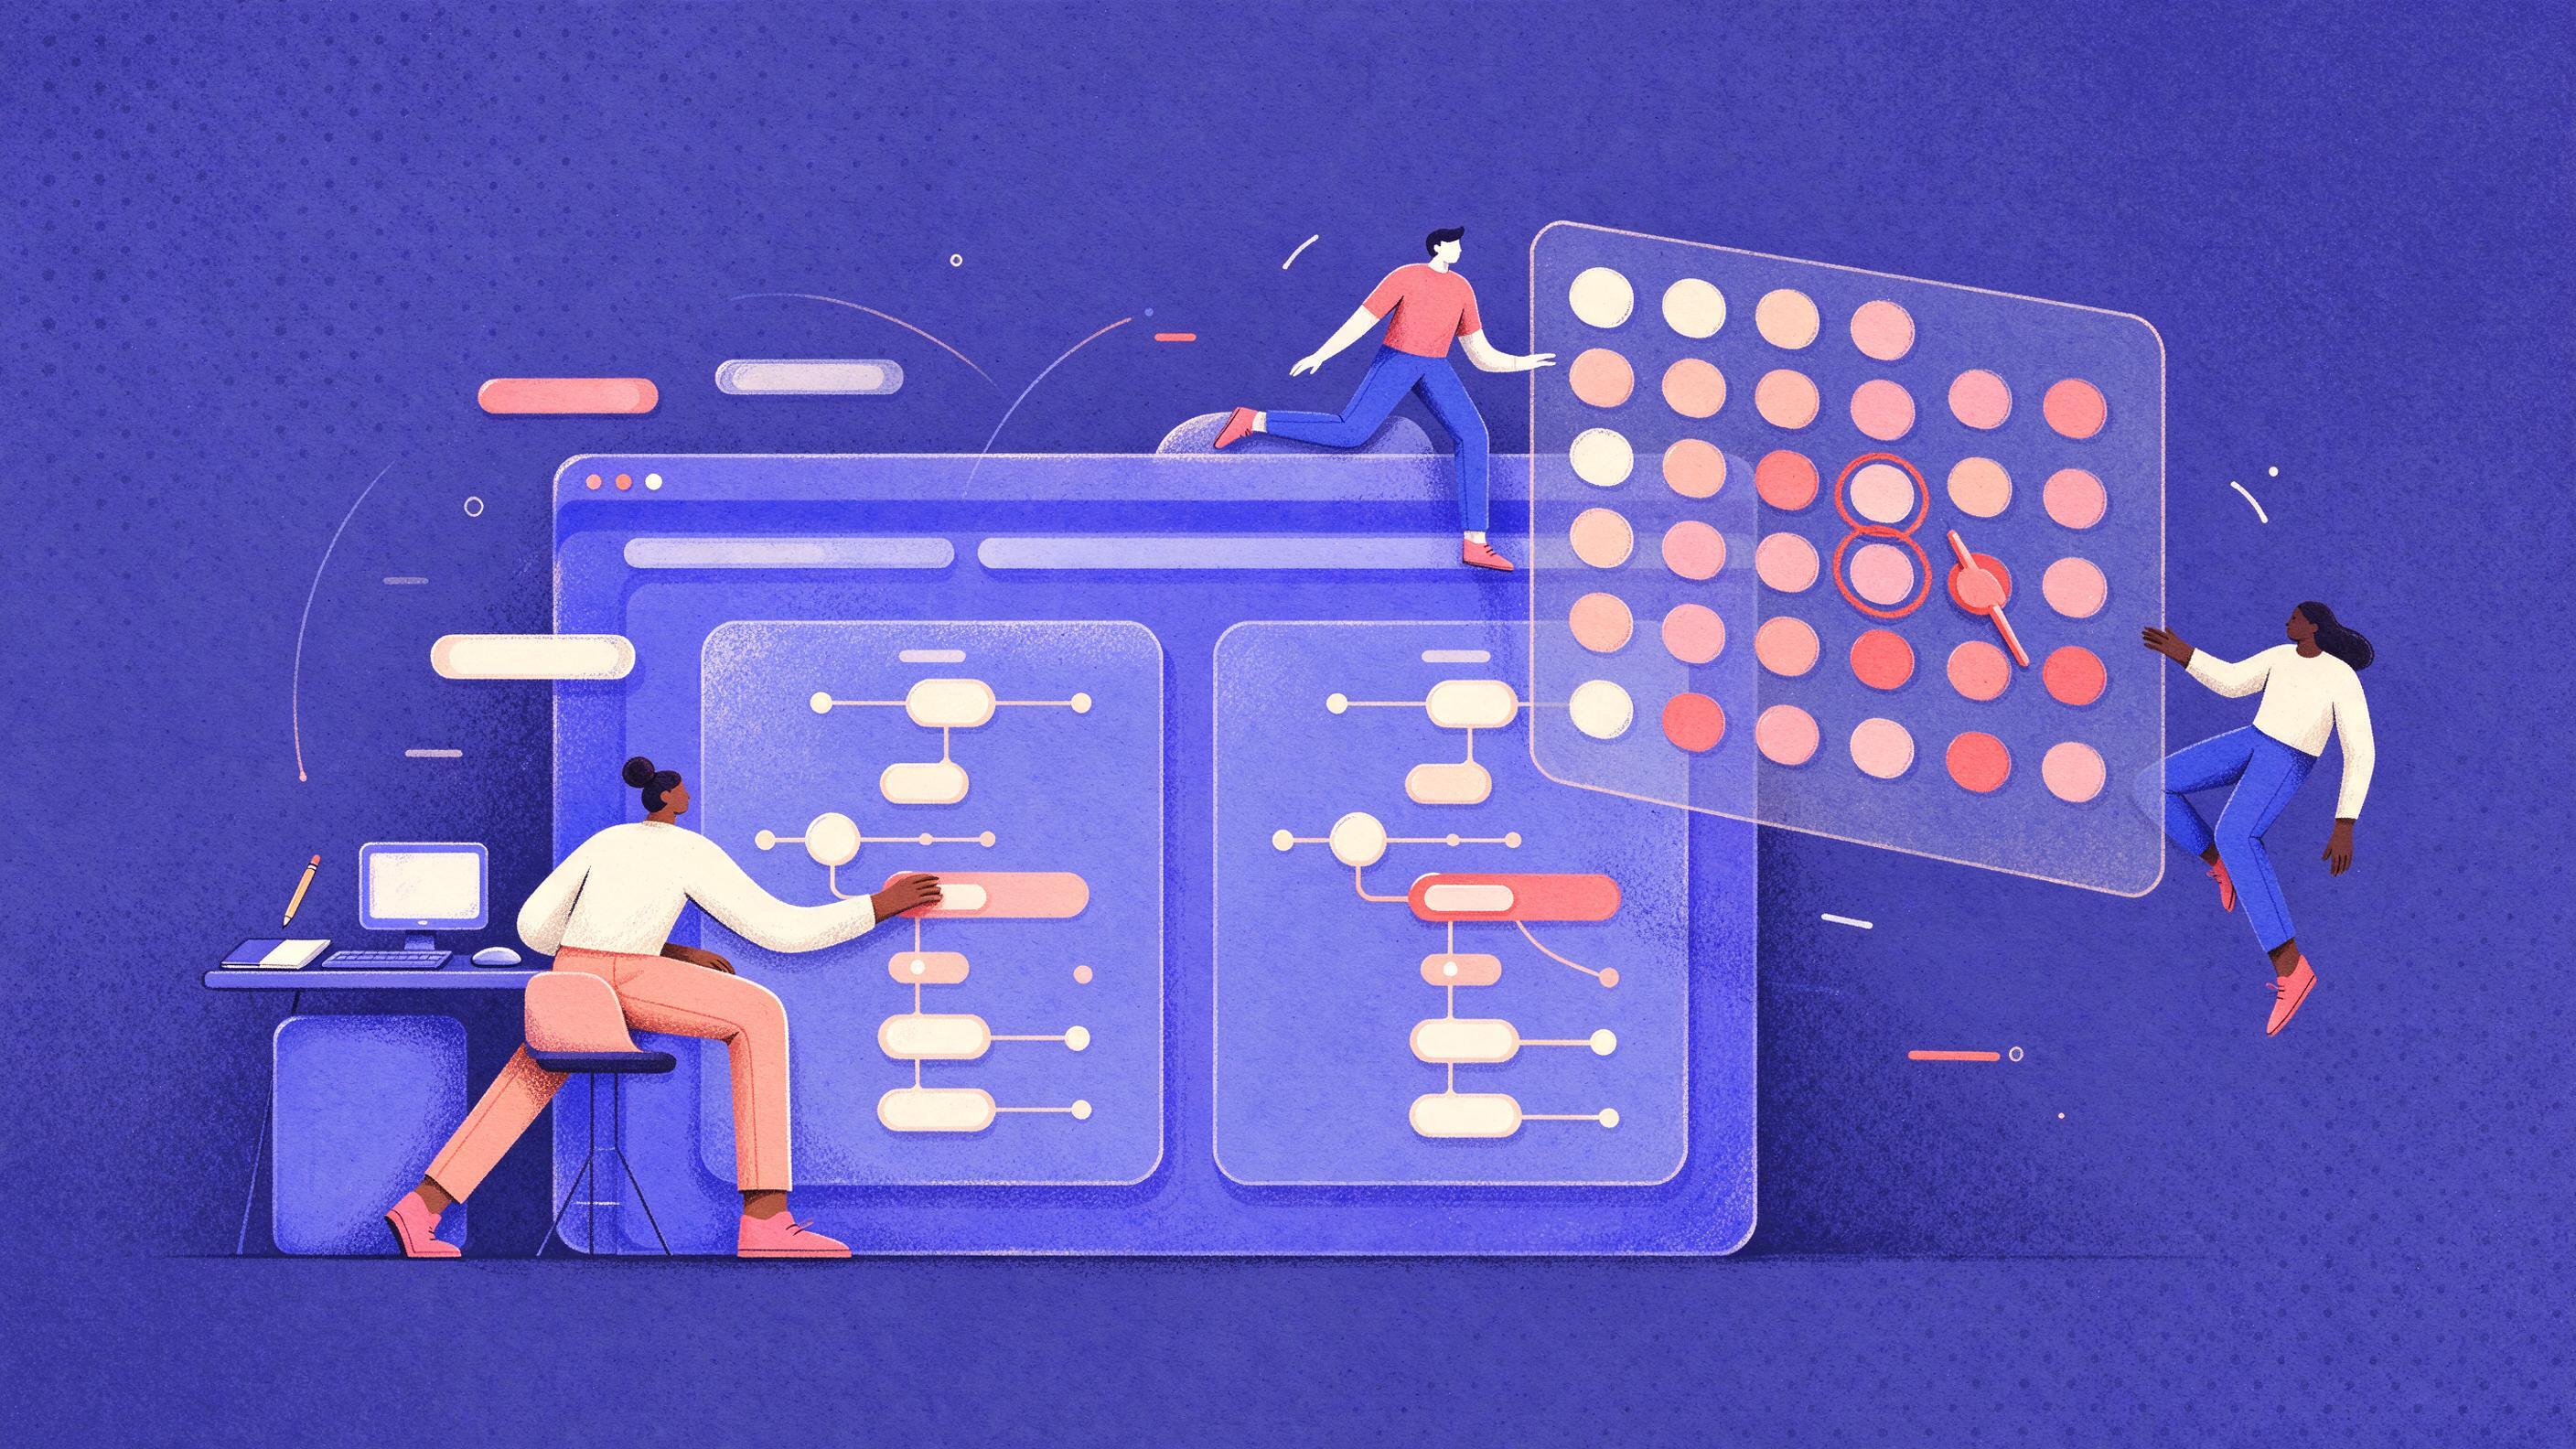
A developer at a desk with two database session timelines open side by side, one read highlighted for returning a different value, and a wall grid mapping isolation levels to anomalies with one cell circled for testing.
Key points

Key points

  1. 1Pick the weakest isolation level whose permitted anomalies cannot break your stated invariants, then test that your code survives the anomalies the level still allows.
  2. 2Map each invariant to a concrete anomaly: read-modify-write maps to lost update, range queries map to phantom reads, and cross-row constraints map to write skew.
  3. 3Proving a concurrent bug requires forcing an interleaving with two sessions and barriers, not running a query twice in a loop.
  4. 4Serialization failures are a normal outcome under strict levels, so retry logic and lock acquisition must be tested and asserted, not assumed.

Start from invariants, not from a level

Most teams pick an isolation level the way they pick a color: by feel. A better procedure is to write down the invariants the data must satisfy at every commit boundary, then work backwards to the weakest level that protects them. An invariant is a statement that must be true of the database whenever no transaction is in flight: "no two active users share an email", "the sum of debits equals the sum of credits", "at least one doctor is on call for each shift".

The SQL standard defines isolation levels in terms of the phenomena they prohibit, from dirty reads up through serialization anomalies the PostgreSQL transaction isolation docs. That framing is convenient for the standard but awkward for application developers, because it describes what the database stops rather than what your code needs. Flipping the direction is what makes the decision tractable: instead of asking "what does repeatable read prevent", ask "which anomaly would violate my invariant, and does this level permit it".

A useful sort order for the anomalies, weakest first:

AnomalyWhat breaksTypical trigger
Dirty readReads see data that may roll backReading uncommitted writes from another session
Nonrepeatable readTwo reads of the same row disagreeBusiness logic that re-reads a value mid-transaction
Lost updateOne write silently overwrites anotherRead-modify-write on a counter or balance
Phantom readA re-run query returns a different row setRange checks, "count then insert" patterns
Write skewCross-row constraint violated by two valid-looking transactionsOn-call rules, inventory holds, double-booking checks
Serialization anomalyOutcomes impossible under any serial orderCyclic dependencies between concurrent transactions

The distinction between anomalous reads and anomalous writes matters more than the table suggests. Write skew is a write anomaly: two transactions each read a set of rows, each makes a change that is locally valid, and the combination violates the invariant. The hospital on-call example is the canonical case, where two doctors each check that at least one other doctor is on call, then both cancel their shift a write-up of write skew on Cockroach Labs' blog. Every transaction is internally consistent; the pair is not.

Decision rule: if an invariant spans more than one row or more than one statement, a lost-update prevention is not enough. You need either a level that detects write skew (serializable), or explicit locking that serializes the conflicting transactions, or a design change that collapses the multi-row check into a single-row constraint the database can enforce for you.

Map your workload patterns to anomalies

Some access patterns are hot spots for particular anomalies. Three recur so often that they deserve names.

Read-modify-write. SELECT balance FROM accounts WHERE id = 1, add to it in application code, UPDATE accounts SET balance = $new WHERE id = 1. Under read committed, two concurrent executions can each read the same starting balance and each write their own result, and one increment disappears. This is a lost update. The fix at read committed is to make the write atomic (UPDATE ... SET balance = balance + $delta) or to take a row lock with SELECT ... FOR UPDATE. Under repeatable read, PostgreSQL detects the conflict and aborts one transaction, which is why it is often described as preventing lost updates a Stack Overflow explanation of repeatable read and write skew. Note that repeatable read prevents lost updates but not write skew, and the difference matters when you choose.

Range queries and phantoms. SELECT count(*) FROM bookings WHERE room = 7 AND day = 'monday' followed by an insert if the count is below capacity. A concurrent insert slips a new row into the range between the count and the insert. This is a phantom. Under read committed, nothing prevents it. Under repeatable read in PostgreSQL, the snapshot is stable within the transaction, but phantom protection depends on the engine: PostgreSQL's repeatable read also blocks phantoms, while the SQL standard permits them at that level.

Cross-row constraints. A check that reads row A, then writes row B, where a concurrent transaction reads B and writes A. Neither transaction touches the same row as the other, so neither lock nor update conflict detects the problem. Only serializable snapshot isolation, which tracks read-write dependencies and aborts on dangerous structures, catches this. PostgreSQL implements this as Serializable Snapshot Isolation, an enhancement over plain snapshot isolation that detects serialization anomalies and aborts one of the transactions a comparison of repeatable read and snapshot isolation.

Worked example: a billing service moves money between accounts and also enforces a rule that no customer may have more than three pending transfers. The transfer update is a read-modify-write on two rows (needs lost-update protection). The pending-transfer rule is a count over a range (needs phantom protection). A concurrent pair of transfers can each see two pending transfers and each insert a third, leaving four (needs write-skew protection if the rule is checked with a count). The correct choice is serializable for the transfer path, with retry-on-serialization-failure in the application.

Set the level per transaction, not per database

Modern engines allow setting isolation per transaction. In PostgreSQL the syntax is BEGIN ISOLATION LEVEL SERIALIZABLE, and the session default is read committed. That default is fine for read-only endpoints and most reporting queries; it is dangerous for the transfer path. The sane policy is a default at the connection or session level and an explicit override at the top of every transaction that writes.

A rough decision matrix:

WorkloadDefault writesRange checksCross-row constraintsRecommended level
Content reads, analyticsNoneNoneNoneRead committed
Single-row countersAtomic updateNoneNoneRead committed
Read-modify-write on balanceYesNoneNoneRepeatable read + retry
Booking with capacity checkYesYesYesSerializable + retry
Inventory with reservationYesYesYesSerializable + retry, or explicit locks

Two practical notes when you set the level per transaction. First, your connection pooler can interfere. In transaction pooling mode, PgBouncer hands the server connection back to the pool when the transaction ends, and SET/RESET and session-level features do not work the way clients expect PgBouncer's feature matrix. A session-level isolation default set on the client may therefore apply to a different physical connection than the one you expect. Set isolation at the start of each transaction (BEGIN ISOLATION LEVEL ..., SET TRANSACTION ISOLATION LEVEL ...) and use Heroku's guidance on running PgBouncer without breaking session semantics the Heroku PgBouncer best-practices guide. Second, drivers expose the level per transaction too, and ORMs often hide it behind connection options or a transaction wrapper; check what the ORM actually sends before assuming it is what you configured.

Another cost to keep in mind: stronger isolation means more aborts and lower throughput under contention. That is the price of correctness on paths that need it. Leaving it strict everywhere charges that price on endpoints that never needed it.

Build a test matrix that reproduces each anomaly

The point of testing isolation is not to demonstrate that your database behaves correctly. It is to demonstrate that your application behaves correctly when the database permits the anomaly you did not pay to prevent. A test that runs the "safe" path under serializable proves nothing about your retry logic; a test that runs the unsafe path under read committed and asserts your locks or atomic updates save you proves a lot.

For each invariant, create three tests:

  1. A unit test that exercises the happy path under the production isolation level.
  2. A concurrency test with two sessions that forces the interleaving which would break the invariant, asserting that either the database aborts one transaction or your application code prevents the bad outcome.
  3. A retry test that asserts the transaction is retried on serialization failure, with a bounded number of attempts and a clear error when exhausted.

The core technique is two independent database sessions and barriers between steps. In pytest with psycopg, the barrier is a pair of threading events:

import threading, psycopg

def test_lost_update_prevented(conn_a, conn_b):
    a_read = threading.Event()
    b_write = threading.Event()

    def tx_a():
        with conn_a.transaction():
            with conn_a.cursor() as cur:
                cur.execute("SELECT balance FROM accounts WHERE id = 1 FOR UPDATE")
                bal = cur.fetchone()[0]
                a_read.set()
                b_write.wait()
                cur.execute(
                    "UPDATE accounts SET balance = %s WHERE id = 1",
                    (bal + 10,),
                )

    def tx_b():
        a_read.wait()
        with conn_b.transaction():
            with conn_b.cursor() as cur:
                cur.execute("UPDATE accounts SET balance = balance + 10 WHERE id = 1")
                b_write.set()

    thread_b = threading.Thread(target=tx_b)
    thread_b.start()
    tx_a()
    thread_b.join()

Without FOR UPDATE, the assertion that the final balance is initial + 20 fails intermittently, which is exactly the bug you are hunting. With it, session B blocks until A commits, and the assertion holds. Note the two assumptions the test makes: FOR UPDATE actually locks the row, and the driver uses the same physical connection for the whole transaction. If the pooler runs in transaction mode, the second session may be issued on a server connection that sees A's lock from another client, which makes the test pass or fail for the wrong reasons. Run these tests against the same pooling configuration as production. If you want to check the queries themselves use the intended path, EXPLAIN ANALYZE shows the plan and actual timings the PostgreSQL Using EXPLAIN docs, and a walk through of reading the output is available from Thoughtbot reading a Postgres EXPLAIN ANALYZE plan.

Assert that retries and locks actually recover

A concurrency test that expects an exception is only half the job. You also need to assert that the failure is the one you expect (serialization failure, deadlock detected, lock timeout) and that the application's retry path turns it into a committed result.

def test_serialization_failure_is_retried(session, attempts=3):
    for i in range(attempts):
        try:
            with session.transaction() as tx:
                tx.execute("ALTER TABLE accounts SET ( autovacuum_enabled = false )")
                # ... the conflicting work ...
                tx.commit()
            return
        except psycopg.errors.SerializationFailure:
            continue
    raise AssertionError("serialization failure exceeded retry budget")

Three properties make a retry test trustworthy. First, it must not swallow other exceptions: catching only the serialization failure class avoids hiding a real bug as a retry. Second, the retry budget must be enforced, not infinite. Third, you should log the attempt count so a test suite that always retries three times is visible as a signal that something is contended, not as a silently passing suite.

Locks need their own assertions. A test that takes a row lock in one session and asserts that a second session blocks until the first commits proves that the lock is held for the duration of the transaction, not just the statement. A test that takes the lock and asserts a timeout proves that your timeout is set and that the application surfaces a clear error rather than hanging. Both belong in the suite if your code relies on SELECT ... FOR UPDATE or advisory locks.

While tests are running, EXPLAIN ANALYZE can also reveal whether the planner is choosing the access path you expect, which matters when a lock or isolation change shifts the plan. Seq scans and index scans behave differently under concurrent writes, and the plan tells you which one you got. For a walk through the basics, see Crunchy Data's guide explaining Postgres query performance.

If you run a fleet of services against shared databases, the test matrix tends to become a central concern rather than a per-service one. It is the kind of thing an AI expert for a line of business can take on as a standing task rather than a one-off review, and it maps well to the specialist model at Quanta, where a described problem gets picked up and built out with you.

Complexity, cost, and the cases where you lower the level

Stronger isolation is not free. Serializable transactions can abort under contention, and the application must retry. The retry loop shifts load back to the client, and under sustained conflict the aborts can outnumber the commits. That is fine if the invariant requires it and not fine if it does not.

Decision rule for lowering the level: identify every invariant whose violation would require manual correction or a customer-visible apology. Keep those paths at the level that protects them. For everything else, read committed is usually the right default, with atomic updates replacing read-modify-write and explicit locks replacing implicit ones.

A worked trade-off. A ticket-sales service uses serializable for the seat-allocation path and read committed everywhere else. Under load, the allocation path aborts and retries on some fraction of requests; the retry absorbs it, and the invariant "no seat is sold twice" holds. The reporting path, at read committed, sees a slightly inconsistent snapshot across tables if it runs several queries. That is acceptable because the report is published and reconciled later. Reversing the two choices would produce slow reports and oversold seats, which is the worst of both.

The same logic applies to key uniqueness. If two concurrent inserts attempt the same unique key, one will fail at commit under most levels, and your application must handle the unique-violation error rather than crashing. A unique index is the cheapest constraint in the system and the most reliable, because the database enforces it without requiring a specific isolation level from the client. Choosing a level does not substitute for a database-enforced constraint when one exists; use both.

FAQ

FAQ

Is serializable always the safe choice?

No. Serializable protects every invariant, but it also raises the rate of serialization failures under contention, and those failures must be retried correctly. If your retry logic is untested or missing, serializable can turn a performance problem into an availability problem. Choose the weakest level that protects your invariants, and use serializable where the invariant genuinely requires multi-row protection.

Why did my repeatable read test still allow a write skew?

Repeatable read guarantees a stable snapshot and, in PostgreSQL, also prevents lost updates and phantoms. It does not detect read-write dependencies across rows, so two transactions that read disjoint sets and write each other's rows can both commit. Only serializable snapshot isolation tracks those dependencies and aborts one of the pair. Write skew is permitted at repeatable read by design, not a bug.

Can I test isolation without a real database?

Not credibly for concurrency behavior. Mocks cannot reproduce MVCC visibility, lock waits, or serialization aborts, and the point of the test is to exercise exactly those. Use a real instance, either local or ephemeral, and run the concurrency tests with two genuine sessions against it.

How do I test when production uses a connection pooler?

Run the tests through the same pooler mode as production, or at least know which features that mode supports. Transaction pooling does not preserve session state such as SET or session advisory locks between transactions, so a test that relies on those will pass or fail for reasons unrelated to your code. Set isolation at the transaction level and avoid session-level features on pooled connections.

What should happen when a retry budget is exhausted?

Return a clear, typed error to the caller and record the event with enough context to debug it: transaction name, attempt count, and the failing exception class. Retrying forever hides contention and can cascade under load, and an error with no attempt count makes the problem invisible in production metrics.

Sources

Sources

  1. Documentation: 18: 13.2. Transaction Isolation - PostgreSQL
  2. What write skew looks like
  3. Why write skew can happen in Repeatable reads?
  4. Repeatable Read vs Snapshot Isolation
  5. PgBouncer features
  6. PgBouncer Configuration and Best Practices - Heroku Dev Center
  7. Documentation: 18: 14.1. Using EXPLAIN - PostgreSQL
  8. Reading a Postgres EXPLAIN ANALYZE Query Plan - Thoughtbot
  9. Explaining Your Postgres Query Performance | Crunchy Data Blog
About the author

About the author

Antonio Evans
Antonio Evans

Antonio Evans is the founder of Quanta Intelligence and a fractional CTO who builds HIPAA-ready AI systems for health and life-science companies. Before that he was technical co-founder of FriendsEAT for twenty years, CEO of Socialdraft, and a data engineer at IBM. Antonio lives with his dog Santino in Lisbon, Portugal.

All articles
