
Marketing

Using an AI Agent to Tag and Route Newsletter Replies

Antonio Evans8 min read

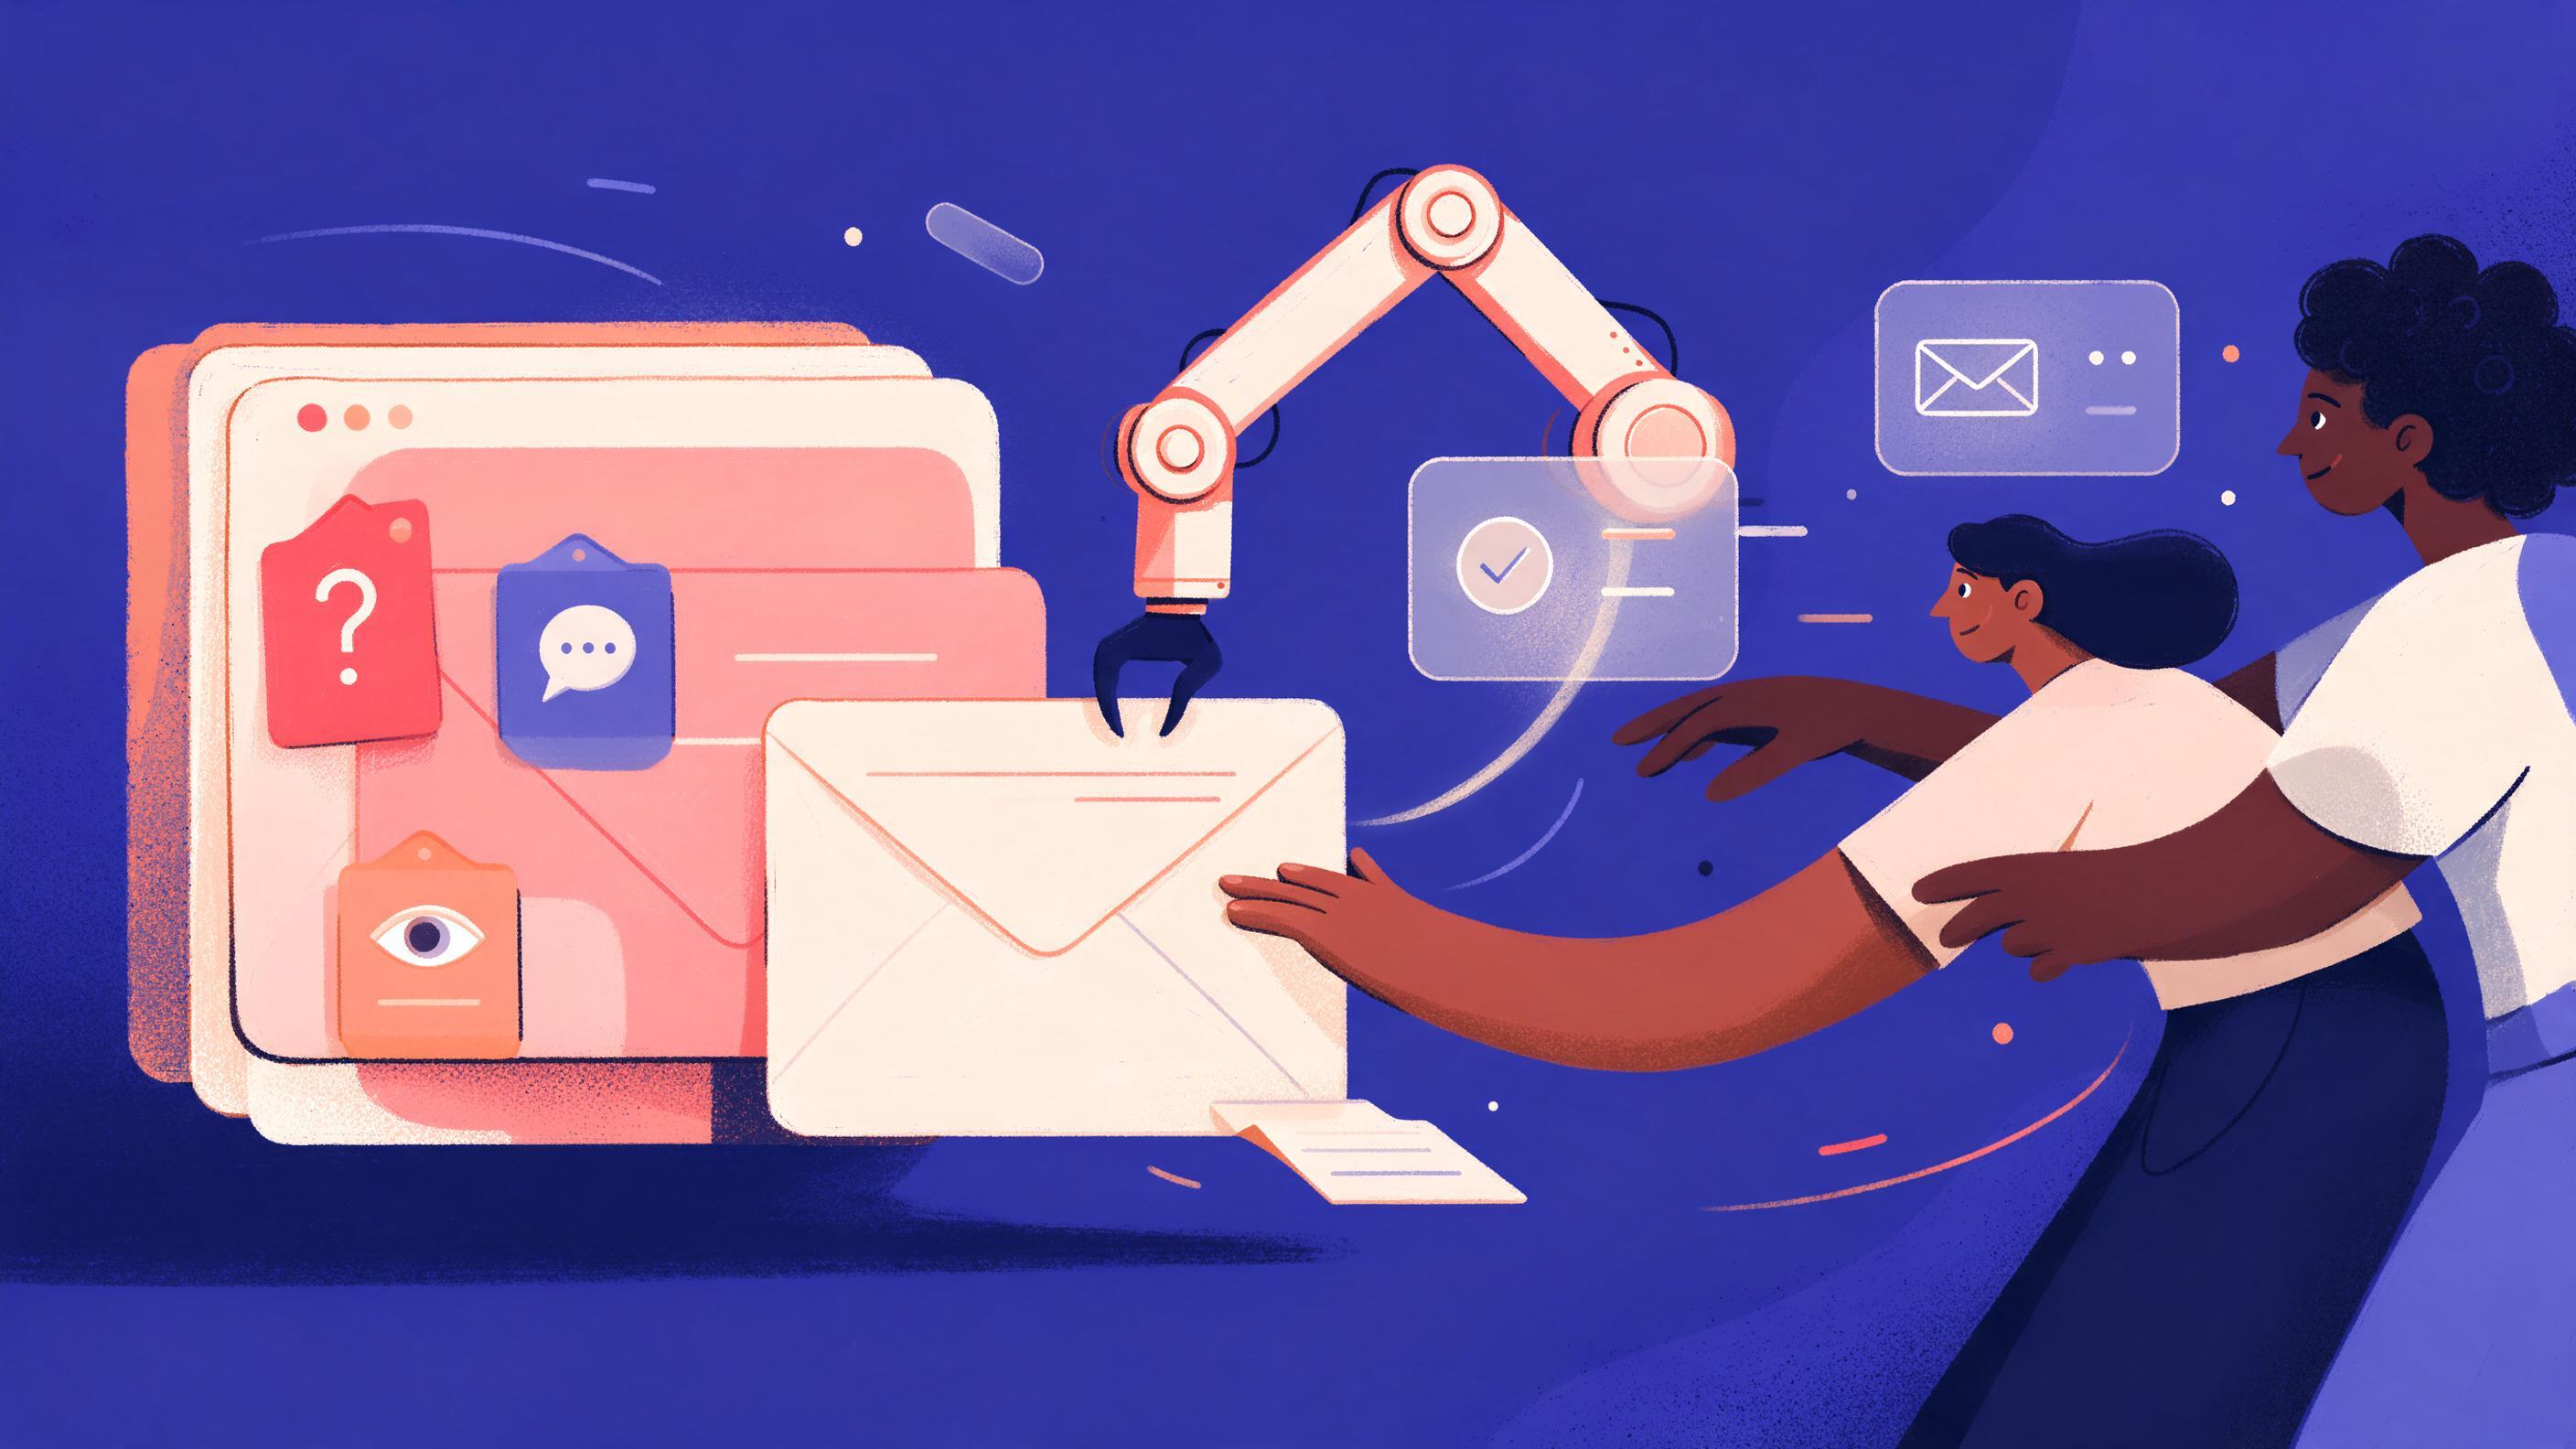
A split scene: on the left, a stack of incoming email cards labeled with colored tags (question, complaint, interested); in the center, a small robot arm picks a card and attaches a draft note; on the right.
Key points

Key points

  1. 1A fixed JSON schema plus a confidence score turns messy replies into rows a human can sort, filter and approve.
  2. 2A five-label intent taxonomy (interested, question, complaint, unsubscribe, out of office) covers most newsletter reply traffic and keeps the model from inventing categories.
  3. 3A confidence cutoff routes weak matches to a review queue, so the agent drafts where it is sure and defers where it is not.
  4. 4Nothing leaves the building without an approve click, and unsubscribe requests are honored within two days per mailbox provider rules.

Start with the reply channel, not the send button

Most newsletter operators spend their energy on deliverability and list growth. That emphasis is well documented: subject lines drive a large share of opens (47% of recipients say they open based on the subject line alone) and segmentation lifts opens and clicks according to The CMO Club's open rate guide. Bulk sender rules from Gmail and Yahoo now require authentication and one-click unsubscribe for high-volume senders per Gmail's sender guidelines and Yahoo's sender best practices.

But the reply channel is where money and churn actually show up. A reader who writes back "can you invoice my team for five seats?" is closer to a sale than any open. A reader who writes "stop emailing me" is a deliverability risk if you ignore it: Yahoo and Gmail both ask senders to keep spam complaint rates below 0.3% as summarized by AWS and PowerDMARC's roundup.

The problem is volume asymmetry. A 20,000-subscriber list at a 0.5% reply rate produces about 100 replies per issue. That is too many to read carefully every week and too few to hire for. An agent that labels, scores and drafts is the right shape of automation: it does the reading, and a human does the deciding.

One measurement note before you build. Open rates are no longer a reliable proxy for attention because Apple Mail Privacy Protection preloads tracking pixels, inflating opens even when nobody reads the message per Constant Contact, Omeda's six-month analysis and Mailchimp's MPP FAQ. Replies are the opposite: a human typed them. That makes the reply channel the cleanest engagement signal you own, which is a second reason to instrument it properly.


Define the intent taxonomy before you write a prompt

The taxonomy is the product decision. Get it wrong and no amount of prompt engineering saves you. Five labels cover the bulk of newsletter reply traffic:

LabelWhat it looks likeDefault routeNeeds a draft?
interested"How much for a team plan?" "Can we sponsor an issue?"Sales or founder inboxYes, with pricing facts
question"Where is the dataset from your last issue?"Author or supportYes, answer the extracted question
complaint"Too many emails." "This issue felt like an ad."Owner, same daySometimes, short and human
unsubscribe"Remove me." "Unsubscribe."Automation, no draftNo, process it
out_of_officeAuto-reply with datesArchiveNo

Two rules keep this taxonomy honest.

First, unsubscribe and out_of_office must be handled by deterministic code, not by the model's judgment. Mailbox providers require a working one-click unsubscribe and expect senders to honor requests within two days per Yahoo's sender requirements. Do not let a language model sit between a reader and the unsubscribe button. Parse the List-Unsubscribe header on the way out, and treat any reply classified as unsubscribe as a trigger that a human confirms, not a suggestion the model can bury.

Second, resist adding labels. Intent classification works best when the label set is small and predefined for a bounded domain; open-ended label sets drift as VeGait's overview of intent classification explains. If you find yourself wanting a sixth label, ask whether it is really a sub-type (complaint about content vs. complaint about frequency) or a routing destination. Routing belongs in a separate field.

The AWS Comprehend walkthrough of automated email response makes the same architectural point: match the message to a known intent, answer automatically when there is a match, and send unmatched messages to a human per the AWS Machine Learning blog. Your five labels are that "known intent" set.

The labeling prompt and a fixed JSON schema

Ask for one object per message with a fixed shape. Constrained output matters here because you are writing to a database, not reading prose. The schema below is the whole contract:

{
  "intent": "interested | question | complaint | unsubscribe | out_of_office",
  "confidence": 0.0,
  "extracted_question": "string or null",
  "key_quote": "verbatim span, max 200 chars",
  "suggested_draft": "string or null",
  "requires_human": true
}

The prompt should do four things: state the label definitions, give one example per label, instruct the model to copy a verbatim span into key_quote, and forbid it from guessing when the message is ambiguous. Keep definitions tight. "Interested means the sender asks about buying, sponsoring, licensing or partnering" is checkable. "Interested means positive sentiment" is not.

A caution on structured outputs. Forcing a schema can make a model more likely to fill every field confidently even when the input does not support it as discussed in this Hacker News thread on false confidence in structured outputs. Two mitigations work well. First, allow null explicitly for extracted_question and suggested_draft and say in the prompt that null is the correct answer when the message does not contain one. Second, score trust separately from the model's self-reported confidence: Cleanlab's benchmark of structured output error detection found that dedicated trust scoring caught bad fields with meaningfully better precision and recall than self-reported log probabilities, which matters when you are deciding what a human must read per Cleanlab's structured outputs benchmark.

If you are running several models to compare labeling quality, or want to swap providers without rewriting the pipeline, Quanta Inference exposes text and embedding models through one OpenAI-compatible API key, which keeps the labeling call and the embedding call behind the same client.

Set the confidence cutoff with numbers, not vibes

The cutoff is a business decision expressed as a threshold. Work it out from the cost of each mistake.

Suppose you get 120 replies per week. At a 0.70 cutoff you might route 55% to auto-draft and 45% to review. At 0.85 you might route 30% and review 70%. The auto-draft bucket is not free: a wrong interested label that reaches a founder as a "hot lead" wastes ten minutes; a wrong complaint label that never reaches anyone costs you a churn signal.

A practical starting policy:

  • 0.85 and above: auto-label, auto-draft, queue for a one-click approve.
  • 0.60 to 0.85: auto-label but no draft; human writes from scratch with the label as a hint.
  • Below 0.60: route to the review queue with no label attached, so a human is not anchored by a bad guess.

Then measure. Each week, sample 20 reviewed messages, record the human's final label, and compute agreement by bucket. If the 0.85+ bucket agrees with humans 95% of the time, you can lower the cutoff to 0.78 and pick up volume. If it agrees 80% of the time, raise it. Track accuracy per label separately, because models tend to be confident about unsubscribe and shaky about complaint.

Two operational rules protect the queue. First, never let the review queue grow past a day: replies are time-sensitive, and a two-day backlog is worse than no automation. Second, make the review UI show key_quote next to the label. Reviewers approve or correct in seconds when the evidence is visible, and the quotes double as your audit trail.

Draft with a tone guide and product facts

A draft is only useful if it is close enough to send. That requires two inputs the model does not have by default: voice and facts.

The tone guide is short and negative. "Write in the first person as the newsletter's author. Sentences under 20 words. No exclamation points. Never promise discounts or features that are not in the facts block. If the question is not answered by the facts block, write one sentence saying you will follow up and stop." The last rule is the important one, because it converts a hallucination risk into a deferral.

Product facts belong in a versioned file that sits next to the prompt, not inside it. Keep it to bullets a support person could defend: what the product does, what the team plan includes, where the pricing page lives. When pricing changes, you edit one file. This is the same discipline the deliverability world applies to authentication: one authoritative record, checked on every send, rather than ad hoc text as Gmail's guidelines describe for authentication and MXToolbox explains for DMARC.

A worked example. A reader writes: "We have a team of nine editors. Does the plan cover seats, and can you invoice us?" With facts stating that the team plan covers seats and that invoicing is available on request, the draft is two sentences: "Yes, the team plan covers seats for editors and we can invoice on request. Want me to send the details?" The extracted_question field is "Does the plan cover seats, and can you invoice us?" and confidence is high because both clauses map directly to facts. A reviewer approves in one click.

Contrast that with: "Loved the issue, made me think about how we handle this." The label may be interested at 0.61, which sends it to review with no draft. That is correct behavior. A generic compliment is a relationship signal, not a request, and a bad auto-draft would be worse than silence.

Approve, send, and close the loop

The approve step is where the agent stops being a toy. Three implementation details matter.

Identity and the draft folder. Write drafts into the mailbox as real drafts, not as rows in a database. Reviewers already know their mail client, and a draft in the folder keeps threading, signatures and reply headers intact. The agent never holds send credentials.

Idempotency. Every message gets a stable ID (the Message-ID header works) and the agent records what it did. If a job reruns, skip anything already labeled. This is the same principle as not sending the same email twice, and it prevents a loop from drafting five replies to one thread.

Suppression. A unsubscribe classification should create both a one-click unsubscribe event and an internal suppression record in the same transaction. Honor unsubscribes within two days, which is the stated expectation for bulk senders per Yahoo's requirements, and keep spam complaints low: below 0.3% is the threshold Gmail and Yahoo enforce per Gmail's guidelines and AWS's summary. A reply-based unsubscribe is a gift compared with a spam complaint, so process it fast.

Finally, feed decisions back. When a reviewer changes a label, log the original label, the new label, the model version and the quote. After a few hundred corrections you have a labeled set to regression-test any prompt or model change against. That set is worth more than any prompt tweak.

If you would rather not run the pipeline yourself, Quanta takes a described workflow (mailbox connection, labels, cutoff, draft folder) and builds it with you.

Measuring whether the agent earned its keep

Track four numbers weekly and put them next to each other:

MetricDefinitionHealthy direction
Auto-draft rateDrafts created / replies receivedRises slowly
Approve-without-edit rateApproved unchanged / approvedRises
Human label agreementCorrections / reviewedFalls
Median time to first human touchReply timestamp to reviewFalls

The first metric can rise while quality falls, which is why you watch the second. Approve-without-edit is the real quality signal: it tells you the tone guide and facts block are working. If it stalls below 60%, the problem is almost always the facts block, not the model.

One more measurement: count replies per issue and per intent over time. A rising interested count after a specific issue is a content signal you can act on. A rising complaint count about frequency is a warning that your list health is slipping, and complaint volume is the input to the 0.3% spam threshold every sender is judged on per Gmail's sender guidelines and PowerDMARC. Data you already collect can tell you what your readers want more of, and the growth tactics literature agrees that replies are a stronger signal than opens per Founderpath's newsletter metrics discussion.

FAQ

FAQ

How much does running this agent cost per issue?

It depends on reply volume and message length, but the shape is small: one classification call per reply, plus one drafting call for the subset that clears the cutoff. At roughly 100 replies per issue you are making a couple of hundred short calls per week, which is well within typical prepaid credit balances on metered APIs. The bigger cost is the human review minutes, which is exactly why the confidence cutoff exists.

Can I use a smaller, cheaper model for labeling?

Often yes, and it is a sensible first test. Labeling is a short classification task with a fixed schema, so a small model can do well when the label definitions and examples are clear. Run 200 historical replies through both a small and a large model, compare agreement with your human labels per intent, and pick the cheapest one that meets your threshold. Keep the drafting step on a stronger model.

What stops the agent from sending something wrong?

Architecture, not prompting. The agent writes drafts into a mailbox folder and holds no send permission; a human clicks send. The prompt forbids claims not in the facts block and tells the model to defer when unsure. And unsubscribe and out_of_office are handled by deterministic rules so they never depend on model judgment.

How do I handle replies in languages other than English?

Add a detected_language field and let the model label in the original language with English label names, then draft in the sender's language. Review quality per language weekly: non-English replies are the most common place a fixed taxonomy cracks, because complaint and interested can blend in translation.

What should I do with the labeled data after a few months?

Keep it. Export label, quote, model version and human correction into a flat table. It becomes your regression suite for prompt changes, your source for spotting taxonomy gaps, and a defensible record if anyone asks why a given reply was routed the way it was. The table is also the fastest way to onboard a new reviewer.

Sources

Sources

  1. 16 Strategies To Increase Email Open Rates in 2026 - The CMO Club
  2. Email sender guidelines - Gmail Help
  3. Sender Best Practices - Yahoo Sender Hub
  4. An Overview of Bulk Sender Changes at Yahoo/Gmail - AWS
  5. Bulk Email Sender Rules For Google, Yahoo, Microsoft & Apple (2026)
  6. How Apple's Mail Privacy Protection Impacts Email Marketing
  7. Apple Mail Privacy Protection Impact on Email Marketing
  8. Apple Mail Privacy Protection (MPP) FAQs
  9. Intent classification: understanding text with the power of AI
  10. Automate email responses using Amazon Comprehend ...
  11. Structured outputs create false confidence - Hacker News
  12. Real-Time Error Detection for LLM Structured Outputs - Cleanlab
  13. New Gmail & Yahoo Sender Requirements - What are they?
  14. Newsletter Growth Strategy: 30 Tactics to Reach 10K Subscribers
About the author

About the author

Antonio Evans
Antonio Evans

Antonio Evans is the founder of Quanta Intelligence and a fractional CTO who builds HIPAA-ready AI systems for health and life-science companies. Before that he was technical co-founder of FriendsEAT for twenty years, CEO of Socialdraft, and a data engineer at IBM. Antonio lives with his dog Santino in Lisbon, Portugal.

All articles
