Marketing

What Interviews into Case Studies Cost in Model Tokens

Antonio Evans8 min read

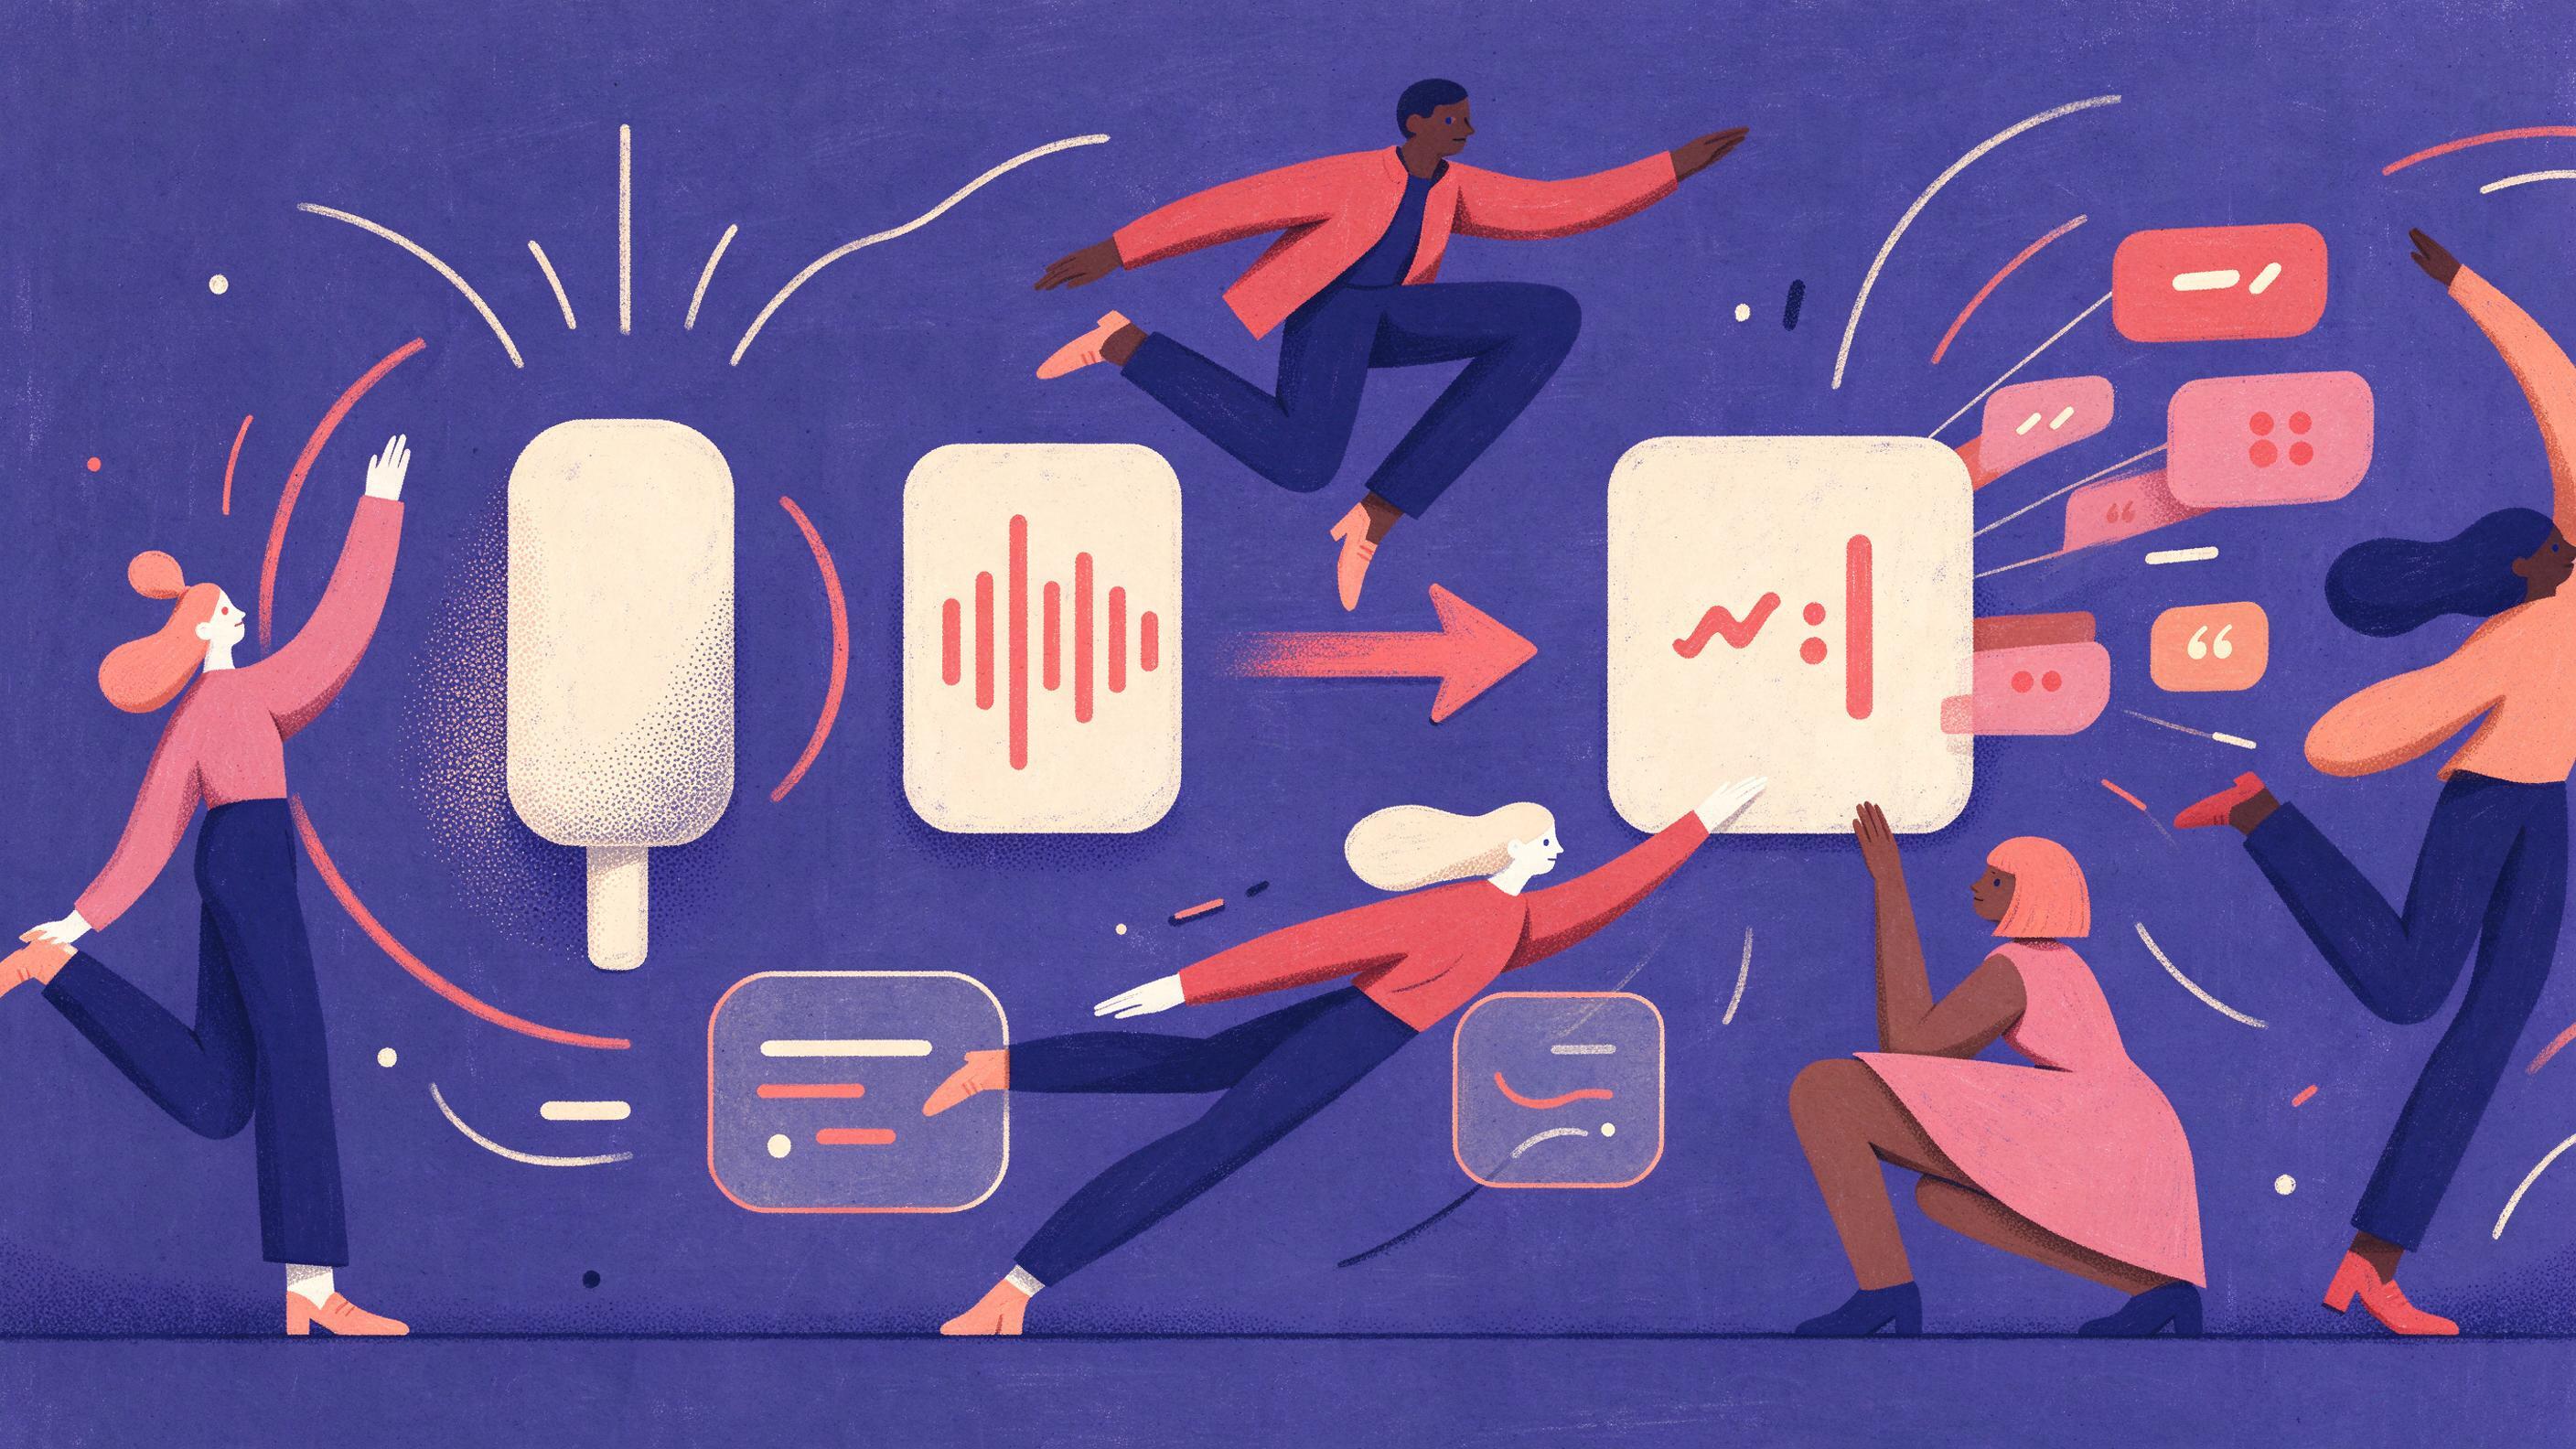
A left-to-right pipeline drawn on a white board: a microphone icon feeding a waveform box labeled transcriber, an arrow to a box labeled extractor with small tags floating out (names, themes, quotes).
Key points

Key points

  1. 1A one-hour recorded interview becomes roughly 8,000 to 10,000 tokens of transcript text at 130 to 160 words per minute and about 1.33 tokens per English word.
  2. 2Across the full pipeline (cleanup, extraction, quote selection, drafting and review) expect 15,000 to 40,000 tokens per interview, and more when you re-send the whole transcript at every stage.
  3. 3At list API rates the total lands between a few cents and roughly 20 cents per interview, and the drafting and review calls dominate the bill rather than the audio transcription.
  4. 4Route tagging and extraction to the cheapest capable model and reserve the large model for the draft and the final review, because a wrong tag costs a re-run while a wrong sentence is read by a named customer.

Building the token budget per interview

Start with the unit everything else multiplies: the transcript. Interview speech runs at roughly 130 to 160 words per minute, and tokenizers average about 1.33 tokens per English word, so a 60-minute recording is about 9,000 words and 12,000 tokens once speaker labels and timestamps are added. Budget 8,000 to 10,000 tokens for the raw text of a typical hour. Practitioners in the testimonial literature typically book 30 to 45 minutes and record on a video platform after asking permission per the t2d3 interview guide. A full question set covering background, the buying decision, implementation and outcomes makes for longer conversations and more tokens as the 20-question framework sets out.

Transcription is billed by audio duration on most speech-to-text endpoints, and the text it produces feeds every later call. That is the budgeting trap: the transcript is generated once and then re-sent, whole or in part, at each downstream stage. Your cost model is really a question of how many times that 10,000-token transcript goes into a prompt.

Transcription and cleanup

Two line items sit here. The speech-to-text call is priced per minute of audio, so a one-hour interview is a single charge you can read straight off the provider's page. Cleanup is a text call: roughly 10,000 input tokens of raw transcript plus a short instruction, with about 9,000 tokens back for punctuation, speaker attribution and removal of filler words.

Cleanup is the cheapest place to save money and a poor place to use a frontier model. Punctuation restoration is a pattern task with a correct answer, so a small model handles it. The decision rule: if the task has one objectively correct output and a wrong output is caught by a person skimming the text, use the smallest model that passes your spot check.

Ask whether you need the pass at all. A strong drafting model tolerates messy punctuation, so you can skip cleanup and save one full-transcript round trip per interview. Keep it when a human editor reads the raw transcript, which is common when the customer must approve quotes before publication as the testimonial workflow recommends.

Extraction: entities, themes and outcome numbers

This stage earns the case study its credibility and multiplies the token count. The evidence base is consistent that the story needs specifics: the problem, the solution and the measured outcome, with striking statistics placed inside the narrative rather than drowning it per Elliott Pearce's B2B case study best practices. Case studies built on named numbers and personal quotes persuade more than vague praise according to Weber Associates.

Split extraction into two or three focused calls rather than one giant prompt. Focused prompts produce cleaner structured output, and each call is easier to re-run alone:

  1. Entity and context call. Send the transcript and ask for company, industry, team size, tools replaced, timeline and named stakeholders as JSON.
  2. Outcome call. Ask for every quantitative claim with the exact quote and timestamp, plus a flag for claims that need verification before publication.
  3. Theme and objection call. Ask for the problem, the alternatives considered, what nearly stopped the purchase and the decisive proof. These map to the buying-decision questions that yield the most useful testimonials per the 100tasks question set.

Each call re-sends the full transcript. Three calls at 10,000 input tokens each is 30,000 input tokens before the draft exists. That is the biggest structural cost in a naive pipeline, and the fix is prompt caching: cached input is billed at a fraction of base input on current Anthropic rates, and the batch API takes half off both input and output per the Metacto pricing breakdown. The equivalent cuts exist on OpenAI tiers, where batch prices run at half of standard and input above a long-context threshold moves to a higher schedule per Silicon Data.

Run all three extraction calls on the small model. A wrong tag here yields a bad draft you catch in review, and a re-run costs one call, not a correction in front of a customer. Structured output modes make small models reliable at JSON extraction, which is exactly the shape these calls need.

Quote selection and the compliance pass

Quote selection is cheap in tokens and expensive in risk. The call sends the transcript plus the extraction JSON and asks for 8 to 12 candidate quotes, each tagged with the theme it supports, the timestamp and a flag for anything that reads as a superlative claim. Output is small, perhaps 600 to 1,000 tokens.

The compliance pass is a narrower call over that shortlist: check for claims needing substantiation, comparative statements about competitors, and anything the customer might regret in print. It is not optional if you follow advertising rules. In the United States, the FTC's endorsements and testimonials guidance is the place to check what a published customer statement must be able to support per the 100tasks guide. A small or mid-tier model handles this provided the prompt states the rule set explicitly.

Keep the customer's voice. The interview guides consistently warn against leading the customer or polishing away credibility, because a testimonial works when it is recognizable as the customer's own words per the t2d3 guide. Instruct the model to make light edits only, and log any quote you rewrite so the approval email shows the final text.

Draft generation

The draft is the first call with substantial output, and it is where quality shows. A 1,200-word case study is roughly 1,600 output tokens. The input is the transcript (or a condensed evidence pack), the extraction JSON, the chosen quotes and your house style instructions, typically 12,000 to 15,000 input tokens.

Budget generously on output. Models that reason before answering bill that reasoning as output, so a draft call can cost several times its visible word count. Output tokens still dominate many production bills, and context length is a pricing event rather than just a longer prompt per Silicon Data. OpenAI publishes the per-million rates for its current tiers including cached input and output on its API pricing page.

Structure the prompt around problem, solution and outcome, the format the case study literature recommends for keeping the narrative tight per Elliott Pearce, and keep the customer as the hero while the vendor stays the guide as the Content Marketing Institute advises. Instructions are nearly free in tokens; what you pay for in the draft call is judgment, which is why this is the stage for the large model.

Generate two drafts at different temperatures and let a human pick. The second draft costs about what the first did and saves an editorial round trip, which is worth more than the tokens.

Review passes and total cost per interview

Review is the quiet budget killer because it is iterative. A typical flow is a fact-check pass (does every number in the draft match the transcript, with a quote and timestamp), a style pass (house voice, reading level, banned phrases) and a final approval-ready pass after the customer's comments arrive. Three review calls at 3,000 to 5,000 input tokens each, with 300 to 600 output tokens, is normal.

The fact-check pass belongs on the large model. It reads the whole draft against the whole evidence pack and is the last line of defense before a named customer sees a wrong number attached to their name. The style pass can run on a mid-tier model. The post-comment pass goes back to the large model, because that is the version that ships.

Here is a worked estimate for one 60-minute interview at standard list rates, using a cheap tier at roughly $0.10 per million input and $0.50 per million output against a large tier at roughly $2 per million input and $10 per million output, the shape of the current Claude ladder as compiled from Anthropic's pricing docs per the Metacto breakdown.

StageModel tierInput tokensOutput tokensCost (USD)
CleanupSmall10,0009,000~$0.005
Extraction (3 calls)Small30,0002,000~$0.004
Quote selection and complianceSmall12,0001,500~$0.002
Draft (2 versions)Large26,0004,000~$0.092
Fact-check and style reviewLarge plus mid14,0001,500~$0.043
Post-comment final passLarge5,000800~$0.018
Total~97,000~19,000~$0.164

Two numbers deserve attention. First, the total sits near the top of the "a few cents to 20 cents" band because the transcript is re-sent six or seven times; a leaner pipeline that condenses the transcript into a 3,000-token evidence pack after extraction halves the draft and review inputs and lands nearer 8 to 10 cents. Second, audio transcription is billed per minute and often costs more than every text call except the draft, which is why the headline attributes the bill to drafting and review rather than to audio.

Repeat that over 200 interviews a year and inference comes to $16 to $33 at list rates, before caching or batch discounts. The labor around it, scheduling, approval emails and editorial judgment, is two orders of magnitude larger. Inference is not the constraint on a case study program; the interview calendar is.

If you are running these calls across several model families to get the tier mix right, putting them behind a single endpoint with one key and one prepaid balance removes most of the plumbing: Quanta Inference serves text, image, video, audio and embedding models through an OpenAI-compatible API priced in US dollars.

The decision rule

The routing rule is not about cost per token; it is about the cost of being wrong.

  • Small model: any task with one correct answer, or where a wrong answer is caught by a cheap check. Cleanup, entity extraction, theme tagging, quote shortlisting, style linting. A bad tag costs one re-run at a fraction of a cent.
  • Mid-tier model: tasks that need judgment over short text with clear criteria. Style rewrites, headline options, meta descriptions, social variants.
  • Large model: tasks whose output a customer or a buyer reads word for word. The draft, the fact-check pass, and the final version after customer comments. Here a wrong sentence is seen by a named customer and possibly by their legal team.

A second rule governs volume: any call that re-sends the full transcript should be cached, and any call whose output nobody reads within the hour should run in batch at half price. Read the discounts off each provider's own page before committing a budget: OpenAI publishes standard, batch and long-context rates per million tokens on its API pricing documentation, and Anthropic's ladder, caching multipliers and batch discount are summarized in the Metacto breakdown here.

Reading the draft against a published buyer's guide is also worth the tokens. Buyers weigh relevance, credibility and context, and journalistically written stories with clear metrics and independent quotes outperform product-dense advertorials per Prime Creative. Put those three criteria in the review prompt as an explicit checklist.

If you would rather not build and tune this pipeline yourself, describe the workflow you need (transcript in, structured evidence out, draft and review passes) and a specialist will build it with you at Quanta.

FAQ

FAQ

How many tokens is a one-hour interview transcript?

Roughly 8,000 to 10,000 tokens. Speech runs at about 130 to 160 words per minute, so an hour is 8,000 to 9,600 words, and English tokenizers average about 1.33 tokens per word. Add speaker labels and timestamps and you land near the top of that range.

Why is drafting more expensive than transcription?

Transcription is billed per minute of audio and happens once. Drafting sends the transcript and the extracted evidence to a large model and asks for 1,200 or more words of output, and large-model rates run roughly 20 times the small-model rate per input token. Two draft versions plus review passes outweigh the single audio charge.

Can I use the cheapest model for everything?

You can, and for internal drafts it often works. The failure mode is the customer-facing sentence: smaller models are likelier to blur a number or overstate a result, and that error is read by a named customer. Keep the draft and the fact-check on the large model and save the cheap tier for extraction and tagging.

What is prompt caching worth here?

It is the biggest single lever after model routing. The transcript is re-sent at every stage, and cached input is billed at a fraction of base input on current pricing, with the batch API taking another half off per the Metacto breakdown. Stacking the two cuts the total well below the uncached estimate.

Do I need customer approval before publishing AI-drafted quotes?

Yes, as a matter of practice and often of compliance. The interview guides recommend telling the customer the material may be used publicly only after they approve the final text per the t2d3 workflow, and the FTC's endorsements guidance sets what a published claim must be able to support as the 100tasks guide notes. Build the approval round into the pipeline as a required step, not an optional one.

Sources

Sources

  1. How to Create Client Testimonials with Examples and Templates
  2. 20 Customer Testimonial Questions That Produce Useful Proof (2026)
  3. How to create compelling B2B case studies - Elliott Pearce
  4. Building Trust with Case Studies - Weber Associates
  5. Claude API Pricing 2026: Opus 4.8, Sonnet 4.6, Haiku 4.5 ...
  6. OpenAI API Pricing per 1M Tokens (2026)
  7. Pricing | OpenAI API
  8. 3 Tips To Create Case Studies That Turn Prospects Into Buyers ...
  9. Case studies: the centre of your 2026 marketing strategy
About the author

About the author

Antonio Evans
Antonio Evans

Antonio Evans is the founder of Quanta Intelligence and a fractional CTO who builds HIPAA-ready AI systems for health and life-science companies. Before that he was technical co-founder of FriendsEAT for twenty years, CEO of Socialdraft, and a data engineer at IBM. Antonio lives with his dog Santino in Lisbon, Portugal.

All articles