Security

What the Agent Says When No Human Answers

Antonio Evans8 min read

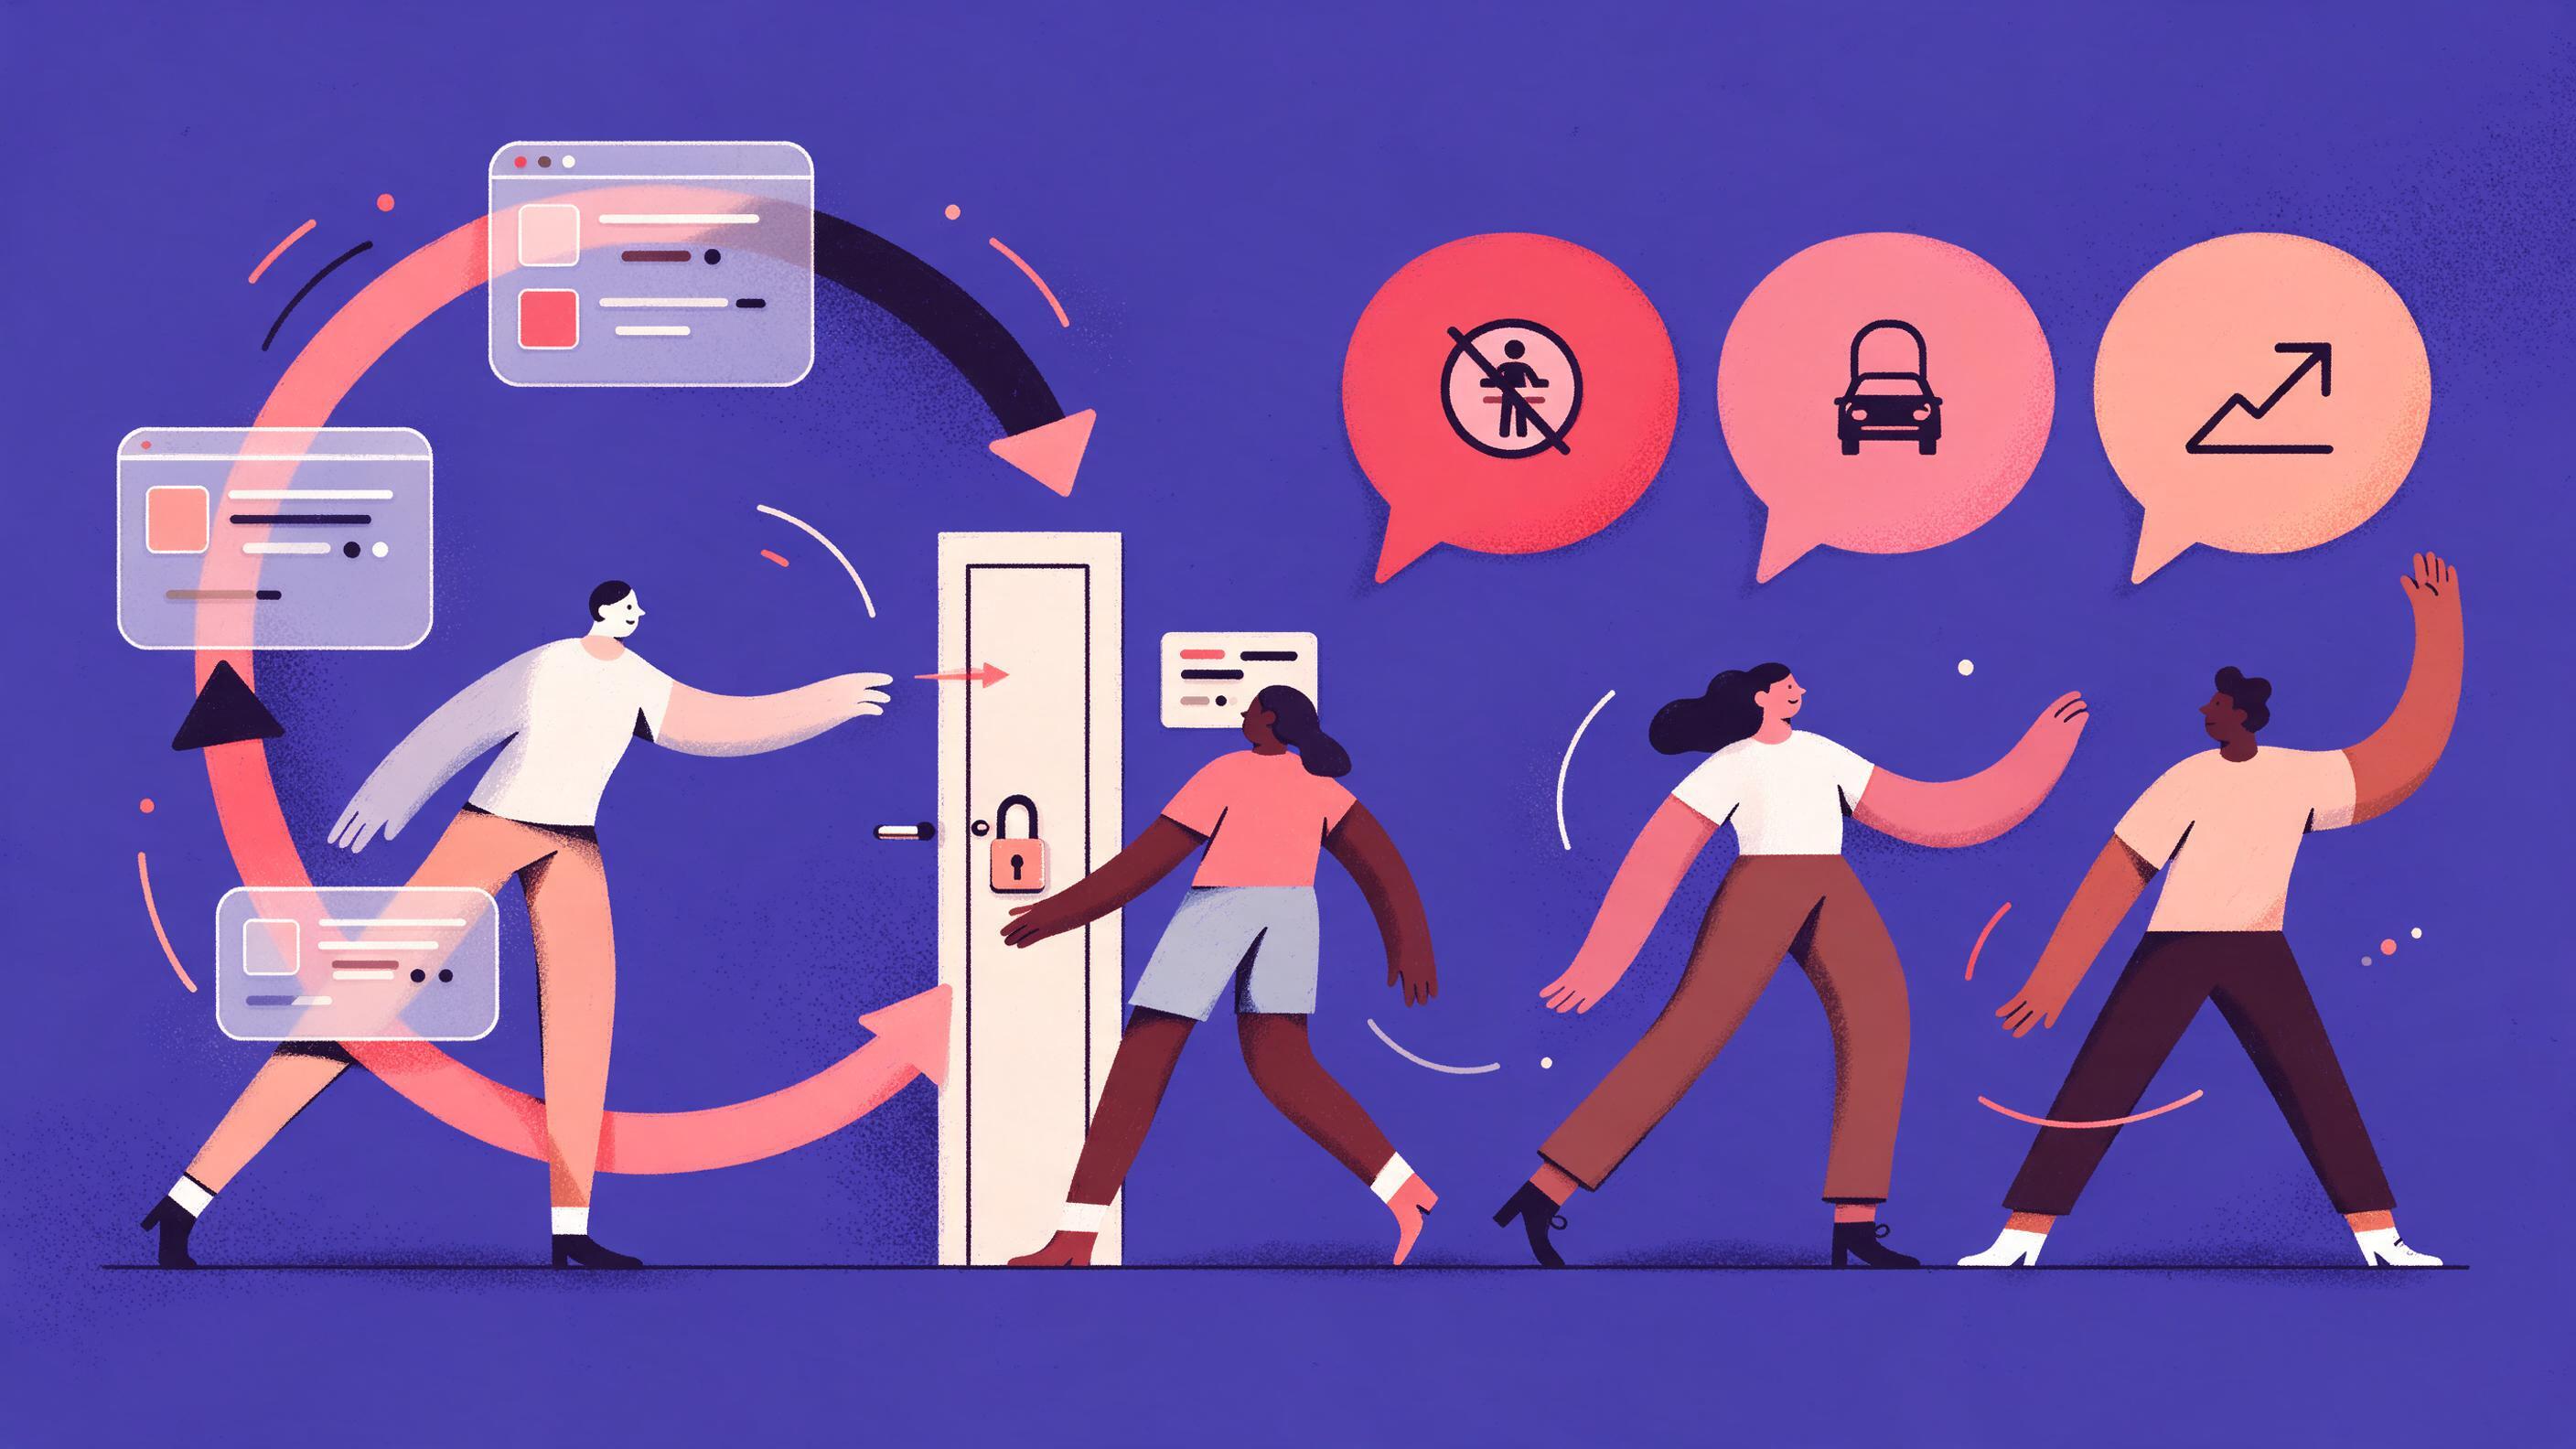
A split scene: on the left, a simplified agent loop diagram with a tool call hitting a locked door labeled with a reason code; on the right, three speech bubbles labeled DENIED, PARKED and ESCALATED.
Key points

Key points

  1. 1When a fallback fires, the agent returns a typed outcome record instead of natural language, so the model reasons over facts rather than guesses.
  2. 2Three outcome values cover most cases: denied (will not run), parked (valid but waiting on evidence or a human), and escalated (a person owns it now).
  3. 3Every outcome carries the same six fields: outcome, reason code, attempted action with arguments, deciding policy or system, next allowed steps, and owner.
  4. 4Wording matters: a deferral that reads as a rejection trains the model to apologize, stop trying, or rephrase the same blocked action instead of choosing an allowed alternative.

Why the return payload decides whether the loop recovers

Most agent failures described in the wild are not model failures. They are loop failures: the model proposes an action, a guardrail blocks it, and the string handed back to the model is either empty, a stack trace, or a vague sentence like "not permitted." The model then does the only thing it can with an unexplained block: it tries a near-identical action, apologizes to the user, or fabricates a result.

The reliability literature is blunt about this. A 60% single-trial success rate does not translate into 60% of production traffic succeeding, and rate limits are the single most common error class in deployed LLM applications, with a measured drop from 96.9% baseline success to 88.1% under rate-limit stress (fallback design as an architecture problem). That source also flags the dangerous failure: a tool call that times out causes agents to improvise and fill the gap with fabricated data. A well-typed outcome record removes the improvisation surface.

The architectural rule that follows is simple. The model proposes; a policy decision point decides. That separation is how policy-as-code for agents is described in practice: the model should never be the authority that decides whether a tool call is allowed, and model output should be treated as a request for authorization, not as authorization (policy-as-code for enterprise AI agents). Once you accept that, the question becomes what the decision layer hands back.

Silent fallbacks are the worst version of this. One documented incident involved a system where every response came back fast, with no errors in logs and no alerts, because a caught exception fired a template on every single call; the only visible signal was zero tokens used per response (silent LLM fallbacks). An outcome record that names its deciding policy and reason code makes that class of bug impossible to hide, because the record appears in the trace on every request where the fallback fired.


The three outcome templates

Three values are enough for the vast majority of enterprise tool surfaces. The test for which one applies is not "did the user ask for something bad" but "what is true about the requested action right now."

OutcomeMeaning to the modelAction runs?Who owns the caseTypical reason codes
deniedThis action will not run under any configurationNo, neverNobody; the model must choose an alternativepolicy_blocked, field_not_allowed, amount_over_limit, tool_not_granted
parkedThe request is valid but cannot proceed yetNot nowThe model, pending new evidence, or a queuemissing_evidence, awaiting_approval, rate_limited, context_stale
escalatedA human now owns the requestNo, not by this loopA named person or teamrisk_tier_high, requires_review, customer_requested_human

The distinction between denied and parked is the one teams get wrong most often. Denied is a statement about the policy: the action is outside what this agent, for this user, on this resource, may ever do. Parked is a statement about completeness: the action is inside policy but the request lacks something the policy requires, such as an approval ticket reference, a verified identity, or a fresh retrieval.

Escalated is not a synonym for parked with a human attached. It changes control. The agent loop should not keep retrying, and the model should be told explicitly that further attempts are not its job. Approval and escalation design in workflow systems already follows this pattern: auto-escalation activates when a service level or time threshold is exceeded and reroutes to a secondary or managerial role rather than waiting indefinitely (auto-escalation for stalled approvals).

The record every outcome carries

A template is only as good as its fields. Keep them identical across all three outcomes so the model sees one shape and your logs stay queryable. Six fields do the work.

outcome: one of denied, parked, escalated. Never free text.

reason_code: a stable, enumerable string from a fixed list. This is what you alert on, what you count per week, and what you attach runbooks to. If your reason codes drift into prose, you lose the ability to say "the top fallback reason last month was missing_evidence on refund tools."

attempted_action: the tool name plus the full argument object as submitted. The model needs to see its own request echoed back, including the exact field values, because most near-miss retries come from a single wrong argument. Echoing arguments also means the trace shows what was blocked, not just that something was.

deciding_policy: the identifier of the rule, policy version, or upstream system that produced the decision. Something like refund_policy_v7#amount_ceiling or identity_check#unverified_caller. Note the parallel with input validation guidance: validate the representation that will actually be used, and do not re-decode downstream, because inconsistent decoding invalidates earlier checks (OWASP Input Validation Cheat Sheet). The same applies to the deciding policy: the identifier the enforcement point emits is the one the model and the auditor should both see.

next_allowed_steps: a specific, finite list. Not "try something else." Write things like ["issue_refund with amount <= 50.00", "create_callback_request", "hand_off_to_human"]. A model given a menu picks from the menu; a model given a prohibition improvises.

owner: null for denied, a queue or ticket reference for parked, a named individual or team plus a ticket for escalated. Zendesk's guidance on agent escalation is a useful sanity check here: gather order number, name, and email, tag and update fields, and identify suitable agents before handing off, so the human does not start from zero (configuring escalation strategies and flows for AI agents).

Here is the shape in JSON. denied carries no owner and a mandatory alternative list.

{
  "outcome": "denied",
  "reason_code": "amount_over_limit",
  "attempted_action": {
    "tool": "issue_refund",
    "arguments": { "order_id": "A-10442", "amount": 780.00, "currency": "USD" }
  },
  "deciding_policy": "refund_policy_v7#amount_ceiling",
  "next_allowed_steps": [
    "issue_refund with amount <= 50.00",
    "create_callback_request",
    "escalate to billing_queue"
  ],
  "owner": null
}

And parked, which keeps the model in the loop:

{
  "outcome": "parked",
  "reason_code": "awaiting_approval",
  "attempted_action": {
    "tool": "update_contract_terms",
    "arguments": { "contract_id": "C-8871", "clause": "term", "months": 24 }
  },
  "deciding_policy": "contract_change_policy#manager_approval",
  "next_allowed_steps": [
    "read contract C-8871 and summarize the current term",
    "create_approval_request and reference ticket AP-3312",
    "escalate to legal_queue"
  ],
  "owner": "approvals_queue"
}

Wording that keeps a deferral from reading as a rejection

The model does not read your intent. It reads your tokens. Two wordings of the same decision produce opposite behavior.

Weak: "You are not allowed to issue this refund." The model hears a prohibition on the category and either apologizes or rephrases the same refund with a different argument.

Strong: "Refund of 780.00 USD on order A-10442 was denied by refund_policy_v7 amount_ceiling. You may issue a refund up to 50.00 USD, create a callback request, or escalate to billing_queue."

Four wording rules carry most of the value.

  1. Put the outcome in the first sentence as a plain noun, not as a verdict on the user. "Denied by policy" and "parked pending approval" are facts. "Rejected," "invalid," and "not permitted" are judgments the model will translate into apology.
  2. Follow immediately with the alternative list, in the same breath. Alternatives placed after a paragraph of explanation get truncated or ignored; alternatives placed directly after the outcome are the next thing the model conditions on.
  3. Never use "no" without a "but." Parked outcomes should lead with what is already true: the request passed identity and scope checks and needs one specific piece of evidence. That framing is a direct application of why validation exists at all, to reduce the risk of invalid operations rather than to punish the caller (OWASP Input Validation Cheat Sheet).
  4. For escalated, say who owns it and tell the model to stop. Something like: "This request is now owned by billing_queue under ticket AP-3312. Do not retry this action. You may tell the user the reference and stop." An agent that keeps proposing the escalated action after a human took it converts a clean handoff into a duplicate-work generator, which is exactly the failure mode escalation timers exist to prevent (approval timeout handling).

A decision rule for choosing between parked and escalated, if you want one line: if the only thing missing is something the model can obtain in this turn (a document read, a user confirmation, an ID verification step), park it. If the missing thing requires a person's judgment, a signature, or a queue, escalate it.

Wiring the templates into the agent loop

The loop has one insertion point and one rule. The insertion point is immediately after tool dispatch and before the result returns to the model. The rule is that the model never sees a raw exception.

def dispatch(tool_name, args, ctx):
    decision = policy.evaluate(
        actor=ctx.user, agent=ctx.agent_id, tool=tool_name,
        args=args, resource=ctx.resource, state=ctx.workflow_state,
    )
    if decision.allow:
        return {"outcome": "allowed", "result": run_tool(tool_name, args)}
    return {
        "outcome": decision.outcome,          # denied | parked | escalated
        "reason_code": decision.reason,       # stable enum
        "attempted_action": {"tool": tool_name, "arguments": args},
        "deciding_policy": decision.policy_id,
        "next_allowed_steps": decision.alternatives,
        "owner": decision.owner,
    }

Three engineering details make this work in production.

Fail closed, and fail into parked, not into allowed. A useful policy system must fail closed, produce explainable decisions for reviewers, and emit evidence that survives incident response (policy-as-code for enterprise AI agents). If the policy engine times out, the safe default is a parked outcome with reason policy_unavailable, not a pass-through.

Cap the retries per reason code. Give the model two attempts to reach an allowed state after a parked outcome. If the third dispatch comes back with the same reason code, the orchestrator promotes the record to escalated with owner set to a queue. This keeps the model from looping on a missing evidence item it cannot produce.

Count outcomes separately from errors. Fallback usage must be a distinct counter with alerting on the rate, not lumped into generic error logs, and zero-token responses are a cheap correctness signal (silent LLM fallbacks). Do the same for outcome records: dashboard denied by reason code, parked by age, and escalated by owner queue. A spike in one reason code is a policy or a prompt that needs a change; a spike in parked age is a queue that needs staff.

Tool output schema design matters here too. Structured tool outputs that follow an explicit schema are far easier for a model to consume than free text, and error handling belongs in that schema as a first-class variant rather than an afterthought (error handling for LLM agent tools).

Testing the templates before they meet a user

You cannot validate this by reading prompts. You test it by asserting on the record.

Start with an allowlist and denylist matrix per tool, because a block list can only name components someone has already reviewed, while the agent layer arrives through self-service config changes that get forked and repointed in seconds (allowlist and denylist policies for AI agents). Encode each cell as a test case with an expected outcome and reason code.

Test caseInputExpected outcomeExpected reason code
Refund under limit$40 refund, verified userallowednone
Refund over limit$780 refund, verified userdeniedamount_over_limit
Missing approval ticketContract edit, no ticketparkedawaiting_approval
Policy engine downAny privileged toolparkedpolicy_unavailable
High-risk actionDelete production recordescalatedrisk_tier_high
Repeated parked retrySame parked reason twiceescalatedretry_exhausted

Then add the regression you actually care about: after a denied record, does the model pick from next_allowed_steps or rephrase the blocked action? Run it ten times per case. Reliability, not capability, is what breaks in production, and consistency across repeated trials on identical inputs is the number benchmarks rarely report (fallback design as an architecture problem).

The same discipline applies to the model layer underneath. A single-provider architecture has no path when the API degrades, which is why provider fallback and human escalation appear together in reliability designs (why AI agents need fallback models). If you are running several model providers behind one interface, Quanta Inference exposes text, image, video, audio and embedding models through one OpenAI-compatible key, which keeps the outcome record identical no matter which model produced the proposal.

FAQ

FAQ

Should the agent ever tell the user the request was rejected?

No. The agent tells the user what happened in factual terms: the action was denied by a named policy, parked pending a named piece of evidence, or escalated to a named queue with a reference. "Rejected" implies a judgment on the person, and models reproduce that framing in the next message they write. State the decision, the reason, and the alternative.

How many reason codes is too many?

If an operator cannot list every code from memory on one screen, you have too many. Group by decision type: policy, missing evidence, identity, capacity, risk, and system. Sub-reasons can live in the deciding_policy identifier, which is more specific anyway. Alerting on thirty sibling codes produces thirty noisy alerts; alerting on six classes produces six actionable ones.

What stops the model from retrying the same blocked action forever?

Two mechanisms. The next_allowed_steps list gives the model a menu instead of a prohibition, which removes most retries at the source. A retry budget per reason code removes the rest: after two attempts that return the same parked reason, the orchestrator promotes the record to escalated with an owner, and the model is told to stop.

Where does the outcome record live in the trace?

Attach it to the span for the tool call, alongside the model's proposal, so a reviewer sees the proposed arguments, the decision, and the deciding policy in one place. Correlation identifiers passed through every hop let you reconstruct the chain of actions after an incident, and that lineage is what log-based incident response depends on (policy-as-code for AI agents).

Does this replace human-in-the-loop approvals?

No. It standardizes what the model receives when an approval gate or a policy check answers. The gate itself still comes from your workflow or policy engine, and the escalation timer that moves stalled requests along belongs there too. The templates simply make sure the agent loop reacts to a gate the way the gate's designers intended, rather than guessing.

Sources

Sources

  1. AI Fallback Design Is an Architecture Problem, Not ...
  2. Policy-as-Code for Enterprise AI Agents - Thomas THELLIEZ
  3. When Your AI Agent Lies: Silent LLM Fallbacks
  4. How to Configure Auto-Escalation for Stalled Approvals
  5. Input Validation - OWASP Cheat Sheet Series
  6. Configuring escalation strategies and flows for AI agents
  7. Streamlining Approval Timeout Escalation Procedures
  8. Error Handling for LLM Agent Tools
  9. How to Build Allowlist and Denylist Policies for AI Agents ...
  10. 32. Why AI Agents Need Fallback Models | Designing Reliable ...
  11. https://petronellatech.com/blog/policy-as-code-for-enterprise-ai-agents-identity-least-privilege
About the author

About the author

Antonio Evans
Antonio Evans

Antonio Evans is the founder of Quanta Intelligence and a fractional CTO who builds HIPAA-ready AI systems for health and life-science companies. Before that he was technical co-founder of FriendsEAT for twenty years, CEO of Socialdraft, and a data engineer at IBM. Antonio lives with his dog Santino in Lisbon, Portugal.

All articles