
Founders

When to Replace a Scorecard with an Agent That Screens Resumes

Antonio Evans10 min read

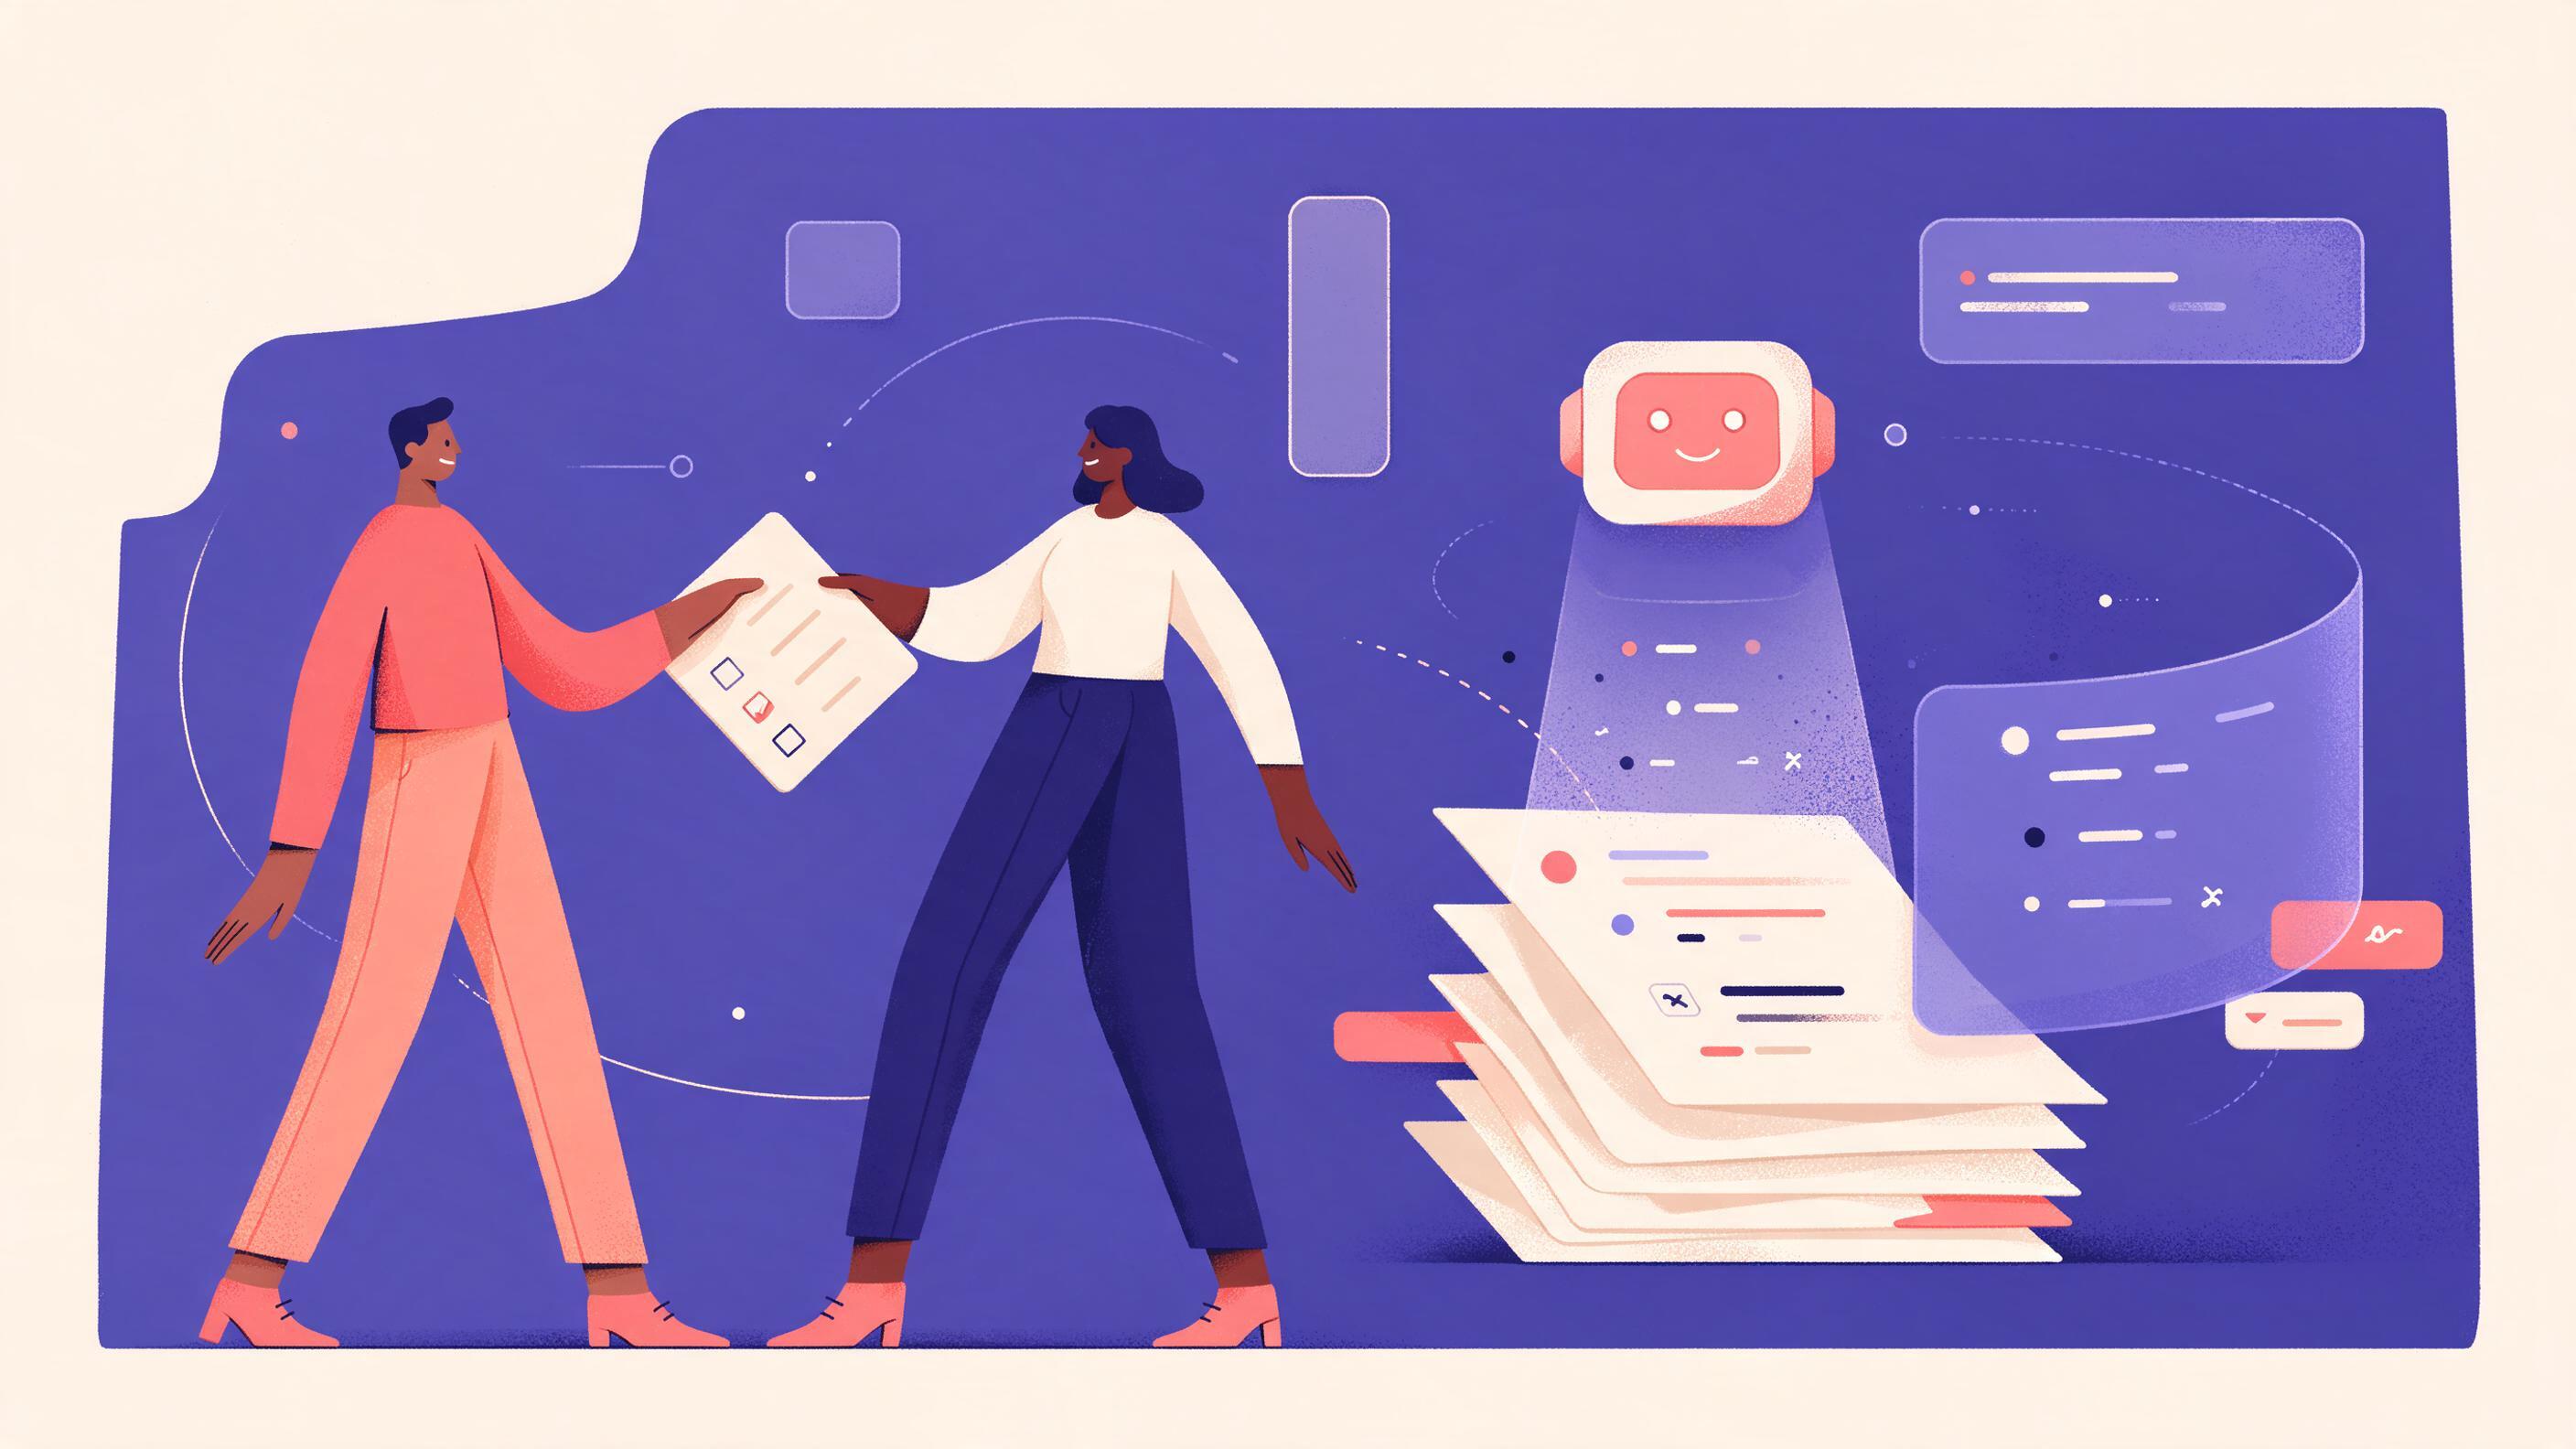
A split scene: on the left, a person hands a paper scorecard with checkboxes to a colleague; on the right, a software agent icon scans a stack of resumes and outputs a shortlist.
Key points

Key points

  1. 1Replace a manual scorecard with an agent only when most of the hiring decision rests on criteria a machine can check consistently, such as required skills, years of experience, or keyword matches from the job description.
  2. 2Keep the scorecard for judgment calls the agent cannot make: culture add, motivation, and growth potential, which structured interview research shows are better judged by people using anchored rubrics.
  3. 3You need enough historical applications to measure the agent's agreement with the human scores before you trust it on live candidates.
  4. 4A human reviewer stays in the loop through sampling, audit trails, and a written record of why each candidate was advanced or rejected.

Start from the scorecard you already have

A role scorecard is not a job description. It is the checklist the hiring decision gets made against: the purpose of the role, the results the person owns, the responsibilities, the required skills, and the behaviors the company expects. Stephen Lynch describes exactly that six-part structure and notes it becomes the basis for both the hiring decision and later performance appraisals. Rhythm Systems makes a similar point: a scorecard exists so the person and the manager are fully aligned on what success means.

The reason this matters for an AI decision is that a scorecard is the only thing that makes an agent auditable. An agent that screens resumes has to score against something, and if that something is a written rubric with numbered, anchored criteria, you can compare its output to a human's output line by line. If criteria live only in a hiring manager's head, you have nothing to measure the agent against.

A usable scorecard for this purpose has roughly four to eight criteria, per the Slite hiring scorecard template, and each criterion gets a one-line description of what a strong candidate shows. A four-point scale works for most roles, and every number on that scale gets its own description so that a 3 means the same thing to two different reviewers. If your current scorecard does not meet that bar, fix it before you consider an agent. Otherwise the agent inherits the ambiguity and multiplies it across every applicant.

There is also a measurable payoff to structure. Pin's summary of scorecard research cites Sackett and colleagues (2022), who found structured interviews predicted job performance at a validity of .42 versus .19 for unstructured interviews. Earlier work by Huffcutt and Arthur found the same pattern by degree of structure, reaching .57 at the most structured end. The same source cites a CareerBuilder survey in which 74% of employers said they had hired the wrong person for a role, at an average cost of $14,900 per bad hire. Those numbers are not specific to screening agents, but they explain why teams push toward structure in the first place.

What an agent can actually judge

Be specific about the division of labor. An agent reads unstructured documents (resumes, cover letters, portfolio pages, application answers) and maps them onto your scorecard. That is a parsing and matching task, and it is what language models are good at. The judgments that hold up are narrow:

Scorecard criterion typeAgent can evaluate consistentlyWhy
Required tool or technology listedYesKeyword and synonym matching against a list you define
Years in a named role or domainYes, with a ruleDate arithmetic on parsed employment history
Required license or certificationYes, if the claim is verifiableMatch against a stated credential
Work authorization or locationYes, as a flag for humansStructured field, but never auto-reject
Structured application answersYes, with a rubricCompare answer to anchored description
Culture add and team fitNoRequires context about the current team
Motivation and reason for applyingNoSelf-reported, hard to verify from text
Growth potential and slopeNoDepends on trajectory judged by a person
Communication under pressureNoBehavior in conversation, not on paper

The pattern is that an agent handles the criteria where the evidence is a string in a document and your rule is unambiguous. It is unreliable where the evidence is absent from the document or where the criterion depends on the person's future behavior.

One common mistake is assuming the agent can infer absence. It can flag that a resume never mentions a required certification, but it cannot tell whether that means the candidate lacks it, chose to omit it, or earned it under a different name. Treat every "missing" finding as a question to send to the candidate, not a rejection.

The second mistake is over-trusting a fit score. A single 0 to 100 number collapses all your criteria into one dimension and hides which criterion drove the result. Demand per-criterion output with a quoted line of source text for each score. That is the difference between an explainable screen and an oracle you cannot question.

What an agent cannot judge, and why that matters legally

Turnitin, which builds text-classification tools, publishes a model for how to read automated outputs: its detection model "may not always be accurate," and the report "should not be used as the sole basis for adverse actions," requiring further scrutiny and human judgment. It surfaces low-confidence ranges as unreliable rather than displaying a percentage. That is a tool vendor telling you the shape of a responsible deployment, and the same discipline applies to a resume-screening agent.

The judgments that most affect a hiring decision are also the least observable from a document. A founder's account of early hires emphasizes resilience under chaos, a bias toward action, adaptability, emotional intelligence and mission obsession, and specifically warns that a perfect resume can mask a lack of resilience (Intro's summary of founder advice). None of those five qualities is reliably scoreable from a resume. They show up in how someone talks about a difficult colleague, which is why one panelist recommends asking about that and then letting the candidate talk (RBCx's hiring panel notes). An agent reading a resume cannot run that conversation.

Early-stage hiring also pushes against narrow rules. Founder Institute's hiring guide notes that early startups usually choose generalists over narrow specialists because they can do several things, and that founders should define the gap they need filled rather than searching for a job title. Generalists often fail keyword screens precisely because their titles and skill lists are broad, which is an argument for using the agent as a first pass and routing borderline generalists to a human, never as a hard filter.

There is a legal shape to this too. The scorecard-plus-agent setup is only defensible if you can produce the record. The EEOC's recordkeeping rules, cited in the same Pin scorecard guide, call for retaining scorecards for one year, and two years for larger federal contractors, and documented evidence behind each rating is what makes a decision defensible. An agent that logs a per-criterion score and the quoted evidence is easy to defend. An agent that returns a hidden embedding and a yes or no is not.

The build versus buy decision, worked through

This is where the article earns its keep. The temptation to build is real: a working prototype that scores resumes against a job description can be assembled in a weekend, and API calls look cheap. Metaview's write-up on build versus buy for recruiting agents makes the honest case that the first version is easy and the third Monday in production is where it breaks: the ATS integration breaks when the vendor changes an API, the prompt that worked on engineering resumes hallucinates on sales candidates, and when a recruiter asks why a candidate was screened out, nobody can answer.

The lifecycle argument is not unique to recruiting. A review of the make-or-buy decision under agentic AI points out that initial development is a minority of total ownership cost, with operations, maintenance and enhancement commonly estimated at 60 to 80% of lifecycle costs. AI lowers the development share but does not remove the operational majority, and it can add governance work when generated codebases need quality assurance. That is the honest frame for a screening agent: the prompt is cheap, the ownership is not.

Use the following scoring approach to force a decision. Score each factor from 1 (clearly favors buying) to 5 (clearly favors building), then read the total.

Decision factorScore of 1 or 2 meansScore of 4 or 5 means
Does screening logic differentiate your productNo, it is overheadThe rubric itself is proprietary and defensible
Integrations neededATS, calendar, email, all standardHighly custom internal systems
Candidate volume per yearLow hundreds or fewerThousands, so tooling effort amortizes
Access to labeled historical decisionsNone, so nothing to calibrate againstSeveral hiring cycles recorded against the same rubric
Security and PII review capacityNo dedicated reviewerFull-time security and legal support
Compliance regimeStandard EEOC retention and recordkeepingFederally regulated with mandated audit trails

A useful rule of thumb: if you cannot score at least a 4 on historical data and on security capacity, buy or stay manual. Composio's build-versus-buy framework makes the same point in a different domain: build when the work is core IP and you have dedicated resources for its full lifecycle, buy when you need speed and want to hand off maintenance and authentication complexity. Screening resumes is rarely core IP for anyone outside a recruiting business.

Here is the generic pattern most teams end up writing against, whether they build or buy. It is illustrative, not vendor code:

criteria = [
    {"id": "python", "type": "keyword", "required": True},
    {"id": "years_backend", "type": "date_range", "min": 3},
    {"id": "cert_aws", "type": "credential", "required": False},
]

for applicant in applicants:
    result = screen(applicant.text, criteria)  # per-criterion + evidence quote
    if result.requires_human:                  # any "missing" or low confidence
        queue_for_review(applicant, result)
    else:
        score_to_rubric(applicant, result)     # does not auto-reject

The key line is score_to_rubric rather than reject. The agent produces a scored record that a human reviews; it never writes a rejection on its own.

Designing the human in the loop

This is the part most teams underbuild. A screening agent without a review process is just a faster way to make decisions you cannot defend. Three mechanisms do the work.

Sampling. Have a human re-score a fixed share of the agent's decisions: every candidate the agent rejects, plus a random sample of every candidate it advances. Compare the human's score to the agent's on each criterion and record the disagreement. If the disagreement rate on a given criterion climbs, that criterion is not ready for automation, and it goes back to manual.

Tiered routing. Route by what the agent found rather than a single score. Candidates with every required criterion evidenced and no unresolved gaps go forward for an interview on the usual schedule. Candidates with a gap on a required criterion get a clarifying question in the screening email, and their file stays open until the answer comes back. Candidates with contradictory evidence go to a recruiter. That preserves the agent's speed while keeping missing information out of the reject pile.

Audit trail. For each candidate, store the rubric version, the criteria applied, the per-criterion score, the quoted line of resume text behind each score, the agent's confidence, the routing decision, and the name of the human who reviewed it. Keep it for the retention period your recordkeeping rules require. This record does three jobs: it lets you answer a candidate's question, it lets you audit for differential outcomes across groups, and it lets you retrain the rubric when a criterion turns out to be noisy.

One more rule worth writing down: never let the agent's score appear next to a candidate's name when an interviewer opens the file. Anchoring is real, and an interviewer who sees a 3 out of 4 will find reasons to agree with it. Keep the agent's output in the screening record and give interviewers a blank scorecard.

Measuring whether the agent agrees with your humans

Replace the scorecard only after you have run the agent alongside it, not instead of it. Two numbers tell you whether you are ready.

The first is per-criterion agreement with human reviewers. For each criterion, take the share of candidates where the agent's score matches the human's within one point on your scale. Criteria with high agreement can be automated. Criteria with low agreement stay manual, and often the disagreement is a signal that the criterion itself is poorly written.

The second is the rate at which the agent's output would have changed the decision. Pull your last several hiring cycles, run every applicant through the agent, and count how many the agent would have advanced that humans rejected, and how many it would have rejected that humans advanced. A small number of disagreements that a human resolves is healthy. A large number means the rubric and the agent are modeling different things.

Work through a small example. Suppose you have 600 historical applications for a backend role and your humans interviewed 60 of them. Run the agent and it flags 70 for interview, 55 of which overlap with the human set. That is roughly nine in ten of the human interviews recovered, plus 15 candidates the humans passed on. Read those 15 by hand. If the humans had a reason, such as a resume that misrepresented experience, encode that rule in the rubric. If they did not, you have just found a case for the agent. Repeat until the extra candidates are explainable, then switch.

This calibration work is the reason the short answer says "enough historical applications." A role with a dozen past applications gives you no calibration set, so the agent runs unmeasured, and an unmeasured screen is worse than a manual one because it is faster and therefore harder to notice when it is wrong.

If you need the screening service built around your own scorecard rather than shoehorned into a vendor's format, that is a build-and-handover job that Quanta can scope with you: describe the rubric, the ATS, and the audit requirements you need and a specialist picks it up. The model access layer is a separate, smaller decision.

FAQ

FAQ

Do I need a scorecard before I can use an AI screening agent?

Yes. The scorecard is what the agent scores against and what you compare its output to. A role description full of vague adjectives gives the agent nothing checkable, and it removes your ability to measure agreement with human reviewers. Write the criteria, the anchors for each score, and the evidence notes first, then evaluate tools.

How many past applications do I need before trusting an agent's screening?

Enough that each criterion has been exercised against real candidates, and enough that you can compare the agent's decisions to recorded human decisions. A few dozen per role is a floor for a rough read; bigger sets make the disagreement rate meaningful. If you have no labeled history for a role, run the agent in shadow mode on live applicants until you do.

Can the agent reject candidates on its own?

It should not. Have it produce a per-criterion score with a quoted line of evidence and route uncertain or gapped candidates to a human, who makes the decision. Automated rejections are the hardest thing to defend, and published guidance on automated classification, such as Turnitin's, explicitly warns against using the output as the sole basis for adverse action.

What should the audit trail contain for each candidate?

The rubric version, the criteria applied, the per-criterion score, the quoted source text behind each score, the confidence, the routing decision, and the reviewing human's name. Retain it for the period your recordkeeping obligations require, which the EEOC sets at one year in the general case and two years for larger federal contractors. This record is what lets you answer a candidate's question and audit for differential outcomes.

Which criteria should stay with a human?

Culture add, motivation, growth potential, and how someone communicates under pressure. Research on early hires puts resilience, bias toward action, adaptability and emotional intelligence among the qualities that matter most, and none of them is reliably readable from a resume. Those criteria belong on the interview scorecard, judged by a person against written anchors.

Sources

Sources

  1. How to Create Role Scorecards | Stephen Lynch
  2. Job Scorecard Examples and Template (Updated for 2026)
  3. Hiring Scorecard Template
  4. 5 Best Free Interview Scorecard Templates for 2026 - Pin
  5. Using the AI Writing Report
  6. Key Qualities of Your First 50 Startup Hires - Intro.co
  7. 7 Tips for Hiring Your Startup's First Employees - RBCx
  8. Build or buy? Why building internal AI recruiting tools may ...
  9. The Buy-or-Build Decision, Revisited: How Agentic AI ...
  10. Build vs. buy AI agent integrations: a 2026 decision ...
About the author

About the author

Antonio Evans
Antonio Evans

Antonio Evans is the founder of Quanta Intelligence and a fractional CTO who builds HIPAA-ready AI systems for health and life-science companies. Before that he was technical co-founder of FriendsEAT for twenty years, CEO of Socialdraft, and a data engineer at IBM. Antonio lives with his dog Santino in Lisbon, Portugal.

All articles
