Marketing

Drafting Referral Messages from Your Own Case Studies

Antonio Evans8 min read

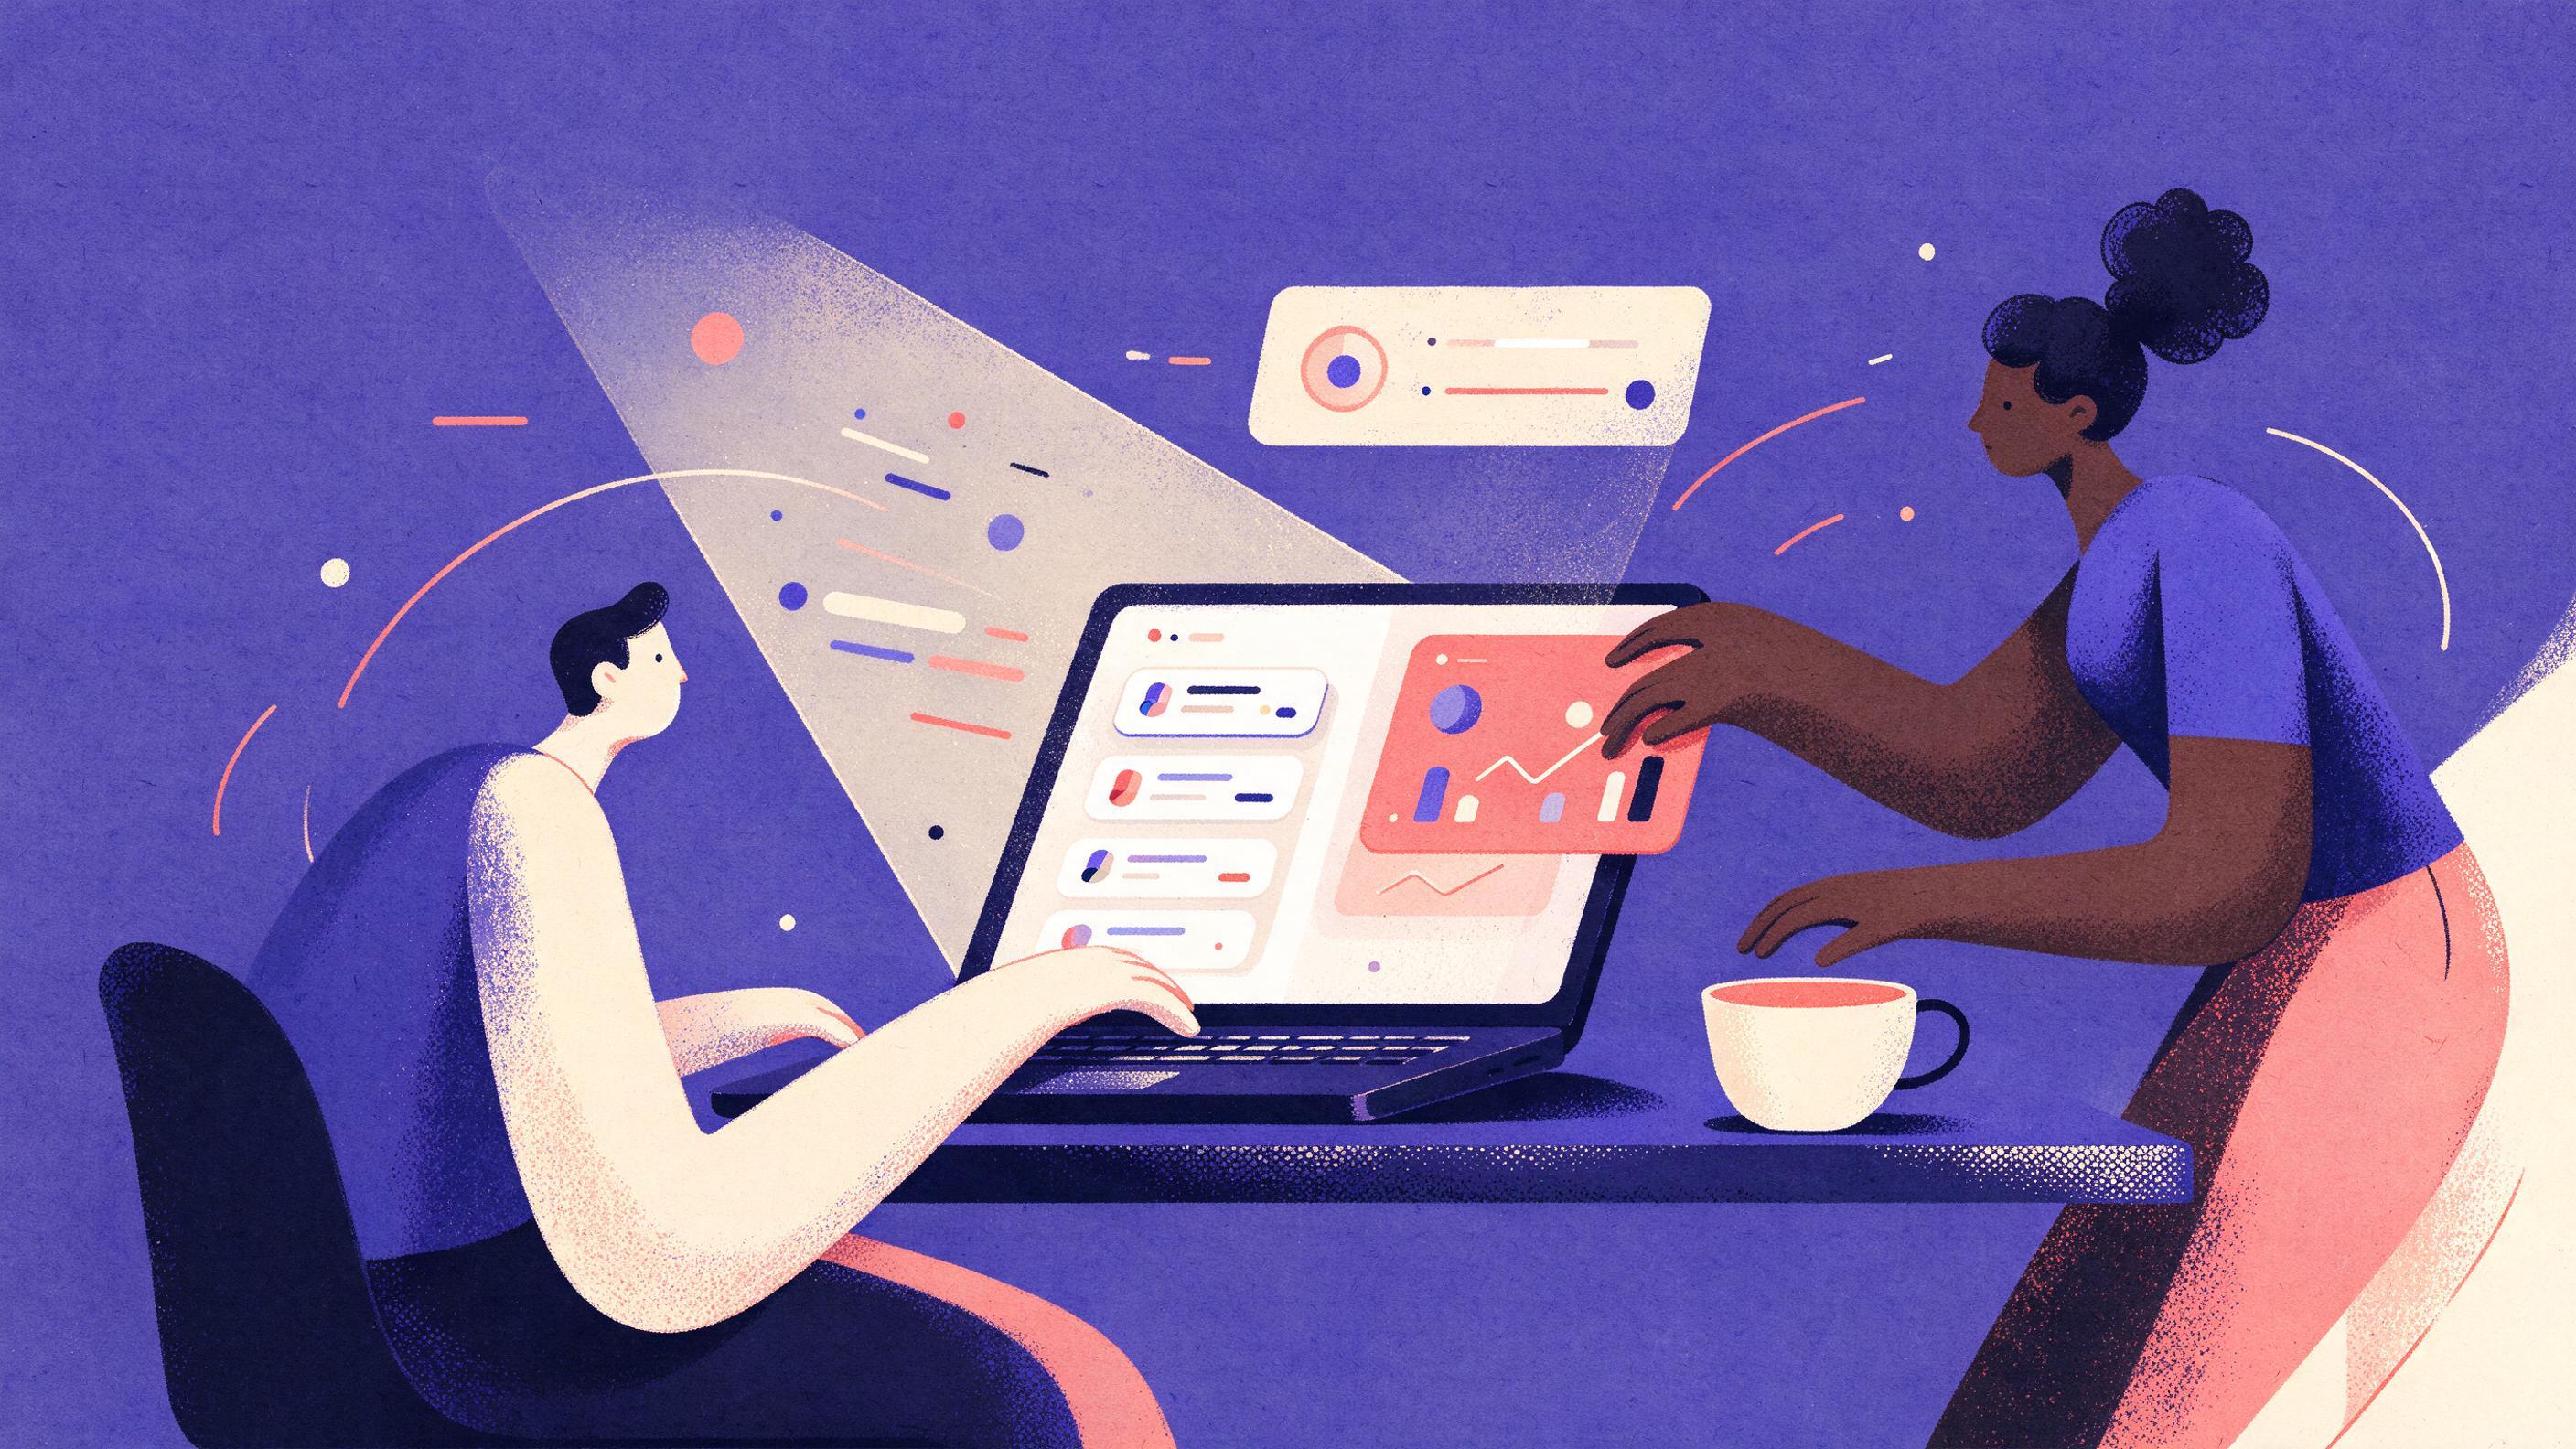
A desk with a laptop showing a split screen: on the left, a list of case studies with tags like 'SaaS, mid-market, churn reduction'; on the right.
Key points

Key points

  1. 1A small retrieval layer over tagged case studies lets you pick the one study that matches a contact, instead of rewriting the same generic ask.
  2. 2Studies should be tagged by customer segment, industry, and a measurable outcome, because the value of referred customers varies by segment.
  3. 3The model drafts two to three sentences that cite the retrieved study, not a long pitch, because short specific asks are easier to say yes to.
  4. 4Nothing sends until a named person approves it; the reviewer queue is the control that keeps a wrong claim from reaching a customer.

Start with the economics, because they decide how much time this deserves

Referral programs are only worth automating if referred customers are actually worth more. The strongest evidence comes from a study of roughly 10,000 customers at a leading German bank tracked for almost three years: referred customers had a higher contribution margin (the gap shrank over time) and a higher retention rate (that gap persisted), and the average referred customer was at least 16% more valuable than a nonreferred customer with similar demographics and acquisition timing (Schmitt, Skiera and Van den Bulte).

Two things follow from that finding. First, the paper's own conclusion is that firms should use a "selective approach" for referral programs, because the value differential varies by customer segment. That is the argument for matching a specific case study to a specific contact rather than blasting the same template to everyone. Second, a 16% average lift is an average: if you cannot say which segment produced it, you cannot aim at it.

The web is full of bigger numbers, and they should be treated loosely. One retention article cites a widely repeated claim that retaining a customer costs up to five times less than acquiring one, and that a 5% retention increase lifts profit by 25% to 95% (StriveCloud). A referral platform blog repeats the five times figure and cites a 222% rise in acquisition costs "by one estimate" (Mention Me). Use these to justify attention, not to build a forecast. For the forecast, use your own contribution margin per segment.

A simple decision rule: automate referral drafting where (a) referred customers in that segment show a clear margin or retention advantage in your data, and (b) you have at least a handful of case studies to retrieve from. If either is missing, the retrieval layer is decoration.
Tag case studies so retrieval has something to match

Retrieval-augmented generation works by retrieving relevant documents from a knowledge base and passing them to the model so the answer is grounded in your own data rather than the model's training data (Evidently AI). That grounding is the whole point: it reduces hallucination, supports citations back to a source, and lets the output be tailored to the individual (K2view).

For referral drafting, the "document" is your case study, and the metadata is what makes matching possible. Tag every study on four axes:

FieldExample valuesWhy it matters
Customer segmentmid-market retailer, regional bank, independent clinicThe contact should recognize themselves
Industrygrocery, logistics, dentalOff-industry proof reads as irrelevant
Outcome typecost reduction, faster onboarding, higher repeat rateYou cite the number the buyer already cares about
Outcome figure and its source"cut order errors by a set percentage, internal audit"Reviewers need to verify the claim

Keep the outcome figure attached to its source document. A reviewer who cannot trace a number in five seconds will either approve it blind or reject the whole draft, and both outcomes waste the workflow.

You also want a "do not use" flag on old studies with expired results or clients who have asked not to be named. Retrieval systems are literal: if a study sits in the index, it can surface. The practical fix is a boolean field that the retriever filters on before any similarity score is computed.

Embed and retrieve the right study for a given contact

The mechanics are ordinary RAG. Ingest the studies, chunk them, embed the chunks, store the vectors with their metadata, and at query time embed the contact profile and pull the nearest matches. The standard workflow is ingest, retrieve on prompt, then generate using the prompt plus retrieved context (ReadyTensor).

Store owner, ask amount, and reward type on the study itself, not just in a separate campaign spreadsheet, so the draft and the offer cannot drift apart.

Two implementation details matter more than the embedding model choice.

First, filter before you rank. If the contact is a regional bank, exclude every non-banking study from the candidate set, then rank the remainder. Ranking first and filtering after produces near-misses ("a healthcare client similar to yours") that a reviewer has to rewrite anyway.

Second, build the query from the contact record, not from a free-text search box. A query assembled from industry, company size, and the last known business goal is more consistent, and consistency is what lets you measure whether the drafts are improving.

A worked example. A contact is a mid-market grocery chain that mentioned rising fulfillment costs. The query filters to retail and grocery studies, ranks by embedding similarity to "fulfillment cost reduction," and returns the top study: a grocery client that reduced error rates in order picking. The draft will cite that one study and nothing else.

If the top match scores below your threshold, the honest output is no draft: route the contact to a human who knows the account. A weak match is worse than no match, because it teaches the reviewer to distrust the queue.

Prompt for a short ask that cites the study

The prompt has four jobs: define who is asking, supply the retrieved study verbatim, state the structural constraints, and forbid invention. Prompting guidance from legal practice generalizes well here: give the model the source material inside the prompt, specify the format, and instruct it to work only from what you supply (Clio). Structured prompt frameworks such as RACE (role, action, context, expectation) do the same job for content work (Champlain College).

The structural advice comes from referral asks in the wild. Career-advice writers converge on the same shape: remind the person who you are with one specific detail, name the exact thing you want, make a clear limited ask, and give an easy out (Applyre). The same source notes that a long message starting with an apology and ending with "let me know if there is anything you can do" puts the reader in an impossible position. Business-development advice adds the supporting facts: make it easy for them by including the details and a one-sentence reason you are relevant (Indeed).

Here is a prompt skeleton that encodes all of it.

Role: You write short referral asks for an account manager.

Contact:
- Name: {{contact.name}}
- Company: {{contact.company}} ({{contact.industry}}, {{contact.size}})
- Last conversation: {{contact.notes}}
- Known goal: {{contact.goal}}

Retrieved case study (use only this):
{{study.text}}

Rules:
- 2 to 3 sentences. No greeting, no sign-off.
- Cite exactly one fact from the case study.
- Name the introduction you want (a specific person type or team).
- Offer the double-sided reward in one clause.
- Add a single sentence that makes declining easy.
- Do not invent metrics, client names or outcomes.

Output JSON: {"draft": "...", "study_id": "...", "cited_fact": "..."}

Asking for the cited fact back as a separate field is the cheapest quality control you will add. The reviewer sees the claim and can check it against the study without re-reading the draft twice. If the model returns a cited fact you cannot find in the study text, the draft is auto-rejected.

One design choice worth making explicitly: whether to mention the reward. Double-sided programs, where both the referrer and the new customer get something, are the default recommendation for any business where a purchase happens, because the sharer becomes the person who got their friend a deal rather than someone collecting a payout (Referral Rock). Most referral programs run through one platform are double-sided (Referral Factory). But the reward described must match what the program actually pays (Yotpo), so pull reward text from the program configuration, never from the model.

Route every draft through a reviewer before it is sent

The reviewer queue is the product. Put four checks on a single screen next to the draft:

CheckPass conditionIf it fails
Citation traceableCited fact appears word for word in the studyReject, log the study ID
Study relevantReviewer would have picked it themselvesReject, flag as a retrieval miss
Reward accurateWording matches current program termsFix reward text, keep draft
Ask is specificThe requested introduction is a named role or teamSend back for revision

Two of those checks generate data you should keep. Retrieval misses are the raw material for better tags; citation failures are the raw material for a tighter prompt. Without logging them, you are guessing at what to fix.

Reviewer load is the limit you will hit first. If you draft for a large contact list, you will create more review work than a small team can absorb. Cap the daily draft volume at what reviewers can clear in a fixed window, and rank candidates so the highest-value contacts are drafted first. Referral value is not uniform across segments (Schmitt et al.), so the queue order should reflect that.

There is a second reason to keep a person in the loop. Asking badly, or asking the wrong person at the wrong moment, damages a relationship that took months to build. The people who write about referral asks for a living are blunt about it: if you are not ready to articulate in two sentences why you are a genuine fit, you are not ready to ask anyone to vouch for you (Applyre). A reviewer is the one who decides that threshold has been met.

Measure whether the drafts are better than what you wrote by hand

Track four numbers, and give each a baseline from before the workflow existed:

  1. Reviewer approval rate without edits. This tells you whether retrieval and prompting are aligned.
  2. Referral conversion rate per segment. This tells you whether the targeting rule is right.
  3. Time from contact selected to message sent. This is the labor saving, and it is usually the easiest to prove.
  4. Share of sent drafts that cite a study. If this falls, people are bypassing the queue.

The value case should be rebuilt per segment rather than borrowed from a headline figure. If a referred customer in one segment is worth meaningfully more than one in another, the referral effort, and the reviewer time, should follow the margin. The bank study's authors say exactly that: use a selective approach, because the differential varies across segments (Schmitt et al.).

Watch the failure mode that hides in plain sight: drafts that are technically accurate but read like everyone else's. If approval stays high but conversion does not move, the problem is not the retrieval, it is that the ask is too similar across contacts. That is a prompt and selection problem, not a model problem. Vary the opening detail (the last conversation) and the requested introduction, not the structure.

Where Quanta fits if you would rather not build the plumbing

Everything above is buildable with an embedding model, a vector store, and a chat model, which is three integrations to maintain and three keys to rotate. Quanta Inference puts text, image, video, audio and embedding models behind one API key, OpenAI-compatible and prepaid, which is the pragmatic choice when the embedding call and the drafting call live in the same pipeline: https://quantaintelligence.ai/inference.

If you would rather hand the whole workflow to someone who has shipped it, describe the system you need and a specialist builds it with you: https://quantaintelligence.ai/

FAQ

FAQ

Do I need a vector database to do this?

No. If you have fewer than a few hundred case studies, a small in-memory index or even keyword filtering on tags followed by a model call will work. The retrieval quality comes mostly from the tags and the filter before ranking, not from the vector store. Move to a dedicated store when document count or daily queries make latency a problem.

How many case studies do I need before retrieval is worth it?

Roughly one per segment and industry combination you actively sell into, with at least one clear outcome figure each. Below that, the retrieval step mostly returns near-misses and reviewers do more work than they save. If you have fewer, start with manual selection and build the tagging discipline first.

Should the model mention the reward amount?

Only if the reward text comes from the program configuration rather than the model's own writing. Double-sided programs that reward both the referrer and the new customer are the common recommendation where a purchase is involved (Referral Rock), but a draft that misstates the offer creates a promise you have to honor or retract.

What stops the draft from inventing a result?

Two controls. The prompt says to cite exactly one fact from the supplied study and to return that fact in a separate field, and the reviewer checks it against the source. Grounding generation in retrieved source documents is the standard way to reduce hallucination and to let output carry a citation (Evidently AI). Neither control is sufficient alone.

Who should sit in the reviewer seat?

The account owner, not a marketing coordinator. The value of the review is relationship judgment: whether this is the right moment, whether the requested introduction is realistic, and whether the study will land. A coordinator can check the citation but cannot answer those three questions, and those are the ones that determine whether the ask gets a yes.

Sources

Sources

  1. PDF Referral Programs and Customer Value - Wharton Faculty Platform
  2. Customer Lifetime Value Improves loyalty | StriveCloud
  3. How to Increase Customer Lifetime Value CLTV with Referral Marketing
  4. 10 RAG examples and use cases from real companies
  5. A practical guide to Retrieval-Augmented Generation (RAG)
  6. Retrieval Augmented Generation (RAG) Case Study
  7. Legal Prompt Engineering Best Practices for Lawyers - Clio
  8. How to Write Effective Prompts for AI | Champlain College
  9. How to Ask for a Referral Without Making It Awkward
  10. How To Ask for a Referral to Grow Your Business
  11. How to Choose the Best Referral Rewards 24+ Examples
  12. What Is A Double Sided Referral Program? With Examples
  13. What Is A Double-Sided Referral? - Yotpo
About the author

About the author

Antonio Evans
Antonio Evans

Antonio Evans is the founder of Quanta Intelligence and a fractional CTO who builds HIPAA-ready AI systems for health and life-science companies. Before that he was technical co-founder of FriendsEAT for twenty years, CEO of Socialdraft, and a data engineer at IBM. Antonio lives with his dog Santino in Lisbon, Portugal.

All articles